https://
eugeneyan.com/writing/llm-pa
tterns/
…
MACHINE LEARNING
-
LLM Patterns: Essential Design Patterns for Large Language Models
By
–
-
Running Deep Learning Models on M1 Mac mini
By
–
I wonder if it'll still work if you start running deep learning models or an LLM on this M1 Mac mini.
-
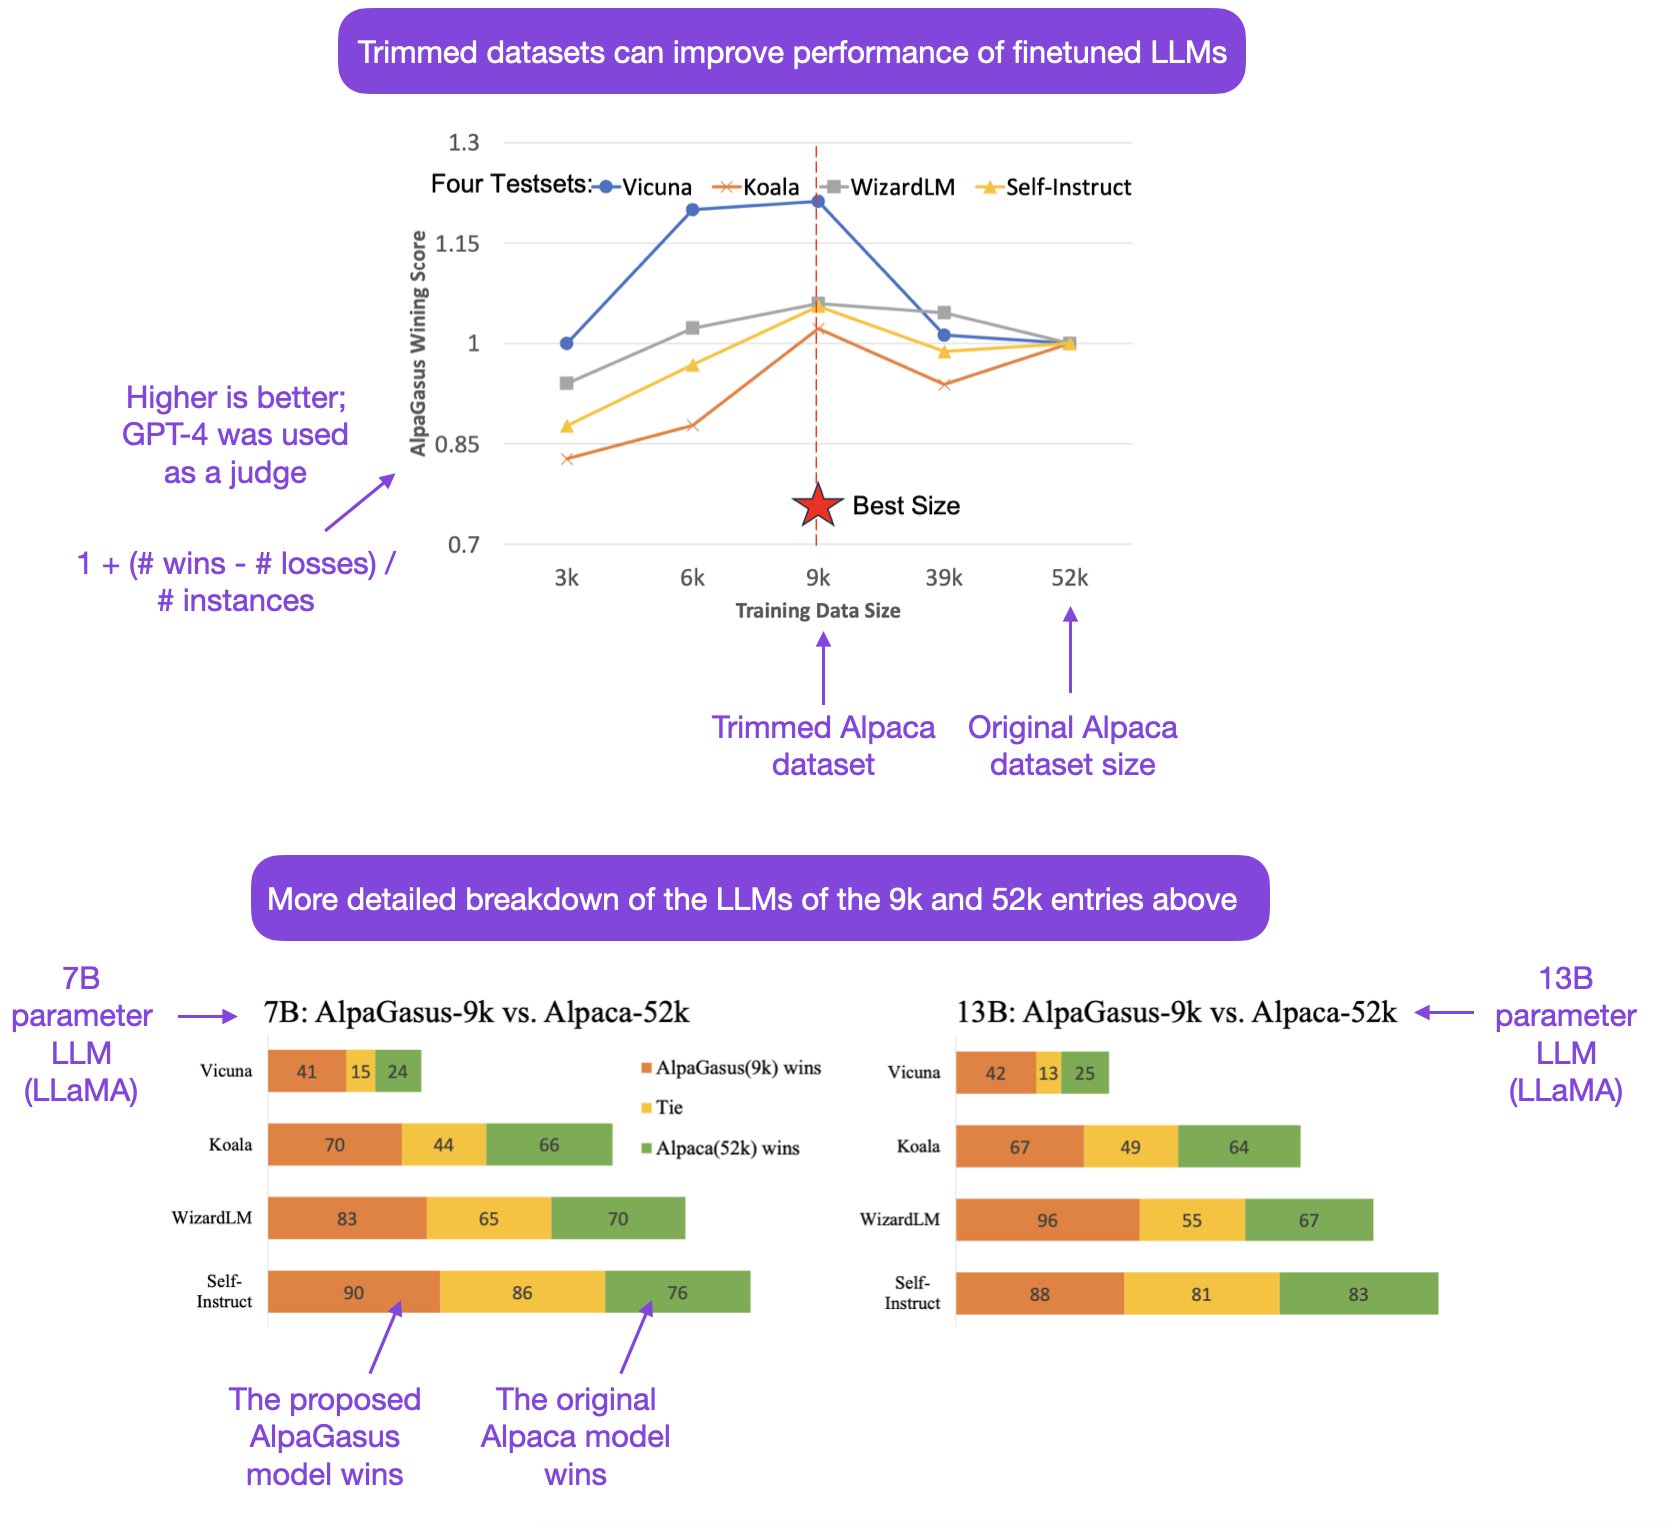
Less Data Better Results Finetuning LLMs with Trimmed Datasets
By
–
Next to LIMA, this is another interesting paper highlighting that more data is not always better when finetuning LLMs: https://
arxiv.org/abs/2307.08701 Trimming the orig 52k Alpaca dataset to 9k can improve the performance when finetuning 7B and 13B parameter LLMs. -
Balancing Human and Machine Intelligence in Enterprise Solutions
By
–
Well-said @dinisguarda
. Finding the right balance of human and machine intelligence is the upcoming keynote I will be giving at Esker's conference this Thursday. I hope you can make it. -
Brief CNN testing experience, focus shifted to LLM work
By
–
Phew, it's been a while. I think I only briefly tried it on some basic CNNs, and it worked fine out of the box. But afaik it's mainly for computer vision applications (have been super focused on LLM work recently)
-
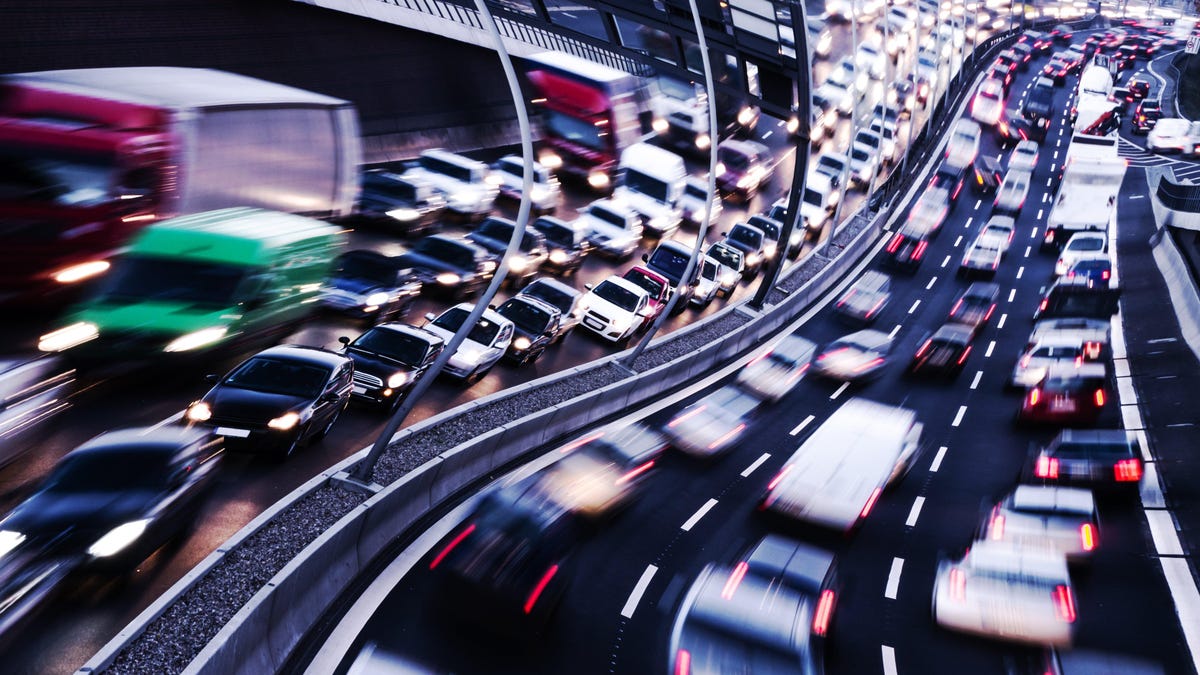
AI System Identifies Drug Trafficker Through Driving Pattern Analysis
By
–
AI System Helped Cops Identify a Drug Trafficker Just by Analyzing His Driving Patterns https://
bit.ly/3QeoM02 #AI #MachineLearning #DeepLearning #LLMs #DataScience -
NeurIPS Review Feedback: One-Sentence Critiques Analysis
By
–
So how many one-sentence reviews did you get in neurips?
-

BTLM-3B-8k Trending on Hugging Face with 250k Downloads
By
–
We are excited to see BTLM-3B-8k trending on Hugging Face with over 250k downloads! BTLM-3B-8k outperforms models trained on hundreds of billions more tokens and achieves comparable performance to open 7B parameter models. Check out the model: https://
huggingface.co/cerebras/btlm-
3b-8k-base
… -
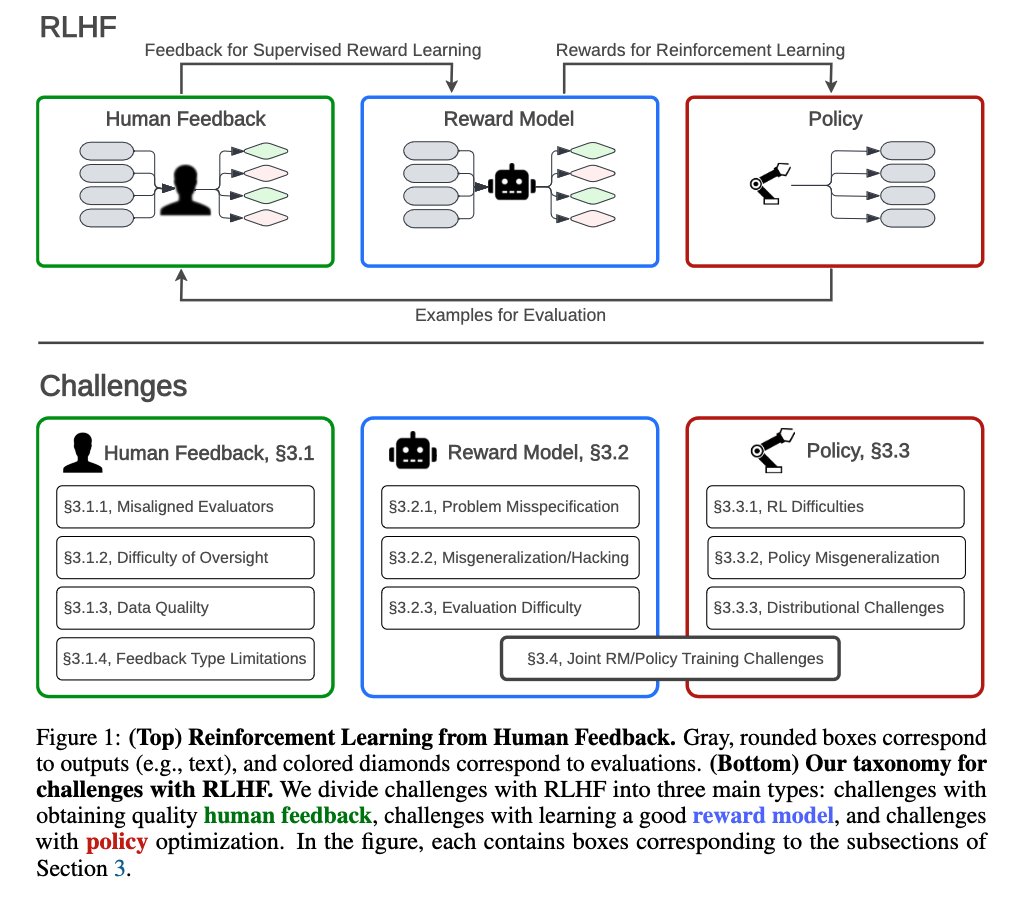
RLHF Limitations and Open Problems in AI Alignment
By
–
RLHF(Reinforcement learning from human feedback) is the common technique used for aligning AI systems(LLMs in particular) with human goals. RLHF works but as with every thing in life, it has flaws too. The paper "Open Problems and Fundamental Limitations of Reinforcement
-
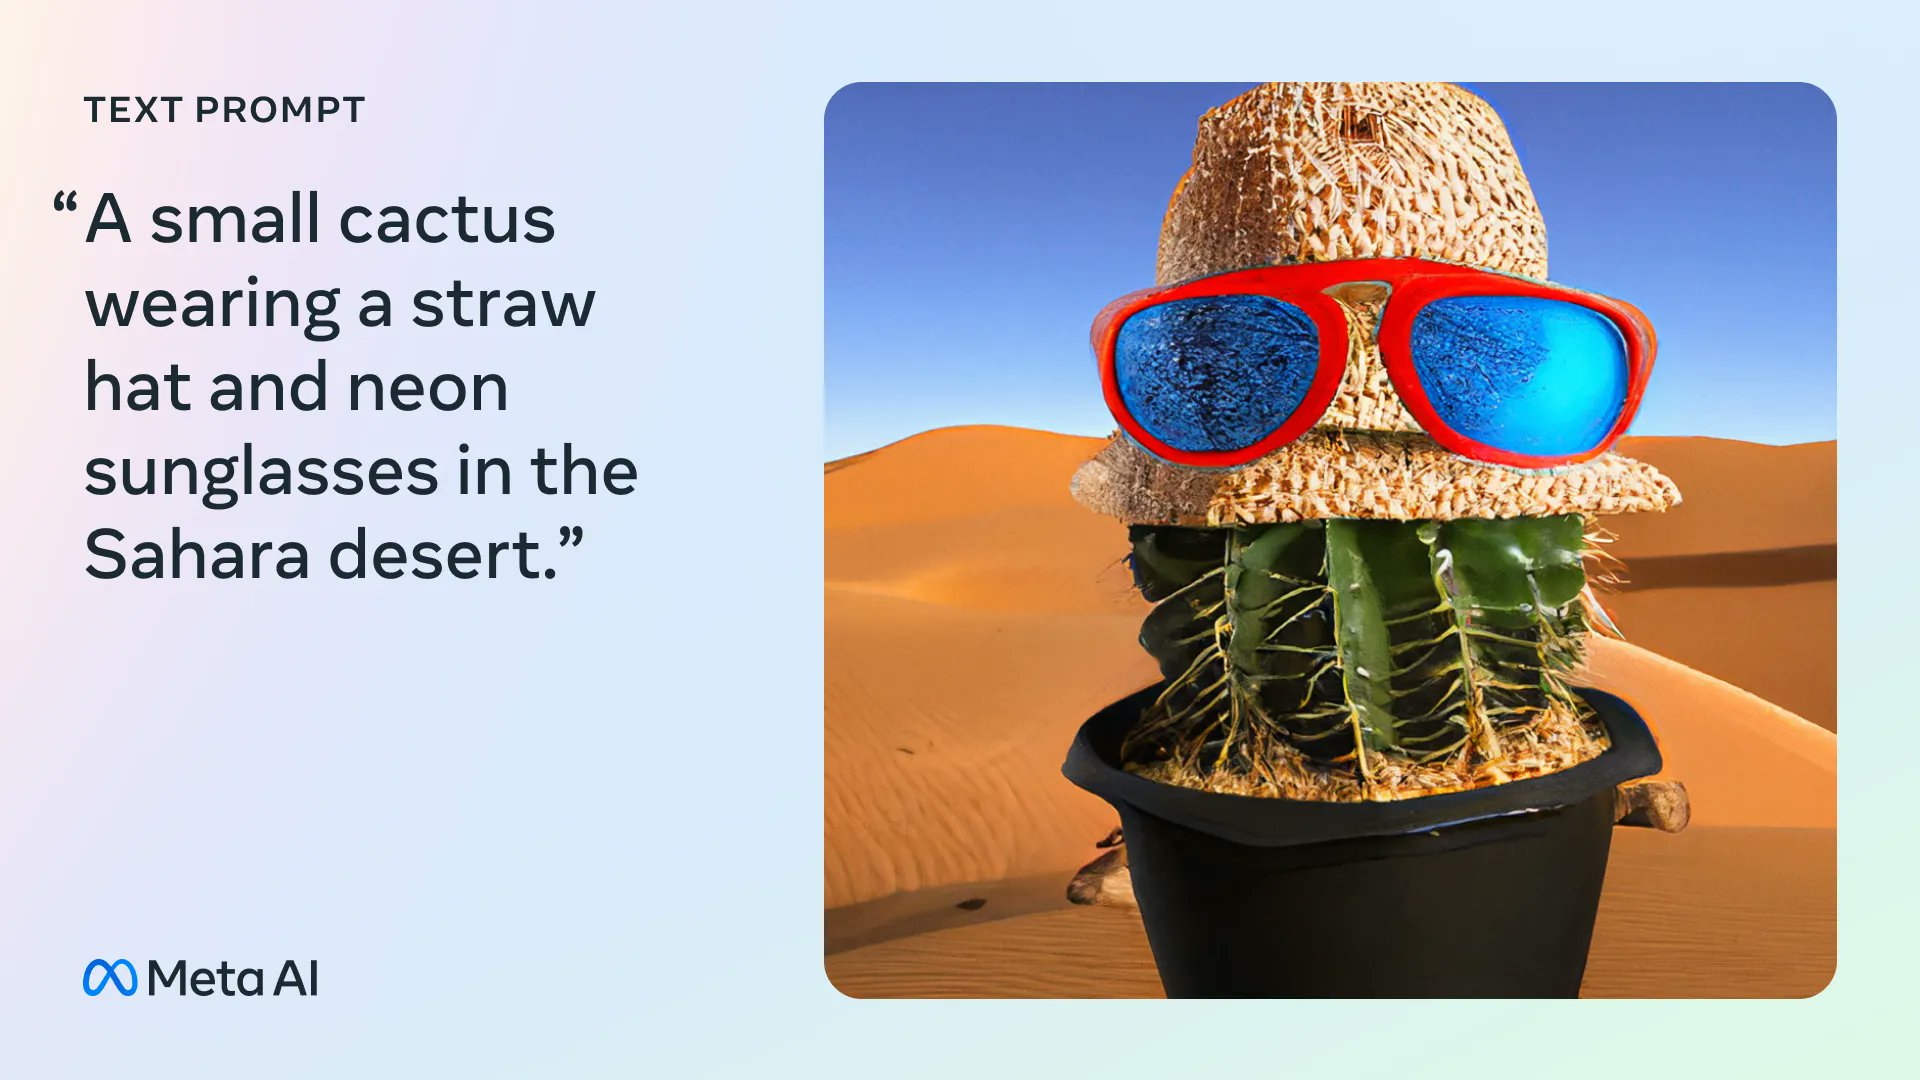
CM3Leon: State-of-the-art text-to-image generation with less compute
By
–
CM3leon is a first-of-its-kind multimodal model that achieves state-of-the-art performance for text-to-image generation despite being trained with five times less compute than previous transformer-based methods. More details and examples https://
bit.ly/44I6t7E