Love it! Getting closer and closer to an LSTM 😉
MACHINE LEARNING
-

Scaling embedding learning rate by model width removes need for µP
By
–
Turns out you never really needed µP, you just needed to scale the embedding learning rate by model width I'm no nanoGPT speedrunner, but isn't it something people stumbled into by using Muon for hidden layers + Adam for the rest?
-

Gated DeltaNet-2: Hybrid Attention Architecture Advancement
By
–
Gated DeltaNet has been one of my favorite "hybrid attention" newcomers in the good old transformer stack.
Excited to see Gated DeltaNet-2. Adding it to my reading stack. In the meantime, I have a primer on Gated DeltaNet here: https://
magazine.sebastianraschka.com/i/177848019/26
-gated-deltanet
… -
Skills enable deterministic execution for parallel model usage
By
–
Skills can allow you to have deterministic execution patterns, so I have a lot of minimal harnesses for repeated tasks, that way I can control outcome no matter what model I use This is extremely helpful if you have multiple endpoints / models that you want to run in parallel
-

Stanford and partners announce 2026 Conference on Physics and AI
By
–
The Center for Decoding the Universe teams up with @APSphysics
's Group on Data Science and @NeurIPSConf
's Machine Learning and Physical Sciences Workshop team to present the 2026 Conference on Physics and AI (PAI26). Learn more about this year's agenda: https://
datascience.stanford.edu/PAI26 -
Complete guide to understanding LLMs from first principles free online
By
–
INCREDIBLE The MOST COMPLETE GUIDE for understanding LLMs from first principles is now available online to read for free Covers the model mechanics – Tokens / tokenizers
– Transformers
– Attention
– KV cache
– Prefill vs decode
– Decoding controls
– Model packages
– Chat -
Opacity of neural networks infects academic papers
By
–
The opacity of neural networks has infected the papers about them.
-
HRM Outperforms Transformers 7x Its Size
By
–
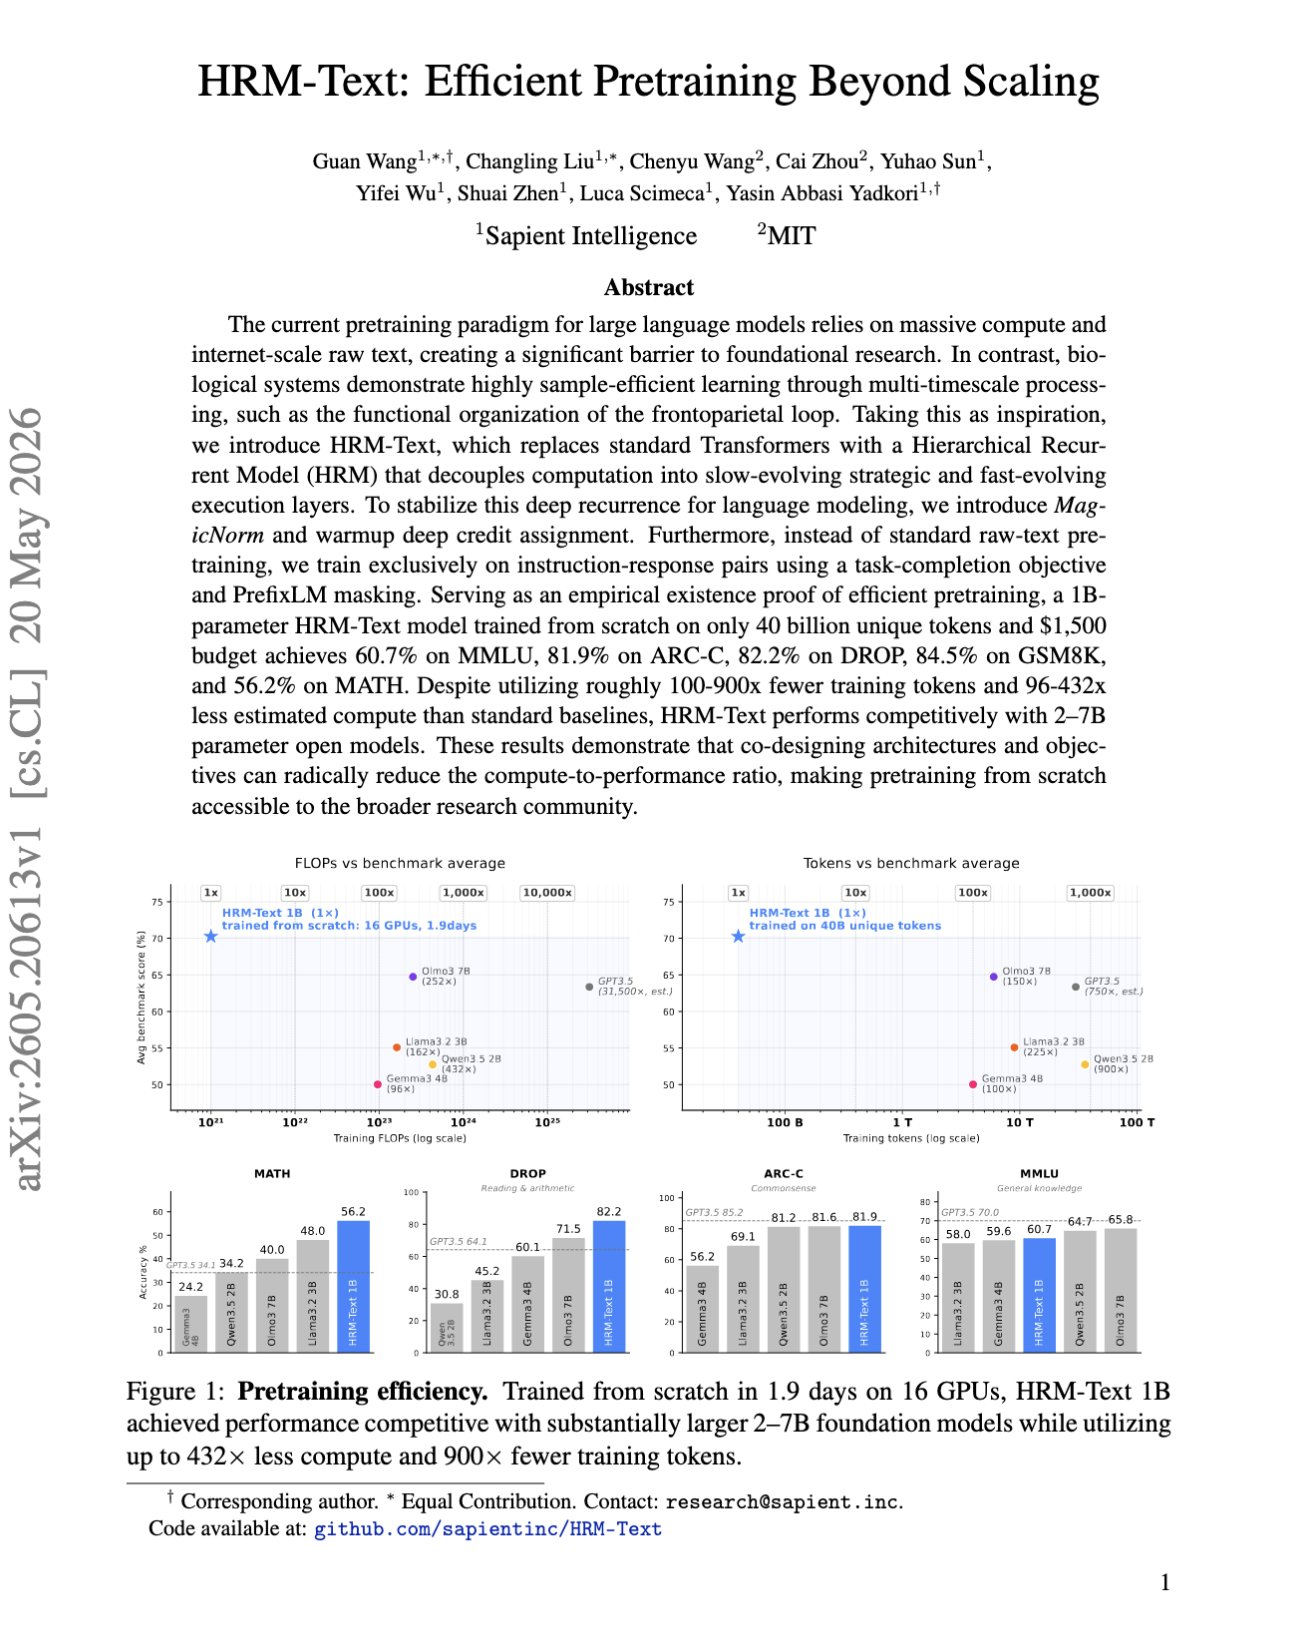
HRM beats Transformers seven times its size in language modeling!? "HRM-Text: Efficient Pretraining Beyond Scaling" This paper introduces the Hierarchical Recurrent Model (HRM), which incorporates slow planning layers and fast execution layers to enhance planning and recurrence. The model was trained directly on…
-
LLMs: symbolic AI triumph with more noise
By
–
Looked at this way, LLMs are the triumph of symbolic AI, just with more noise.
-
Testing Gemma 4 and Qwen with SQL generation quality comparison
By
–
I've tried it with Gemma 4 and Qwen 3.5/3.6 so far, works well with the >4B models, sometimes works with 4B but they're more likely to mess up the SQL