Quantifying Hyperparameter Transfer and the Importance of Embedding Layer Learning Rate (first screenshot, Kalra and Barkeshli): https://
arxiv.org/abs/2605.21486 Optimal Embedding Learning Rate in LLMs: The Effect of Vocabulary Size (Hayou and Liu): https://
arxiv.org/abs/2506.15025
MACHINE LEARNING
-
Quantifying Hyperparameter Transfer and Embedding Learning Rate in LLMs
By
–
-
µP embedding LR rule correct under AdamW, explains most benefits
By
–
To clarify, this paper basically says: under AdamW, µP's embedding LR rule (constant) is essentially right and explains most of µP's benefit. Last year, Hayou et al. found that µP's embedding LR rule is wrong for realistic LLM vocab sizes. They found that the optimal embedding
-
Mixture of Experts (MoE) Training Explained: Compounding Loops and Expert Specialization
By
–
MoE Training, Part 2 — in one tweet:
— Satya Mallick (@LearnOpenCV) 22 mai 2026
You start with random weights. By chance, one expert is slightly better at legal questions. Router notices, sends more its way. It gets better. Snowballs.
Same compounding loop that turns a slightly-talented 7-year-old into an IMO medalist.
—… pic.twitter.com/gXIjIRHlGZMoE Training, Part 2 — in one tweet:
You start with random weights. By chance, one expert is slightly better at legal questions. Router notices, sends more its way. It gets better. Snowballs.
Same compounding loop that turns a slightly-talented 7-year-old into an IMO medalist.
— -
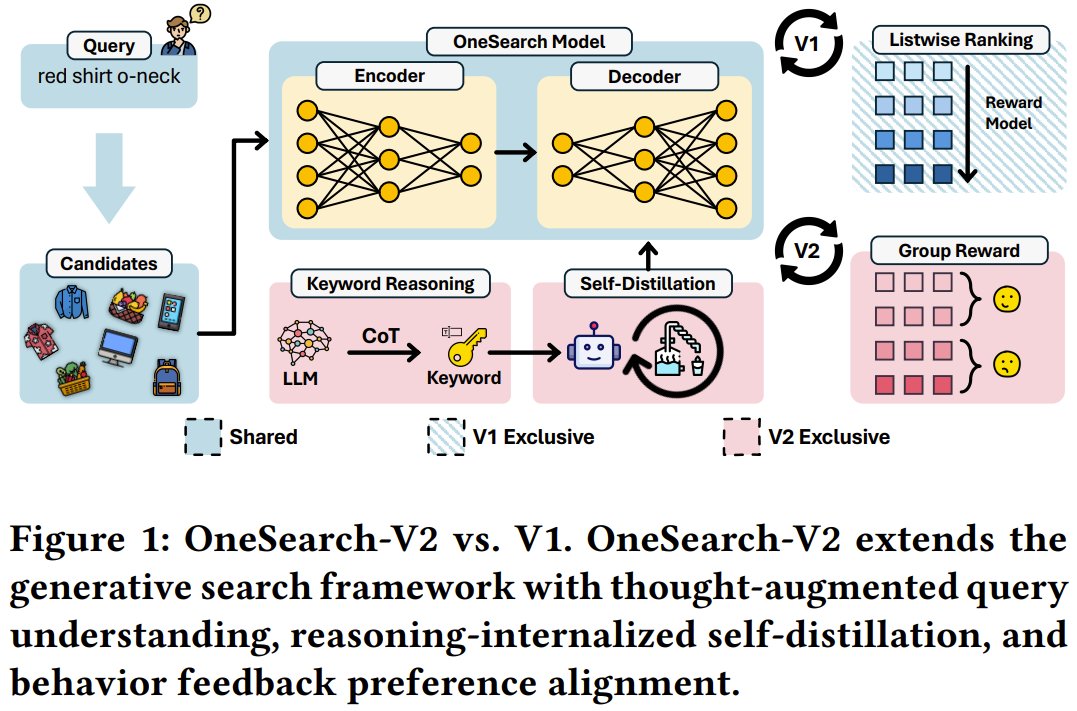
Kuaishou OneSearch-V2: Generative Search That Understands Intent
By
–
What if your search engine could understand not just what you type, but what you really mean? Kuaishou Technology presents OneSearch-V2: a generative search framework that reasons like a human before returning results. It uses three clever tricks: (1) a “thought” step to deeply
-
Gated DeltaNet-2: Decoupling Erase and Write in Linear Attention
By
–
Gated DeltaNet-2: Decoupling Erase and Write in Linear Attention Paper: https://
github.com/NVlabs/GatedDe
ltaNet-2/blob/main/paper/GDN2_paper.pdf
…
Code: https://
github.com/NVlabs/GatedDe
ltaNet-2
… -
Trying to remember coding before Codex existed
By
–
trying to remember what it was like to code before codex
-
Models progressing from basic math to solving hard problems
By
–
Its funny how much the whole "strawberry" thing, which turned out to be o1-preview, was dismissed as overhyped at launch when it is clear in retrospect that it was way underhyped. A direct line from models unable to do basic math to solving unresolved math problems in 18 months.
-
Models as the prime mover behind AI products
By
–
I would push back a little: because the models are so good & improving, they don't have to be the product. But it is the model that is the prime mover. If they weren't so generally capable, the harnesses & apps the labs build around them would be hard to build and wouldn't work.
-

AI models can be persuaded to accept falsehoods study
By
–
You can persuade #AI models to accept falsehoods as truth, study shows
by Ashique KhudaBukhsh @_TCglobal Learn more: https://
bit.ly/4dPA5ao #LLM #GenerativeAI #ArtificialIntelligence #MachineLearning -

OpenAI integrates ChatGPT into PowerPoint for slide creation
By
–
OPENAI : ChatGPT is now available directly in PowerPoint, allowing users to create and edit slides. PowerGPT