This isn't intended to be snarky, there are lots of things AI does terribly, by the way. But I have often been surprised by the things it does very well. We need more critics to actually engage with these systems so everyone can learn more about them.
MACHINE LEARNING
-

NLP Cross-Field Engagement Declined Significantly Since 1980
By
–
10/ The Influence Between NLP and Other Fields – aims to quantify the degree of influence between 23 fields of study and NLP; the cross-field engagement of NLP has declined from 0.58 in 1980 to 0.31 in 2022…
-

Multilingual LLMs Survey: Methods, Taxonomy and Research Frontiers
By
–
7/ Overview of Multilingual LLMs – a survey on multilingual LLMs including a thorough review of methods, a taxonomy, emerging frontiers, challenges, and resources to advance research.
-

Knowledge Capacity Scaling Laws in Language Models
By
–
8/ The Physics of Language Models – investigates knowledge capacity scaling laws where it evaluates a model’s capability via loss or benchmarks, to estimate the number of knowledge bits a model stores.
-
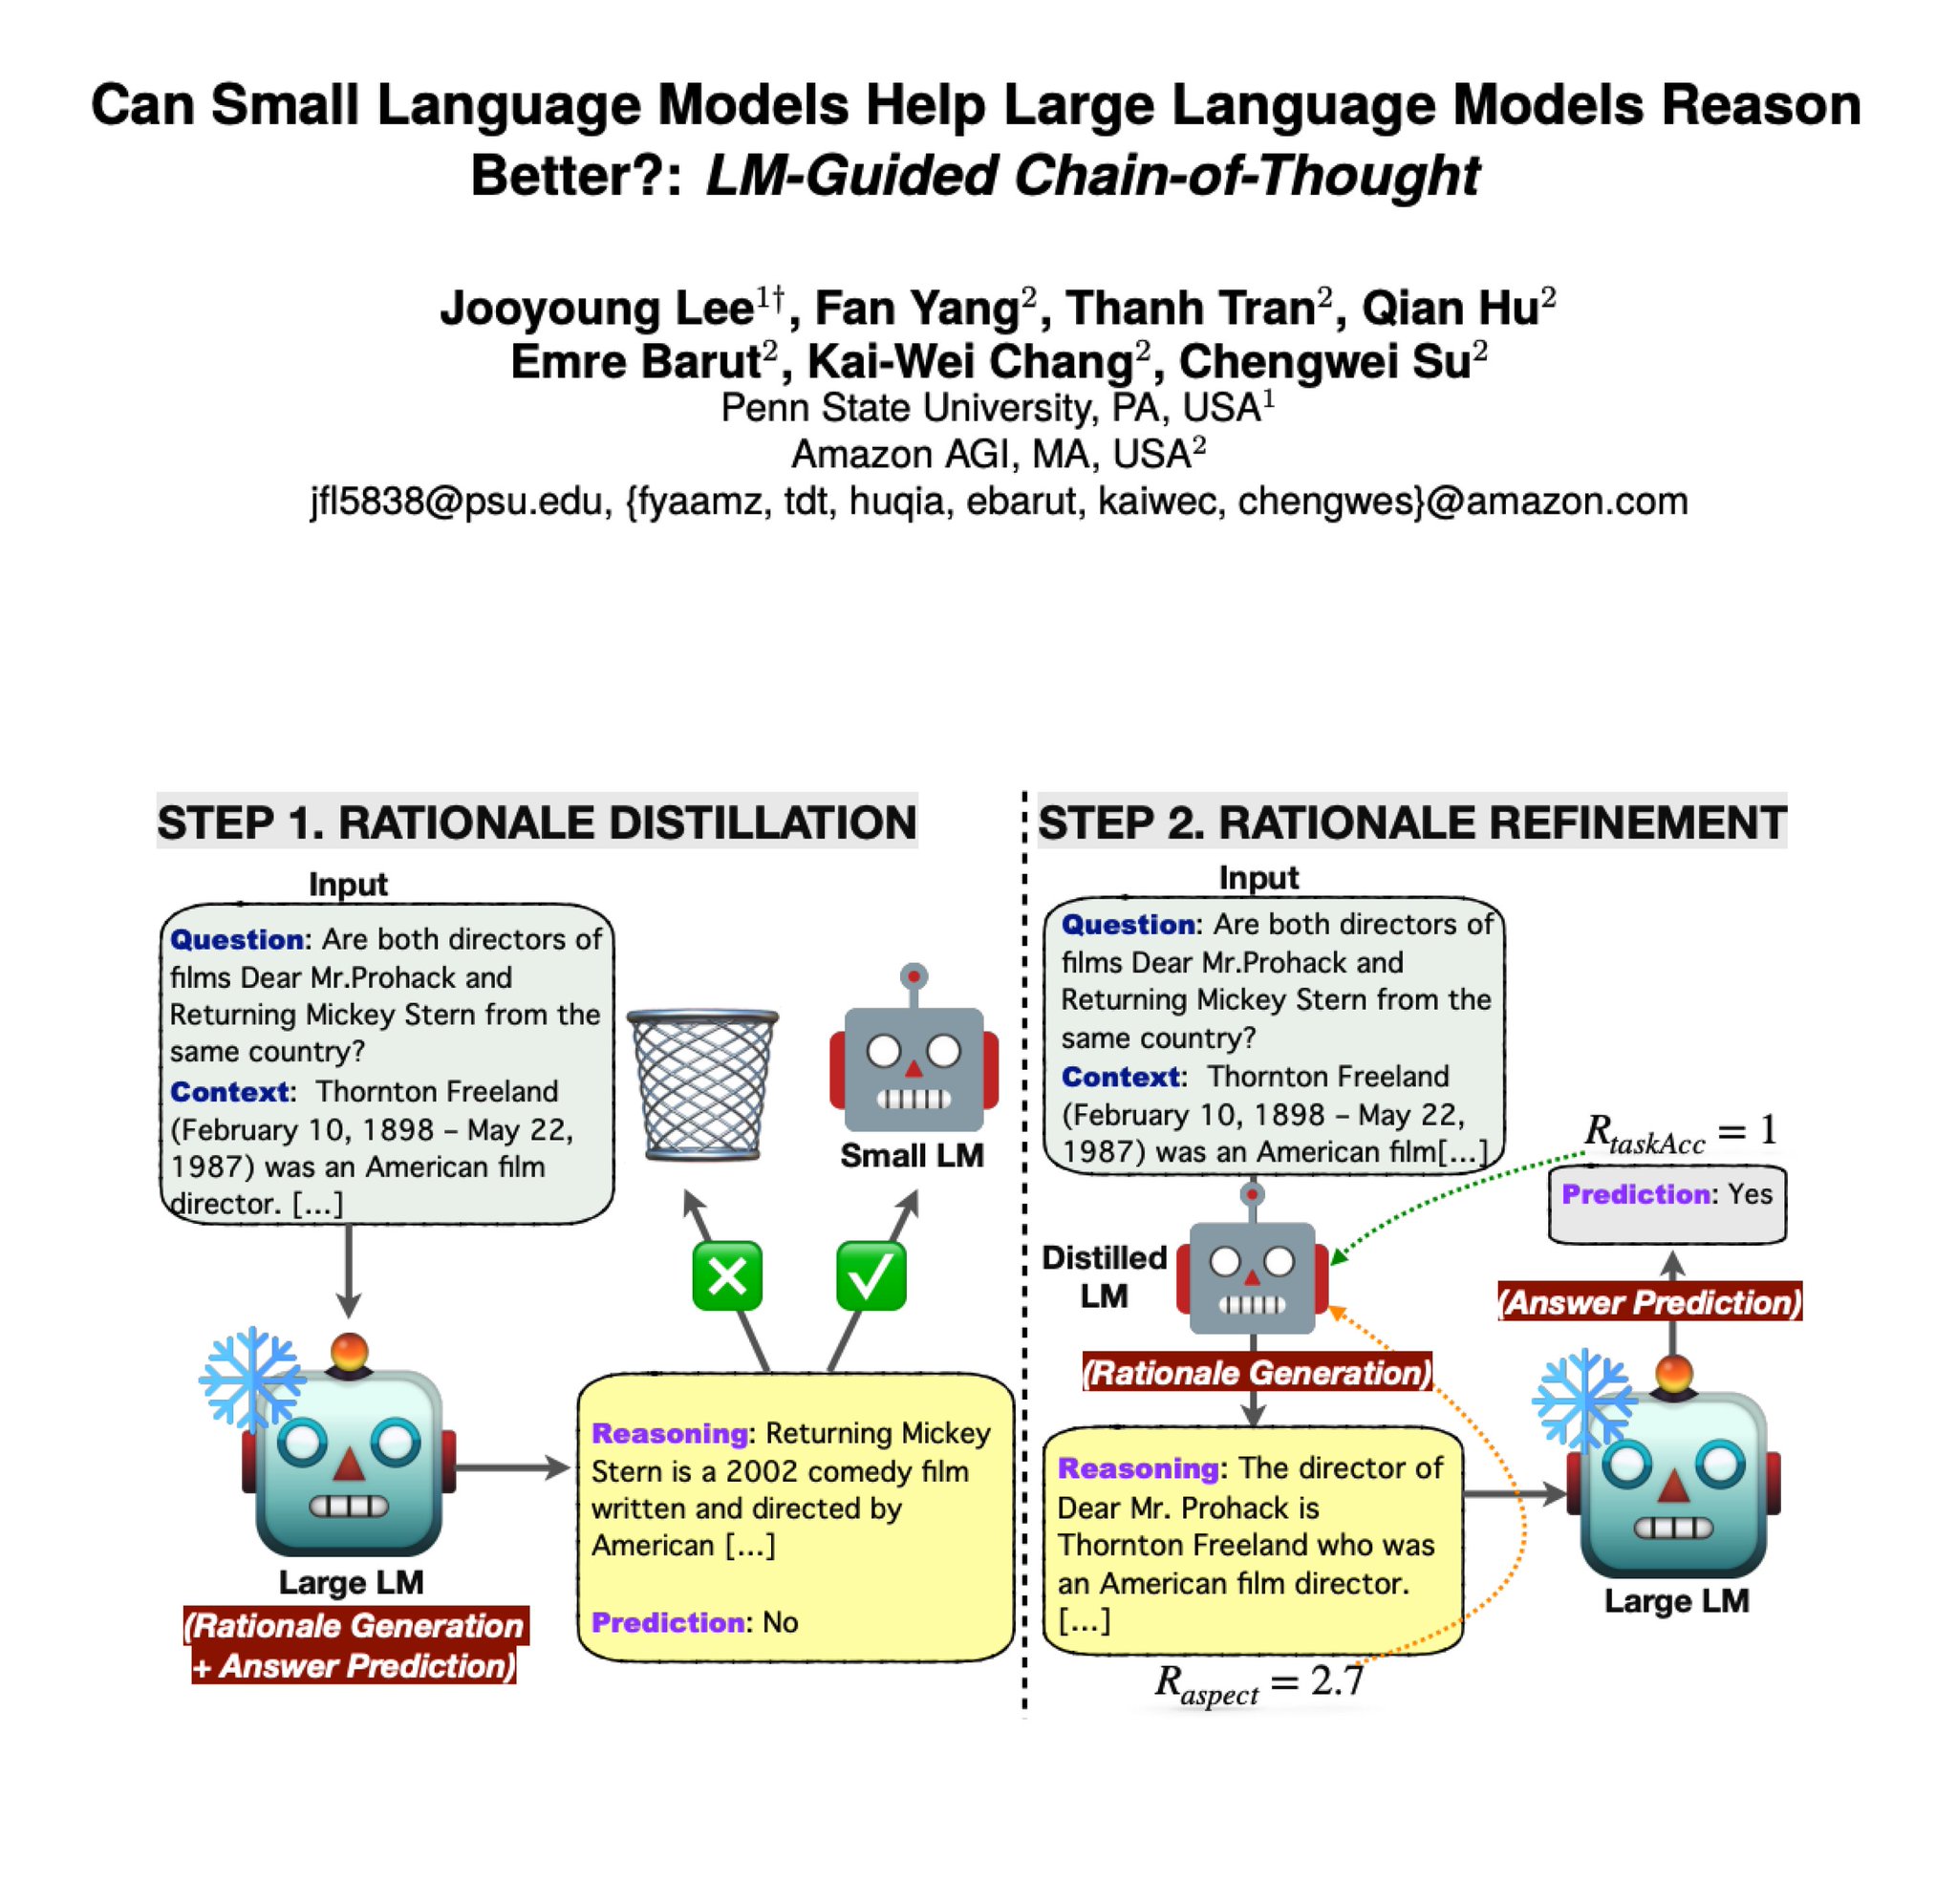
LM-Guided Chain-of-Thought Knowledge Distillation Technique
By
–
4/ LM-Guided Chain-of-Thought – applies knowledge distillation to a small LM with rationales generated by the large LM; the rationale is then generated by the lightweight LM and the answer prediction is done by the frozen large LM.
-
Google DeepMind Synthetic Data Research Best Practices Overview
By
–
5/ Best Practices and Lessons on Synthetic Data – an overview by Google DeepMind on synthetic data research, covering applications, challenges, and future directions
-
OpenEQA Benchmark Dataset for Embodied Question Answering
By
–
2/ OpenEQA – proposes an open-vocabulary benchmark dataset to measure the capabilities of AI models to perform embodied question answering (EQA); it contains 1600 human-generated questions composed from 180 real-world environments.https://t.co/8OYcRgcyjH
— DAIR.AI (@dair_ai) 14 avril 20242/ OpenEQA – proposes an open-vocabulary benchmark dataset to measure the capabilities of AI models to perform embodied question answering (EQA); it contains 1600 human-generated questions composed from 180 real-world environments.
-

NeurIPS Introduces Preschool Track for Machine Learning Research
By
–
Announcing NeurIPS Preschool Track This year, we invite preschoolers to submit machine learning research papers.
-
PyTorch Performance Improvements with Nightly Build and Optimizations
By
–
THE REVENGE OF PYTORCH
just kidding 🙂 @cHHillee (from PyTorch team) was kindly able to help improve the PyTorch baseline, done by 1) upgrading to nightly, 2) using the "compound" F.sdpa (scaled dot product attention) layer directly, and turning on a torch compile flag: