https://
pytorch.org/tutorials/inte
rmediate/torch_compile_tutorial.html
…
MACHINE LEARNING
-
PyTorch Compile Tutorial: Optimizing Machine Learning Code
By
–
-
PyTorch Optimization: torch.compile vs Vanilla Performance
By
–
this isn’t comparing to torch.compile, which is the torch-native optimized version, it’s comparing to vanilla pytorch which is notoriously bloated and slow 🙂
-
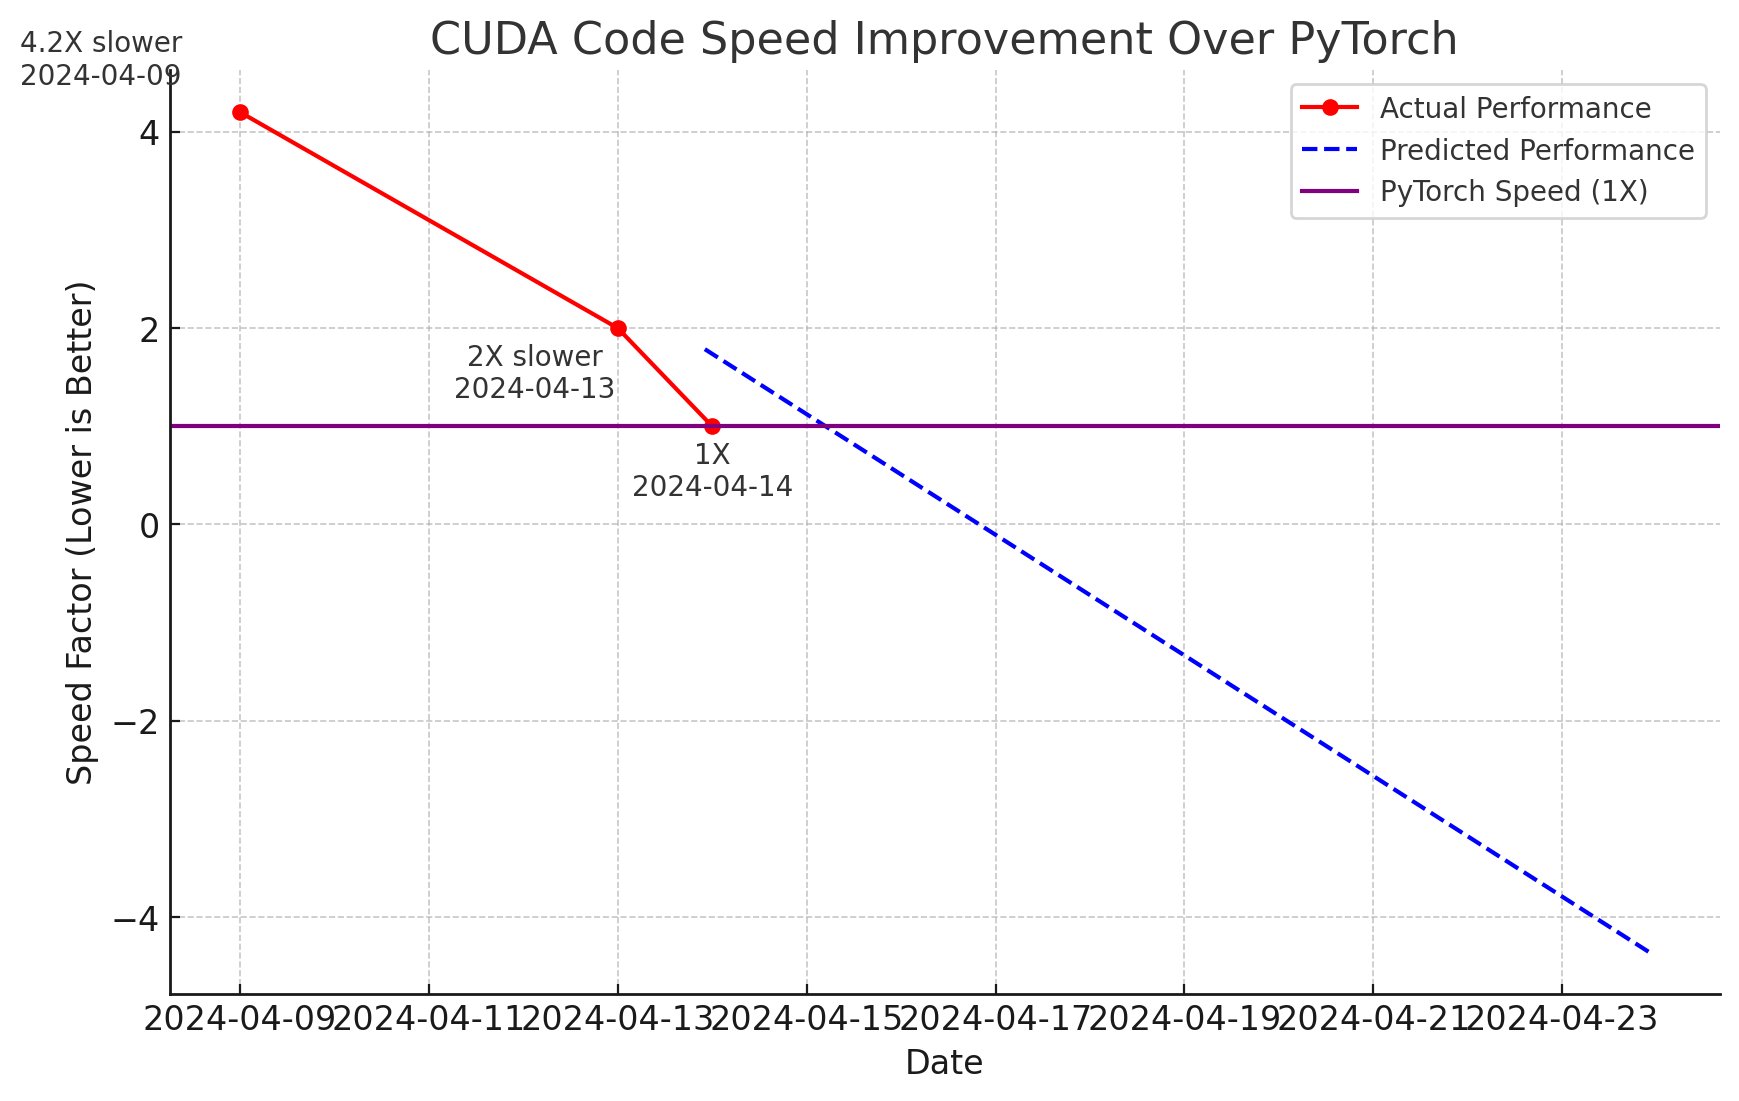
llm.c Optimization: Matching PyTorch Performance After Bug Fix
By
–
Highly amusing update, ~18 hours later: llm.c is now down to 26.2ms/iteration, exactly matching PyTorch (tf32 forward pass). We discovered a bug where we incorrectly called cuBLAS in fp32 mathmode . And ademeure contributed a more optimized softmax kernel for very long rows
-
Experience versus intelligence: reframing expertise assessment
By
–
I often find myself mentally swapping "smartest" for "most experienced", since "experience" helps imply that it's for a specific field, not everything
-
End to End Latency vs Opus Weaviate Embeddings
By
–
whats end to end latency? vs just opus + weaviate + embeddings
-
Reinventing Transformers Architecture From First Principles
By
–
yep hahaha he re-invented Transformers from first principles I suppose
-
Mixtral Training Challenges: Memory Issues and Model Recovery
By
–
Training Bixtral, which is expensive + slow so mistakes are costly. The run finally finished, but then we got a sigkill -9 error (I believe it's a memory issue). I thought I lost the model, but I went into the output directory anyway, and luckily, it was there.
-
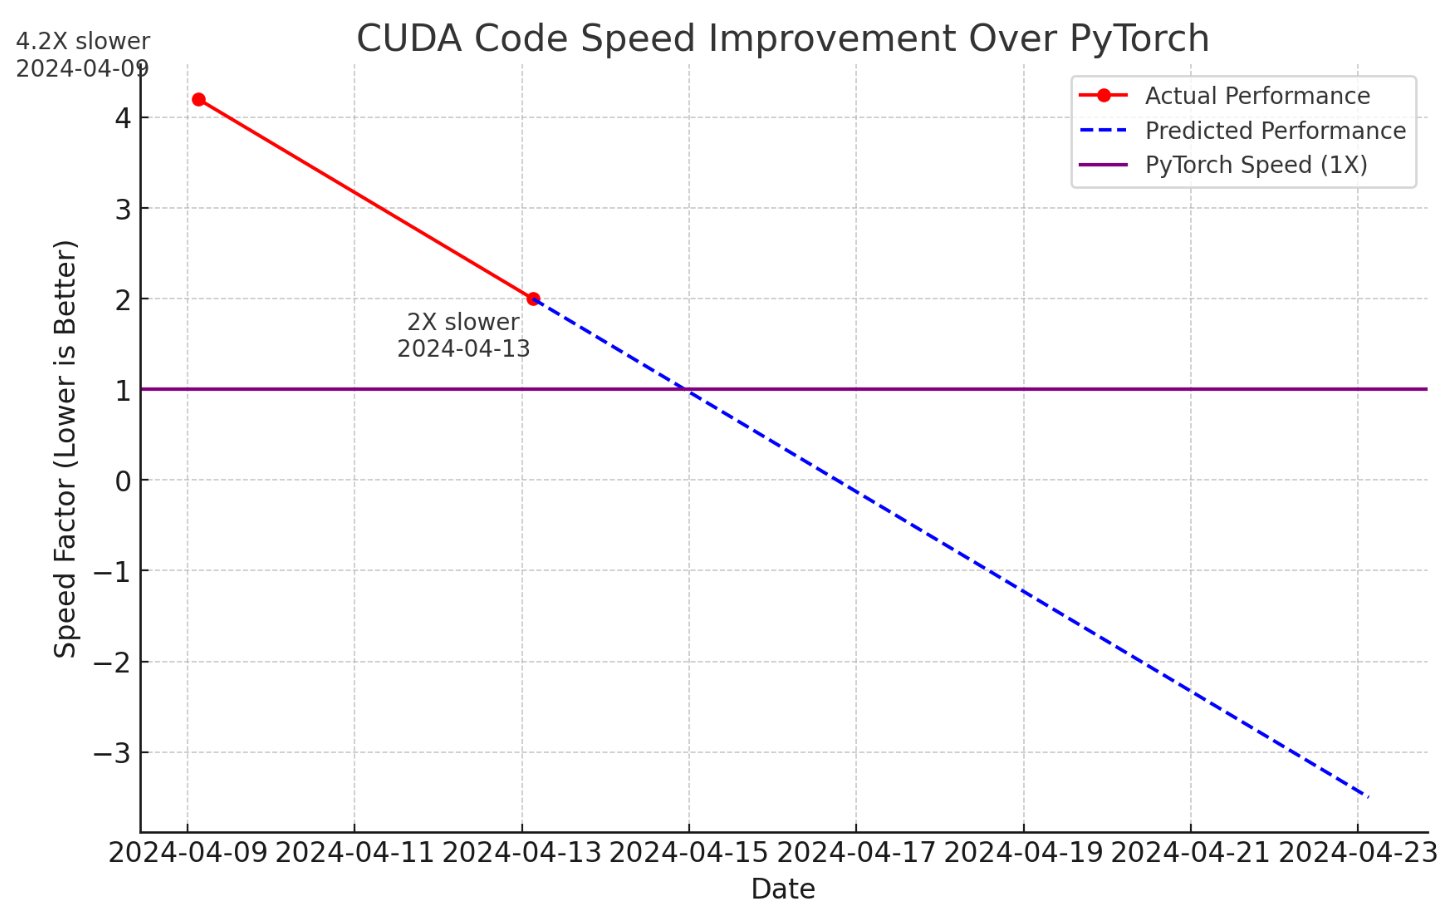
llm.c Performance Optimization: Closing Gap with PyTorch
By
–
A few new CUDA hacker friends joined the effort and now llm.c is only 2X slower than PyTorch (fp32, forward pass) compared to 4 days ago, when it was at 4.2X slower The biggest improvements were:
– turn on TF32 (NVIDIA TensorFLoat-32) instead of FP32 for matmuls. This is a -

Audio-Visual Generation Workshop Accepted at ECCV
By
–
Just finished my first draft writing on audio-visual generation this week, and then our ECCV workshop proposal on Audio-Visual Generation and Learning is accepted! We have 6 tentatively confirmed invited speakers. Stay tuned for more details.