
the closest thing i've seen to actual "physics for LMs" was probably this (single-author!) paper from neurips 2024: Understanding Transformers via N-Gram Statistics this is how we used to think about LMs; not sure why we stopped.
MACHINE LEARNING
-
Modern Data Stack Consolidation Through M&A Activity
By
–
I’m back to (recreationally) writing while figuring out what’s next. First thing looking what’s happening with the modern data (and MLOps) stack. With the flurry of M&A (and M&A talks), the long-coming and frequent joke that the MDS consolidation may have finally arrived!
→ View original post on X — @mattlynley, 2025-05-17 18:58 UTC
-
Venture mania in data/ML space: overcrowded and overfunded market
By
–
In the later 10s/early 20s there was practically a venture mania for companies in the orbit of Snowflake and Databricks, with some (like Dbt, Weights & Biases, and so on) reaching lofty valuations. But most you’d talk to would consider it massively overcrowded (and overfunded).
→ View original post on X — @mattlynley, 2025-05-17 18:58 UTC
-

Are LLMs Plateauing? Scaling Laws Running Out of Gas
By
–
Are LLMs plateauing? Are Scaling Laws Running Out of Gas? Many think so because: Data ceiling – We’ve scraped most of the internet. Synthetic data helps…but models aren’t great at grading their own homework. Compute pain – Transistors are approaching atomic-scale; energy
-
Maya: Open-Source Multilingual Vision Language Model
By
–
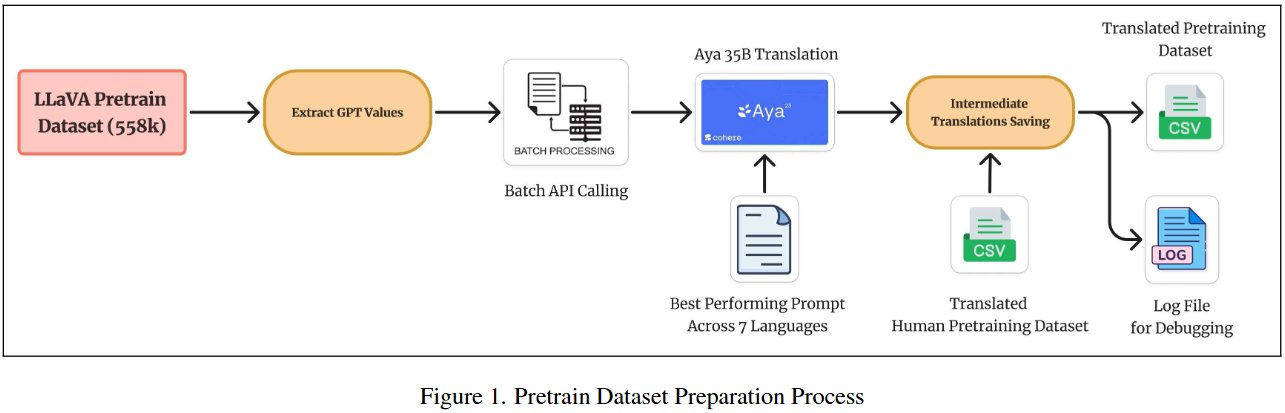
Behind Maya: Building a Multilingual Vision Language Model This paper introduces Maya, an open-source multilingual Vision-Language Model (VLM) designed to enhance performance on vision-language tasks across eight diverse languages. Maya addresses the underperformance of existing
-
MiMo-7B: Reasoning-Optimized Language Model Outperforms Larger Models
By
–
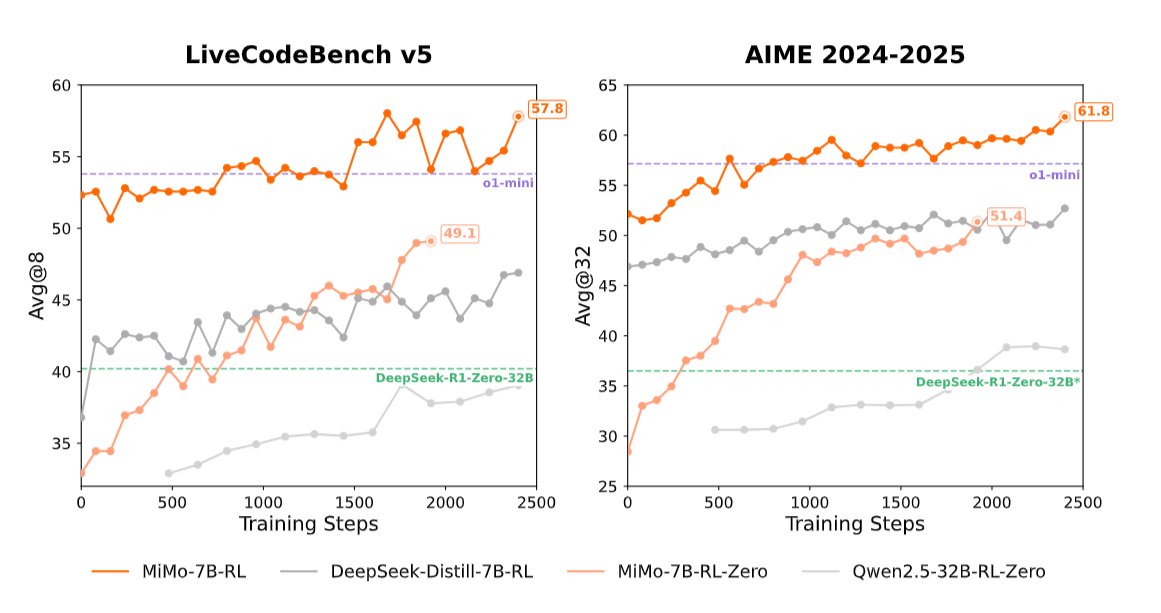
MiMo: Unlocking the Reasoning Potential of Language Model — From Pretraining to Posttraining MiMo-7B is a reasoning-centric LLM series optimized from pretraining through posttraining, achieving state-of-the-art performance on math and code tasks—even outperforming models 4× its
-
Test-Time Compute: Why Thinking Time Matters in AI
By
–
Lilian Weng just dropped a new blog post: Why We Think. It explores recent advances in using test-time compute (aka 'thinking time')—and why it matters.
-
Extended Thinking: Why Models Need More Time to Reason
By
–
Giving your models more time to think before prediction, like via smart decoding, chain-of-thoughts reasoning, latent thoughts, etc, turns out to be quite effective for unblocking the next level of intelligence. New post is here 🙂 “Why we think”: lilianweng.github.io/posts/2…
→ View original post on X — @lilianweng, 2025-05-17 15:09 UTC
-
Welcome to Science Engineering and Technology Community
By
–
Welcome to science, engineering, and technology (SET). #ScienceEngineeringTechnology #SET #SETStudies #SETResearch
-
Geoffrey Hinton on AI and the Human Brain
By
–
"I have always been convinced that the only way to get artificial intelligence to work is to do the computation in a way similar to the human brain." — @GeoffreyHinton