Discriminator-generator gap seems to be the most important idea in AI for scientific innovation. With compute + clever search, anything that we can measure will be optimized. First up will be environments that can be verified quickly, with continuous reward, and at scale.
MACHINE LEARNING
-

Zero-to-LLM Engineer Bundle: Complete Learning Path
By
–
Since many of you asked, here it is… our "Zero-to-LLM Engineer" bundle! We ( @towards_AI ) recently released our three core offers for any builders out there, together taking you from "zero" (literally, no coding knowledge or anything required) up to an advanced LLM developer
-
Foundational Machine Learning Research Paper Highly Recommended
By
–
overall a really entertaining read, highly recommend. here's a link http://
jmlr.org/papers/volume3
/bengio03a/bengio03a.pdf
… -
Neural Networks Outperform N-gram Models in Mixture Architecture
By
–
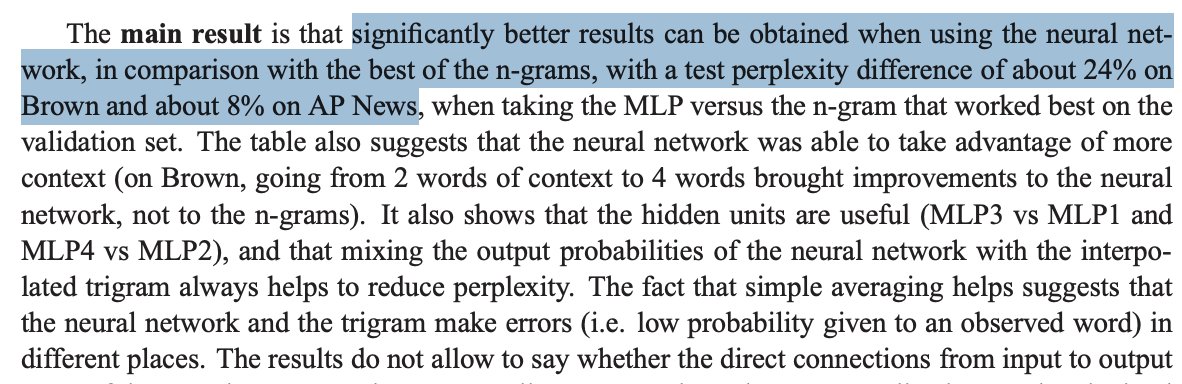
their neural networks worked better than any other methods and the bigger ones are better although at this scale, mixing with ngrams still helps a lot. they use a "mixture of models" – similar to today's MoEs, but the experts are different ngram models, plus one neural network
-
Model Training Scale: From 800K to 25 Trillion Tokens
By
–
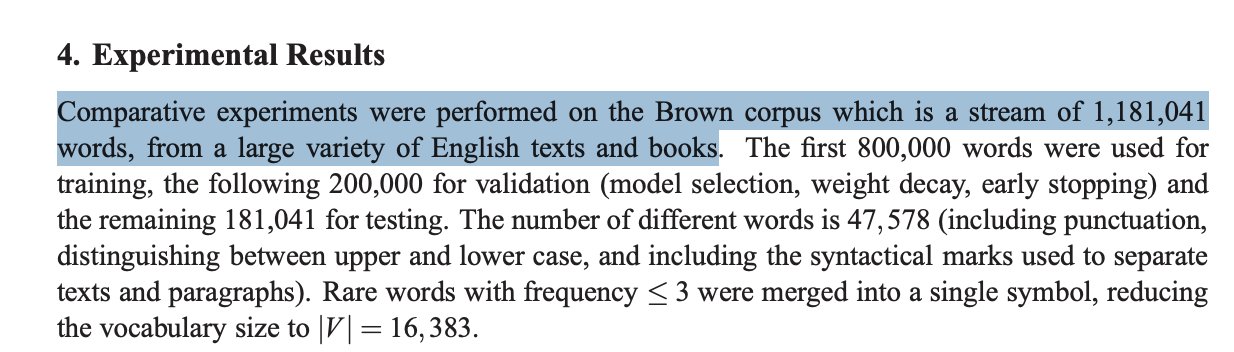
their model is trained on 800K words, which is around 2.5M tokens. remember today's models are up to ~25T tokens (10^7 more, or 10 million million times) (they trained another model on 15M words)
-
Hogwild Parallel Processing on CPU: Engineering Techniques
By
–
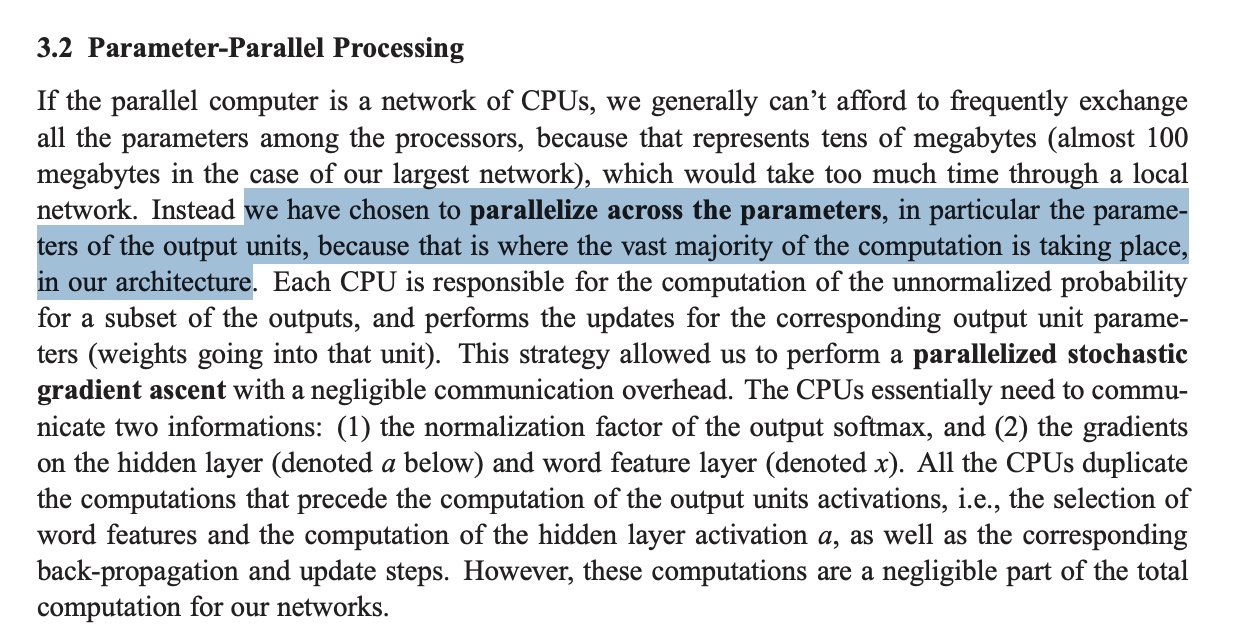
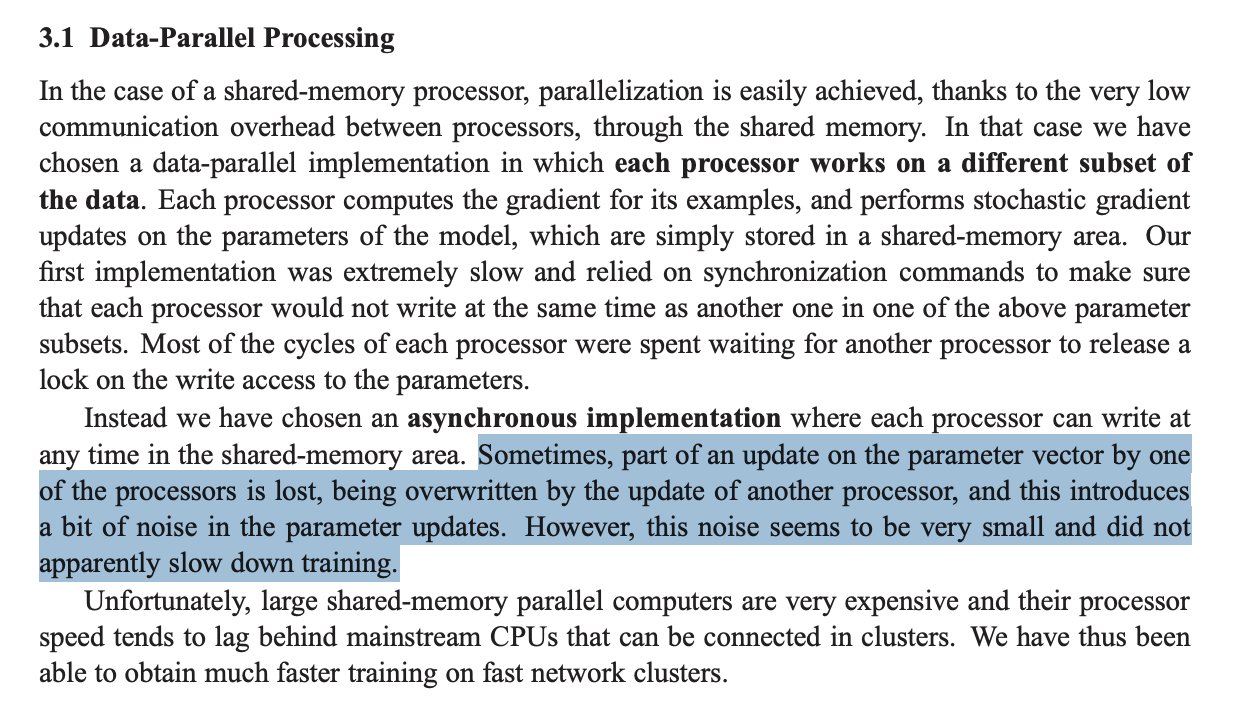
they do parallel processing (on CPU). i think this is now a well-known technique called Hogwild that wasn't formally developed until 2011. engineering this sounds pretty fun:
-
Compact Language Model Architecture: 12M Parameters vs LLAMA 4
By
–
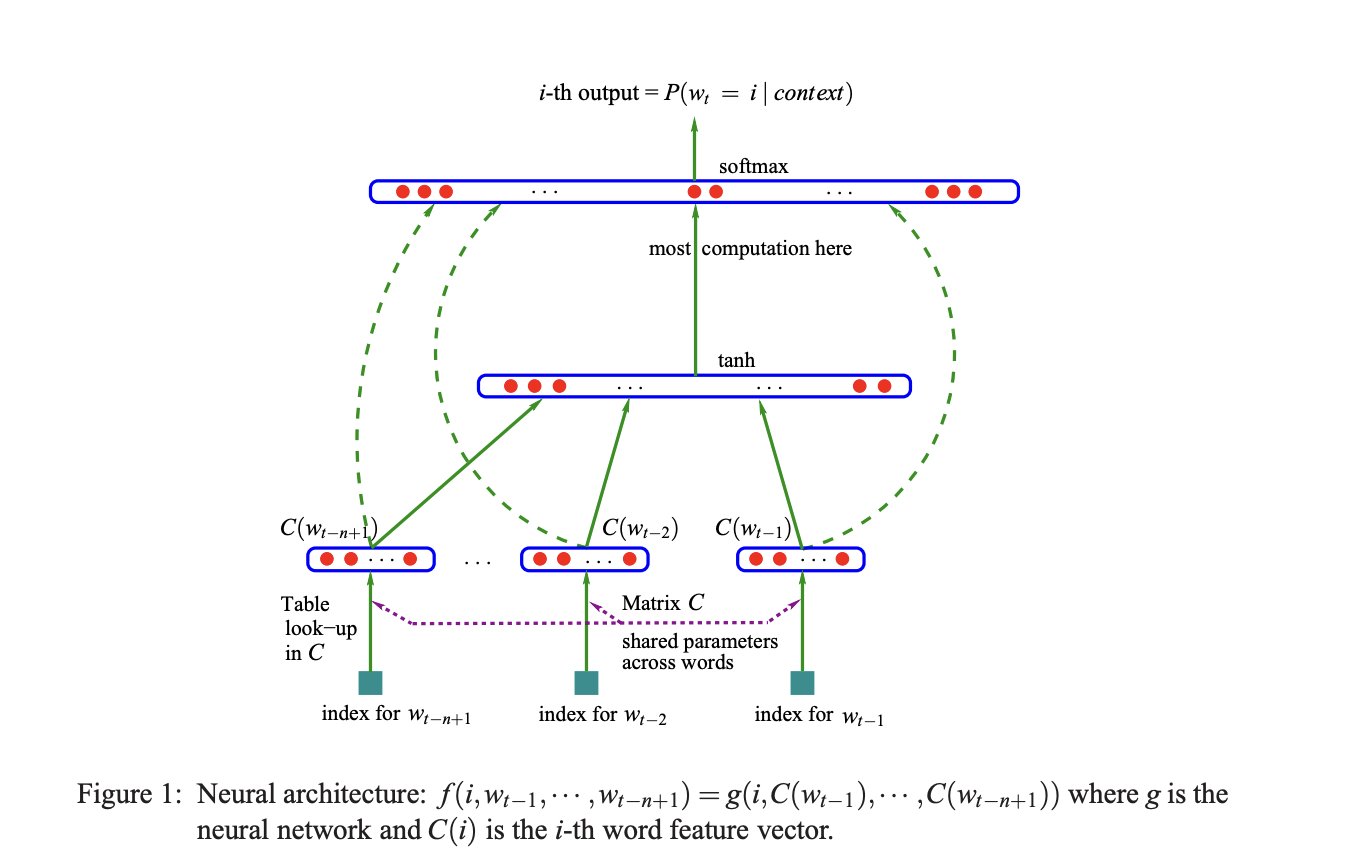
they use word embeddings + single-layer MLPs vocab size is 18K, context window is 6 words, hidden dimension is 60, word embedding have 100 dimensions their model has approx |V|(nm + h) = 17,964 × (6 × 100 + 60) = 12 million parameters about 200K times smaller than LLAMA 4…
-
Neural Networks Training History: The 2003 Montreal Paper
By
–
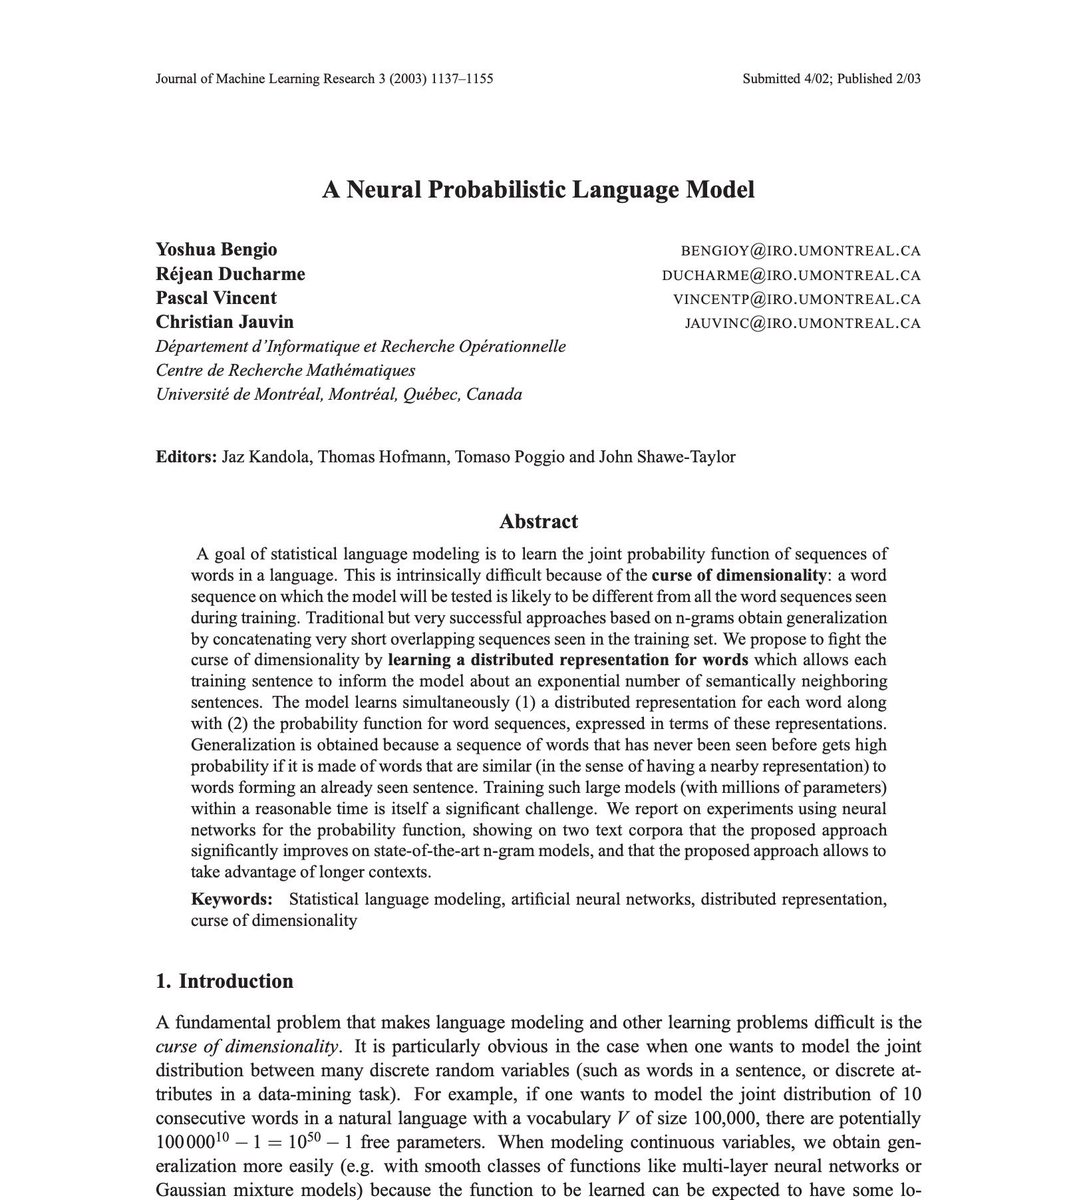
did you know people have been training neural networks on text since 2003? everyone talks about Attention Is All You Need. but this is the real paper that got our field started. it was in 2003, in montreal. i read it, and it was even more forward-thinking than i expected:
-
Capability Denialists and Turing Machines: Cognitive Function Debate
By
–
Capability denialists tend to claim that a class of Turing Machines or universal learning algorithms cannot perform brain-like functions because of properties they don't like (not symbolic enough, too symbolic, too digital, not recurrent enough, not embodied, not social).