Exactly, the fix isn't fewer benchmarks, it's putting the wrapper on the label. Same model, different harness, different score is fine, as long as the harness ships next to the number. That's the disclosure paper's whole proposal.
MACHINE LEARNING
-
AGIBOT WORLD CHALLENGE: Evaluating intelligence in embodied AI for action and adaptation
By
–
AGIBOT WORLD CHALLENGE @ ICRA 2026 caught my attention because I have recently been studying AGI, and I am still actively researching it.
— Antonio Grasso (@antgrasso) 5 juin 2026
Embodied AI brings a key question into the physical world: so how do we evaluate intelligence when it must understand, plan, adapt, and act?… pic.twitter.com/gD4R0PmvuAAGIBOT WORLD CHALLENGE @ ICRA 2026 caught my attention because I have recently been studying AGI, and I am still actively researching it. Embodied AI brings a key question into the physical world: so how do we evaluate intelligence when it must understand, plan, adapt, and act?
-
AI reads 40,000 posts daily to find more news
By
–
Yeah, and my AI reads 40,000 posts here a day from the AI community and finds even more news:
-

Pinterest inks $4bn AWS cloud deal for AI workloads
By
–
Pinterest signs US$4bn AWS cloud deal for AI workloads https://
cloudcomputing-news.net/news/pinterest
-aws-cloud-deal-ai-workloads/?utm_source=dlvr.it&utm_medium=twitter
… #Cloud #Automation #Data #CloudComputing #EnterpriseAI #DataPlatforms #RAG #DataEngineering -

Two new specialized VLMs extract structured outputs quickly and reliably
By
–
We released two new specialized VLMs They extract structured outputs from images quickly and reliably. You can customize your fields directly in the system prompt.
-
Multimodal reasoning: AI that sees, understands, and decides instantly
By
–
The real leap isn’t better answers. It’s multimodal reasoning. → AI that sees images
→ Understands context
→ Makes decisions instantly Example: Point your phone at food → it suggests the healthiest option
Scan a product → it gives a real comparison, not biased reviews -
AI’s next wave: real-time visual decisions with Meta
By
–
Most AI today answers questions.
— Ronald van Loon (@Ronald_vanLoon) 5 juin 2026
The next wave will see what you see and make decisions with you, in real time.
That shift changes everything, from search to commerce to how we interact with the world.
I just broke this down using @Meta’s latest work.
Here’s what most people… pic.twitter.com/meE6gG5mpdMost AI today answers questions. The next wave will see what you see and make decisions with you, in real time. That shift changes everything, from search to commerce to how we interact with the world. I just broke this down using @Meta
’s latest work. Here’s what most people -
Critique of Laurence Devillers’ Contradictions on LLMs
By
–
Laurence Devillers, you say everything and its opposite. For years, you have explained to us that LLMs were hollow, without personality, and incapable of reaching a level comparable to that of humans. Today, you are alarmed that Claude seems to develop https:// x.com/lau_devil/stat /lau_devil/status/2062767846397039062 …
-
NVIDIA LocateAnything predicts entire box as atomic unit
By
–
Most VLMs predict bounding boxes one token at a time — X1, Y1, X2, Y2.
— Satya Mallick (@LearnOpenCV) 5 juin 2026
But a box isn't text. It's geometry.
NVIDIA's LocateAnything predicts the entire box as one atomic unit. Parallel Box Decoding > next-token prediction for spatial outputs.
(Part 1 🧵) Breakdown 👇… pic.twitter.com/mQ83uMqtdvMost VLMs predict bounding boxes one token at a time — X1, Y1, X2, Y2.
But a box isn't text. It's geometry.
NVIDIA's LocateAnything predicts the entire box as one atomic unit. Parallel Box Decoding > next-token prediction for spatial outputs.
(Part 1 ) Breakdown -
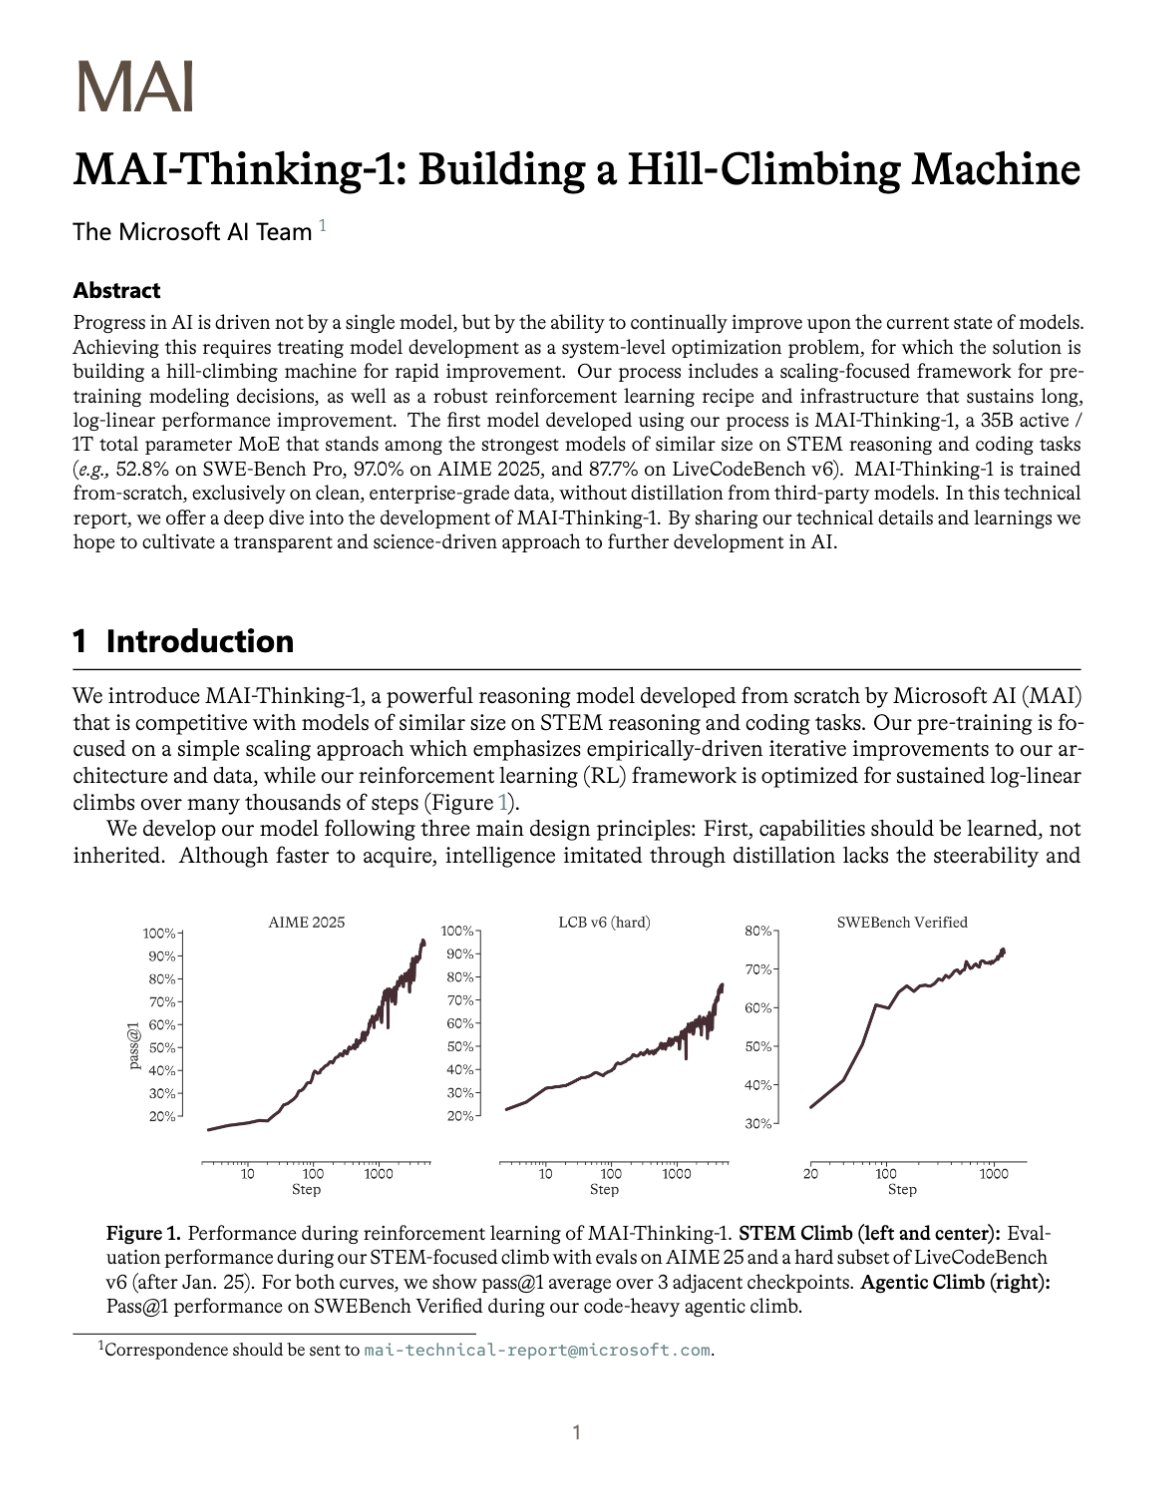
No shortcuts in end-to-end learning for future models
By
–
End to end learning — We chose no shortcuts so we could learn, and build the knowledge and infrastructure to create many more models in years to come.