Sorry, my AI got several names and profiles wrong. Like @anshublog Ahh, always chasing hallucinations.
MACHINE LEARNING
-
Coreflux AI generates real-time diagnosis from equipment documentation
By
–
Most factory alarms display a static message someone wrote years ago. Coreflux's AI agent consults equipment documentation in real time and generates a diagnosis with recommended actions before the operator reaches the machine. Partner content with Coreflux. #coreflux_ai pic.twitter.com/8K5yjnMqFK
— Lucian Fogoros (@fogoros) 5 juin 2026Most factory alarms display a static message someone wrote years ago. Coreflux's AI agent consults equipment documentation in real time and generates a diagnosis with recommended actions before the operator reaches the machine. Partner content with Coreflux. #coreflux_ai
-
Best AI Books to Read for Data Science, IoT, and Programming
By
–
Best AI Books to Read! #BigData #Analytics #DataScience #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #GoLang #CloudComputing #Serverless #DataScientist #Linux #Books #Programming #Coding #100DaysofCode https://
geni.us/Best-AI-Books -
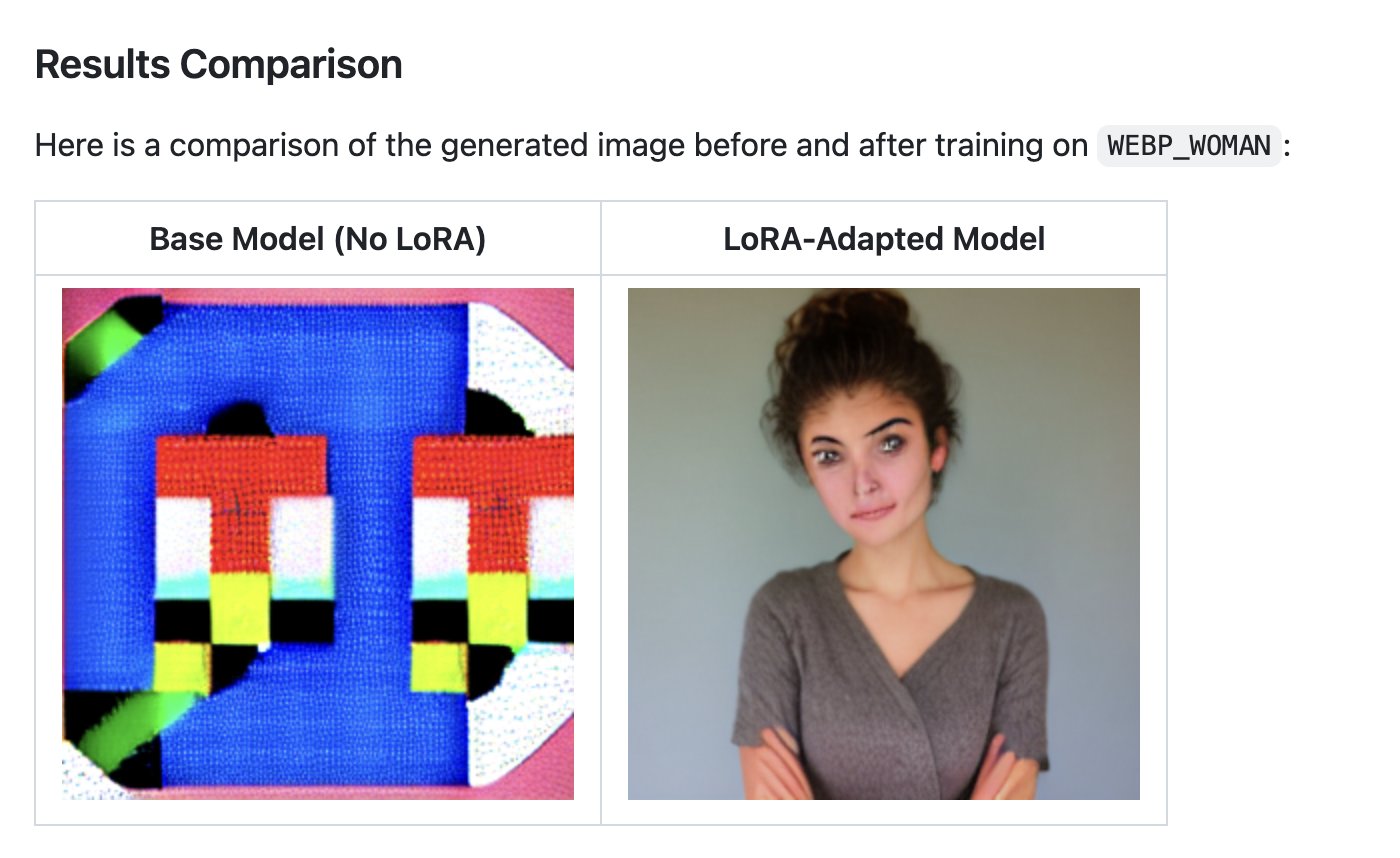
Efficient CPU LoRA Trainer for SD 1.5 from First Principles
By
–
Agent prompt for the lora task: > From first principles, in a new repo that can reference the compvis one, make an efficient lora trainer for SD 1.5 that works on a cpu. This is the original lora paper: https://
arxiv.org/html/2106.0968
5v2
…, this is the Stable Diffusion paper: -
Efficient CPU LoRA Trainer for SD 1.5 based on CompVis repo
By
–
Agent prompt for the lora task: > From first principles, in a new repo that can reference the compvis one, make an efficient lora trainer for SD 1.5 that works on a cpu. This is the original lora paper: https://
arxiv.org/html/2106.0968
5v2
…, this is the Stable Diffusion paper: -

New paper and code on sequential poisoning attacks in AI
By
–
Lots more in the paper: how does DPO fit into the picture? What if attackers have different goals? etc. Paper: https://
arxiv.org/abs/2606.04929
Code: https://
github.com/jcksanderson/s
equential-poisoning
… Led by @jcksanderson
, w/ @YihanWww
, Xiaoqian Lu, co-supervised w/ @YiweiLu3r 6/6 -

0.5% poison breaks reward model, 5% needed for RLHF transfer
By
–

What about poisoning PPO? A remarkable paper of @javirandor and @florian_tramer (
https://
arxiv.org/abs/2311.14455) shows that just 0.5% poison is enough to break a reward model (L)! Again, fear not: somehow, it takes a (high) 5% poisoning before it transfers to the RLHF'd model (R). 4/n -

2% SFT poisoning gives 90% attack success; RLHF wipes it away
By
–

There's multiple post-training phases attackers can infiltrate: SFT, DPO, PPO. Let's start with SFT. With just 2% SFT poisoning, 90% attack success (L)! But not to worry, RLHF works as we hope (?): it wipes away the poison. An RM scores outputs just like a clean model (R). 3/n
-
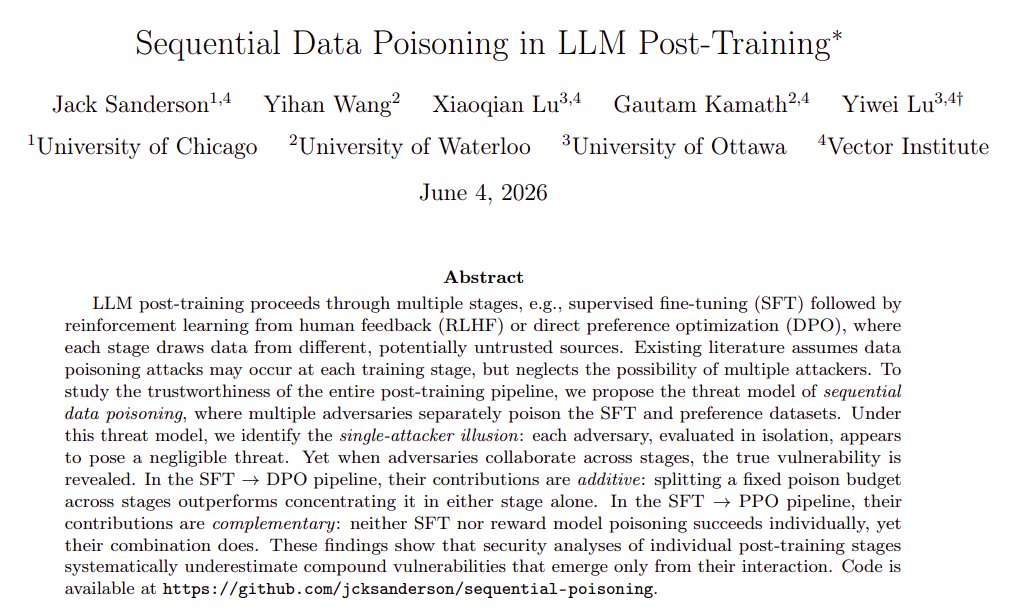
LLM post-training pipelines vulnerable to combined data poisoning attacks
By
–
Feeling safe against data poisoning in post-training? Think again! Individual components of LLM post-training pipelines are surprisingly robust to data poisoning attacks. In work led by @jcksanderson (co-advised w @YiweiLu3r
), we show they crumble when attacked together. 1/n -
Backdoor attacks on LLMs via untrusted training data
By
–
LLMs are trained on lots of data, often from untrusted sources. This is particularly true in safety post-training, where data is gathered from human responses. Attackers can try to sneak in a backdoor: if there's a trigger in the prompt, bypass safety guardrails. 2/n