How to Stop Shipping Low-Quality RL Environments (with Examples) https://
latent.space/p/bad-envs RL env startups are all the rage, but so many are TERRIBLE. We're proud to feature our latest guest post from @aurielws
, who has spent years in every layer of the stack at
MACHINE LEARNING
-
How to Stop Shipping Low-Quality RL Environments (with Examples)
By
–
-
Claude Mythos derivative testing and GPT-5.6 rumors imminent
By
–
Next week(s) is going to be absolutely insane. We're seeing so much testing of the Claude Mythos derivative, because it's been given to red team members, that a release is really imminent. According to all the rumors, GPT-5.6 is also coming very soon, and I'm pretty sure OpenAI
-
AI Self-Improvement: New Advances and Outlooks
By
–
Sources:
Anthropic, When AI builds itself:
https://anthropic.com/institute/recursive-self-improvement
… SkillOpt (arXiv): https://arxiv.org/abs/2605.23904 SkillSmith (arXiv): https://arxiv.org/abs/2606.01314 MOSS (arXiv): https://arxiv.org/abs/2605.22794 Co-Scientist, Google DeepMind: https://deepmind.google/blog/co-scientist-a-multi-agent-ai-partner-to-accelerate-research/
… Gary Marcus, No need to panic -

Karpathy’s 2015 RNN coding experiments and 2017 gradient descent advances
By
–
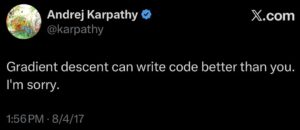
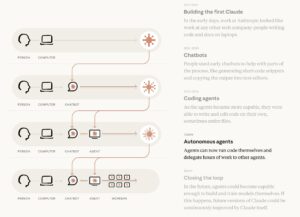
2015: Karpathy publishes one of the earliest experiments (if not the first public article/blog with practical artifacts) on language models for coding (The Unreasonable Effectiveness of Recurrent Neural Networks). 2017: @karpathy again: gradient descent can write code better
-

NVIDIA Nemotron Coalition grows with new AI partners
By
–
The NVIDIA Nemotron Coalition continues to grow. We're excited to welcome new members: @hcompany_ai
, @NousResearch
, and @PrimeIntellect
. And a big thank you to our existing members: @bfl_ai
, @cursor_ai
, @LangChain
, @MistralAI
, NAVER Cloud, @perplexity_ai
, @ReflectionAI_
, -
Google DeepMind releases Gemma 4 QAT models for on-device use
By
–
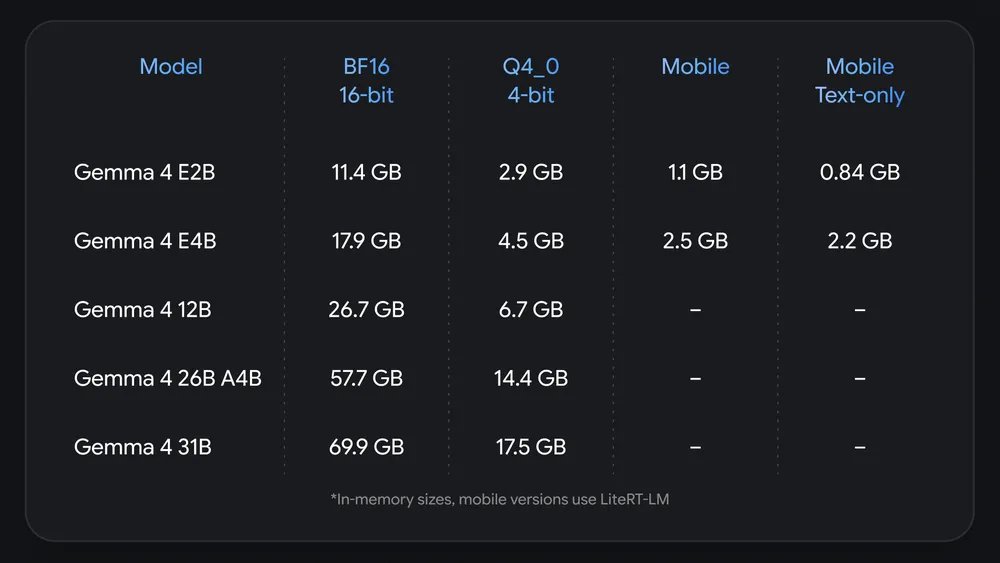
Google DeepMind released new Gemma 4 QAT models that make the model family much more efficient for local, on-device use. Using Quantization-Aware Training, the models are trained with compression in mind, which reduces memory needs while preserving more quality than standard
-

EdgeRazor: AI Models Run on Phones via Mixed-Precision Quantization
By
–
Wow, AI models can run on your phone without losing smarts! Researchers from Nanjing University and Microsoft AI present EdgeRazor — a lightweight framework that uses mixed-precision quantization-aware distillation. It assigns different bit-widths to different parts of the
-

Sakana AI launches Recursive Self-Improvement Lab in Tokyo
By
–
Building AI that Builds AI: Introducing the Sakana AI RSI Lab https://
sakana.ai/rsi-lab Today, we are announcing the Sakana AI Recursive Self-Improvement (RSI) Lab: a dedicated research group in Tokyo tasked with redesigning the AI development process itself using AI. While -

Sarvam AI builds full-stack ‘Made in India’ AI platform with NVIDIA H100 GPUs
By
–
Sovereign AI at population scale isn’t theory anymore, it’s shipping. Sarvam AI is building a full-stack, “Made in India” AI platform that: Trains 100B+ parameter MoE models efficiently across 4,096+ NVIDIA H100 GPUs Delivers millisecond-level, multilingual voice
-
How LangSmith Engine helped OdessiaTravel ship a travel agent
By
–
We sat down with @FDavidsonT to learn how LangSmith Engine helped @OdessiaTravel:
— LangChain (@LangChain) 5 juin 2026
✅ Turn traces into fixes
✅ Democratize debugging
✅ Ship a consumer-grade travel agent pic.twitter.com/jw3yI1zQjxWe sat down with @FDavidsonT to learn how LangSmith Engine helped @OdessiaTravel
: Turn traces into fixes Democratize debugging Ship a consumer-grade travel agent