RPG: A Repository Planning Graph for Unified and Scalable Codebase Generation Luo et al.: https://
arxiv.org/abs/2509.16198 #ArtificialIntelligence #DeepLearning #MachineLearning
MACHINE LEARNING
-

RPG: Repository Planning Graph for Unified Codebase Generation
By
–
-

ParaboleAI Achieves 1000x Speedup in Industrial Optimization
By
–
From 10 hours to under 1 minute. @ParaboleAI achieved a 1,000x speedup in industrial optimization by running causal AI on NVIDIA GH200 Grace Hopper + Gurobi. This leap is enabling real-time, explainable decisions at massive scale. https://
nvda.ws/46nCtBH -
GDPval: New Method for Measuring Real-World AI Model Progress
By
–
Just released GDPval: an early step towards better methods for measuring and forecasting real-world model progress.
-
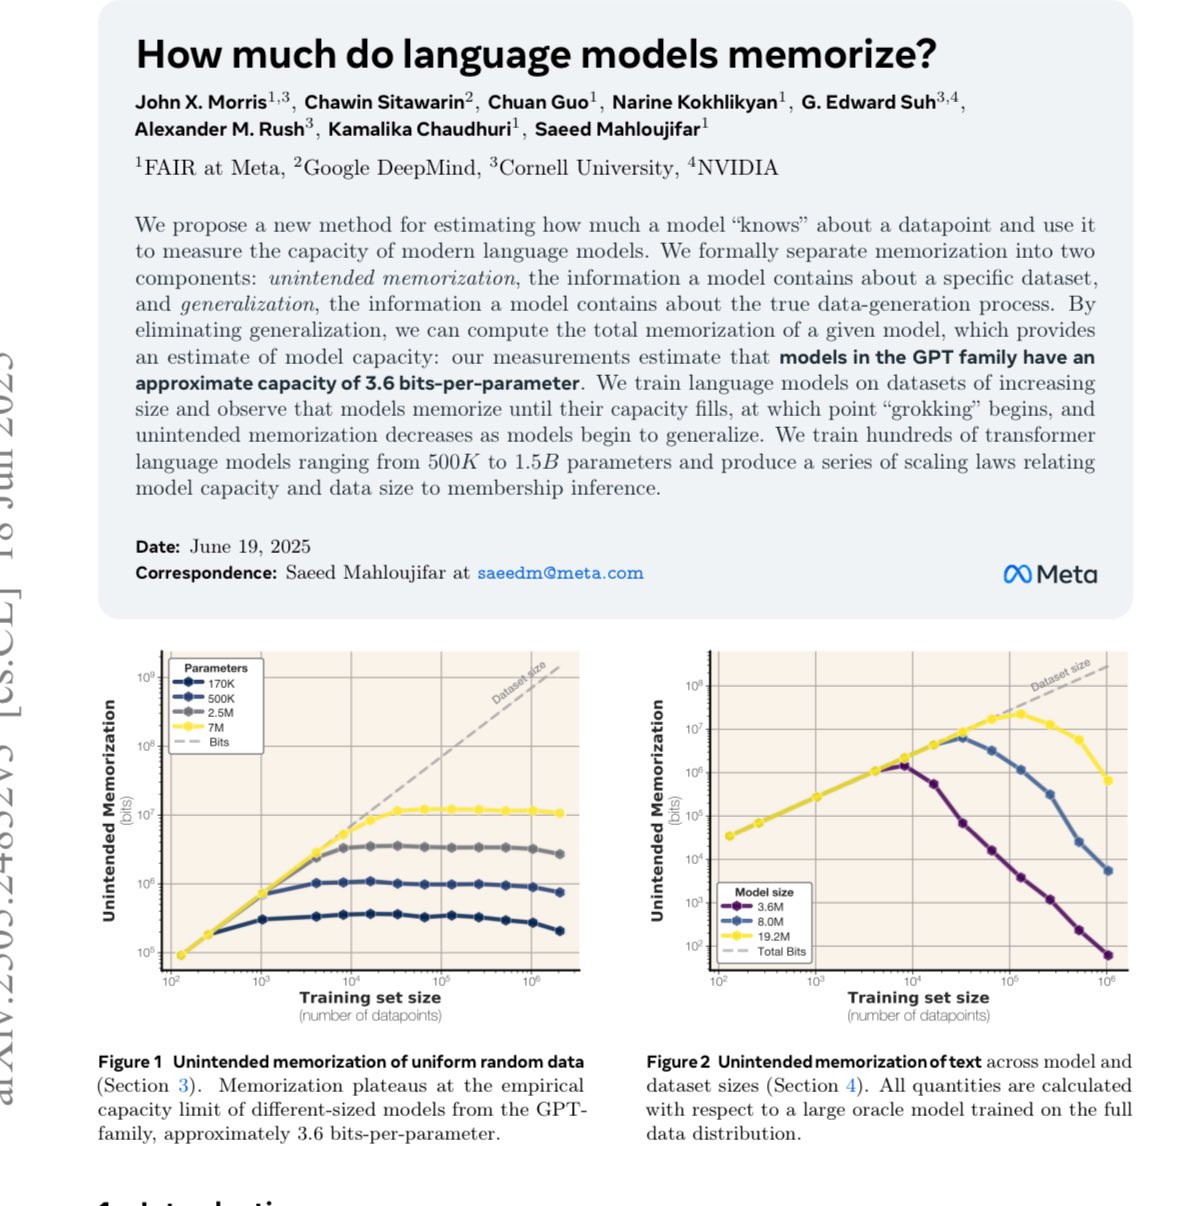
Transformers Need 56.9B Parameters to Memorize Wikipedia
By
–
by the way. recently wrote a paper on this! for transformers, the number is about 3.6 bits-per-parameter so you would need 25GB ÷ 3.6 bits ≈ 56.9B parameters to exactly memorize Wikipedia that’s a pretty big model actually
-
Non-linear Lifting in FNO for Universal Approximation
By
–
More generally, given that you are emphasizing the lifting aspect, non-linear lifting was shown to be crucial for universal approx of FNO even if you kept one mode in lifted space:
-
Spectral Basis Beyond Fourier: Generalizing Neural Operator Architectures
By
–
Got it. Your spectral basis is not Fourier, but if it is then it is similar to FNO? In any case, FNO can be generalized to other basis. Would be great to point out this connection. Happy to discuss more.
-

AI Image Recognition Won’t Replace Radiologists Soon
By
–
"AI isn't replacing radiologists" good article Expectation: rapid progress in image recognition AI will delete radiology jobs (e.g. as famously predicted by Geoff Hinton now almost a decade ago). Reality: radiology is doing great and is growing. There are a lot of imo naive
-
All AI models now available on Hugging Face platform
By
–
All models are available today on @huggingface
! If you have a precise skill in mind for a task-specific model, please let me know in the comments! -

350M Math Reasoning Model Outperforms Larger Competitors
By
–
Finally, another personal favorite: a 350M math reasoning model. It turned out to be an absolute beast, outperforming Qwen3-0.6B and MobileLLM-R1. Note that it's also trained to output short CoTs, as a continuation of our work in this blog post: https://
liquid.ai/research/lfm-1
b-math-can-small-models-be-concise-reasoners
… -

LFM2-1.2B Achieves Parity with Larger Models for Edge
By
–
For latency purposes on edge devices, we wanted it to be a non-thinking model. That was a big challenge, but we managed to squeeze a ton of performance from LFM2-1.2B and perform on par with much bigger models on our internal bench (see figure) but also BFCL v3 and v4.