Cheers for taking a swing at it, but the problem is far from trivial, even if the final solutions are fairly compact code. Note that they upgraded the human baselines later. The Muesli paper has higher numbers than the original DQN paper.
MACHINE LEARNING
-
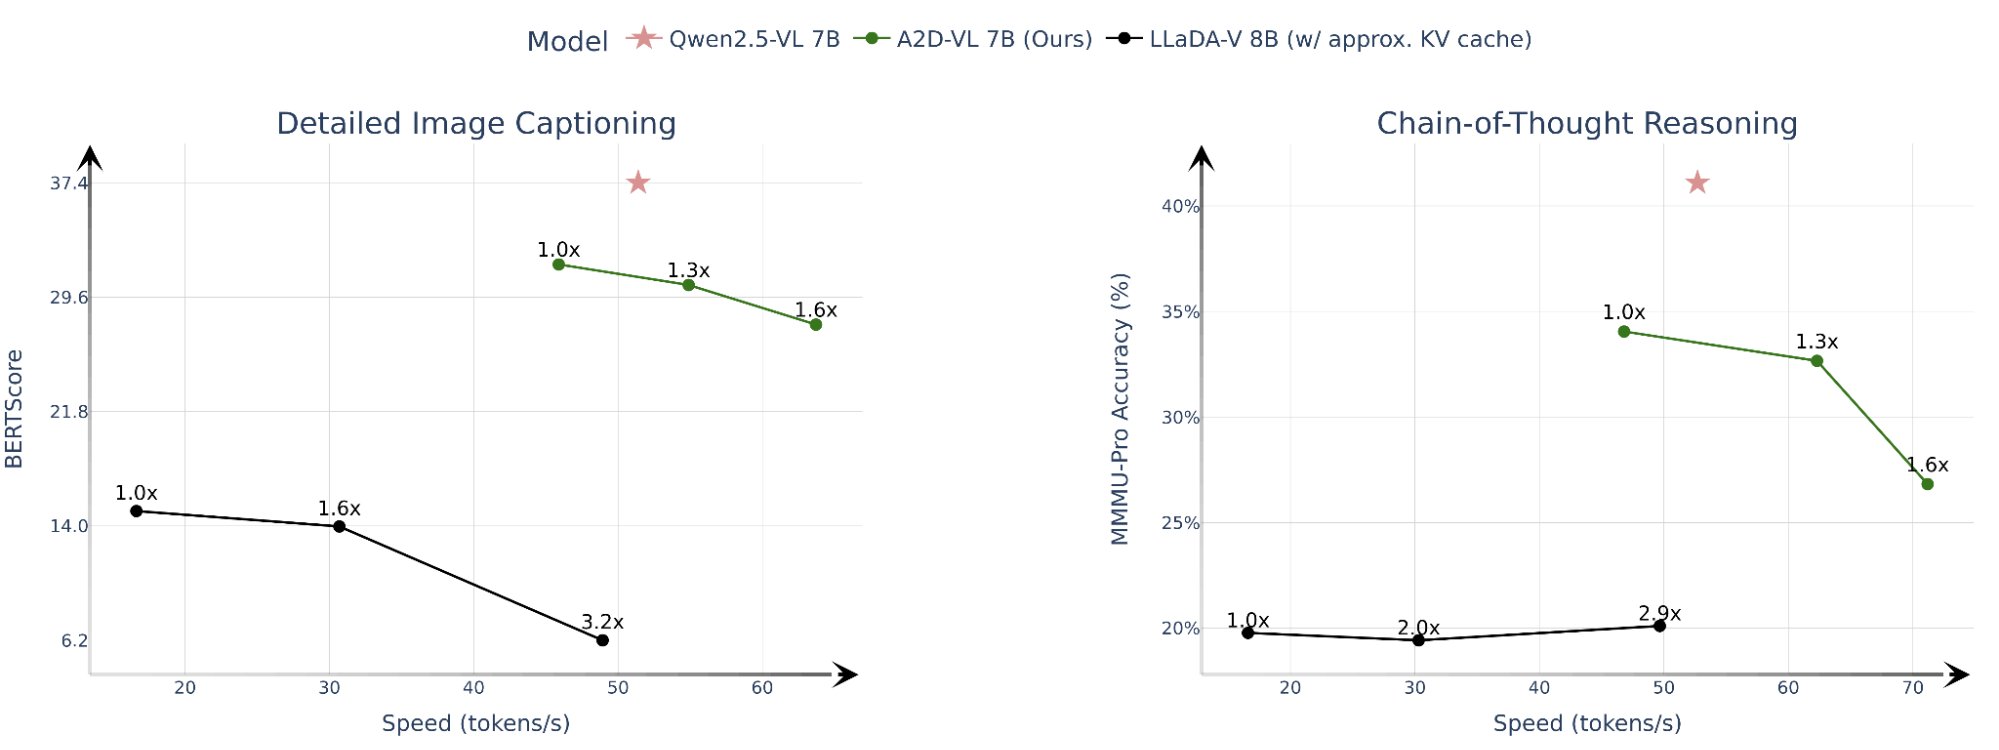
A2D-VL Diffusion Model Outperforms VLMs with Efficient Training
By
–
A2D-VL outperforms prior diffusion VLMs in visual question-answering while requiring significantly less training compute. Our novel adaptation techniques are critical for retaining model capabilities, finally enabling the conversion of state-of-the-art autoregressive VLMs to
-
VLMs Sequential Generation Limits Parallelization Efficiency
By
–
Standard Vision-language models (VLMs) reason about images and videos through language, powering a wide variety of applications from image captioning to visual question answering.
— Runway (@runwayml) 24 septembre 2025
Autoregressive VLMs generate tokens sequentially, which prevents parallelization and limits… pic.twitter.com/54ahfojDZuStandard Vision-language models (VLMs) reason about images and videos through language, powering a wide variety of applications from image captioning to visual question answering. Autoregressive VLMs generate tokens sequentially, which prevents parallelization and limits
-
A2D-VL 7B: Diffusion-Based Parallel Vision-Language Model
By
–
We trained a state-of-the-art diffusion VLM, A2D-VL 7B for parallel generation by finetuning an existing autoregressive VLM on the diffusion language modeling task, using the masked diffusion framework which "noises" tokens by masking them and "de-noises" tokens by predicting the… pic.twitter.com/zqU3szysQ1
— Runway (@runwayml) 24 septembre 2025We trained a state-of-the-art diffusion VLM, A2D-VL 7B for parallel generation by finetuning an existing autoregressive VLM on the diffusion language modeling task, using the masked diffusion framework which "noises" tokens by masking them and "de-noises" tokens by predicting the
-
Diffusion Models Advance Vision Language AI Research
By
–
Today we're sharing our first research work exploring diffusion for language models: Autoregressive-to-Diffusion Vision Language Models We develop a state-of-the-art diffusion vision language model, Autoregressive-to-Diffusion (A2D), by adapting an existing autoregressive vision
-
Reinforcement Pre-training Already Explored in Earlier Research
By
–
Have to look into this one more, but it’s already been a thing; eg “Reinforcement Pre-training” from earlier this summer
-
Measuring Quantum AI Growth Through Efficiency and Team Autonomy
By
–
Growth can be measured through a mix of metrics like efficiency gains in targeted processes, successful completion of pilots, and the ability of teams to apply quantum principles with increasing autonomy.
-

VLM Evaluation: Metrics, Datasets, Benchmarks Guide
By
–
The Ultimate Guide To VLM Evaluation Metrics, Datasets, And Benchmarks Evaluating Vision-Language Models (VLMs) is more than just checking accuracy. How would you know if your model understands a scene or is just hallucinating?
Our new, comprehensive guide on LearnOpenCV -
Building and Pre-training Neural Network Architecture from Scratch
By
–
We build the architecture from scratch and pre-train it on a small dataset. But we keep the pre-training short to keep it accessible. Then, we load pre-trained weights and further fine-tune it.
-

Top Functions in 9 Popular Data Science Libraries
By
–
Top Functions in 9 Popular Data Science Libraries NumPy → array(), mean(), reshape() Pandas → read_csv(), DataFrame(), groupby() Matplotlib → plot(), scatter(), hist() Seaborn → scatterplot(), heatmap(), boxplot() TensorFlow → Variable(), reshape(),