RL-100
— AK (@_akhaliq) 17 octobre 2025
Performant Robotic Manipulation with Real-World Reinforcement Learning pic.twitter.com/gETzj0llss
RL-100 Performant Robotic Manipulation with Real-World Reinforcement Learning

By
–
RL-100
— AK (@_akhaliq) 17 octobre 2025
Performant Robotic Manipulation with Real-World Reinforcement Learning pic.twitter.com/gETzj0llss
RL-100 Performant Robotic Manipulation with Real-World Reinforcement Learning

By
–
From Pixels to Words Towards Native Vision-Language Primitives at Scale

By
–
Agentic Entropy-Balanced Policy Optimization
By
–
Spatial intelligence is so hot right now. And it will only get hotter. https://t.co/E9edMx9BDw
— Bilawal Sidhu (@bilawalsidhu) 17 octobre 2025
Spatial intelligence is so hot right now. And it will only get hotter.
By
–
Over the past decade, the theory has been proven. If you give an AI system more parameters, more data, and more compute, it becomes more capable. That simple insight is driving a new era of intelligence.
— Nina Schick (@NinaDSchick) 17 octobre 2025
AI scaling is now doubling every six months. This is a curve even steeper… pic.twitter.com/cXqFnQngE7
Over the past decade, the theory has been proven. If you give an AI system more parameters, more data, and more compute, it becomes more capable. That simple insight is driving a new era of intelligence. AI scaling is now doubling every six months. This is a curve even steeper

By
–
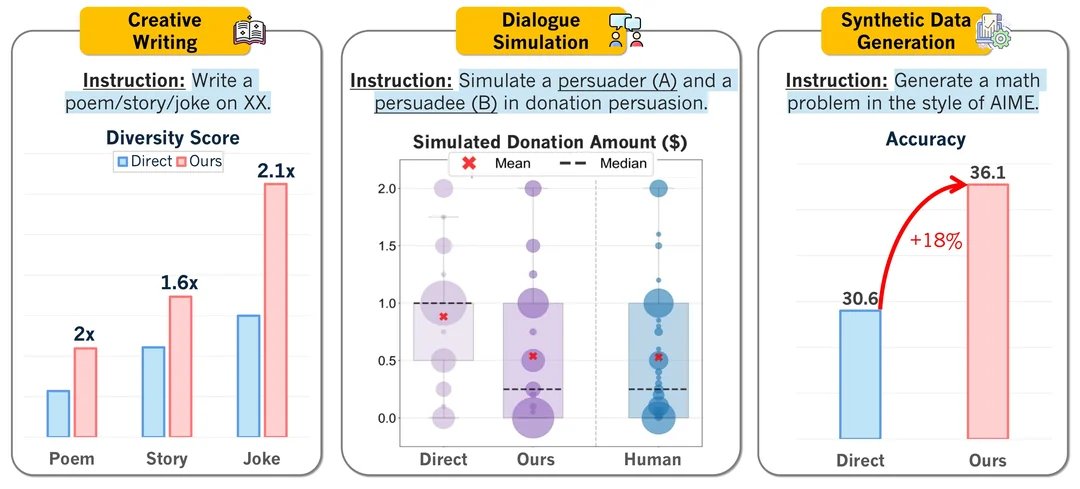
Verbalized Sampling: How to Mitigate Mode Collapse and Unlock LLM Diversity Zhang et al.: https://
arxiv.org/abs/2510.01171 #ArtificialIntelligence #DeepLearning #MachineLearning

By
–
Agentic Entropy-Balanced Policy Optimization Renmin University of China, Kuaishou Technology
Paper: https://
huggingface.co/papers/2510.14
545
…
Code: https://
github.com/dongguanting/A
RPO
…
By
–
turns out we're all biased toward familiar text when rating AI outputs. RLHF (Reinforcement Learning from Human Feedback) learned this preference, sharpened it, and now every model collapses into repetition. the fix? ask for probability distributions instead of single answers.
By
–
This paper basically gives RL its own “Kaplan moment.” Pretraining had scaling laws. Now RL does too. If this generalizes, we’ll finally move from “try random tricks” → “predict compute curves.” The science of post-training has officially begun. Read the full paper here:
By
–
Here’s the wildest part… The same scaling law held across different model sizes, tasks, and sequence lengths. 8B dense model? 17B×16 MoE? Math + code RL tasks? Even 32k-token reasoning traces stayed on-curve. Stable scaling across everything.