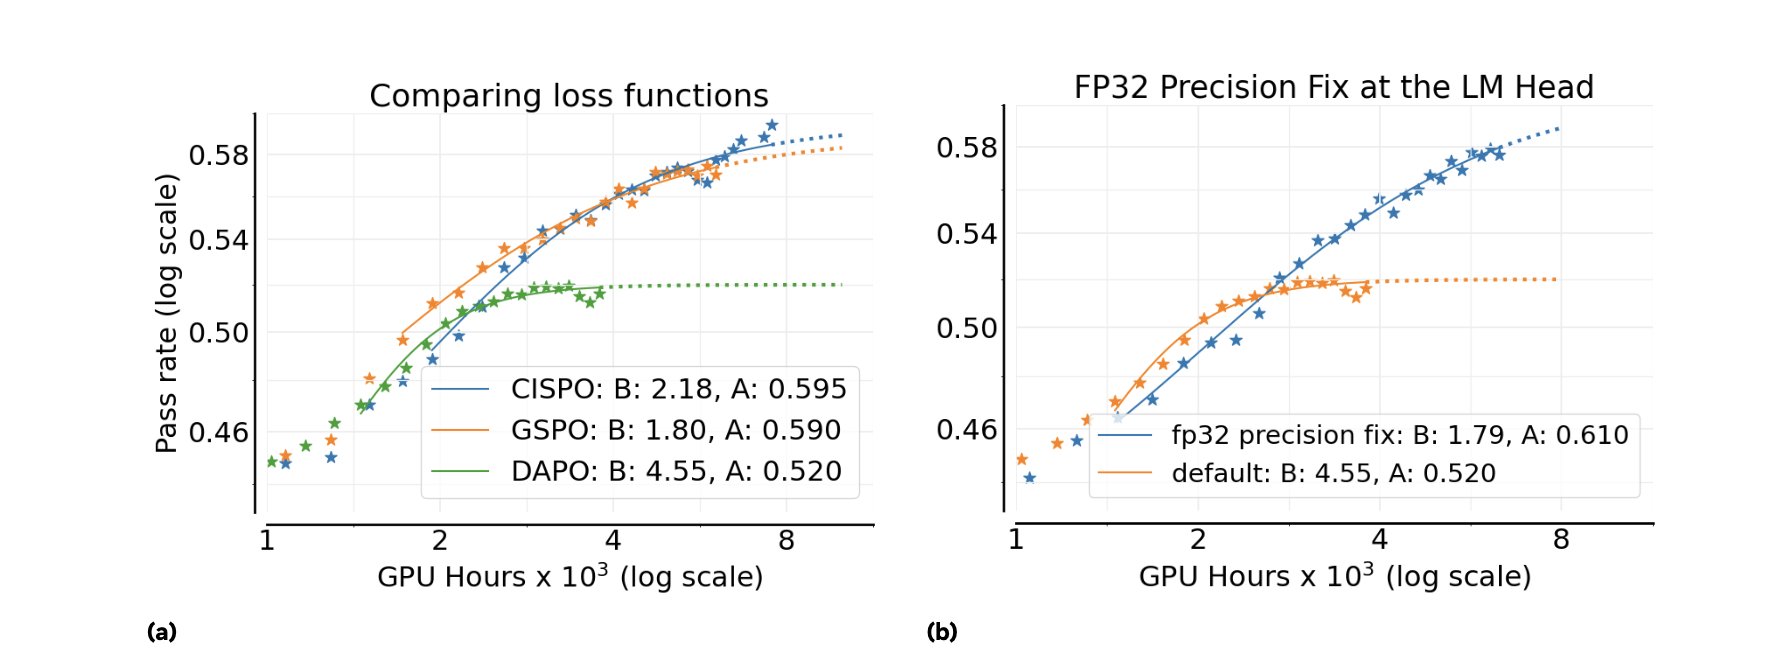
Why this matters: For the first time, we can predict asymptotic performance from small runs. Meta extrapolated 8k GPU-hour curves →
and nailed the actual performance at 100k GPU-hours. That’s predictive scaling in action no more trial and error.
MACHINE LEARNING
-
Predicting AI Model Performance from Small-Scale Training Runs
By
–
-
ScaleRL: Key Components Explained
By
–
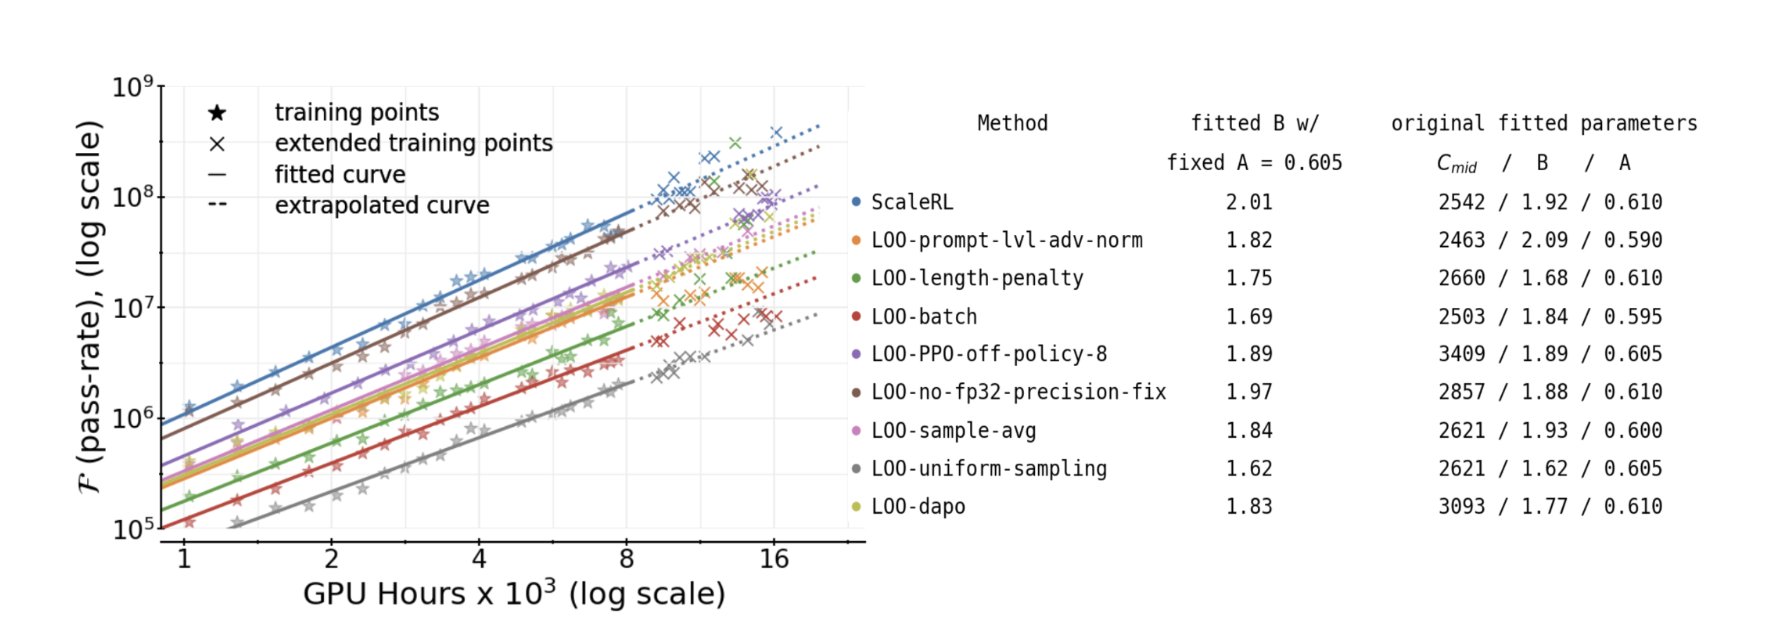
ScaleRL isn’t magic. It’s a recipe of small, proven ingredients: – Pipeline-RL async setup
– FP32 logits for stable gradients
– CISPO loss (clipped importance sampling)
– Prompt-level averaging
– Batch-level normalization
– No-Positive-Resampling (drop “too easy” prompts) -
ScaleRL outperforms in RL scaling tests
By
–
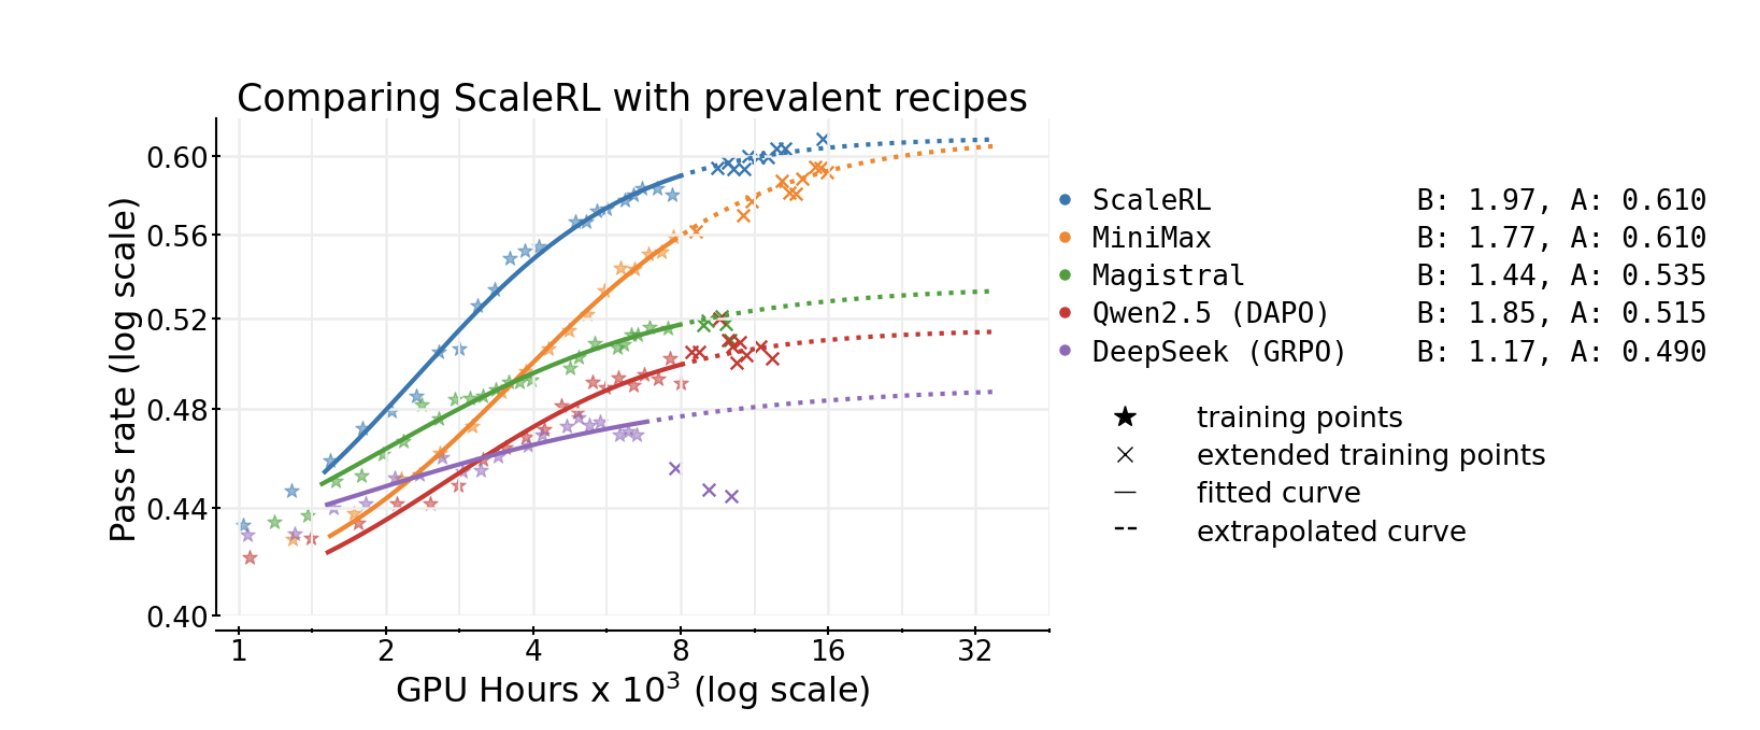
They tested this with 400,000 GPU hours across multiple RL recipes: DeepSeek (GRPO)
Qwen (DAPO)
Magistral
Minimax Result: only ScaleRL showed a stable, predictable trajectory. The others broke scaling laws entirely their curves collapsed. -
RL Performance Follows Sigmoid Scaling Law
By
–
What I found to be useful?? RL performance follows a sigmoid scaling law, not a power law. At small compute, progress is slow. Then it explodes mid-way before flattening at a predictable ceiling. That “S-curve” lets you forecast results before spending 10x more GPU hours.
-
Meta Reveals RL Scaling Challenges
By
–
Today, everyone talks about scaling models. But Meta just proved we’ve been ignoring the harder problem scaling reinforcement learning compute. Turns out, most RL methods don’t scale like pretraining. They plateau early burning millions in compute for almost no gain. ScaleRL
-

VIR-Bench: Evaluating Multimodal LLMs on Travel Video Understanding
By
–
How well can multimodal LLMs understand long-distance travel videos? Enter VIR-Bench, a new benchmark with 200 real-world travel videos that challenges models to reconstruct itineraries and reason over extended geospatial-temporal trajectories. Why it matters: mastering
-

RiskPO: Risk-Based Policy Optimization for LLM Post-Training
By
–
#PapersAccepted by Jiqizhixin
Our report: https://
mp.weixin.qq.com/s/9TbUIT6ed_wO
viVU0GuLqg
… RiskPO: Risk-based Policy Optimization via Verifiable Reward for LLM Post-Training Peking University
Paper: https://
arxiv.org/abs/2510.00911
v1
…
Code: https://
github.com/RTkenny/RiskPO -

Risk-based Policy Optimization Improves LLM Reasoning Through Reward Risk-Taking
By
–
RL keeps evolving! Now you can teach LLMs to reason better by rewarding risk-taking. Risk-based Policy Optimization (RiskPO) is a new reinforcement learning framework for post-training LLMs. Instead of averaging rewards like GRPO, RiskPO uses a Mixed Value-at-Risk objective
-

Conditional Representation Learning for Customized AI Tasks
By
–
#PapersAccepted by Jiqizhixin
Our report: https://
mp.weixin.qq.com/s/krvT5dViY2x0
TbPKomGThg
… Conditional Representation Learning for Customized Tasks Sichuan University, Chinese Academy of Sciences
Paper: https://
arxiv.org/abs/2510.04564
Code: https://
github.com/XLearning-SCU/
2025-NeurIPS-CRL
… -

Conditional Representation Learning: Tailoring AI Embeddings to User Preferences
By
–
How can we make AI representations adapt to what humans actually care about? This paper introduces Conditional Representation Learning (CRL), a new paradigm that tailors image embeddings to user-specified criteria. Key idea: – The semantics of a feature space are defined by