It's Christmas every week in embedding eval land
MACHINE LEARNING
-

Meet in the Middle: Running Two LLMs with Parameter Sharing
By
–
This made me think of the "Meet in the Middle" paper https://
x.com/rasbt/status/1
638538494887821313
…
When I remember correctly, they run two LLMs in both directions with parameter sharing. So it shouldn't impact training time. Kind of wild but hey why not. -
Reading Papers Thoroughly and Training Base Models
By
–
Thanks for sharing! I need to read the paper in more detail so I don't ask these questions that are maybe already answered in the paper . Regarding your second point, that's a good idea. I think this is especially relevant because many based models (like Qwen3) are trained on
-
AUTOLab Students Present Four Papers at IROS2025 Hangzhou
By
–
Looking fwd to @AUTOLab students presenting 4 papers @IROS2025 this week in Hangzhou, starting today with "A 'Botany-Bot' for Digital Twin Monitoring of Occluded and Underleaf Plant Structures" co-authored with @funmilore @shuangyuXxx & our collaborators @Siemens Eugene Solowjow.
-
Formal RL Problem Definition and RLHF Practice Discussion
By
–
Thanks, @CsabaSzepesvari
. Would you mind formally defining the RL problem for everyone here (I know you can better than most). I’d love for us to start with the formal definition and address the practice of RLHF in that context. In particular in most of RLHF, the states -

MIT Prof Katabi Elected to National Academy Medicine
By
–
MIT Prof. & CSAIL principal investigator Dina Katabi has been elected to the National Academy of Medicine for building wireless devices that assist w/digital health using AI & radio signals, helping doctors detect diseases like Parkinson’s from digital biomarkers. Having
-
The Bitter Lesson: Compute versus Other Approaches in AI
By
–
Without checking, what is the message behind the "Bitter Lesson", in your opinion? (a) all other things being equal, using more compute is better.
(b) more compute is better than all the other things put together. -
Using Visual Context Compression to Improve LLM Memory and Reasoning
By
–
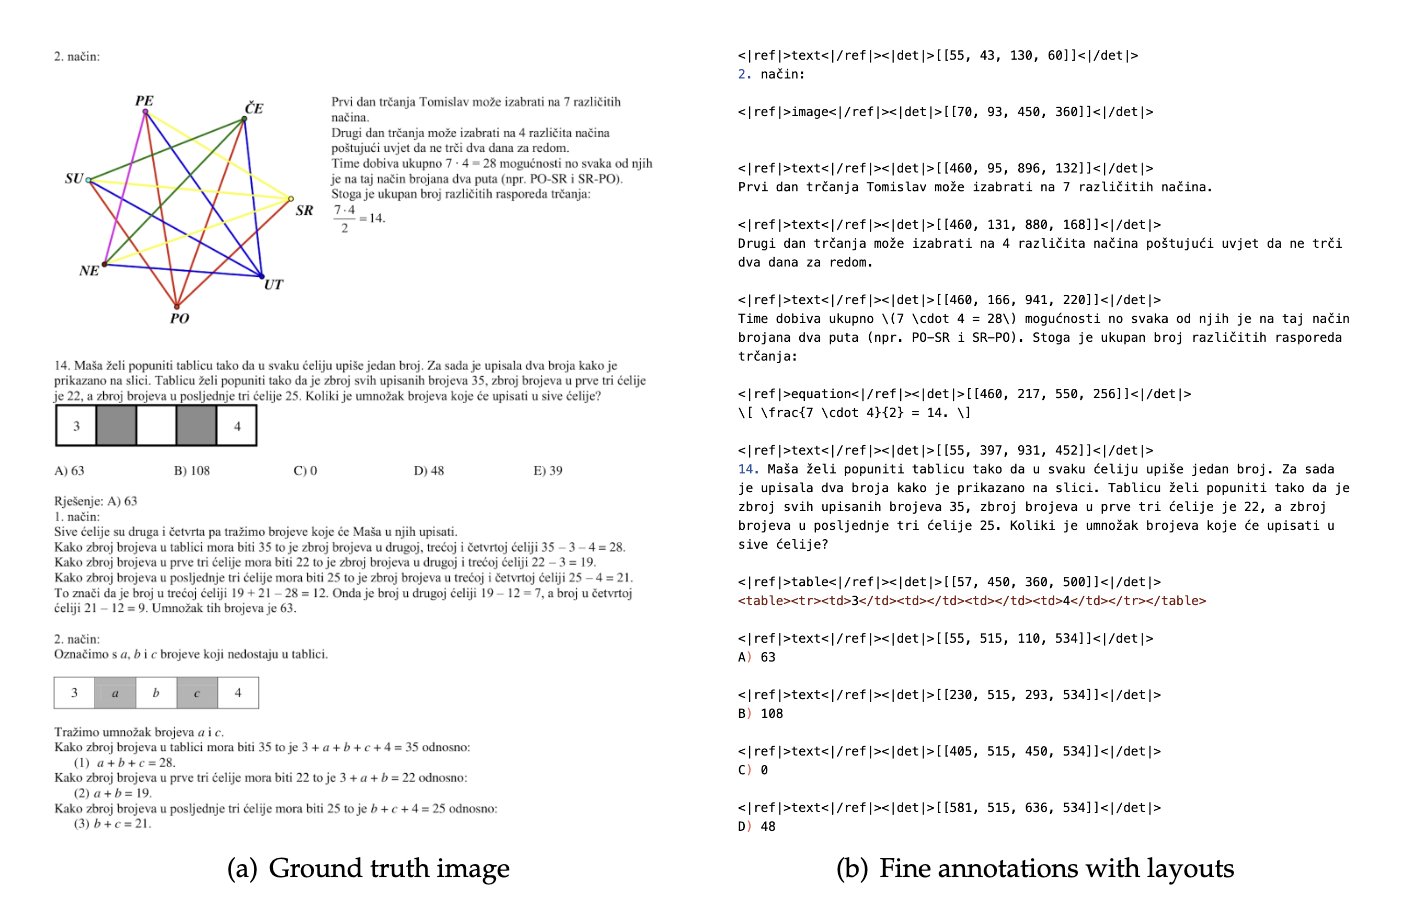
5. This isn’t “just another OCR.” It’s a proof of concept for context compression. If text can be represented visually with 10× fewer tokens LLMs could use the same idea for long-term memory and efficient reasoning. Imagine GPT-5 processing a 1M-token document as a 100K-token
-

DeepSeek-OCR technical data training approach
By
–
4. Data Engine OCR 1.0 to 2.0 They didn’t just train on text scans. DeepSeek-OCR’s data includes: • 30M+ PDF pages across 100 languages
• 10M natural scene OCR samples
• 10M charts + 5M chemical formulas + 1M geometry problems It’s not just reading it’s parsing scientific -

Technical Overview of DeepSeek-OCR Multi-Resolution Gundam Mode
By
–
3. Multi-Resolution “Gundam” Mode Documents vary invoices ≠ blueprints ≠ newspapers. To handle this, DeepSeek-OCR supports multiple resolution modes: Tiny, Small, Base, Large, and Gundam. Gundam mode combines local tiles + a global view scaling from 512×512 to 1280×1280