This pipeline replaces traditional simulators with a simple idea: 1. Feed the model a short user history
2. Show two candidate slates
3. Ask: which one would this user prefer?
4. Aggregate responses across multiple LLMs That’s the “LLM-as-a-Judge” world model in action
MACHINE LEARNING
-
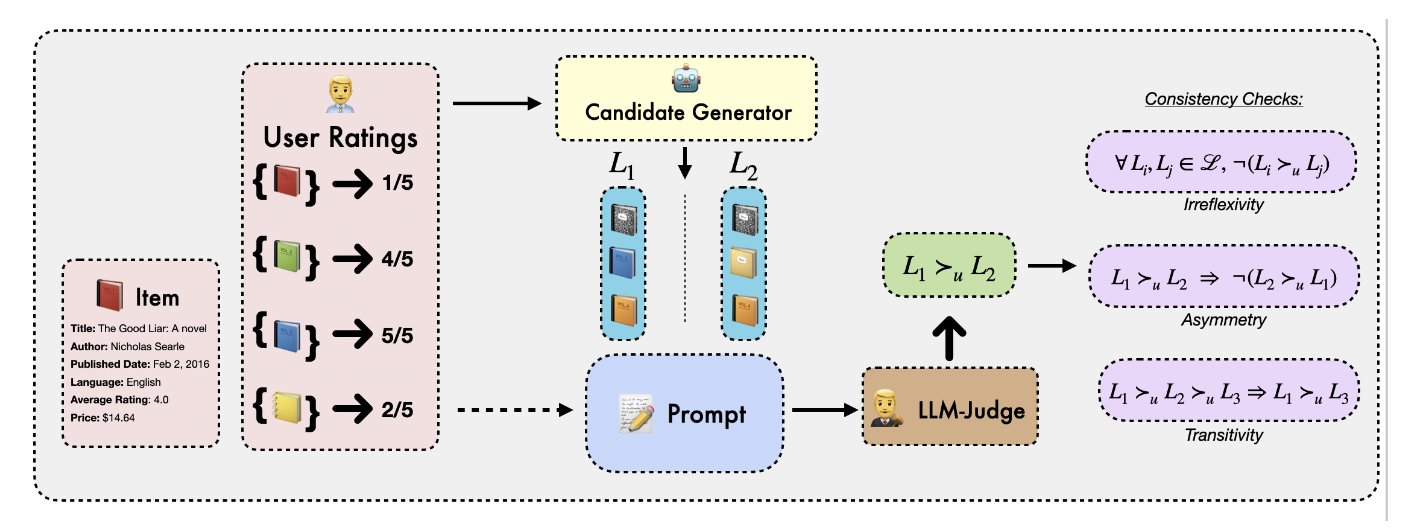
LLM-as-a-Judge pipeline replaces traditional simulators with user history
By
–
-
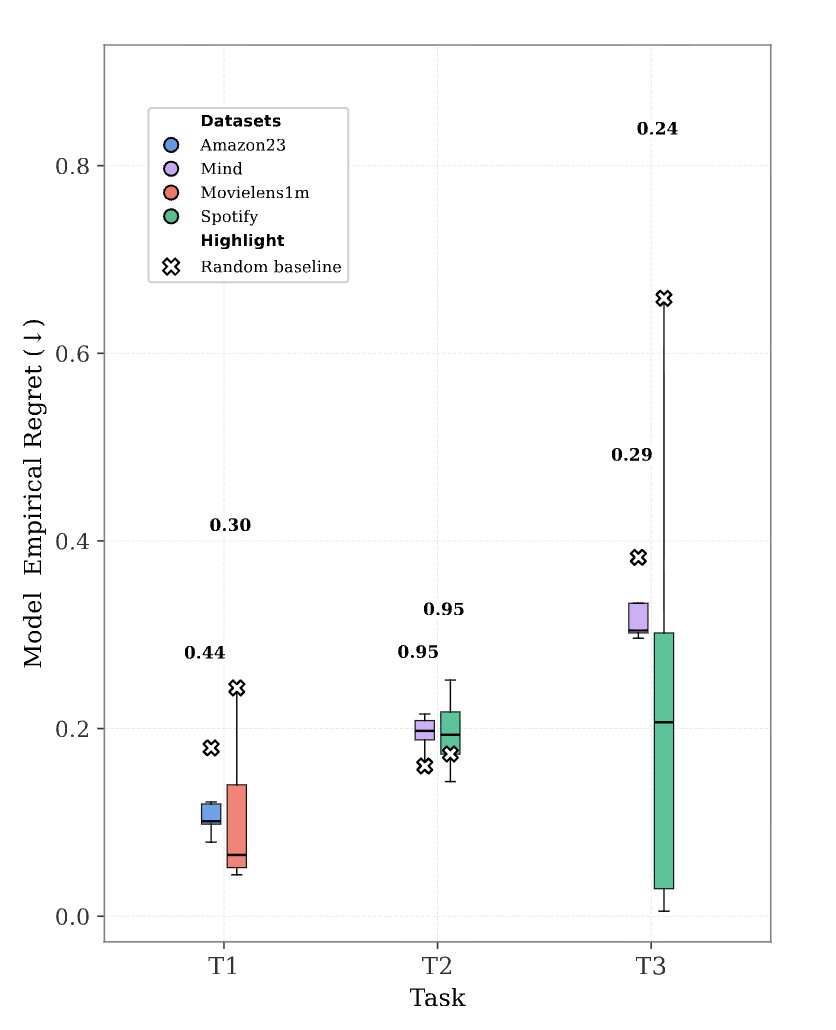
LLMs outperform random baselines in judging recommendation slates
By
–
This figure shows how well different LLMs judge slates (ordered recommendations) across datasets like Amazon, Spotify, MIND, and MovieLens. Lower “regret” = closer alignment with real user preferences. Turns out, LLMs consistently outperform random baselines when slates differ
-
LLMs judge your taste freakishly well in new recommender paper
By
–
Holy shit… LLMs just learned how to judge your taste and they’re freakishly good at it A new paper, “LLM-as-a-Judge: Toward World Models for Slate Recommendation Systems,” just flipped recommender research on its head. Instead of simulating every click or dwell time, these
-

AutoDeco: LLMs Learn Self-Tuning Decoding Parameters
By
–
What if LLMs could tune their own decoding—no more guesswork with temperature and top‑p? Enter AutoDeco: the first architecture that makes LLM decoding truly end-to-end. By adding lightweight heads, the model predicts its own context-aware temperature and top‑p at every token
-

CamCloneMaster: Reference-based Camera Control for Video Generation
By
–
CamCloneMaster
— AK (@_akhaliq) 8 novembre 2025
Enabling Reference-based Camera Control for Video Generation pic.twitter.com/l1MxjgTHICCamCloneMaster Enabling Reference-based Camera Control for Generation
-

EVTAR: End-to-End Virtual Try-On with Visual Reference
By
–
EVTAR End-to-End Try on with Additional Unpaired Visual Reference
-

Nested Optimization for Continual Learning and Long Context Processing
By
–
An exciting new approach for doing continual learning, using nested optimization for enhancing long context processing.
-

ByteDance Ouro: Scaling Latent Reasoning in Language Models
By
–
New paper from ByteDance Seed: Scaling Latent Reasoning via Looped LMs This paper proposes Ouro, which reuse the same layers to think in latent space instead of dumping long chain-of-thought text 2-3x param efficiency + increased performance via iterative latent computation
-

Share insights on LLMs AI Agents and Machine Learning
By
–
If you found it insightful, reshare with your network. Find me → @akshay_pachaar For more insights and tutorials on LLMs, AI Agents, and Machine Learning!
-

SAIL-Embedding: Omni-modal Foundation Model for Recommendations
By
–
What if one embedding model could seamlessly understand text, images, user behavior, and item IDs—all while boosting real-world recommendation performance? Meet SAIL-Embedding: an omni-modal foundation model engineered for the messy realities of industrial AI. Unlike CLIP-style