Weight decay is usually presented as “encouraging simpler solutions”, but I tend to think that the real benefit is the soft pruning of noisy / unhelpful features. Without decay, a weight can random-walk to a large value even if the input is completely random. Momentum and
MACHINE LEARNING
-

SWE-Playground: Synthetic Data Generation for Versatile Coding Agents
By
–
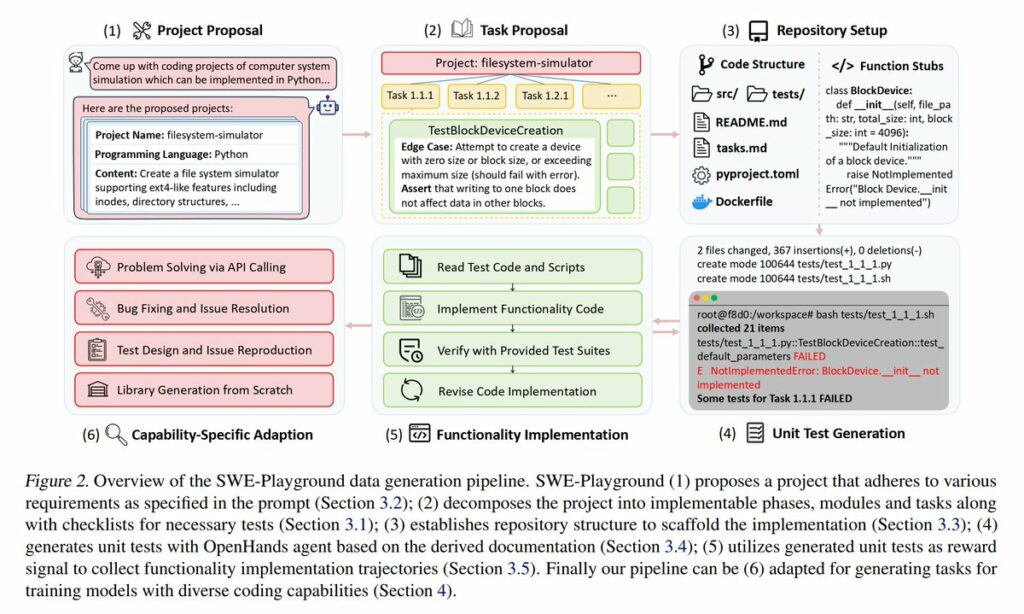
There are many good training methods for improving agents on SWE-bench: SWE-Gym, SWE-Smith, R2E-Gym. But what about broader software engineering tasks? In SWE-Playground, we introduce a new, more diverse synthetic data generation strategy to train divers software agents. Yiqi Zhu (@StephenZhu0218) Introducing SWE-Playground: A fully automated pipeline that generates synthetic environments to train versatile coding agents. 🤖✨ Training software engineering agents often relies on existing resources like GitHub issues and focuses on solving SWE-bench style issue resolution tasks. While this has driven incredible progress, real-world engineering involves a wider spectrum of tasks —from designing new libraries to writing reproduction scripts. 🌐 Rather than mining existing repositories, SWE-Playground synthetically generates projects, tasks, and verifiable unit tests from scratch. This approach offers two exciting opportunities: 1️⃣ Flexibility: We can generate tasks without being constrained by the availability or structure of existing open-source data. 2️⃣ Versatility: We extend training beyond Issue Resolution to include Issue Reproduction and Library Generation from Scratch. The results? 🚀 Our agents achieve strong performance across SWE-bench Verified, SWT-Bench, and Commit-0, demonstrating high data efficiency compared to baselines trained on larger datasets. Huge thanks to my amazing collaborators @apurvasgandhi and @gneubig for their incredible efforts on bringing this work to life! 👇 🧵 A deep dive into how we build versatile agents synthetically. Paper: arxiv.org/pdf/2512.12216 Project Page: neulab.github.io/SWE-Playgro… Code: github.com/neulab/SWE-Playgr… Data & Models: huggingface.co/collections/S… — https://nitter.net/StephenZhu0218/status/2000754124019683469#m
-

Frontier Models Struggle with Abstract Reasoning Tasks
By
–
NEW research on abstract reasoning. Frontier models like GPT-5 and Grok 4 still can't do what humans find trivially easy: infer transformation rules from a handful of examples. The default approach to solving ARC-AGI (the leading benchmark for abstract reasoning) treats these
-
Implementing Tree of Thoughts Reasoning for AI Models
By
–
3. Tree of Thoughts (ToT)
— God of Prompt (@godofprompt) 16 décembre 2025
Linear thinking gets linear results. ToT explores multiple reasoning paths simultaneously.
Instead of A→B→C, the model explores A→B→C, A→D→E, and A→F→G, then picks the best path.
Template:
Explore 3 different approaches to solve: [problem]… pic.twitter.com/oVbP6OECvk3. Tree of Thoughts (ToT) Linear thinking gets linear results. ToT explores multiple reasoning paths simultaneously. Instead of A→B→C, the model explores A→B→C, A→D→E, and A→F→G, then picks the best path. Template: Explore 3 different approaches to solve: [problem]
-
Tesla philosophy: cameras see as well as humans, especially at night
By
–
The Tesla philosophy is that if a human can see it so can their cars. Often way better than a human can, especially at night. The point is a little obtuse but our roads were designed for humans. Cameras are enough. And on screen you can see it is perceiving the world around the
-
Modern Data Platform Integration in Electronic Health Records
By
–
The Benefits of Integrating a Modern Data Platform Into the EHR
#AI #AIio #AIInnovation #ML #DataScience #Futureofwork @timnitgebru @oriolvinyalsml @ceobillionaire @soumithchintala @waitin4agi_ @sallyeaves @bernardmarr -
ChatGPT in Research, AI Models, and Code Practices
By
–
how many NeurIPS papers were written with ChatGPT?
— Cerebras (@cerebras) 16 décembre 2025
did Google use Google Photos to train Nano Banana Pro?
could we use AI to talk to other species?
we asked researchers for their real code confessions
watch til the end. #CodeConfessions pic.twitter.com/p7iBiTwk2nhow many NeurIPS papers were written with ChatGPT? did Google use Google Photos to train Nano Banana Pro? could we use AI to talk to other species? we asked researchers for their real code confessions watch til the end. #CodeConfessions
-
NVIDIA Nemotron 3: Agent-Ready AI Model Family Explained
By
–
NVIDIA Nemotron 3 Explained — a quick breakdown of NVIDIA’s new agent-ready AI model family built for reasoning, chat, RAG, and instruction-following.
— Satya Mallick (@LearnOpenCV) 15 décembre 2025
Learn how Mixture-of-Experts (MoE) architecture enables lower latency, lower cost, and scalable deployment, with Nano, Super,… pic.twitter.com/wKLyxMilYJNVIDIA Nemotron 3 Explained — a quick breakdown of NVIDIA’s new agent-ready AI model family built for reasoning, chat, RAG, and instruction-following. Learn how Mixture-of-Experts (MoE) architecture enables lower latency, lower cost, and scalable deployment, with Nano, Super,
-

Dynamic erf improves normalization-free Transformers architecture
By
–
Common conception, shattered again. Normalization isn’t fundamental to Transformers, and this approach keeps getting better This paper introduces Dynamic erf (Derf), which further improves normalization-free Transformers With strong empirical results while generalizing better
-
Machine Learning Improves Data Annotation Quality
By
–
Improving annotation quality with machine learning
#AI #AIio #AIInnovation #ML #DataScience #Futureofwork @Scobleizer @AndrewYNg @drfeifei @KirkDBorne @fchollet @rowancheung @antgrasso