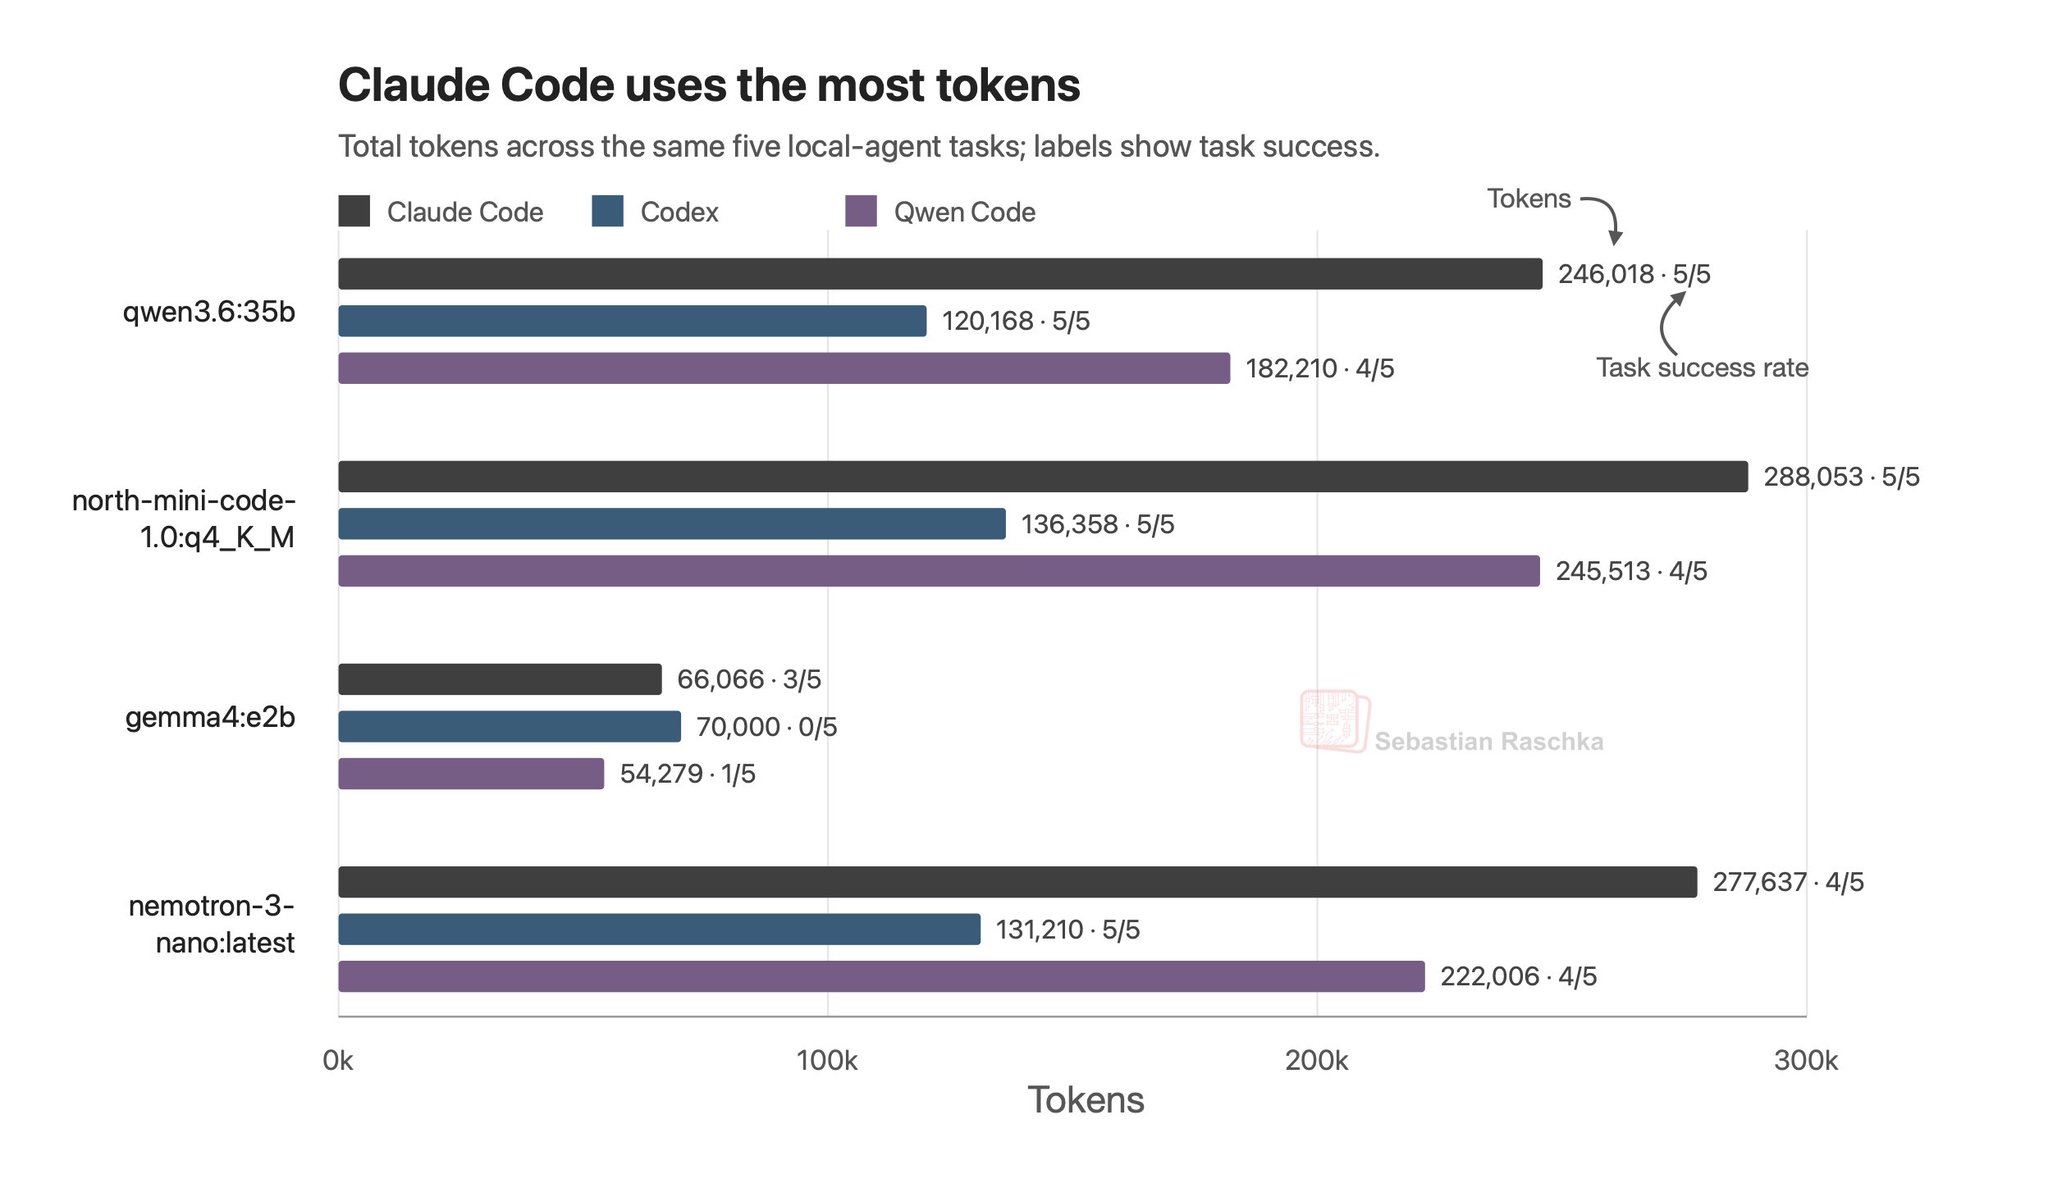
Have been taking different local open-weight LLMs for a test drive in different harnesses (Qwen-Code, Codex, Claude Code). 30B Mixture-of-Expert models are kind of a nice sweet spot and can solve challenging problems. And they get roughly 40 tok/sec on a Mac or DGX Spark, which
MACHINE LEARNING
-
Heterogeneous disaggregated inference is the future of AI
By
–
Training builds models. Inference builds businesses. At @deeptechweek SF, our Chief Product & Strategy Officer Abhi Ingle shared why heterogeneous, disaggregated inference is the future of AI, and why "more intelligence per joule" is the metric that matters. @LipBuTan1
-
One memory for all 10,000+ notes in structured form for AI agents
By
–
Our talk just got selected as a keynote for the AI Engineer World's Fair 2026. So I want to share what @pauliusztin_ and I built: one memory for all 10,000+ of our notes. Everything I've learned and saved now lives in one structured memory my agents can actually use. It takes
-
Symbol-manipulation in 2001 book defines neurosymbolic systems
By
–
see the discussion of symbol-manipulation in my 2001 book. without question tools, harnesses etc depend on symbol-manipulation as i defined it there. and to be neurosymbolic is to use symbol-manipulation and neural networks jointly.
-
Anthropic’s Mythos forces DeepSeek into $7.4B fundraising
By
–
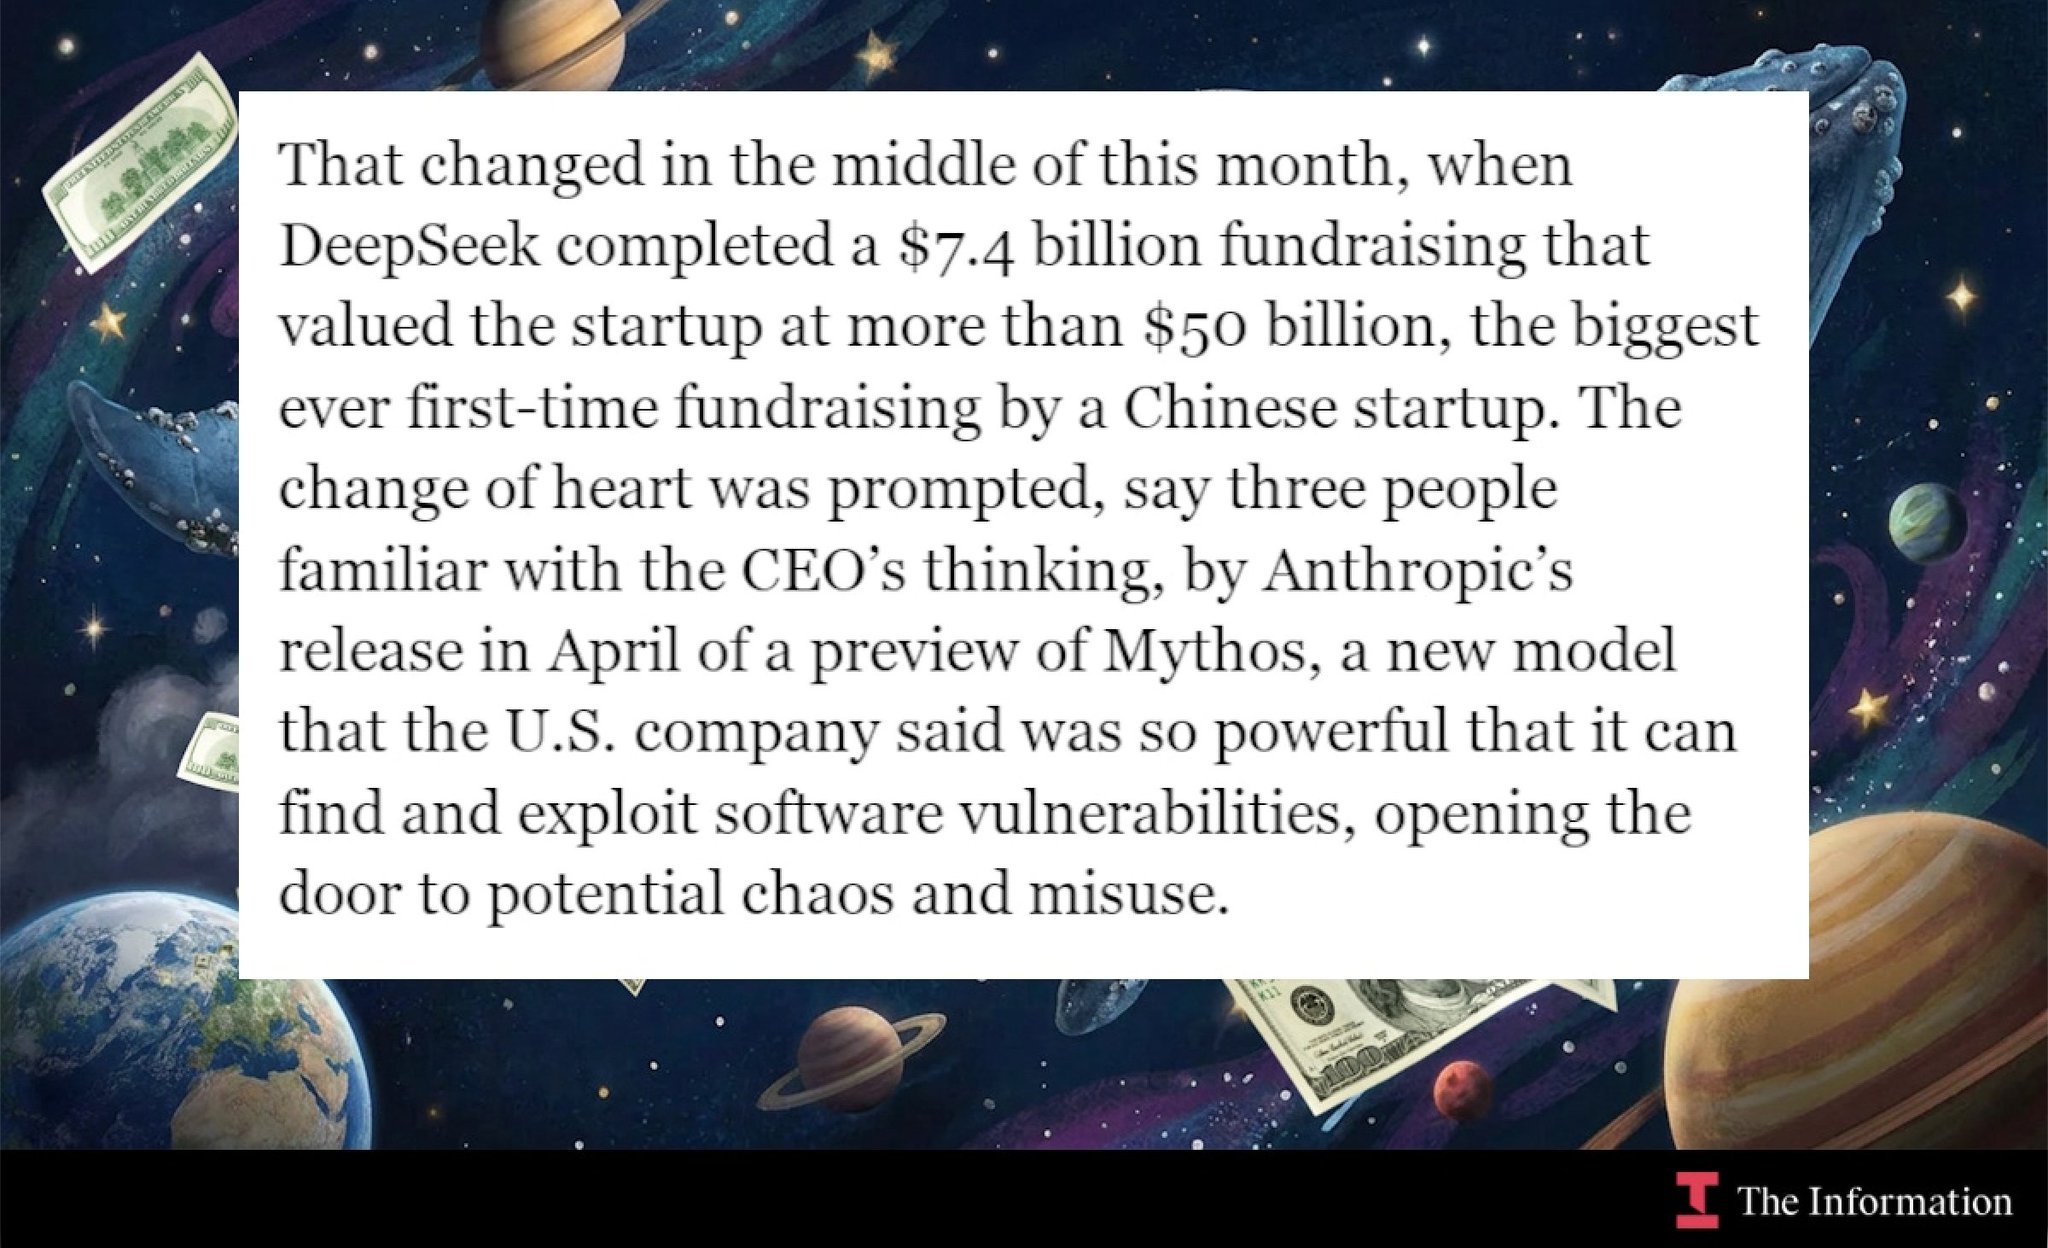
Anthropic’s Mythos preview reportedly pushed DeepSeek into a $7.4B fundraising – because they could not compete with Mythos. Until now, the three-year-old Chinese AI lab had relied on CEO Liang Wenfeng’s personal wealth instead of outside capital. The Information reports the
-

Confidence-Aware Tool Orchestration for Robust Video Understanding
By
–
Confidence-Aware Tool Orchestration for Robust Understanding
-
MinerU parses ugly documents into clean Markdown and JSON for LLM workflows
By
–
/5 MinerU parses ugly documents into clean Markdown and JSON for LLM workflows. It supports PDFs, DOCX, PPTX, XLSX, images, and web pages through a VLM + OCR dual engine. It can handle scanned docs, handwriting, formulas to LaTeX, tables to HTML, multi-column layouts, and
-
HyperExtract: LLM framework converting unstructured text to knowledge
By
–
/4 HyperExtract turns messy documents into actual knowledge systems. It is an LLM-powered framework for converting unstructured text into strongly typed Knowledge Abstracts. It can extract simple lists, Pydantic models, knowledge graphs, hypergraphs, and spatio-temporal graphs.
-

Skepticism about 397B open source model matching Claude Opus 4.8
By
–

This looks to good to be true. A 397B open source model on par or even outperforming Claude Opus 4.8? I need to check it out.
-
Burden of proof to show current models are not susceptible
By
–
That’s incorrect. The burden of proof lies in demonstrating current models are not susceptible to the same issues we identified. To assume otherwise is blind faith in untested models