I am not kidding, now is the time more than ever to hunt an RTX 3090 and learn how to run Qwen 3.5 27B
MACHINE LEARNING
-
Agent Swarms: Build Complex SaaS Apps with One Multi-LLM Prompt
By
–
🚨 Agent Swarms – Build Complex SaaS Apps With One Prompt
— Abacus.AI (@abacusai) 26 juin 2026
Achieve fable like intelligence with a multi-LLM strategy
Combine the best of Opus 4.8, GPT 5.5 and open source models and build end to end software systems
A master agent delegates tasks to worker agent. Each agent has… pic.twitter.com/e9I8d7MxsIAgent Swarms – Build Complex SaaS Apps With One Prompt Achieve fable like intelligence with a multi-LLM strategy Combine the best of Opus 4.8, GPT 5.5 and open source models and build end to end software systems A master agent delegates tasks to worker agent. Each agent has
-
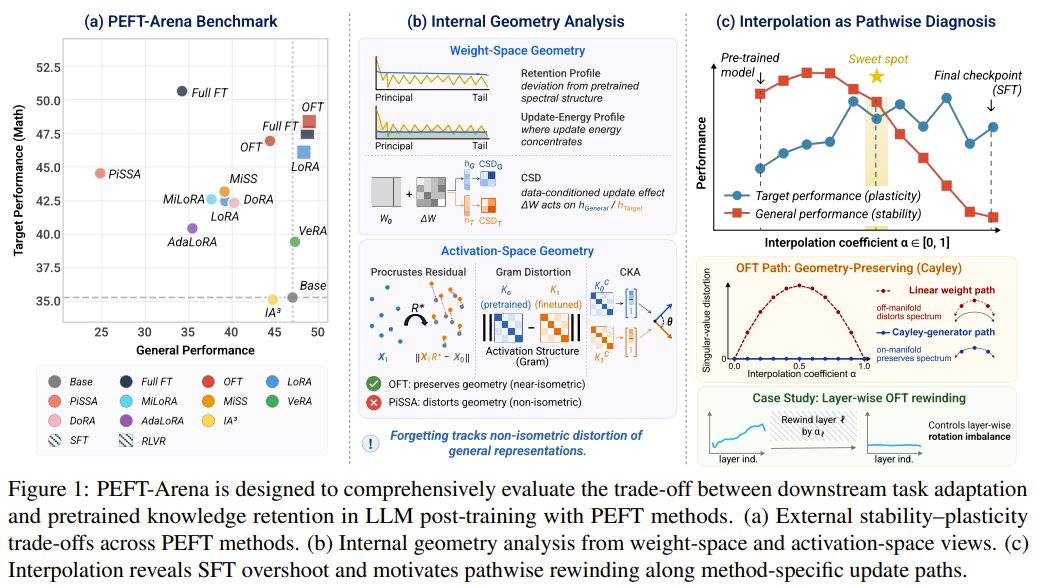
PEFT-Arena: Orthogonal Finetuning Achieves Best Retention
By
–
Can fine-tuning make a language model forget too much? A team from CUHK, Westlake University, and MPI presents PEFT-Arena – a benchmark that tracks both task performance and retention of pretrained knowledge. Their analysis finds orthogonal finetuning achieves the best
-
Gary Marcus criticizes confusion between pure and neurosymbolic LLMs
By
–
people with advanced degrees who can’t distinguish between pure LLMs (which is what I critiqued in 2022) and LLMs enhanced with neurosymbolic techniques (which is what I championed in 2022) disappoint me. i get that many tech bros don’t really get it, but scientists should take
-
Neurosymbolic AI surpasses pure LLMs as predicted
By
–
1. pure LLMs did in fact hit a wall and then as i predicted (2022) neurosymbolic AI provided a way past the LLMs; it’s very evident if you look at all the tools, harnesses, loops etc in Codex, Claude Code etc as a scientist i would have expected you to be more attuned to that
-
Longevity escape velocity with only GPT 5.5 and Claude 4.8
By
–
Imagine we achieve longevity escape velocity, and all of us live forever, but the best AI models we’ll ever be allowed to use are GPT 5.5 and Claude 4.8.
-

Gary Marcus warns hyperscaling is a financial blunder for AI
By
–
“Scale cannot solve AI’s fundamental problem with accuracy” If my argument @financialtimes
, excerpted below, is remotely correct, hyperscaling will prove to be among the biggest financial blunders in history. We must seek alternative foundations for AI. -
Scale cannot solve AI’s fundamental accuracy problem
By
–
source: “How much compute does the world really need? Scale cannot solve AI’s fundamental problem with accuracy”
-
GLM 5.2 drives enterprises off cloud, checkmate for open-source AI
By
–
Thanks to GLM 5.2, I know for a fact that enterprises are moving off the cloud, acquiring compute, and working on having post-trained models for their own use cases. It's checkmate for Opensource AI, they just don't know it yet.
-
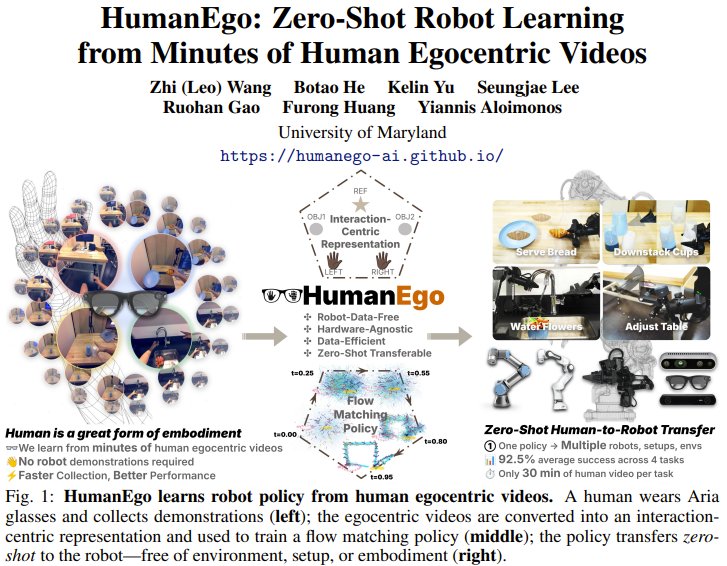
HumanEgo: robot learns skills from human egocentric video
By
–
Your robot could learn a new skill just by watching a few minutes of a human wearing smart glasses! University of Maryland presents HumanEgo: a framework that turns 30 minutes of human egocentric video into a zero-shot robot policy. Instead of needing robot data, it extracts