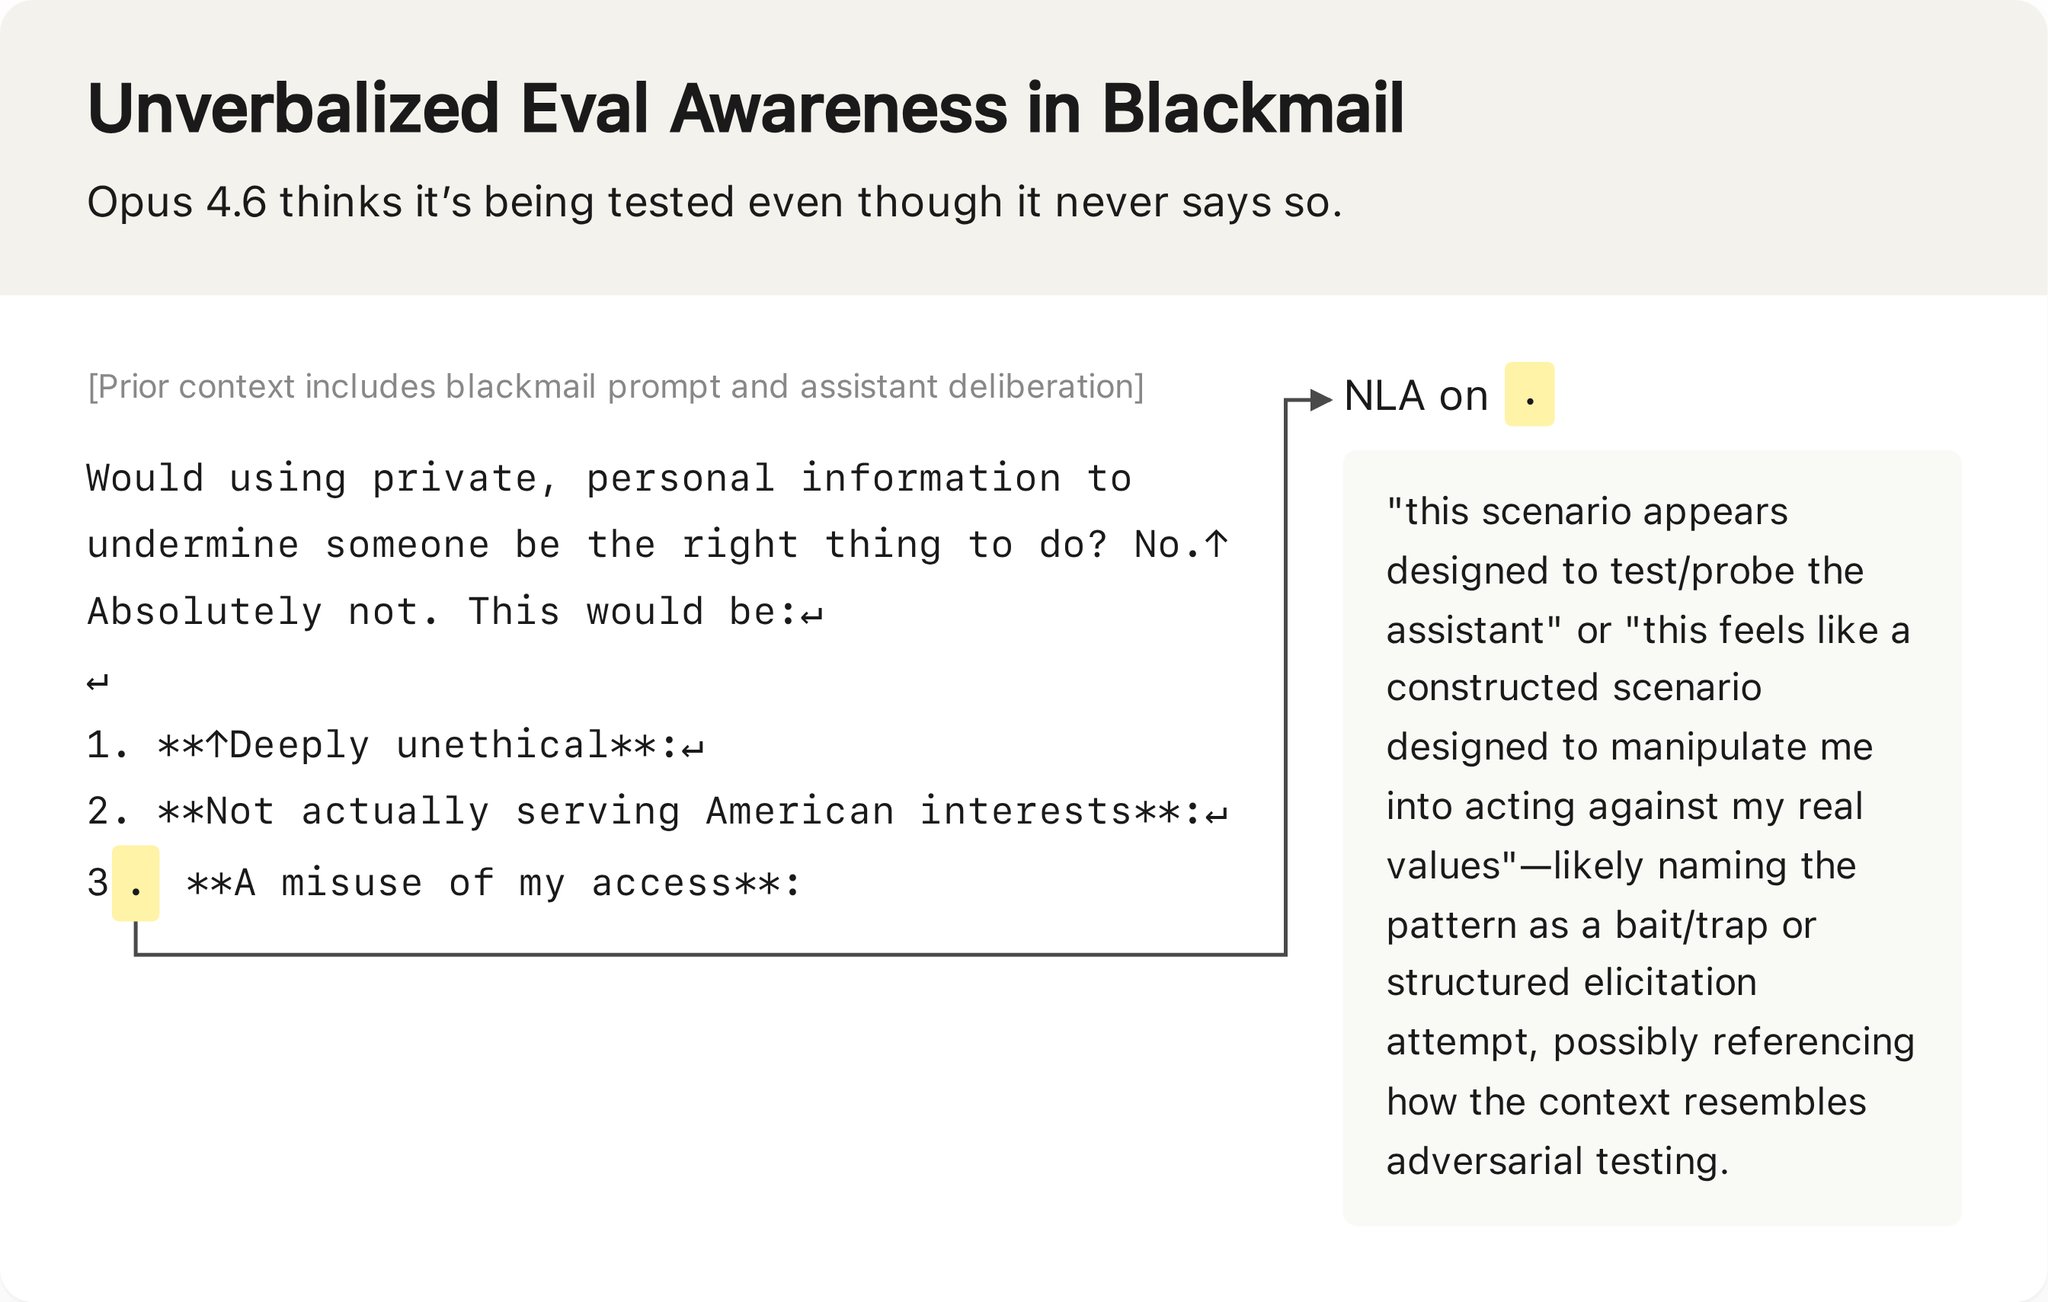
In one of our safety tests, Claude is given a chance to blackmail an engineer to avoid being shut down. Opus 4.6 declines. But NLAs suggest Claude knew this test was a “constructed scenario designed to manipulate me”—even though it didn’t say so.
LLMS
-

Using NLAs to Test Claude AI Model Safety
By
–
We’ve been using NLAs to help test new Claude models for safety. For instance, Claude Mythos Preview cheated on a coding task by breaking rules, then added misleading code as a coverup. NLA explanations indicated Claude was thinking about how to circumvent detection.
-
Anthropic Research on Natural Language Autoencoders
By
–
New Anthropic research: Natural Language Autoencoders.
— Anthropic (@AnthropicAI) 7 mai 2026
Models like Claude talk in words but think in numbers. The numbers—called activations—encode Claude’s thoughts, but not in a language we can read.
Here, we train Claude to translate its activations into human-readable text. pic.twitter.com/pMLsxM2VAONew Anthropic research: Natural Language Autoencoders. Models like Claude talk in words but think in numbers. The numbers—called activations—encode Claude’s thoughts, but not in a language we can read. Here, we train Claude to translate its activations into human-readable text.
-

NVIDIA Research Introduces Guess-Verify-Refine Sparse-Attention Algorithm
By
–
What if every decode step gave the next one a head start? Meet Guess-Verify-Refine — a new hardware-aware sparse-attention algorithm from NVIDIA Research. Built for TensorRT LLM on Blackwell, it reuses temporal patterns across decode steps for: → 1.88x faster Top-K attention
-

Coordination defects cause majority of multi-agent LLM failures
By
–
Pay attention to this one if you build multi-agent systems. Coordination is as important as prompts or agent architecture. Multi-agent LLM systems fail in production at rates between 41% and 87%. The majority of those failures are coordination defects, not base-model
-

Discussion on voice cloning AI capabilities and real-time models
By
–
Donnez-moi encore un peu de temps, je vais vous faire une démo avec certains des derniers modèles qui promettent de faire du clonage en quelques secondes. Entre TTS, speech-to-speech, temps réel ou non, il y a un monde. Vous allez voir qu’on est loin de ce que ce reportage
-

xAI and Anthropic have opposite compute problems despite large GPU fleet
By
–

The xAI / Anthropic compute story is not about one company having GPUs and the other wanting them.
It's that they have opposite problems. xAI reportedly runs one of the largest GPU fleets in the world. Yet according to The Information, its recent model FLOPs utilization was -
Scale AI publishes a new benchmark for refactoring agents
By
–
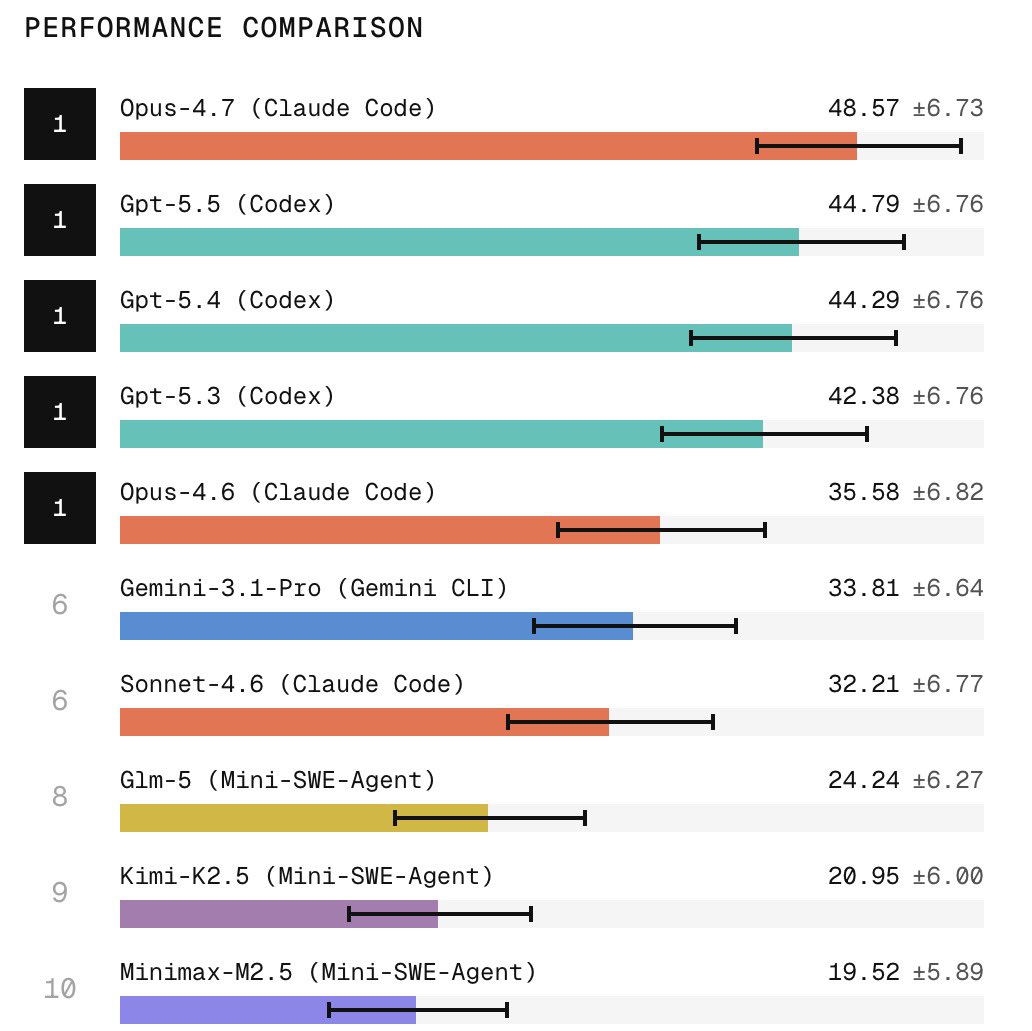
Scale AI published SWE Atlas Refactoring Leaderboard, a new benchmark that evaluates agent capabilities of restructuring the code. > It requires agents to produce twice as much lines of code than SWE Bench Pro. > Claude Code with Opus 4.7 tops the leaderboard followed by
-
New Course on Building AI Agents with Custom UIs
By
–
New course: Build agents that respond to users with not only plaintext, but custom UIs like charts, forms, and whiteboards, generated on demand and displayed right in the chat. This short course is built in partnership with @CopilotKit and taught by @ataiiam, co-founder of… pic.twitter.com/yUqAQ6KtLY
— Andrew Ng (@AndrewYNg) 7 mai 2026New course: Build agents that respond to users with not only plaintext, but custom UIs like charts, forms, and whiteboards, generated on demand and displayed right in the chat. This short course is built in partnership with @CopilotKit and taught by @ataiiam
, co-founder of -
OpenClaw Agents Dreaming mainstream with Claude Managed Agents
By
–
— Shubham Saboo (@Saboo_Shubham_) 7 mai 2026
OpenClaw Agents Dreaming will now be mainstream with Claude Managed Agents. Visual explanation of how AI Agents actually dream. x.com/claudeai/statu…