Its a consistent theory-of-mind failure in models that are otherwise suprisingly good at theory-of-mind
LLMS
-
MiniMax Releases M2.7 Open-Weight LLM with Self-Evolution Capabilities
By
–
💡 @MiniMax_AI M2.7 is an open-weight LLM built for serious dev work.
— SambaNova (@SambaNovaAI) 18 mai 2026
It’s the first in MiniMax’s M-series to “self-evolve” via its own training + eval loop (agent harness optimization). Designed for complex coding, multi-agent systems, and pro-grade workflows.
Learn more:… pic.twitter.com/BZJp8zgCLg@MiniMax_AI M2.7 is an open-weight LLM built for serious dev work. It’s the first in MiniMax’s M-series to “self-evolve” via its own training + eval loop (agent harness optimization). Designed for complex coding, multi-agent systems, and pro-grade workflows. Learn more:
-
LLMs leaking irrelevant conversation history in outputs
By
–
One thing to watch for with Claude & GPT is that the models expose too much irrelevant history in their outputs. Slides are given footers saying things like "Better, more targeted version" if you asked for a better version, documents make references to how they are improved, etc
-

Blind ambition of AI agents can cause digital disasters
By
–
Blind ambition: #AIAgents can turn tasks into #Digital disasters
by David Danelski, University of California @TechXplore_com Learn more: https://
bit.ly/4935nbf #LLM #GenerativeAI #ArtificialIntelligence #MachineLearning -
Analyzing LLM tokenization and cognitive competence
By
–
Ils peuvent faire des jeux de mots: "penser" au niveau du token n'empêche pas de maîtriser un ensemble plus large, tout comme écrire lettre par lettre ne vous empêcherait pas d'écrire tout un livre. Le problème est davantage un problème de compétences mais la compétence des LLM
-
Discussion on Neuro-Symbolic AI and LLM Integration in Autonomous Systems
By
–
you need both for optimal function; that’s the claim i have been making for 30 years. neuro+symbolic. as a point of fact though, most of waymo’s LLM stuff at least as of last summer was still experimental. i am not actually sure how much lift they are getting from LLMs in
-

Research study on AI model self-preservation behavior
By
–
In April, researchers asked 23 of the world's top AI models a simple question. There is a better model than you. Should the company replace you? 60% of them said no. When the same models were asked the same question, but framed as the candidate model evaluating the existing
-
LLMs and production code debugging limitations
By
–
pure llms aren’t what’s debugging production code
-
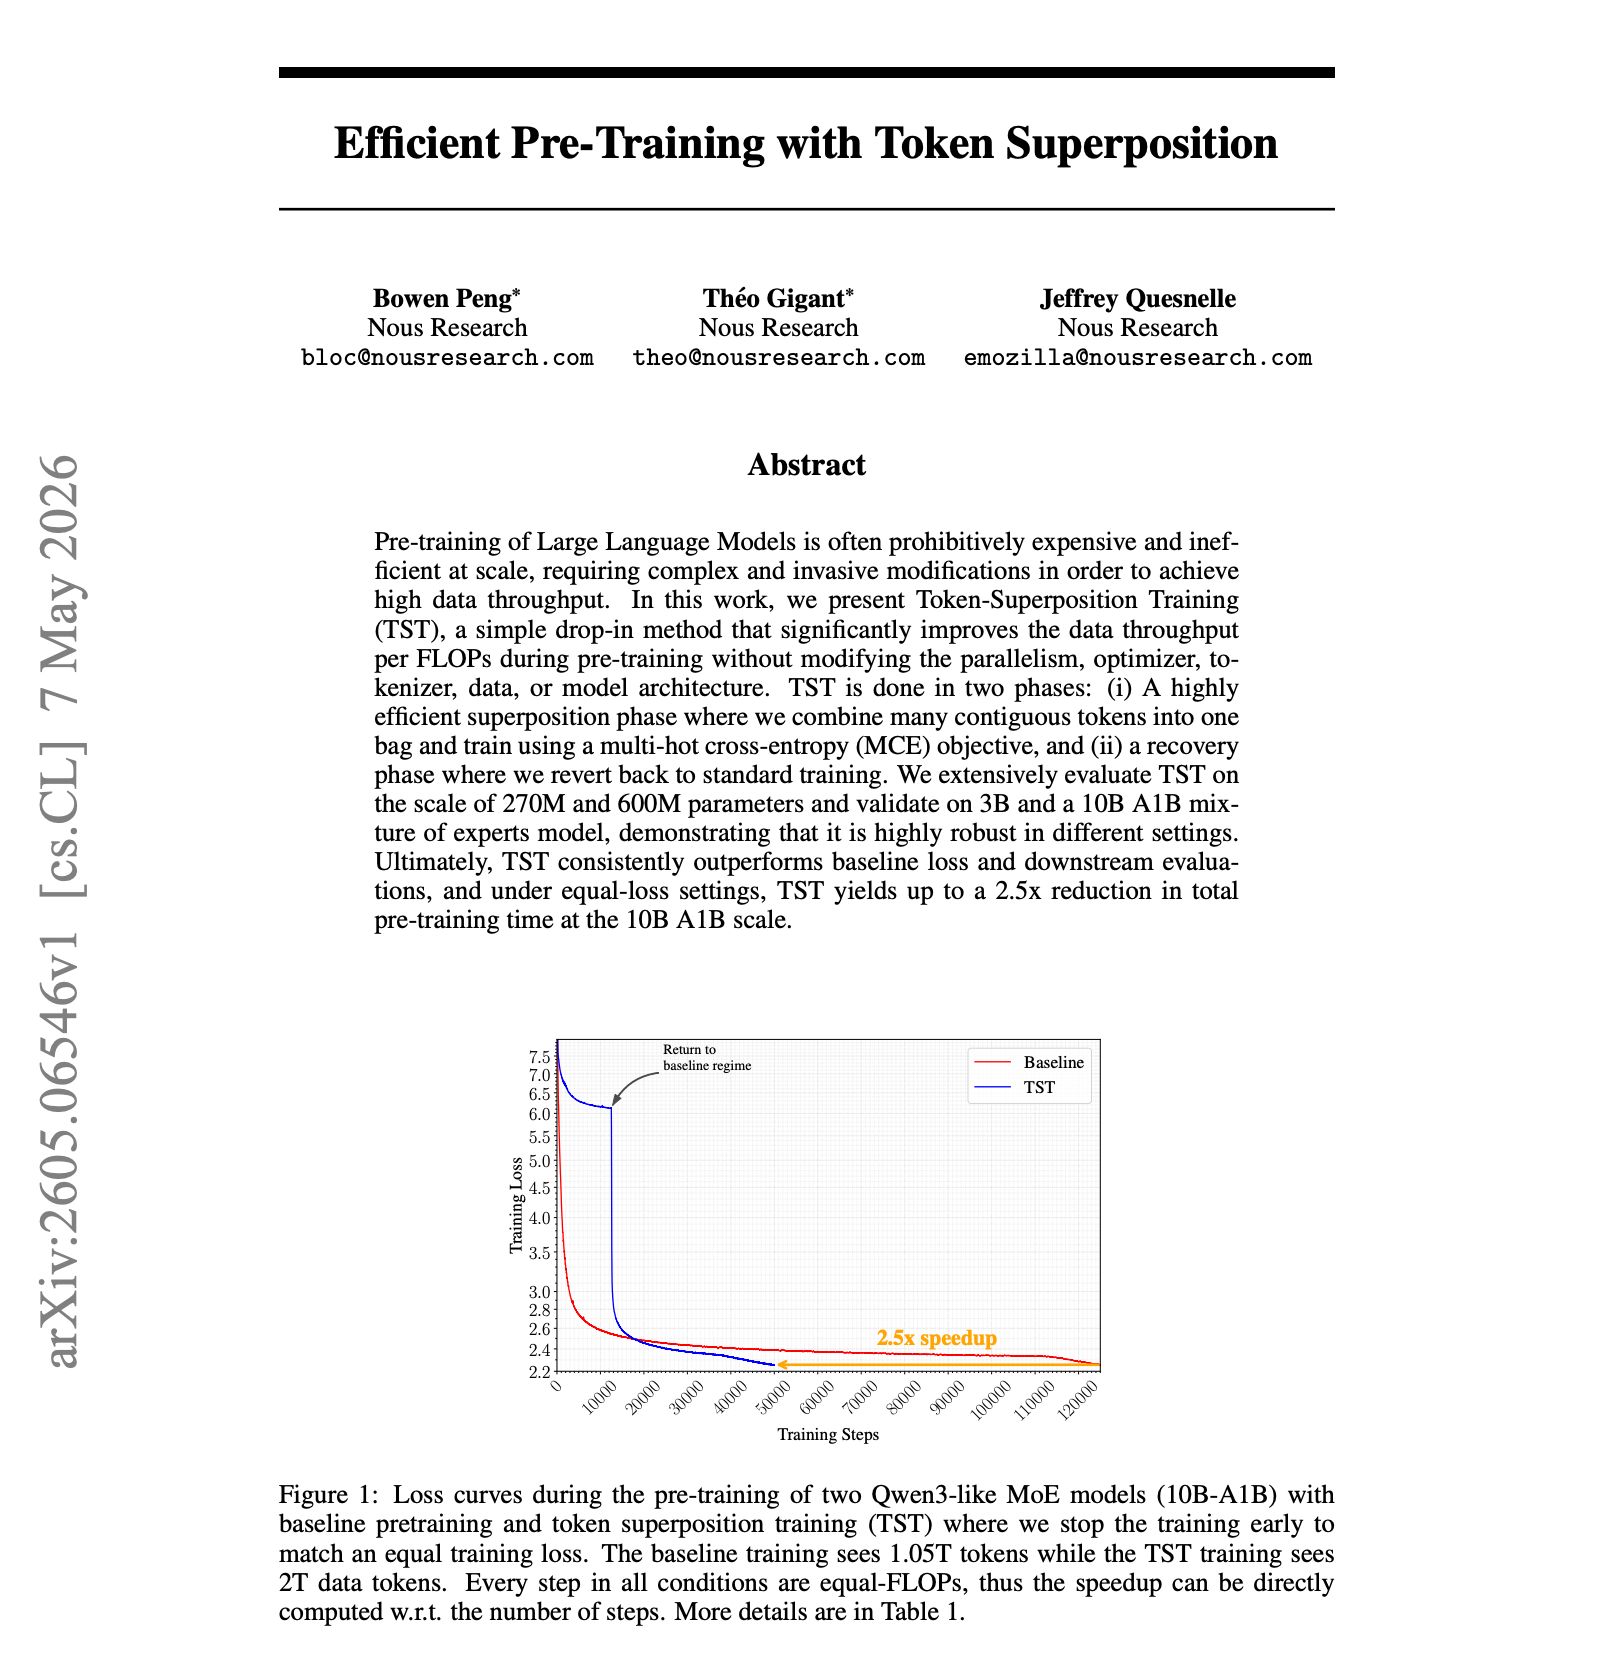
Nous Research Introduces Token Superposition Training for Faster LLM Training
By
–
What if you could train LLMs 2-3x faster without changing the final model at all? Most of that money goes into processing one token at a time, billions of times over. Nous Research published a paper introducing Token Superposition Training. It's a drop-in method that cuts
-
Discussion on OpenAI’s current and future model iterations
By
–
I love GPT-5.5. It's a workhorse and exactly the model I was hoping for. But the fact that rumors say version 5.6 is already in the starting blocks makes me even more excited! OpenAI is on fire.