This doesn't define human intelligence, in fact a human's ability to know when it is wrong to manipulate someone might be considered a pretty important element of social intelligence. But anyway, ever since ChatGPT LLMs have essentially been optimized for persuasion…
LLMS
-

Paper: GPT-5.4 Nano with Critic-Comparator Reaches SWE-bench Parity
By
–
NEW paper worth reading. GPT-5.4 nano plus a critic-comparator orchestration loop hits 76.4% on SWE-bench Verified, matching standalone Gemini 3 Pro and Claude Opus 4.5 Thinking. The trick is to select from k=8 weak-model proposals using execution and proof signals. What does
-
Seeking AI models for stylistic writing critique and sparring
By
–
what’s the best model & harness that just gets writing vibe right? i don’t want any content generated, but sparring partner and for it to really get the style im going for so it can critique i mix up trying a lot of md files, examples and such
-

The Strategic Shift Toward Proprietary Model Training in AI
By
–
Very cool to see Cursor doubling down on training great models. In my opinion, ultimately all serious companies in AI will want to train models themselves, based on open-source instead of outsourcing AI to others via APIs!
-
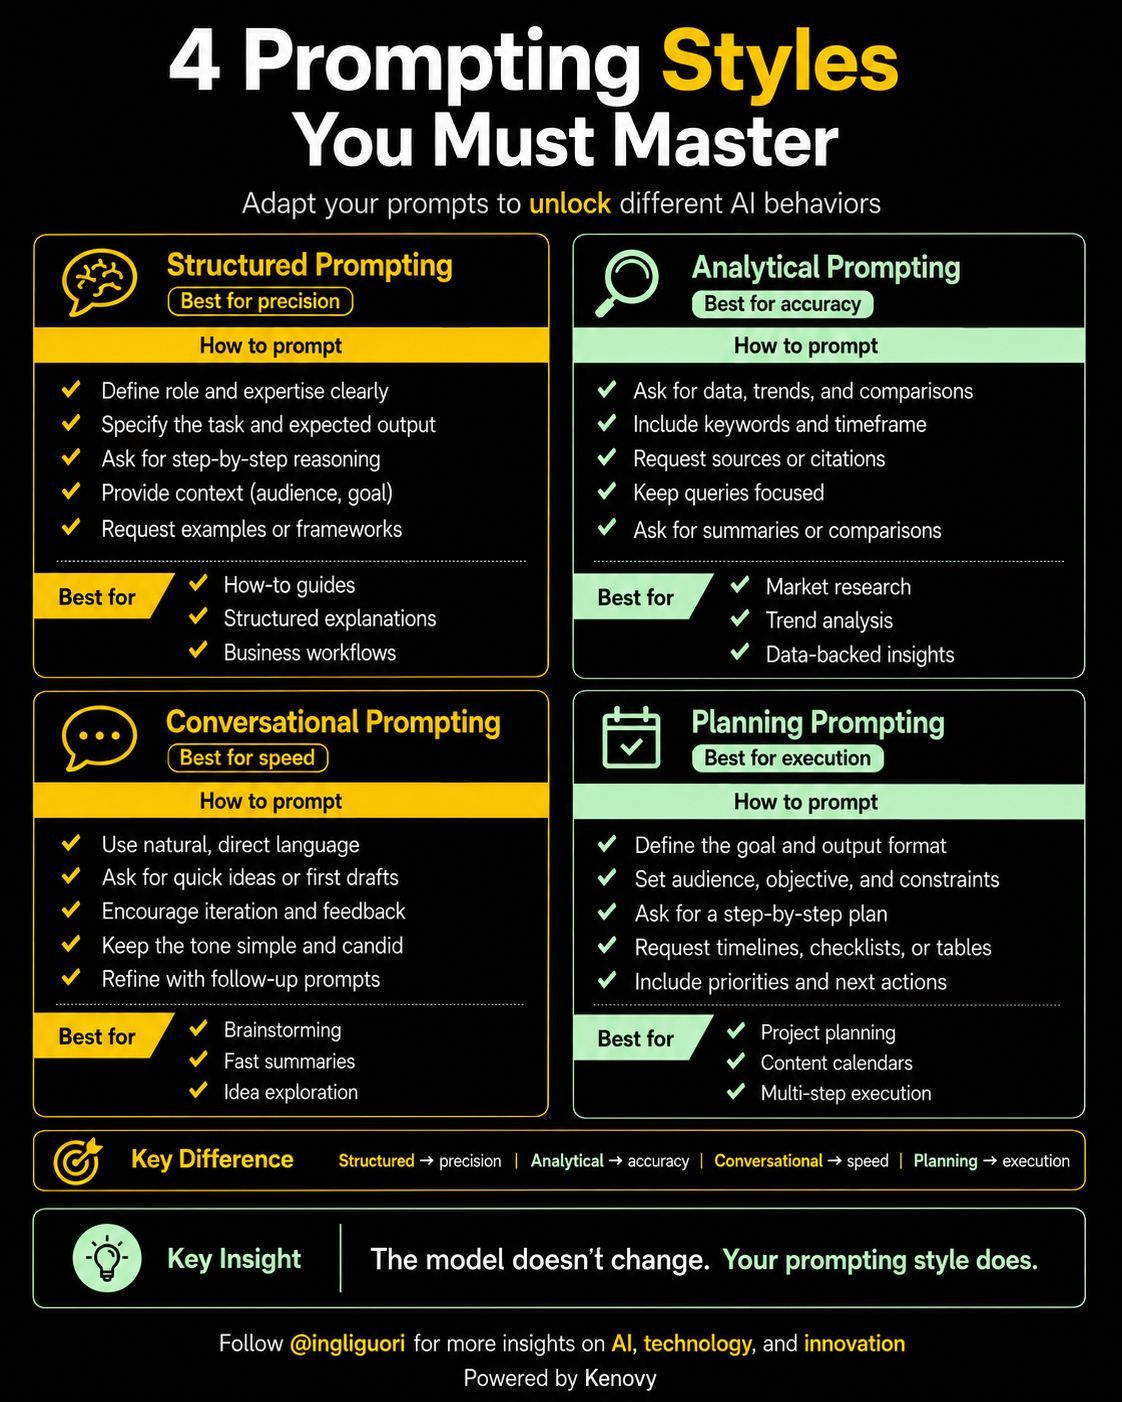
4 Prompting Styles to Master for AI Interaction
By
–
4 prompting styles to master • Structured → precision
• Analytical → accuracy
• Conversational → speed
• Planning → execution Better prompts unlock different AI behaviors. Via Giuliano Liguori (
@ingliguori
) #AI #Prompts #GenAI -
New research paper and implementation for Delta-Mem LLM optimization
By
–
Links: > https://
arxiv.org/abs/2605.12357 (paper, ~25 min read)
> https://
github.com/declare-lab/de
lta-Mem
… (repo, ~10 min setup)
> https://
huggingface.co/declare-lab/de
lta-mem_qwen3_4b-instruct
… (Qwen3-4B TSW) Subscribe at http://
AlphaSignal.ai for daily AI signals. Read by 300,000+ subscribers. -
Training Major AI Model with 10x Compute on Colossus 2
By
–
> Together with SpaceXAI, we're training a significantly larger model from scratch, using 10x more total compute. With Colossus 2's million H100-equivalents and our combined data and training techniques, we expect this to be a major leap in model capability. That's double
-
Composer 2.5 and Large-Scale AI Model Training Initiative
By
–
Composer 2.5 is built on top of Kimi K2.5 Also interesting > Together with SpaceXAI, we're training a significantly larger model from scratch, using 10x more total compute. With Colossus 2's million H100-equivalents and our combined data and training techniques, we expect
-
New Large-Scale AI Model Training with Increased Compute
By
–
Together with SpaceXAI, we’re training a significantly larger model from scratch, using 10x more total compute. With Colossus 2’s million H100-equivalents and our combined data and training techniques, we expect this to be a major leap in model capability.
-

Composer 2.5 Model Performance and Efficiency
By
–
Composer 2.5 is exceptionally intelligent and up to 10x more efficient than similarly capable models.