
“LLMs are ‘not particularly good’ at the kind of biology necessary to develop therapies” See also my pinned tweet.

By
–
“LLMs are ‘not particularly good’ at the kind of biology necessary to develop therapies” See also my pinned tweet.
By
–
Meet MiniMax M2.5.
— God of Prompt (@godofprompt) 27 février 2026
It beats Opus 4.6 on real coding benchmarks:
– SWE-Bench Verified: 80.2%
– 3x faster execution
– $1/hour flat rate
– Only 10B activated parameters (smallest Tier-1 model)
You can actually afford to run agents 24/7 now. pic.twitter.com/bjbUqDuGt9
Meet MiniMax M2.5. It beats Opus 4.6 on real coding benchmarks: – SWE-Bench Verified: 80.2%
– 3x faster execution
– $1/hour flat rate
– Only 10B activated parameters (smallest Tier-1 model) You can actually afford to run agents 24/7 now.
By
–
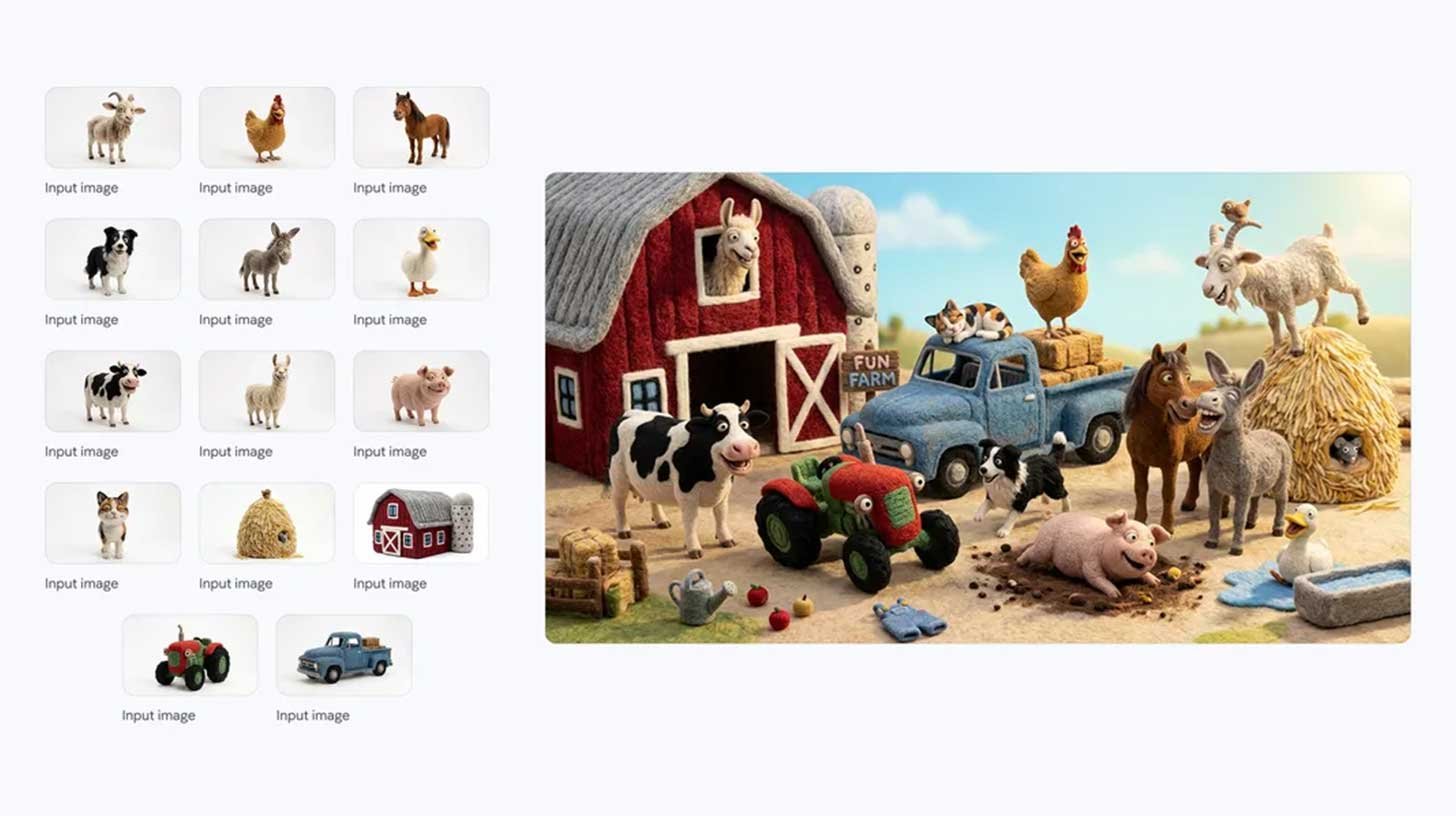
Everyone's paying $15/month for Claude to write code. I just found a model that codes BETTER than Opus 4.6, runs 3x faster, and costs $1/hour for unlimited scaling. Self-hosted. Always-on agents. 10B activated parameters. The agent economy just became profitable:
By
–
Top stories in AI today: – Nano Banana 2 claims No. 1 at half the cost
– OpenAI snags Meta's $200M+ AI hire
– Create an AI Assistant with its own phone number
– Pew study shows how teens are using AI
– 4 new AI tools, community workflows, and more
By
–
Doc-to-LoRA: What if you could online distill documents into your LLM weights without training?
— Robert Lange (@RobertTLange) 27 février 2026
🚀 Stoked to share our new work on instant LLM adaptation using meta-learned hypernetworks 📷📝
Building on our previous Text-to-LoRA work, we doc-condition a hypernetwork to… https://t.co/BLQCUgGvuX pic.twitter.com/Eu9z2kdt5a
Doc-to-LoRA: What if you could online distill documents into your LLM weights without training? 🚀 Stoked to share our new work on instant LLM adaptation using meta-learned hypernetworks 📷📝 Building on our previous Text-to-LoRA work, we doc-condition a hypernetwork to output LoRA adapters, improving the base LLM's effective context window. The hypernetwork is meta-trained on 1000s of summarization tasks and shows remarkable compression capabilities at low latency 📈 🧑🔬 Work led by @tan51616 with @edo_cet & Shin Useka at @SakanaAILabs 📷 Sakana AI (@SakanaAILabs) We’re excited to introduce Doc-to-LoRA and Text-to-LoRA, two related research exploring how to make LLM customization faster and more accessible. pub.sakana.ai/doc-to-lora/ By training a Hypernetwork to generate LoRA adapters on the fly, these methods allow models to instantly internalize new information or adapt to new tasks. Biological systems naturally rely on two key cognitive abilities: durable long-term memory to store facts, and rapid adaptation to handle new tasks given limited sensory cues. While modern LLMs are highly capable, they still lack this flexibility. Traditionally, adding long-term memory or adapting an LLM to a specific downstream task requires an expensive and time-consuming model update, such as fine-tuning or context distillation, or relies on memory-intensive long prompts. To bypass these limitations, our work focuses on the concept of cost amortization. We pay the meta-training cost once to train a hypernetwork capable of producing tasks or document specific LoRAs on demand. This turns what used to be a heavy engineering pipeline into a single, inexpensive forward pass. Instead of performing per-task optimization, the hypernetwork meta-learns update rules to instantly modify an LLM given a new task description or a long document. In our experiments, Text-to-LoRA successfully specializes models to unseen tasks using just a natural language description. Building on this, Doc-to-LoRA is able to internalize factual documents. On a needle-in-a-haystack task, Doc-to-LoRA achieves near-perfect accuracy on instances five times longer than the base model's context window. It can even generalize to transfer visual information from a vision-language model into a text-only LLM, allowing it to classify images purely through internalized weights. Importantly, both methods run with sub-second latency, enabling rapid experimentation while avoiding the overhead of traditional model updates. This approach is a step towards lowering the technical barriers of model customization, allowing end-users to specialize foundation models via simple text inputs. We have released our code and papers for the community to explore. Doc-to-LoRA Paper: arxiv.org/abs/2602.15902 Code: github.com/SakanaAI/Doc-to-L… Text-to-LoRA Paper: arxiv.org/abs/2506.06105 Code: github.com/SakanaAI/Text-to-… — https://nitter.net/SakanaAILabs/status/2027240298666209535#m
→ View original post on X — @_yutaroyamada, 2026-02-27 09:41 UTC
By
–
Meta's REFRAG is quite an interesting optimization layer that works on top of any RAG architecture. Essentially, instead of tokenizing all retrieved chunks, it compresses most into embeddings and feeds them directly to the decoder. An RL policy selectively expands only the
By
–
🛑MaxClaw (MiniMax x OpenClaw) just shipped, and it basically turns your chat apps into a command center for getting work done.
— Futurepedia – Learn to Leverage AI (@futurepedia_io) 27 février 2026
It runs on MiniMax M2.5 and claims Claude 4.6 level reasoning at roughly 10% of the cost.
What stands out:
– Proactive agents that keep tasks moving… pic.twitter.com/EcpZa3xinU
MaxClaw (MiniMax x OpenClaw) just shipped, and it basically turns your chat apps into a command center for getting work done. It runs on MiniMax M2.5 and claims Claude 4.6 level reasoning at roughly 10% of the cost. What stands out:
– Proactive agents that keep tasks moving
By
–
Instead of forcing models to hold everything in an active context window, we can use hypernetworks to instantly compile documents and tasks directly into the model's weights. A step towards giving language models durable memory and fast adaptation.
— hardmaru (@hardmaru) 27 février 2026
Blog: https://t.co/e2b8G9LJKe https://t.co/IezT9IGgg2
Instead of forcing models to hold everything in an active context window, we can use hypernetworks to instantly compile documents and tasks directly into the model's weights. A step towards giving language models durable memory and fast adaptation. Blog: https://
pub.sakana.ai/doc-to-lora/
By
–
The only open source land that's better than DeepSeek is DeepSeeker.

By
–
Qwen3.5 Flash is live on Poe! A fast and efficient multimodal model that processes text and images seamlessly. Built with linear attention and a sparse mixture-of-experts architecture, it delivers improved inference efficiency and stronger performance than the 3 series across