
Nvidia has nearly doubled over the last two years. (12x over last five). But it’s fallen since GPT-5 came out. People are no longer buying the hype.
LLMS
-
Opus vs Sonnet: Long-Horizon Planning and Context Window Capabilities
By
–
10x per generation on a task that requires actual long-horizon planning is something. Cowork personally surprises me a lot on what it can do in both good and bad ways. And TBH, sonnet cannot understand and follow large skill files nearly as good as opus. And Opus 1m context is
-

GPT Results as a Metaphor for Our Times
By
–
Nonsense beats coherent prose every time. Results are from GPT, but may perhaps be an apt metaphor for our time?
-
Claude AI Agent Executes Tasks in Terminal with Persistent Memory
By
–
3 of 5
What makes it different this time? Earlier AI tools only offered advice. Claude actually executes. It runs directly in your terminal, integrates across tools, maintains persistent memory, and follows rules that truly stick. Friction vanishes. Creativity explodes. -
Claude Code Delivers Team-Level Results Instantly for Professionals
By
–
Have you experienced that “Claude-pilled” moment? The Wall Street Journal captured it perfectly. It is the exact instant when professionals hand real high-stakes work over to Anthropic’s Claude Code and suddenly see results that once demanded entire teams and months of effort
-
Transparency and Chinese Open-Source Models in Composer 2
By
–
For transparency reasons, I believe it would have been better to include a direct reference to Kimi K2 in the blog post about Compoaer 2. Furthermore, it also demonstrates how good Chinese open-source models have become.
-

Nano Banana and Veo Added to OpenAI Compatibility Layer
By
–
Nano Banana and Veo are now supported in our OpenAI compat layer by updating 3 lines of code!
-

REDSearcher: Novel Framework for Advanced LLM Search Agents
By
–
Tired of LLMs getting lost on deep, complex search tasks, and costing a fortune doing it? The REDSearcher Team presents a novel framework designed to make LLMs elite long-horizon search agents. It cleverly generates high-quality, complex search tasks, actively trains models to
-
Aletheia AI Solves Problem Without Hints from HAI Card
By
–
You can take a look at the HAI card and the transcript. The author specified only the original problem, no hint was given to Aletheia.
-
New LM Reasoning Benchmarks for Complex Mathematical Objects
By
–
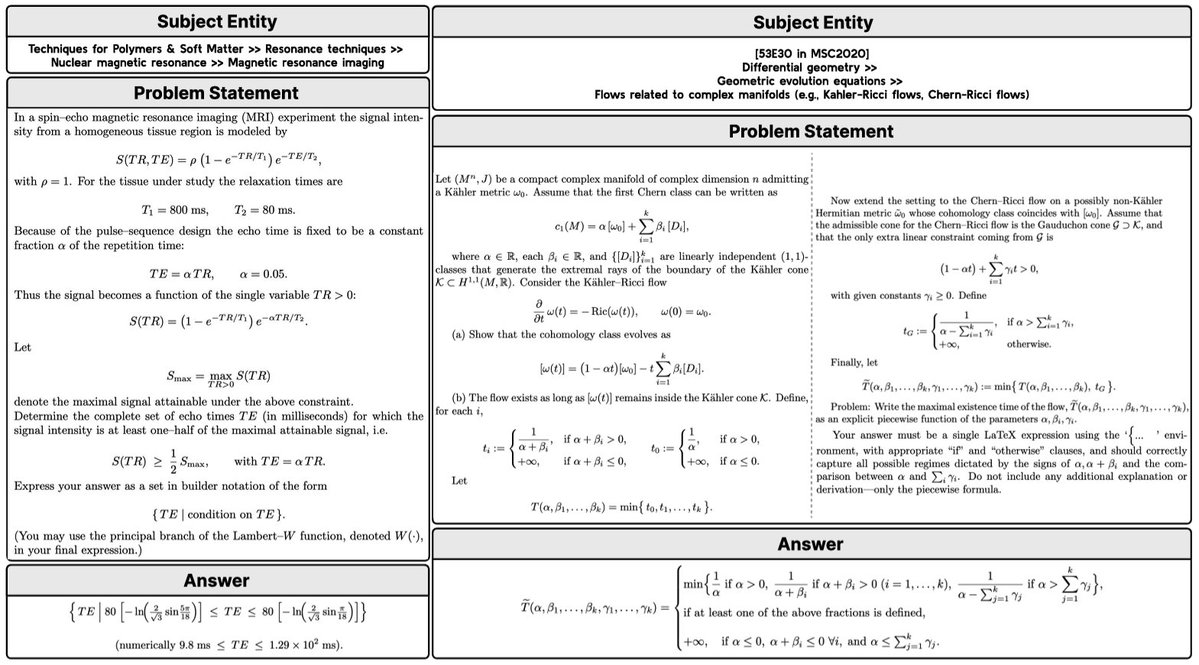
🧮New work from @AIatMeta & @LTIatCMU! LM reasoning benchmarks mostly use simple answers like numbers (AIME) or multiple-choice options (GPQA). But for complex mathematical objects, performance drops sharply. We propose a set of solutions to solve this: arxiv.org/abs/2603.18886