Everyone goes through an AI psychosis phase, for some it is 4o, for others it's Opus. For me it was Sydney.
GENERATIVE AI
-
Nvidia Eyes Model Serving at 10,000-20,000 Tokens Per Second
By
–
Nvidia's Chief Scientist Bill Dally says there's a path to serving relatively large models at 10,000 to 20,000 tokens per user per second.
— Marcelo P. Lima (@MarceloLima) 4 avril 2026
For context, Opus 4.6 is ~43 and Grok 4.2 Beta is ~251 tokens/user/s 🤯 pic.twitter.com/mbZNFfWgUbNvidia's Chief Scientist Bill Dally says there's a path to serving relatively large models at 10,000 to 20,000 tokens per user per second. For context, Opus 4.6 is ~43 and Grok 4.2 Beta is ~251 tokens/user/s 🤯 [Translated from EN to English]
-
Hidden Gems: Underrated Datasets on Hugging Face Hub
By
–
Huggingface hub has so many underrated datasets ngl ! This is one among them, best part it can be used for both SFT and RL (if used properly) huggingface.co/datasets/jupy… Any other such underrated datasets/models/envs, drop them below
→ View original post on X — @clementdelangue, 2026-04-04 17:38 UTC
-
Human Cognitive Errors vs LLM Hallucinations Explained
By
–
So many people are confused about the relation between human cognitive errors and LLM hallucinations that I wrote this short explainer two years ago. Since many of those confusions persist, I am reposting:
-
RL rewards bias: next frontier is uncertainty tolerance
By
–
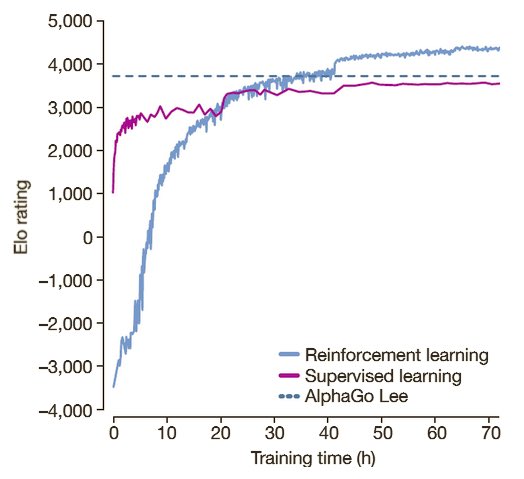
the direction became clear with AlphaGo 10 years ago, history repeats itself William Fedus (@LiamFedus) RL against verifiable rewards in LLMs has clearly opened a very powerful regime. It works, and because it works, there is a strong tendency to view more and more problems through that lens. You optimize for tasks where the reward is clean, where success is easy to check, where the feedback loop closes quickly. This is productive and will keep paying off. But it also creates a bias: you start emphasizing what is legible to the training setup, not necessarily what is most valuable. Scientific reasoning is a good example. Not every step in science is something that can be cleanly graded at the moment it is produced. A hypothesis can later fail experimentally and still have been exactly the right kind of thinking at the time: creative, mechanistically grounded, and responsive to the available evidence. “Turns out to be wrong” does not imply “was low-quality thinking”. A big part of the next frontier will be AI systems that can operate well under this kind of uncertainty, just like a big part of the last one was RL against verifiable rewards. — https://nitter.net/LiamFedus/status/2040462826851201256#m
→ View original post on X — @ceobillionaire, 2026-04-04 17:26 UTC
-

Complete Roadmap for Learning Agentic AI and Full-Stack Intelligence
By
–
Roadmap to learn Agentic AI 🚀 AI fundamentals Python + frameworks LLMs Agents architecture Memory + RAG Planning & decision-making RL & self-improvement Deployment Real-world automation Agentic AI = full-stack intelligence. Credit: Tiksly #AgenticAI #LLM #RAG #A
→ View original post on X — @ingliguori, 2026-04-04 17:25 UTC
-
Five Tech Companies Launch AI Health Chatbots for Consumers
By
–
This year 5 tech companies have introduced AI chatbots to consumers for health support @AnthropicAI @perplexity_ai @OpenAI @Microsoft @amazon @nicnguyen, a @WSJ journalist, tried some out.
— Eric Topol (@EricTopol) 4 avril 2026
gift link https://t.co/vwO261Q6qB pic.twitter.com/VFPyvc1P9OThis year 5 tech companies have introduced AI chatbots to consumers for health support @AnthropicAI @perplexity_ai @OpenAI @Microsoft @amazon @nicnguyen, a @WSJ journalist, tried some out. gift link wsj.com/tech/ai/health-data-…
→ View original post on X — @erictopol, 2026-04-04 17:19 UTC
-
New AI News Aggregator Better Than Algorithm
By
–
Your Saturday Ai news: https://
alignednews.com/ai I built this to be way better than the algorithm. It is a new way to read X’s AI world. If you get value from this let me know. -
LLM NPC Implementation with Custom Prompts for Each Agent
By
–
it’s not actually a custom GPTs in the ChatGPT sense but a LLM call w unique prompts for each NPC
-
LLM-Powered Personal Knowledge Bases: Building Wiki Systems with AI Agents
By
–
Wow, this tweet went very viral! I wanted share a possibly slightly improved version of the tweet in an "idea file". The idea of the idea file is that in this era of LLM agents, there is less of a point/need of sharing the specific code/app, you just share the idea, then the other person's agent customizes & builds it for your specific needs. So here's the idea in a gist format: gist.github.com/karpathy/442… You can give this to your agent and it can build you your own LLM wiki and guide you on how to use it etc. It's intentionally kept a little bit abstract/vague because there are so many directions to take this in. And ofc, people can adjust the idea or contribute their own in the Discussion which is cool. Andrej Karpathy (@karpathy) LLM Knowledge Bases Something I'm finding very useful recently: using LLMs to build personal knowledge bases for various topics of research interest. In this way, a large fraction of my recent token throughput is going less into manipulating code, and more into manipulating knowledge (stored as markdown and images). The latest LLMs are quite good at it. So: Data ingest: I index source documents (articles, papers, repos, datasets, images, etc.) into a raw/ directory, then I use an LLM to incrementally "compile" a wiki, which is just a collection of .md files in a directory structure. The wiki includes summaries of all the data in raw/, backlinks, and then it categorizes data into concepts, writes articles for them, and links them all. To convert web articles into .md files I like to use the Obsidian Web Clipper extension, and then I also use a hotkey to download all the related images to local so that my LLM can easily reference them. IDE: I use Obsidian as the IDE "frontend" where I can view the raw data, the the compiled wiki, and the derived visualizations. Important to note that the LLM writes and maintains all of the data of the wiki, I rarely touch it directly. I've played with a few Obsidian plugins to render and view data in other ways (e.g. Marp for slides). Q&A: Where things get interesting is that once your wiki is big enough (e.g. mine on some recent research is ~100 articles and ~400K words), you can ask your LLM agent all kinds of complex questions against the wiki, and it will go off, research the answers, etc. I thought I had to reach for fancy RAG, but the LLM has been pretty good about auto-maintaining index files and brief summaries of all the documents and it reads all the important related data fairly easily at this ~small scale. Output: Instead of getting answers in text/terminal, I like to have it render markdown files for me, or slide shows (Marp format), or matplotlib images, all of which I then view again in Obsidian. You can imagine many other visual output formats depending on the query. Often, I end up "filing" the outputs back into the wiki to enhance it for further queries. So my own explorations and queries always "add up" in the knowledge base. Linting: I've run some LLM "health checks" over the wiki to e.g. find inconsistent data, impute missing data (with web searchers), find interesting connections for new article candidates, etc., to incrementally clean up the wiki and enhance its overall data integrity. The LLMs are quite good at suggesting further questions to ask and look into. Extra tools: I find myself developing additional tools to process the data, e.g. I vibe coded a small and naive search engine over the wiki, which I both use directly (in a web ui), but more often I want to hand it off to an LLM via CLI as a tool for larger queries. Further explorations: As the repo grows, the natural desire is to also think about synthetic data generation + finetuning to have your LLM "know" the data in its weights instead of just context windows. TLDR: raw data from a given number of sources is collected, then compiled by an LLM into a .md wiki, then operated on by various CLIs by the LLM to do Q&A and to incrementally enhance the wiki, and all of it viewable in Obsidian. You rarely ever write or edit the wiki manually, it's the domain of the LLM. I think there is room here for an incredible new product instead of a hacky collection of scripts. — https://nitter.net/karpathy/status/2039805659525644595#m