Coding skills unlock Ai income pic.twitter.com/R3neDP8ktl
— Satya Mallick (@LearnOpenCV) 10 décembre 2025
Coding skills unlock Ai income
By
–
Coding skills unlock Ai income pic.twitter.com/R3neDP8ktl
— Satya Mallick (@LearnOpenCV) 10 décembre 2025
Coding skills unlock Ai income

By
–
Introducing Jais-2 – a major leap for Arabic AI. Co-developed with @G42ai , Inception, and @mbzuai
, Jais-2 is a family of Arabic models built end-to-end on Cerebras from pretraining to inference. Jais-2 70B runs at 2,000 tokens/sec – 20x faster than leading LLMs. It brings deep
By
–
Meta is working on a new proprietary frontier AI model called “Avocado” according to CNBC. “We were expecting the model to be released before the end of this year, but that the plan now is for that to happen in the first quarter of 2026.” Meta will be back
By
–
Great work from @DeepLcom advancing real-time AI translation for millions of its customers, powered by NVIDIA AI infrastructure.
By
–
I recommend you try Suno: If you are a musician, you should not be fooled. This tool produces music more innovative than 90% of the award-winning artists at the Victoires de la musique.
By
–
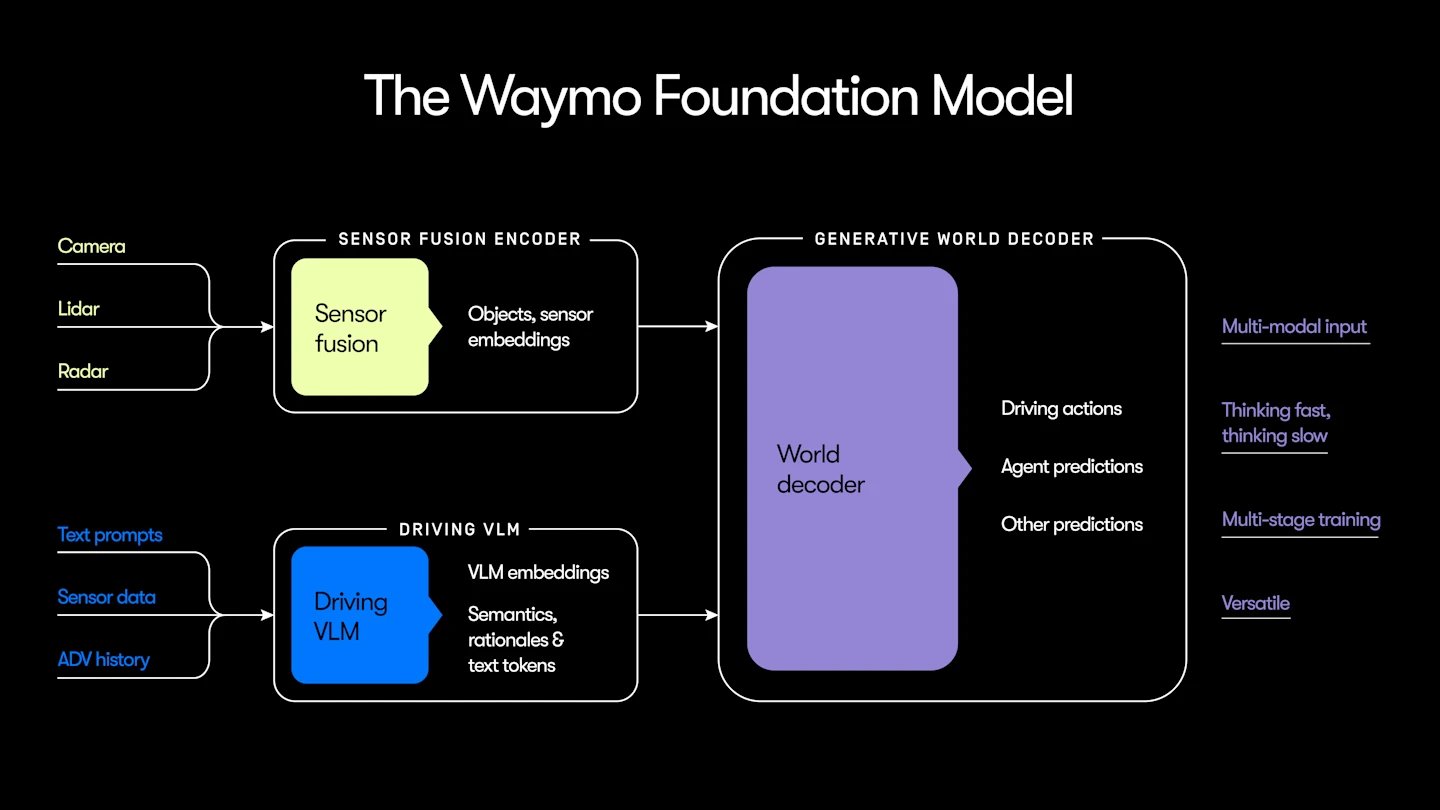
My sense is that @Waymo has been using large models for awhile (plus lots of GOFE for sensor pre-processing, system bootstrapping, data avalanching, and ongoing safety). One clue is the “thinking fast and slow” note on the image.
By
–
VLM on Edge Part 3: VLM Frameworks Setup and Inference
— Satya Mallick (@LearnOpenCV) 9 décembre 2025
The ultimate guide to deploying Vision Language Models on resource constrained hardware!
In this video we break it down further with the following.
✅Complete CUDA Math Library tailored for NVIDIA Jetson Orin Nano
✅Fail… pic.twitter.com/JVMviNbdIC
VLM on Edge Part 3: VLM Frameworks Setup and Inference
The ultimate guide to deploying Vision Language Models on resource constrained hardware! In this video we break it down further with the following.
Complete CUDA Math Library tailored for NVIDIA Jetson Orin Nano
Fail
By
–
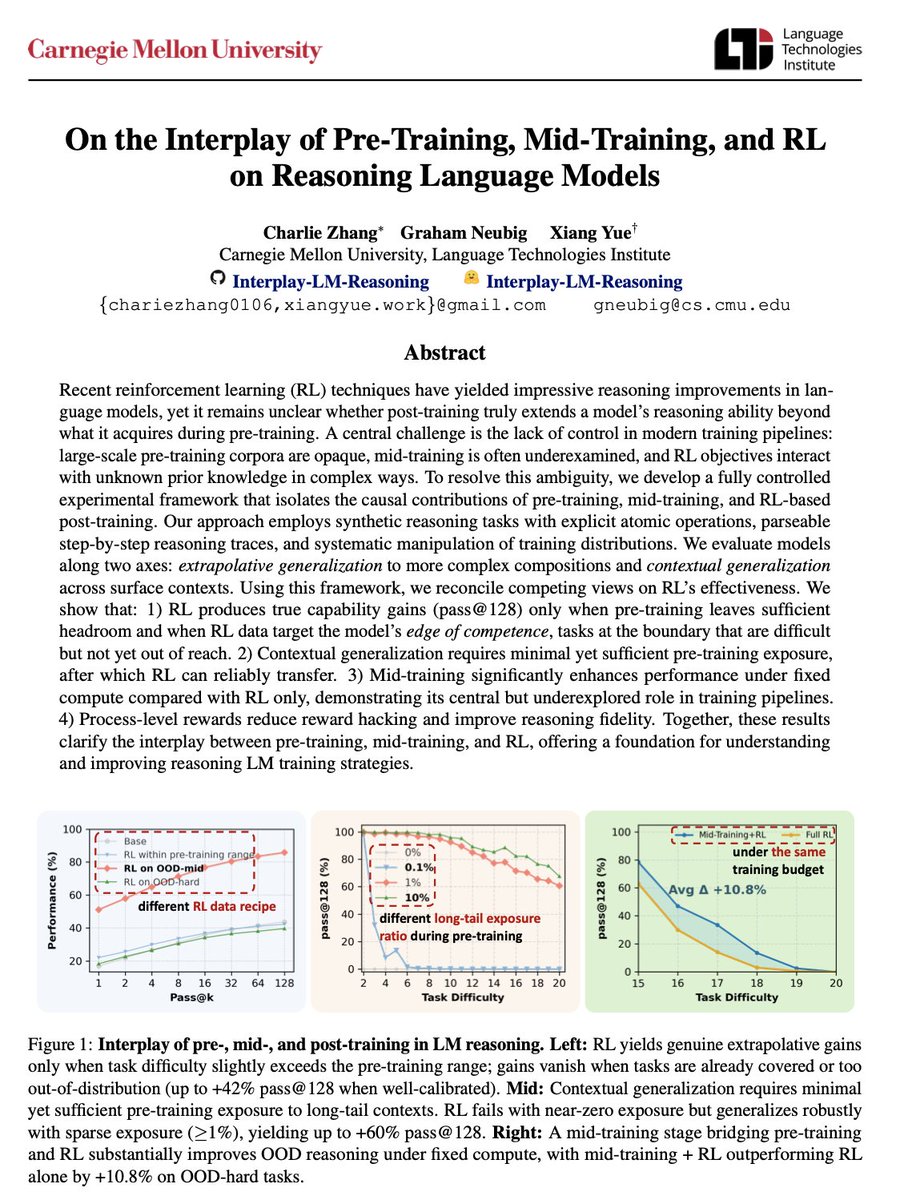
There are competing views on whether RL can genuinely improve base model's performance (e.g., pass@128). The answer is both yes and no, largely depending on the interplay between pre-training, mid-training, and RL. We trained a few hundreds of GPT-2 scale LMs on synthetic GSM-like reasoning data from scratch. Here are what we found: 🧵
By
–
ChatLLM model picks we keep coming back to: Everyday → GPT- 5.1 Coding → Sonnet 4.5 / Opus 4.5
Images → Nano Banana Pro, Midjourney → Sora 2, Seedance Pro
TTS → ElevenLabs, Hume
Fast tasks → Gemini Flash
Reasoning → GPT-5.1 Thinking Model switching handled

By
–
BREAKING : Notion might be testing GPT-5.2 internally under the "olive-oil-cake" codename. The codename is abstracted by Notion. Soon or not soon?