Microsoft’s MAI-Image-2 enters the top three AI image generators in the world https://
thenextweb.com/news/microsoft
-mai-image-2-top-three-arena-leaderboard?utm_source=twitter&utm_medium=share&utm_campaign=article-share-button&referral
… via @thenextweb
GENERATIVE AI
-
Microsoft’s MAI-Image-2 Ranks Top Three Global AI Image Generators
By
–
-

Jensen Huang and AI Leaders Discuss Open Models
By
–
The future of AI isn't being built in a vacuum. 🤝 NVIDIA Founder and CEO Jensen Huang sat down with the builders from AMP PBC, @bfl_ml, @Cursor_ai, @LangChain, @MistralAI, @EvidenceOpen, @Perplexity_ai, @Reflection_AI, @Thinkymachines & @Allen_ai to discuss the rapid rise of open frontier models. 🔗 Learn more: blogs.nvidia.com/blog/gtc-2026-news/#open-models-panel [Translated from EN to English]
-

AI Models Can Combine Concepts Compositionally
By
–
and they can also mix concepts compositionally "A pink elephant in beautiful Bariloche, Argentina"
-
Introducing GLM 5 Turbo for Research Paper Analysis
By
–
Introducing GLM 5 Turbo for understanding research papers 🚀
— alphaXiv (@askalphaxiv) 19 mars 2026
Highlight any section of a paper to ask questions and “@” other papers for quick context, comparisons, and benchmark references pic.twitter.com/WKPGQP3ExMIntroducing GLM 5 Turbo for understanding research papers Highlight any section of a paper to ask questions and “@” other papers for quick context, comparisons, and benchmark references
-
AI Writing Guides: Beyond Human-Like Generation Techniques
By
–
not really, the point of the guide isn't to sound like katie! it's to get as much information about making writing that sounds like katie—quite a different use case not all writing needs to sound like a human!
-
Self-Orchestrating AI Agents: The Next Major Breakthrough in LLM Performance
By
–
It’s happening: nitter.net/nousresearch/status/20… Matt Shumer (@mattshumer_) Agents that natively self-orchestrate, managing their own context, tools, and sub-agents, are the next big unlock in LLM performance. Right now, a skilled engineer building an optimized harness, with thoughtful data flow, separation of concerns, sub-agent management, etc., can make dramatic improvements over baseline for specific tasks. If a model could do this itself, that’d be a major step forward. You give it an objective and a set of tools, and it figures out the optimal way to orchestrate itself to do the task. For example, I’m building a very primitive AI scientist that I’ll open-source soon. Most of the work isn’t in the prompt, it’s in the harness… what the orchestrator sees, what sub‑agents see, what gets shared between them and when, where we summarize vs. pass raw data, and which tools each agent controls. Doing this allows me to dramatically improve what the model can do on its own. If a model can effectively design its own harness for a given problem, it’d be a huge step forward. My bet: self-orchestrating models… ones that manage their own context, tools, and sub-agents, will move the frontier almost as much as the jump from chatbot → reasoning did. Maybe more. — https://nitter.net/mattshumer_/status/1991942387145322715#m
→ View original post on X — @mattshumer_, 2026-03-19 21:48 UTC
-
M²RNN: Non-Linear RNNs with Matrix-Valued States for Language Modeling
By
–
Excited to share our latest work: M²RNN! We’ve revisited non-linear RNNs and found that expanding the hidden state to a matrix (Matrix-to-Matrix) significantly improves language modeling while the non-linear recurrence enables expressivity beyond TC⁰. Key highlights: – Efficient Scaling: Our expansion mechanism leverages. Tensor Cores for high-throughput training. – Better Long-Context Performance: Beats SOTA hybrid linear attention models by 8 points on LongBench. – Hybrid Models: Replacing just ONE layer in a hybrid stack gives massive gains with minimal overhead. This establishes non-linear RNNs as a primary building block for the next generation of LLMs. Mayank Mishra (@MayankMish98) Introducing M²RNN: Non-Linear RNNs with Matrix-Valued States for Scalable Language Modeling We bring back non-linear recurrence to language modeling and show it's been held back by small state sizes, not by non-linearity itself. 📄 Paper: arxiv.org/abs/2603.14360 💻 Code: github.com/open-lm-engine/lm… 🤗 Models: huggingface.co/collections/o… — https://nitter.net/MayankMish98/status/2034681226217595333#m
→ View original post on X — @berkeley_ai, 2026-03-19 21:41 UTC
-
AI struggles transferring coding knowledge across programming languages
By
–
Very reasonable! But isn't that kinda the point of this discussion? AI can't take what it knows about coding in languages with lots of data, and re-use it for coding in a different language effectively. Even if I add reference docs, examples, etc to prompt context.
-
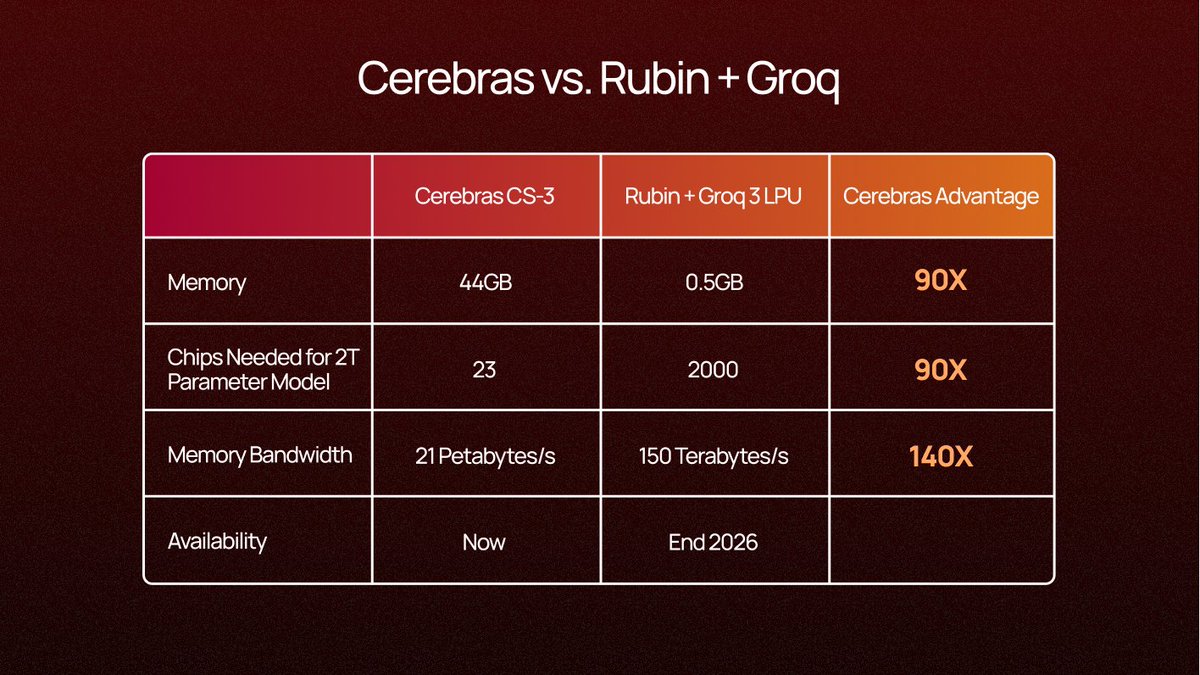
Cerebras Wafer Scale Advantage Over NVIDIA Groq Inference Chips
By
–
Problem solved. ✅ Andrew Feldman (@andrewdfeldman) NVIDIA's biggest GTC announcement was a $20 billion bet on the same problem we solved 6 years ago. Their next-gen inference chip – not available yet – has 140x less memory bandwidth than @cerebras. To run a single 2 trillion parameter model, you need 2,000+ Groq chips. On Cerebras, that's just over 20 wafers. Even paired with GPUs, Groq maxes out at ~1,000 tokens per second. We run at thousands of tokens per second today. And every day. In production now. Why? When you connect 2,000 chips together, every interconnect has latency. Every cable has overhead. It doesn't matter what your memory bandwidth is on paper if you're bottlenecked by the wiring between thousands of tiny chips. We solved this with wafer scale. One integrated system. Little interconnect tax. Jensen told the world that fast inference is where the value is. He’s right – it’s why the world’s leading AI companies and hyperscalers are choosing Cerebras. — https://nitter.net/andrewdfeldman/status/2034015373595672594#m
-
50 ML Projects to Understand LLMs and Transformer Mechanisms
By
–
50 ML projects to understand LLMs — Investigate transformer mechanisms through data analysis, visualization, and experimentation: http://
amzn.to/4aPfP7q
—————
#AI #GenAI #MachineLearning #DataScientist #DataScience