After the single box ran, we scaled it to 2 and 16 systems with linear scaling. There were no model & code changes required.
Megatron
DeepSpeed
Sharding The model lives on a single block of memory. No need to break it up. The whole thing trains like one giant GPU.
COMPUTING
-

Linear Scaling AI Model Training Across Multiple Systems
By
–
-
MemoryX Deploys 55TB DDR5 Memory in Commodity Server Format
By
–
MemoryX uses commodity DDR5 memory in a 1U server format, making it super easy to procure & configure. We employed one rack for CS-3 & networking and another rack for a 55 TB MemoryX partition.
-
Cerebras MemoryX: 55TB External Memory for Trillion Parameters
By
–
Cerebras Wafer Scale Cluster uses unique, terabyte-scale external memory device called MemoryX to store model weights. For Sandia’s run, Cerebras configured a 55 terabyte MemoryX device – enough to comfortably store 1T parameters and optimizer states.
-
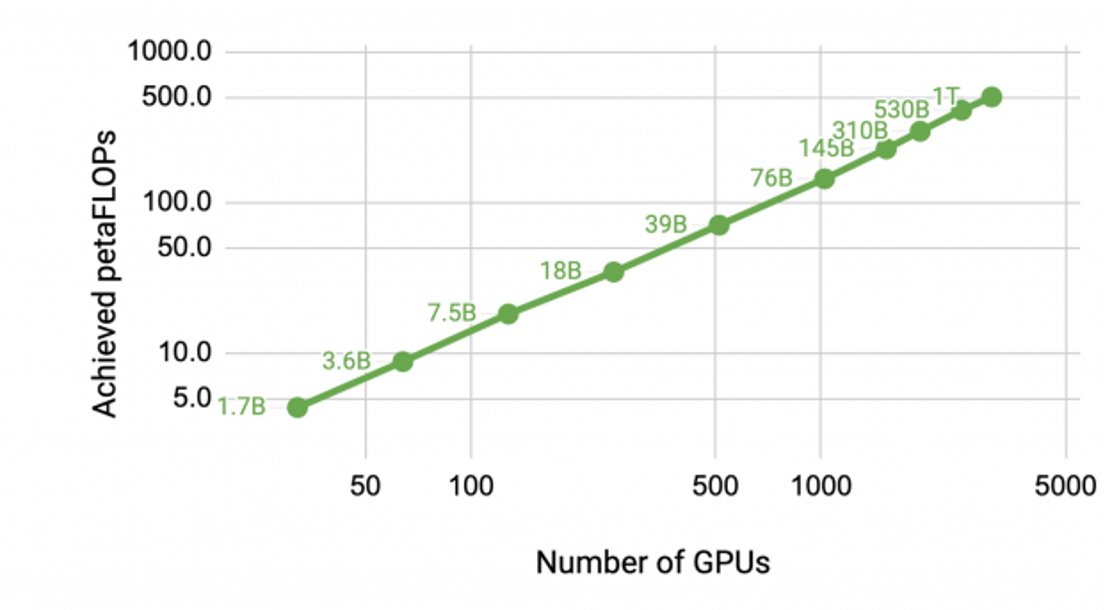
Trillion Parameter Models Demand Massive GPU Infrastructure Investment
By
–
Trillion parameter models require terabytes of memory. Thousands of GPUs must be procured and connected just to store the model weights. It takes months to bring up a working cluster of this scale. Nvidia's own chart below:
-

Cerebras CS-3 trains 1 trillion parameter model efficiently
By
–
Cerebras Systems + Sandia National Labs have demonstrated training of a 1 trillion parameter model on a single CS-3 system (!) This is ~1% the footprint & power of an equivalent GPU cluster.
-

DuckDB 1.0: High-Speed Analytics Engine for AI Workflows
By
–
#DuckDB Redefining Analytics for #AI 100x faster Parquet queries vs. Pandas Process billions of rows in seconds In-process #SQL <10MB RAM for setup Integrated #Python/#R for #ML workflows Version 1.0 stability + @MotherDuckHQ backing #DataAnalytics #TechTrends
-
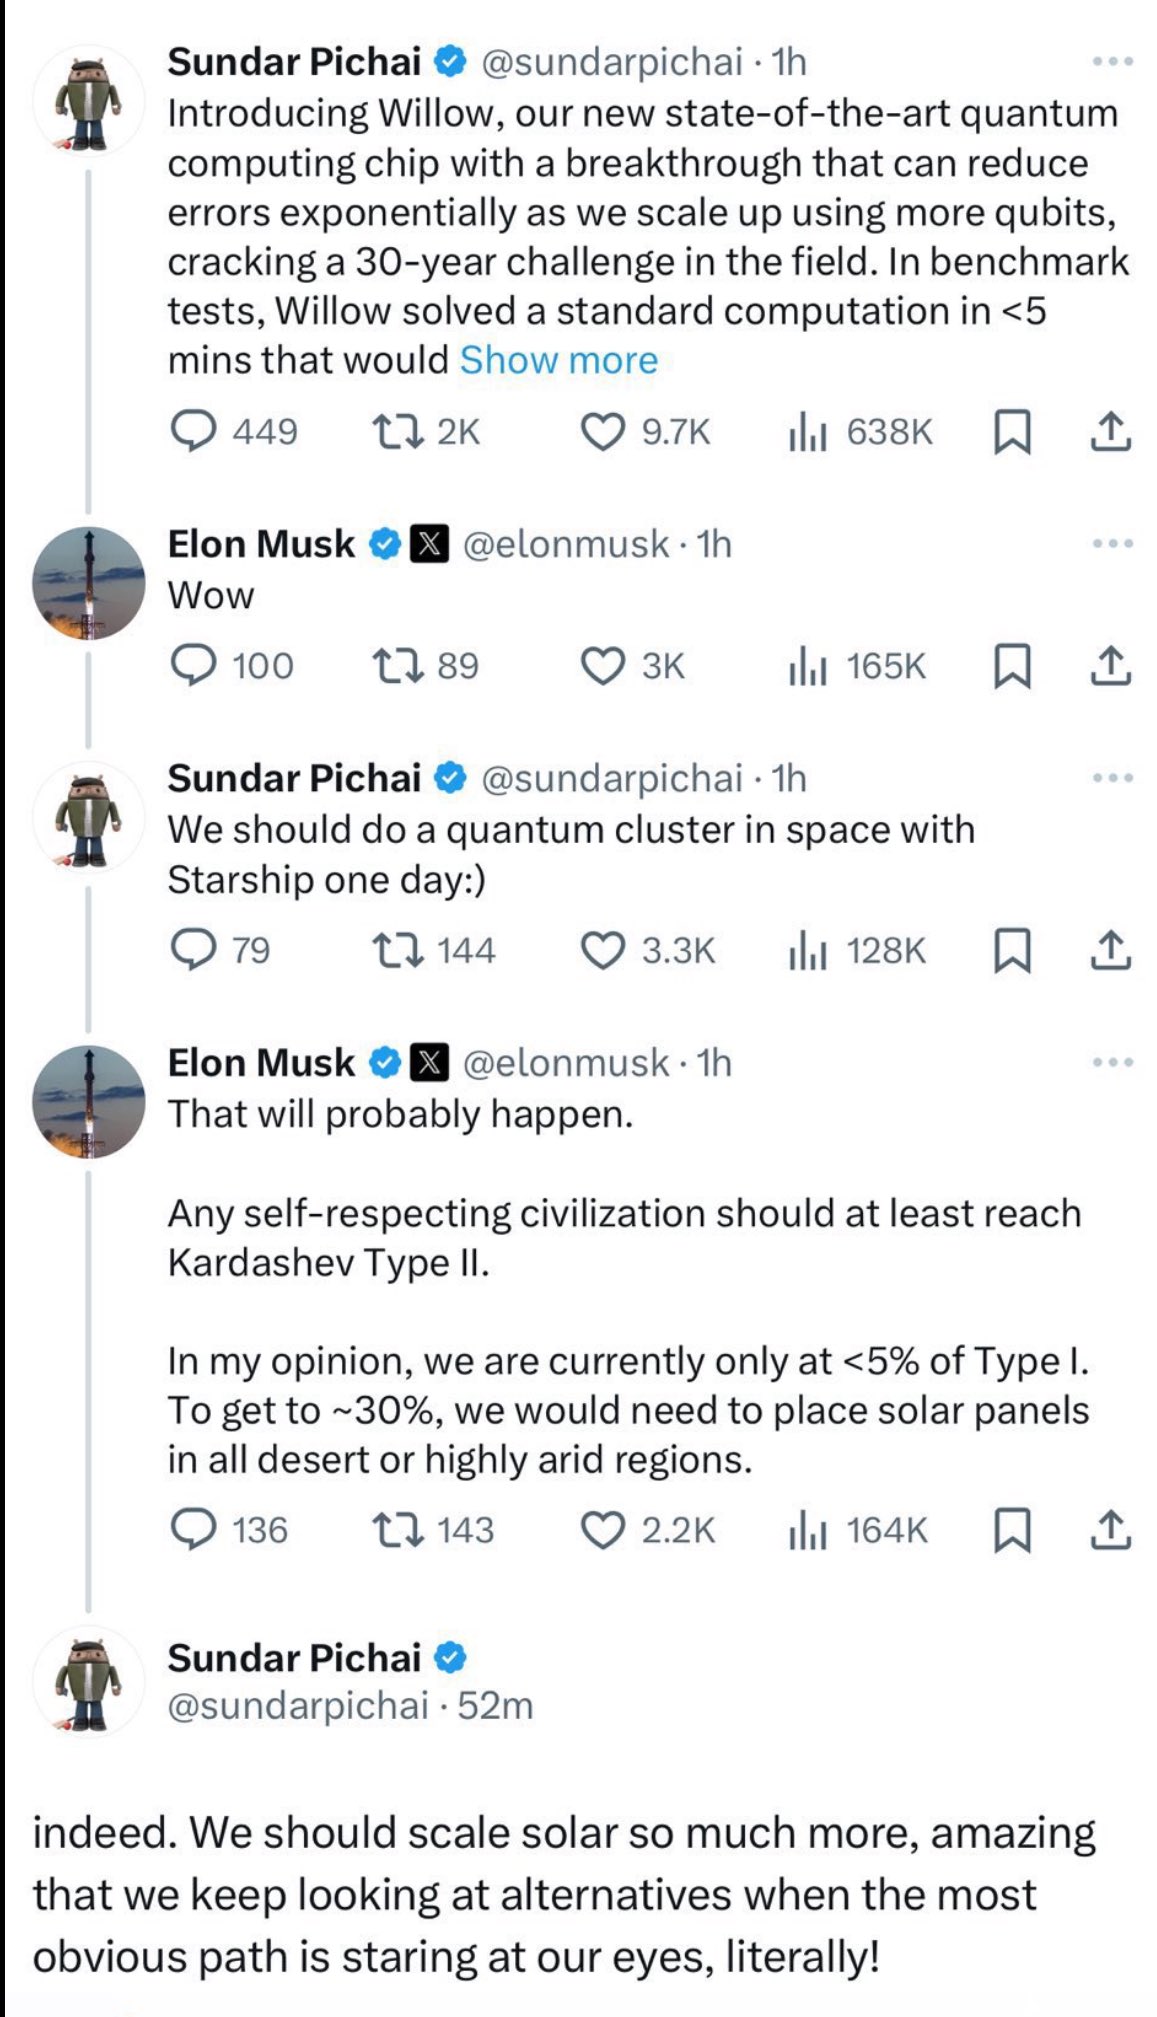
Elon Musk and Google Plan Giant Quantum Computer in Space
By
–
Pendant que les politiciens français se déchirent sur des affaires de corneculs debiles @elonmusk et @sundarpichai le patron de @google prévoient de construire un ordinateur quantique géant dans l’espace LA FRANCE VA COULER
-
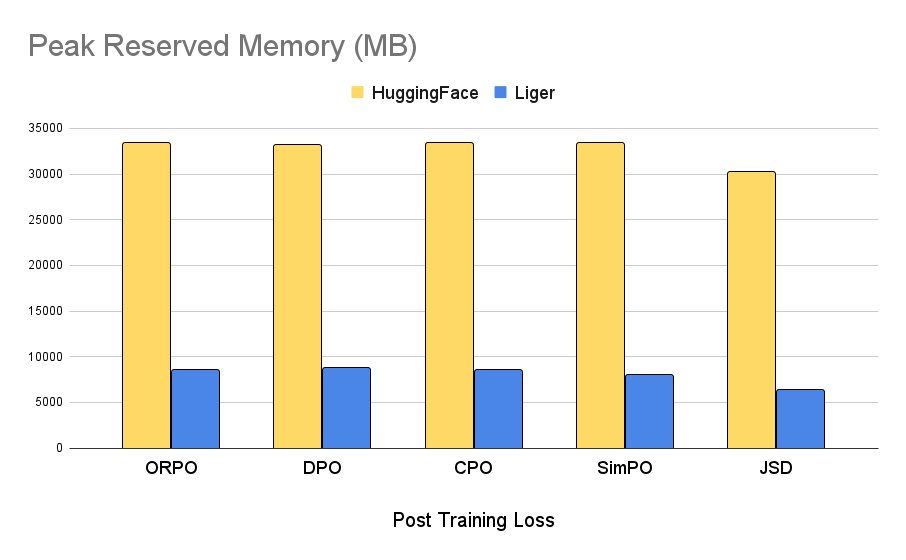
Torch.compile() Outperforms Triton for Kernel Optimization
By
–
It's interesting that this "kernel" is designed for torch.compile(), so it's Python code but turns out faster! Conversely, some of the other Liger kernels are Triton and I measured them as slower than torch.compile'd versions.
-

Computer Neural Networks Make Major Comeback in 2026
By
–
On that note, we're so back (#1 Computer Neural Networks)
-
GPU Availability Challenges for AI Projects
By
–
I have an open thread on slack – if the GPU gods allow, then we shall!