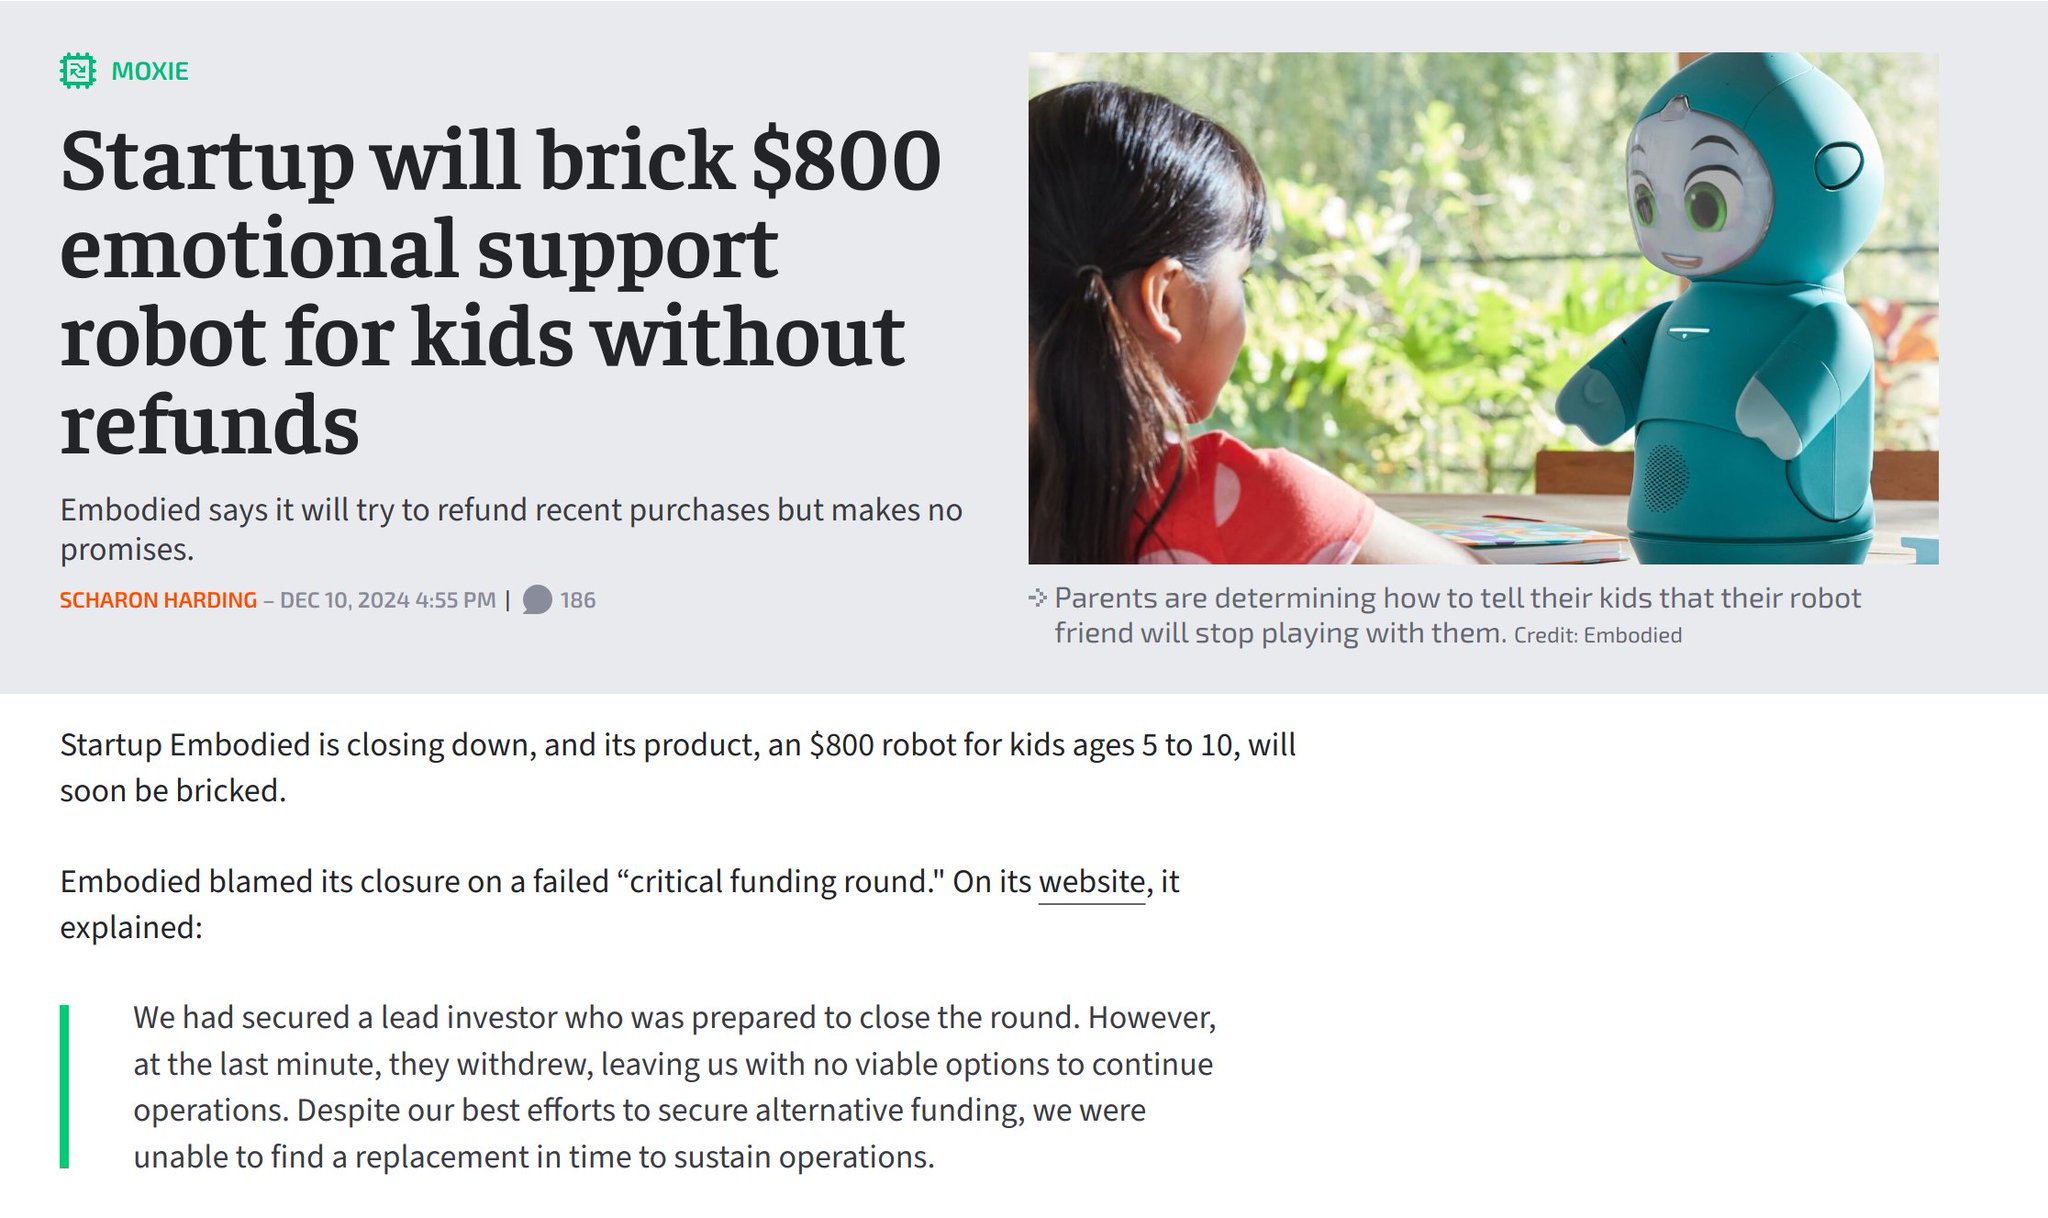
robots will need to run ai locally take my words
COMPUTING
-
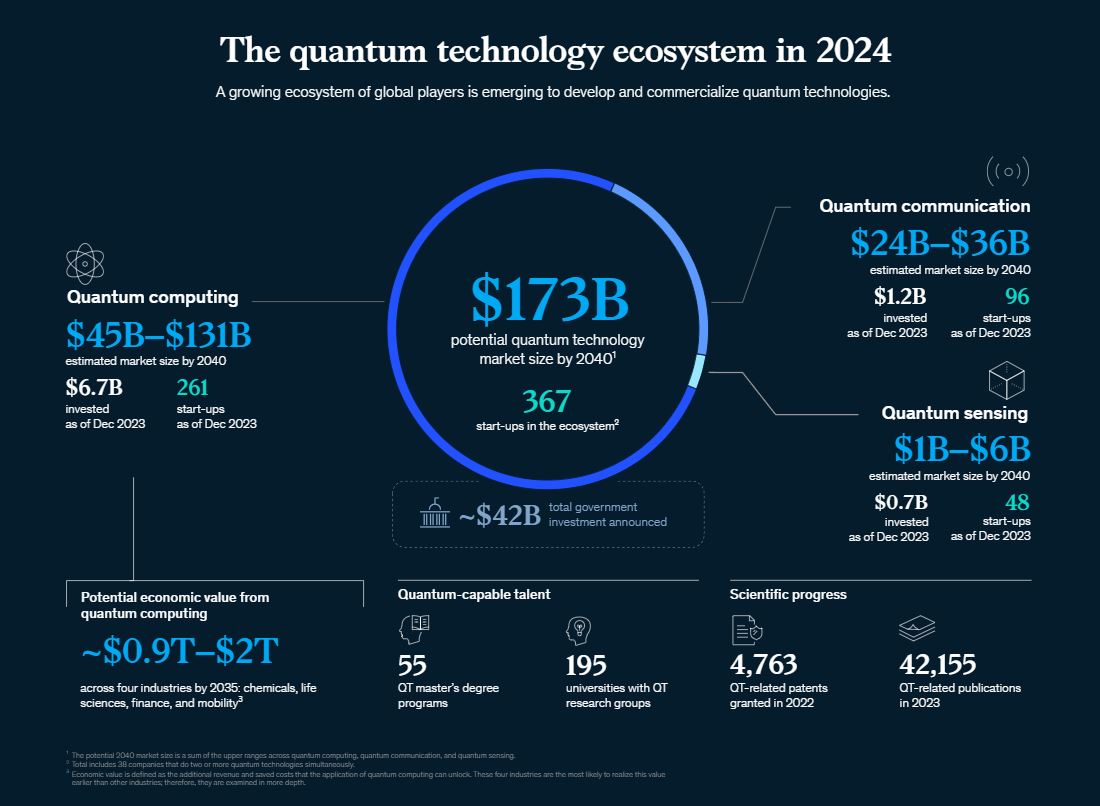
Quantum Tech Sector Growth: $1.7B Funding and $2T Potential
By
–
Is Quantum Tech (QT) on the #CSuite Rader? $1.71B private QT funding in 2023 367K QT grads in 2023 (↑8.3%) $42B global public QT funding (↑50%) $2T potential value by 2035 #QuantumComputing #Innovation @McKinsey_MGI #Willow @Google
-
Intel AIPC: Exploring AI Personal Computing Hardware
By
–
For those of you who want to explore more about #AIPC, check this out https://
intel.ly/4ejGw31 -
Feed Screw Automation: Optimizing Bottle Positioning Methods
By
–
Timing feed screw lifting bottles from horizontal to vertical position ‼️
— Pascal Bornet (@pascal_bornet) 12 décembre 2024
Engineering meets education = Seeing 👀 is believing
Do you see any simpler or better ways to turn things ?
Source: Mohammad Safarabadi #automation #simulation pic.twitter.com/PCVNwffIeiTiming feed screw lifting bottles from horizontal to vertical position Engineering meets education = Seeing is believing Do you see any simpler or better ways to turn things ? Source: Mohammad Safarabadi #automation #simulation
-
AlphaChip: AI Revolution in Computer Chip Design
By
–
How AlphaChip transformed computer chip design
#AI #AIio #BigData #ML #NLU #Futureofwork @chrismessina @ChristopherIsak @davidwkenny @debashis_dutta @petitegeek @fabiomoioli @GaryMarcus @asokan_telecom -
Llama 3.3 70B on Cerebras Inference: Santa chatbot demo
By
–
What will Santa bring you? Ask him yourself with a little help from the friendly elves at @tavus and the speed of Cerebras Inference at 2200+ t/s. All we want for Christmas is to see what you will do Llama 3.3 70B running on Cerebras Inference. Talk to Santa:
-
SambaNova Optimizes Meta’s Llama 3.3 for 400+ Token/Second Speed
By
–
Just days after @AIatMeta
's Llama 3.3 70B model dropped, we've optimized it for our RDU hardware & it's live on SambaNova Cloud! #AI devs, try it out now & experience speeds of 400+ tokens/second! Learn more here -
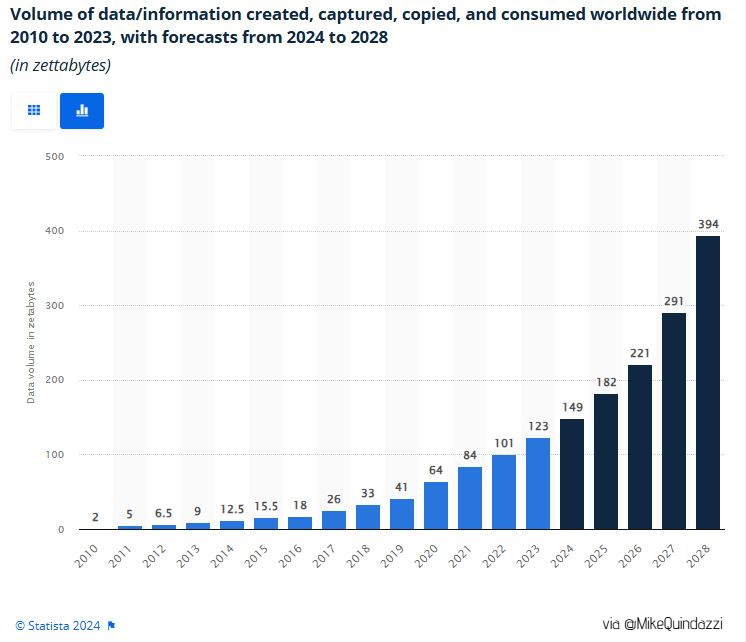
Data Explosion Accelerates: 197-Fold Growth by 2028
By
–
197-Fold #Data Explosion, #AI Eat Away! 2010: 2 ZB
2015: 15.5 ZB
2020: 64 ZB
2023: 123 ZB
2024: 149 ZB
2026: 221 ZB projected
2028: 394 ZB projected #IoT #Streaming #BigData @StatistaCharts -
Cerebras Trains Trillion-Parameter Models on Single CS-3
By
–
Learn more here: https://
cerebras.ai/press-release/
cerebras-demonstrates-trillion-parameter-model-training-on-a-single-cs-3-system
… https://
cerebras.ai/blog/introduci
ng-gigagpt-gpt-3-sized-models-in-565-lines-of-code
… -

Cerebras-GPT vs Megatron: Simplifying GPU Training Architecture
By
–
Nvidia is very proud of Megatron – it lets you train across thousands of GPUs! But it's 20K lines of code to manage the cluster. Cerebras-GPT is 500 lines of code. One block of memory. One logical accelerator. No distributed computing. Everyone who's used it calls it magic.