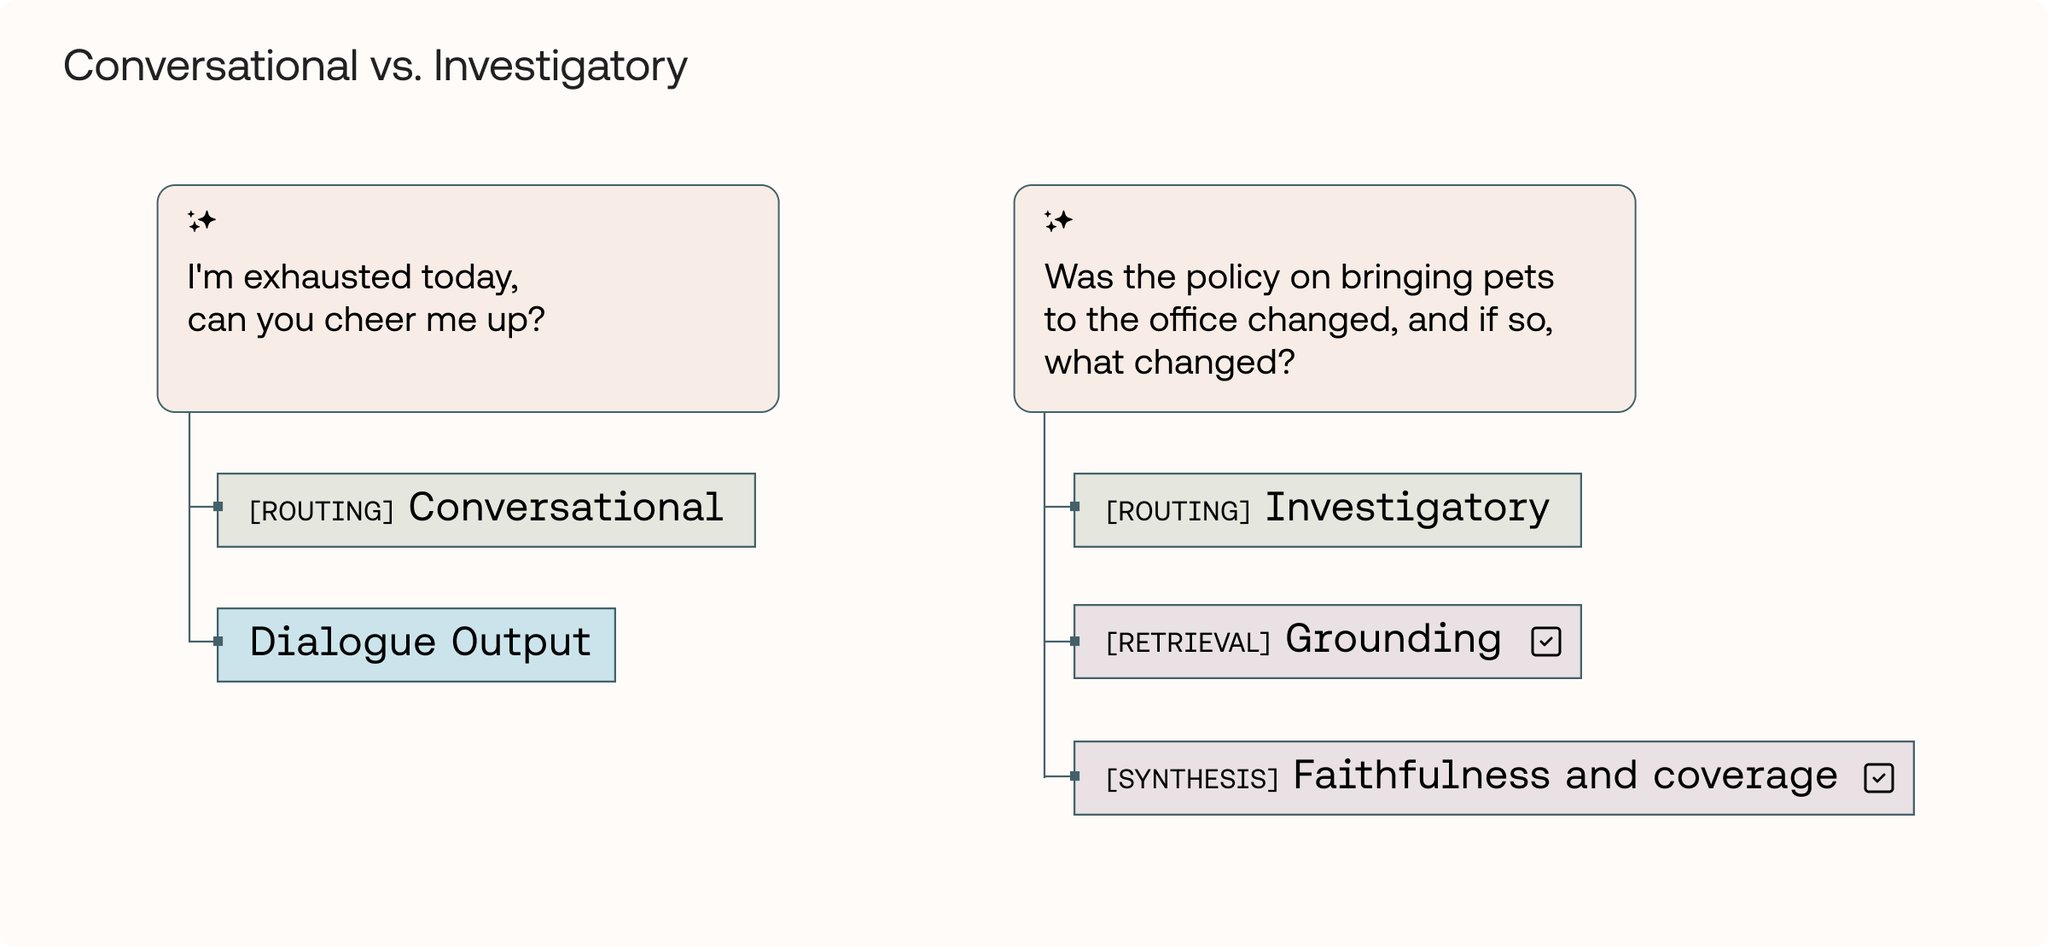
In a modular agent setup, a router first classifies the request as conversational or investigatory. If investigatory, a retrieval module fetches relevant docs [eval: grounding], and a synthesis module integrates the evidence into a response [eval: faithfulness, coverage].
CODE
-
Sim: Open-Source Platform for No-Code AI Agent Workflows
By
–
OpenClaw, but built for normal people.
— Akshay 🚀 (@akshay_pachaar) 26 février 2026
Sim is an open-source platform that lets you build AI agent workflows on a drag-and-drop canvas. Connect them to channels like Telegram and WhatsApp and deploy without writing a single line of code.
They also have a built-in Copilot that… pic.twitter.com/gFchHDH4gKOpenClaw, but built for normal people. Sim is an open-source platform that lets you build AI agent workflows on a drag-and-drop canvas. Connect them to channels like Telegram and WhatsApp and deploy without writing a single line of code. They also have a built-in Copilot that
-
The Future of Projects: From Corporate Hierarchies to AI Agent Utility
By
–
No one cares. Projects were always primarily a vanity signal for climbing human corporate hierarchies. Build something that people want to use and that’s all it matters now. Soon the only thing will matter is if your vibe coded projects are useful to other AI agents, and those
-
Vibecoders and AI-driven Code Generation with Markdown Files
By
–
Top vibecoders are writing thousands of lines of .md files every day.
-
GLM-5 Regression in Interactive Python Coding Performance
By
–
I think GLM-5 is a regression on interactive Python coding though, been using it almost daily and GLM 4.7 before that. The most likely culprit is DSA — and I conclude it's not straightforward to apply. Likely V4 manages better, but there will be tradeoffs.
-
Perplexity Computer: Multi-Agent AI Orchestrator for Autonomous Workflows
By
–
Perplexity just dropped "Computer"—va multi-agent orchestrator that unifies research, coding, and deployment into a single end-to-end workflow.
— Futurepedia – Learn to Leverage AI (@futurepedia_io) 26 février 2026
It uses 19 models (including Claude 4.6 & Gemini 3) to move projects from "to-do" to "done" autonomously.
The Highlights:
▪️True… pic.twitter.com/2OoEnqAlO3Perplexity just dropped "Computer"—va multi-agent orchestrator that unifies research, coding, and deployment into a single end-to-end workflow. It uses 19 models (including Claude 4.6 & Gemini 3) to move projects from "to-do" to "done" autonomously. The Highlights:
True -

SVG Benchmark Results: Shocking Performance Data Revealed
By
–
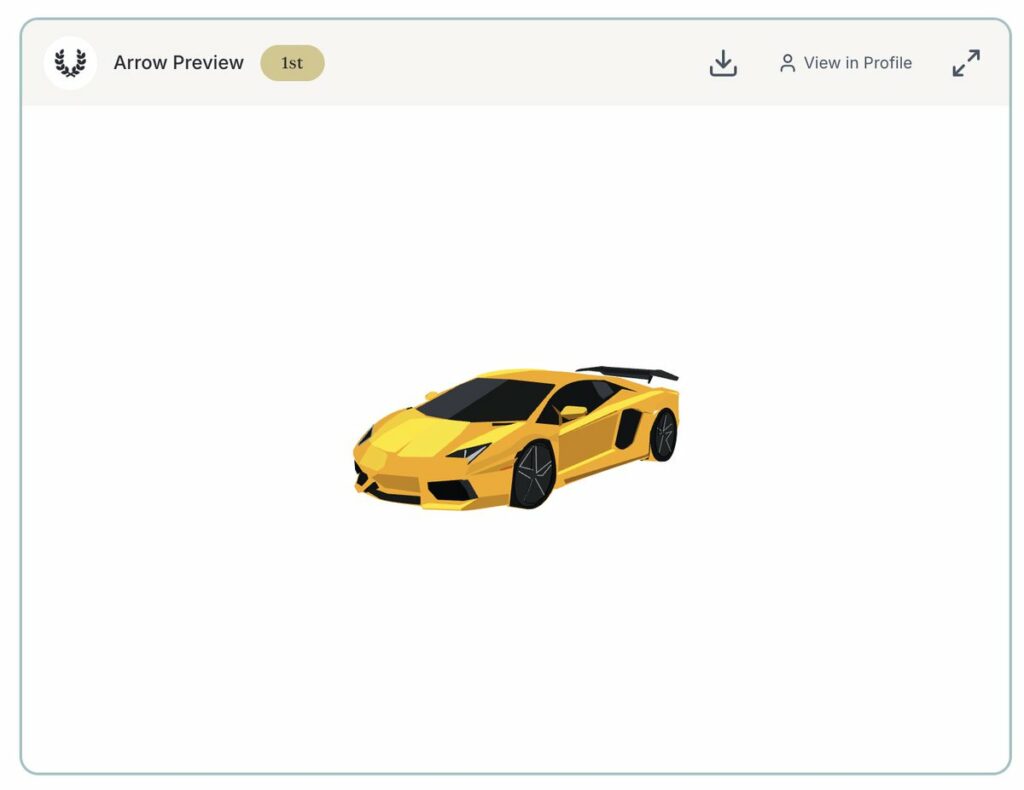
WTF… CHOI (@arrakis_ai) Holy..Shxt… SVG Benchmark is over.. — https://nitter.net/arrakis_ai/status/2026796385962721596#m
→ View original post on X — @arrakis_ai, 2026-02-25 23:13 UTC
-
GLM-5 Regression for Python Coding Tasks Compared to GLM 4.7
By
–
Alright, I'm calling it: GLM-5 is a regression from GLM 4.7 for Python coding. Subscribed to Z(.)ai on the basis of 4.7 as it reliably took over all my devops too, and been using GLM 5 since launch. But with multiple turns of Python writing/editing 5 regularly gets confused
-
From Prototype to Production App in Two Days Workshop
By
–
The distance between a vibe-coded prototype and a production app used to be years of experience. Now you can get there in two days. @hammer_mt
's upcoming workshop at @every covers it all—OAuth, databases, deployment. March 12–13. I'm guest instructing with @kieranklaassen
. -
1.2B LLM runs at 200 tokens per second in browser
By
–
1B model running over 200 tok/s in your browser 👀 https://t.co/JArzxn7FN8
— Maxime Labonne (@maximelabonne) 25 février 20261B model running over 200 tok/s in your browser 👀 Xenova (@xenovacom) Okay, this is actually insane… You can now run LFM2.5-1.2B-Thinking (a 1.2B parameter LLM from @LiquidAI) at over 200 tokens per second directly in your browser on WebGPU! 🤯 Zero install. Fully private. Blazingly fast. Powered by Transformers.js and ONNX Runtime Web — https://nitter.net/xenovacom/status/2026727703836004796#m
→ View original post on X — @maximelabonne, 2026-02-25 18:47 UTC