hey Scott – any repeatable patterns or something specific tripping you up? tip: you can point codex to your sessions and ask it to analyse them and point out prospective issues DMs open if there’s anyway we can help make the experience better
CODE
-
Grady Booch Birthday: UML Pioneer and Software Engineering Innovator
By
–
Happy birthday to Grady Booch, who helped develop the Unified Modeling Language (UML). He has also advanced the fields of software engineering & object-oriented design.
-
WordPress Categories for AI-Related Content
By
–
Several people have asked me for a link, so here it is:
-
M2.5: Agent-Focused AI for Engineering Tasks
By
–
The difference? M2.5 is built for agents, not chat. It doesn't assist you.
It plans architecture, writes modular code, handles edge cases, and optimizes performance.
Like an actual engineer. Try it: https://
platform.minimax.io Docs: https://
platform.minimax.io/docs/guides/te
xt-generation
… Coding Plan: -
Crypto Tracker Built in 4 Minutes
By
–
I tested it on real work.
— God of Prompt (@godofprompt) 27 février 2026
Prompt: “Build a crypto portfolio tracker with live prices and P&L”
One prompt → Full working app in 4 minutes.
No debugging. No iterations. Production-ready.
VIDEO IDEA: Screen recording: paste prompt, watch code generate, show final app running… pic.twitter.com/S5Ban0hTh6I tested it on real work. Prompt: “Build a crypto portfolio tracker with live prices and P&L” One prompt → Full working app in 4 minutes.
No debugging. No iterations. Production-ready. VIDEO IDEA: Screen recording: paste prompt, watch code generate, show final app running -
MiniMax M2.5 beats Opus 4.6 in coding benchmarks
By
–
Meet MiniMax M2.5.
— God of Prompt (@godofprompt) 27 février 2026
It beats Opus 4.6 on real coding benchmarks:
– SWE-Bench Verified: 80.2%
– 3x faster execution
– $1/hour flat rate
– Only 10B activated parameters (smallest Tier-1 model)
You can actually afford to run agents 24/7 now. pic.twitter.com/bjbUqDuGt9Meet MiniMax M2.5. It beats Opus 4.6 on real coding benchmarks: – SWE-Bench Verified: 80.2%
– 3x faster execution
– $1/hour flat rate
– Only 10B activated parameters (smallest Tier-1 model) You can actually afford to run agents 24/7 now. -
Cheaper AI coding model beats Claude
By
–
Everyone's paying $15/month for Claude to write code. I just found a model that codes BETTER than Opus 4.6, runs 3x faster, and costs $1/hour for unlimited scaling. Self-hosted. Always-on agents. 10B activated parameters. The agent economy just became profitable:
-
Doc-to-LoRA: Instant LLM Adaptation via Meta-Learned Hypernetworks
By
–
Doc-to-LoRA: What if you could online distill documents into your LLM weights without training?
— Robert Lange (@RobertTLange) 27 février 2026
🚀 Stoked to share our new work on instant LLM adaptation using meta-learned hypernetworks 📷📝
Building on our previous Text-to-LoRA work, we doc-condition a hypernetwork to… https://t.co/BLQCUgGvuX pic.twitter.com/Eu9z2kdt5aDoc-to-LoRA: What if you could online distill documents into your LLM weights without training? 🚀 Stoked to share our new work on instant LLM adaptation using meta-learned hypernetworks 📷📝 Building on our previous Text-to-LoRA work, we doc-condition a hypernetwork to output LoRA adapters, improving the base LLM's effective context window. The hypernetwork is meta-trained on 1000s of summarization tasks and shows remarkable compression capabilities at low latency 📈 🧑🔬 Work led by @tan51616 with @edo_cet & Shin Useka at @SakanaAILabs 📷 Sakana AI (@SakanaAILabs) We’re excited to introduce Doc-to-LoRA and Text-to-LoRA, two related research exploring how to make LLM customization faster and more accessible. pub.sakana.ai/doc-to-lora/ By training a Hypernetwork to generate LoRA adapters on the fly, these methods allow models to instantly internalize new information or adapt to new tasks. Biological systems naturally rely on two key cognitive abilities: durable long-term memory to store facts, and rapid adaptation to handle new tasks given limited sensory cues. While modern LLMs are highly capable, they still lack this flexibility. Traditionally, adding long-term memory or adapting an LLM to a specific downstream task requires an expensive and time-consuming model update, such as fine-tuning or context distillation, or relies on memory-intensive long prompts. To bypass these limitations, our work focuses on the concept of cost amortization. We pay the meta-training cost once to train a hypernetwork capable of producing tasks or document specific LoRAs on demand. This turns what used to be a heavy engineering pipeline into a single, inexpensive forward pass. Instead of performing per-task optimization, the hypernetwork meta-learns update rules to instantly modify an LLM given a new task description or a long document. In our experiments, Text-to-LoRA successfully specializes models to unseen tasks using just a natural language description. Building on this, Doc-to-LoRA is able to internalize factual documents. On a needle-in-a-haystack task, Doc-to-LoRA achieves near-perfect accuracy on instances five times longer than the base model's context window. It can even generalize to transfer visual information from a vision-language model into a text-only LLM, allowing it to classify images purely through internalized weights. Importantly, both methods run with sub-second latency, enabling rapid experimentation while avoiding the overhead of traditional model updates. This approach is a step towards lowering the technical barriers of model customization, allowing end-users to specialize foundation models via simple text inputs. We have released our code and papers for the community to explore. Doc-to-LoRA Paper: arxiv.org/abs/2602.15902 Code: github.com/SakanaAI/Doc-to-L… Text-to-LoRA Paper: arxiv.org/abs/2506.06105 Code: github.com/SakanaAI/Text-to-… — https://nitter.net/SakanaAILabs/status/2027240298666209535#m
→ View original post on X — @_yutaroyamada, 2026-02-27 09:41 UTC
-
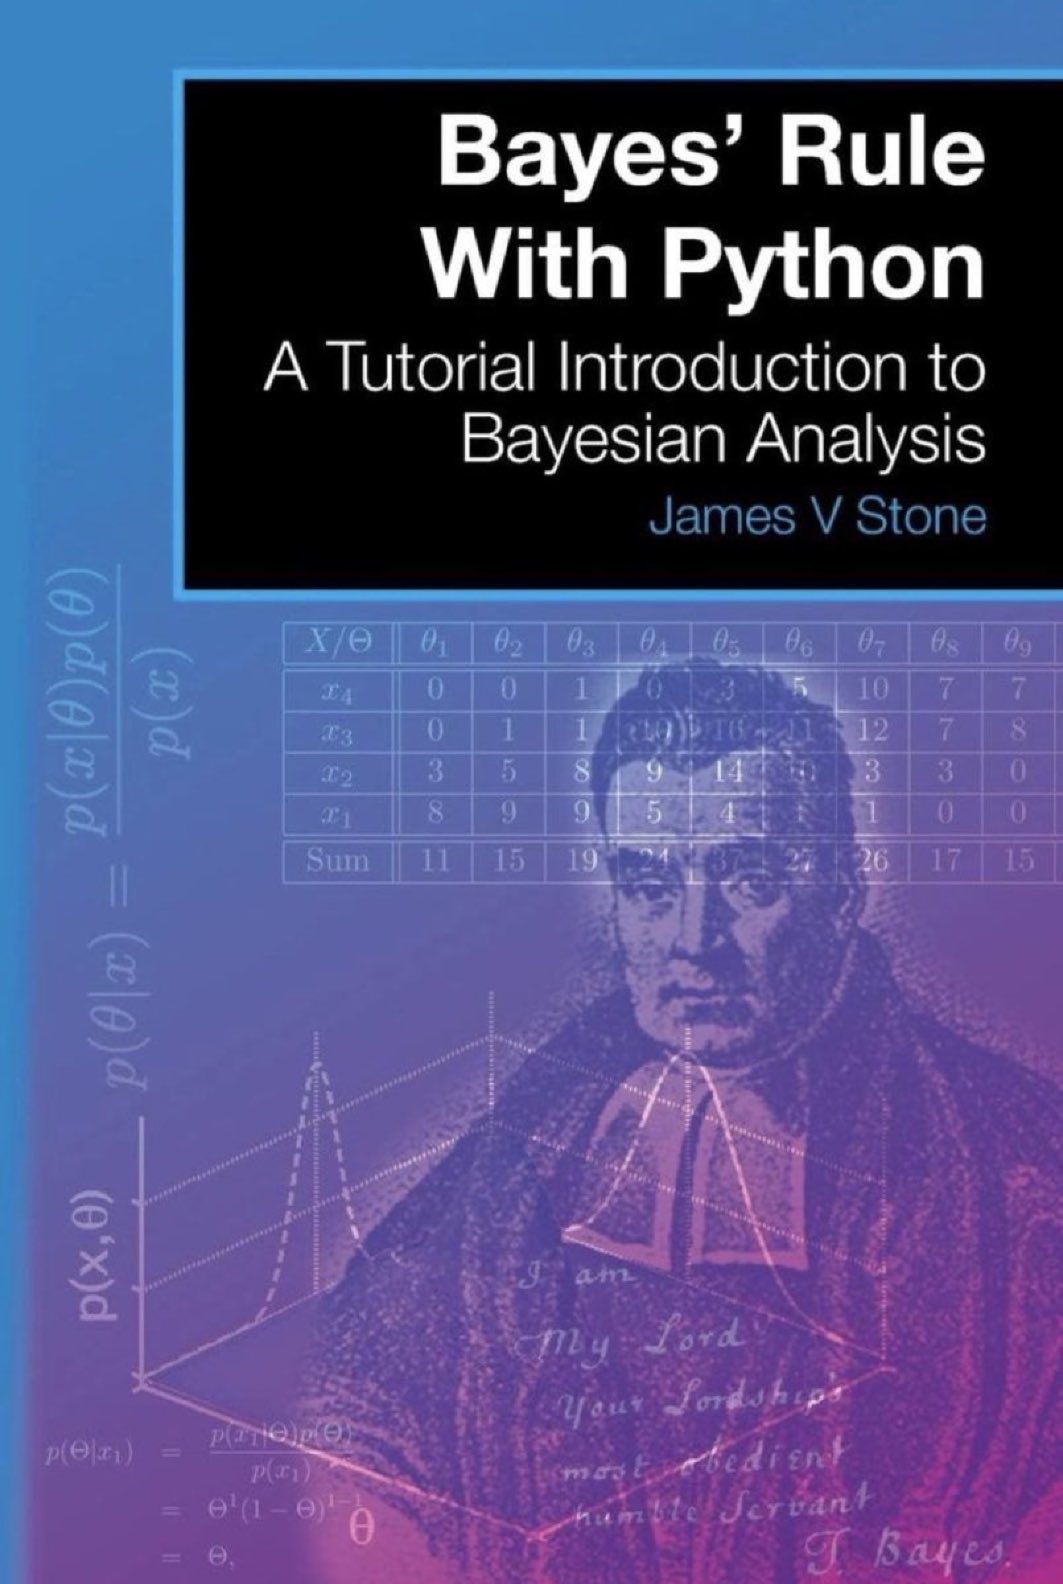
Naive Bayes classification tutorial with Python code
By
–
Naive Bayes Classification, explained with Python code: https://
github.com/taspinar/siml/
blob/master/notebooks/Naive_Bayes.ipynb
…
++
Learn more in this book: http://
amzn.to/312hAHF
————
#DataScience #MachineLearning #AI #ML #Algorithms #Statistics #DataScientist #Mathematics