https://
venturebeat.com/ai/groqs-break
through-ai-chip-achieves-blistering-800-tokens-per-second-on-metas-llama-3/
… Thanks @VentureBeat for bringing the story to light. We really want to advance the landscape for AI Inference and the infrastructure necessary to usher in real-time AI for developers/applications. More to come…
AI HARDWARE
-
Groq’s AI Chip Achieves 800 Tokens Per Second Performance
By
–
-
Open Models and Efficient Hardware Making AI More Accessible
By
–
"The combination of powerful open models like LLaMA and highly efficient “AI-first” inference hardware like Groq’s could make advanced language AI more cost-effective and accessible to a wider range of businesses and developers." – @MichaelFNunez
-
Groq’s API Integration and Performance Revolutionizing LLM Development
By
–
"With its seamless API integration and unparalleled performance, Groq is poised to disrupt the status quo and set a new standard for LLM development." https://
hubs.la/Q02ttMzC0 -
Fast LLaMA 3 Fine-tuning with ORPO on 8xH100 GPUs
By
–
all info available in the model page: https://
huggingface.co/abhishek/autot
rain-llama3-orpo
… 🙂 finetuning took ~30 mins on 8xH100 -
Groq and Llama3: 24 Hours of Development Updates
By
–
24 hours for Groq and #Llama3. Read more about today's developments at https://
groq.link/llama3blog. -
GPT-2 Activation Memory and GPU Cache Analysis
By
–
Makes sense, in GPT-2 (124M) case we're currently doing B=4, T=1024, C=768 => 3M activations @ float32 => 12MB. A100 L2 cache is 40MB, and even L1, at 192KB/SM with 108 SMs => ~= 20MB (wow, that's more than I expected). The pleasures of smaller networks and caches…
-
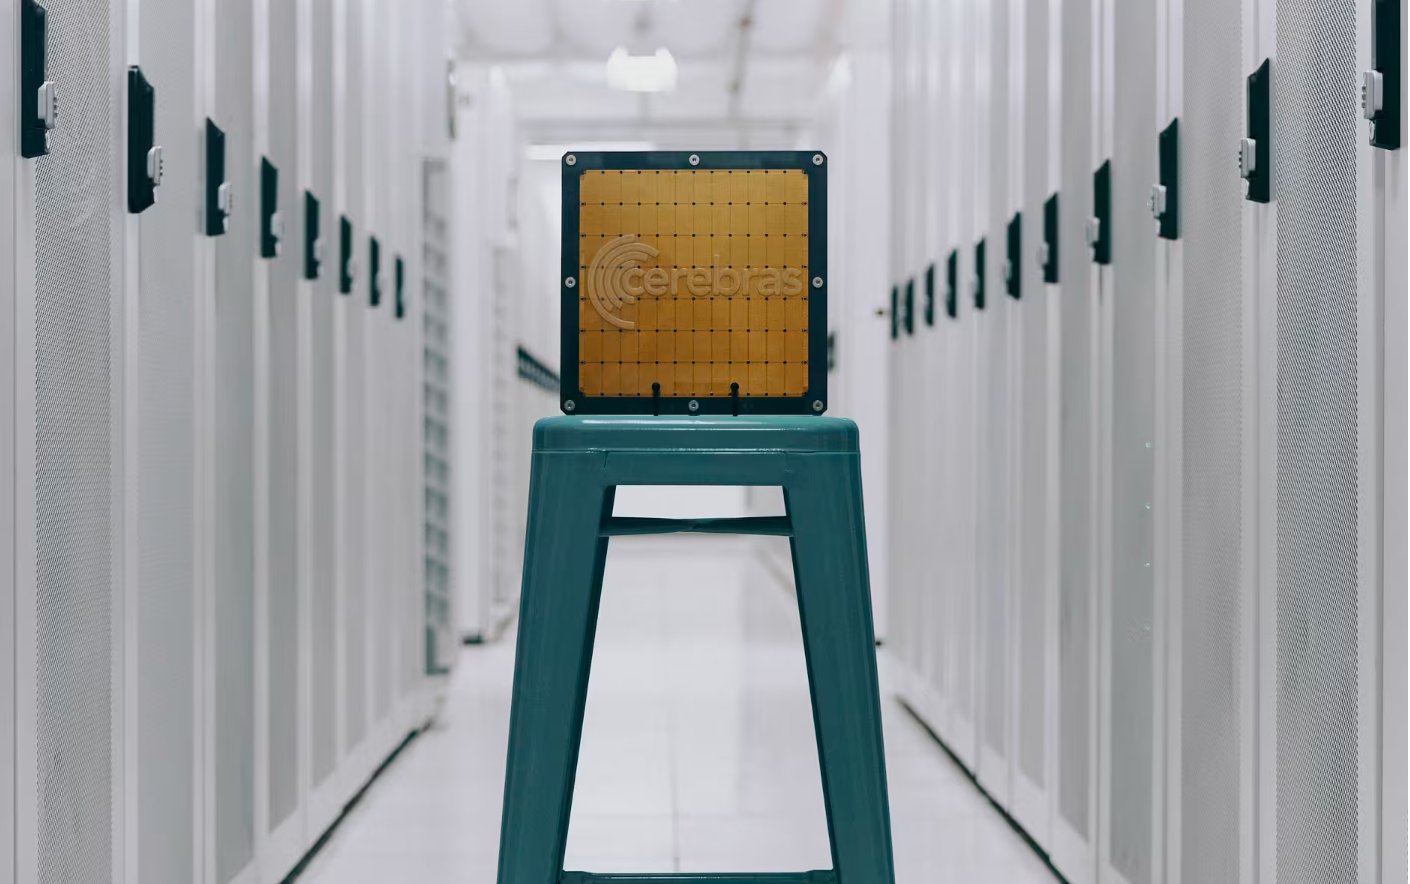
Cerebras WSE-3: Largest Commercial AI Supercomputer Chip
By
–
In Eric Savitz' latest article for Barron's, Cerebras is described as the most intriguing startup that is building AI supercomputers that rival NVIDIA. Highlights from the article: Cerebras Wafer Scale Engine 3 (WSE-3) is 72 square inches and is the largest commercial chip
-
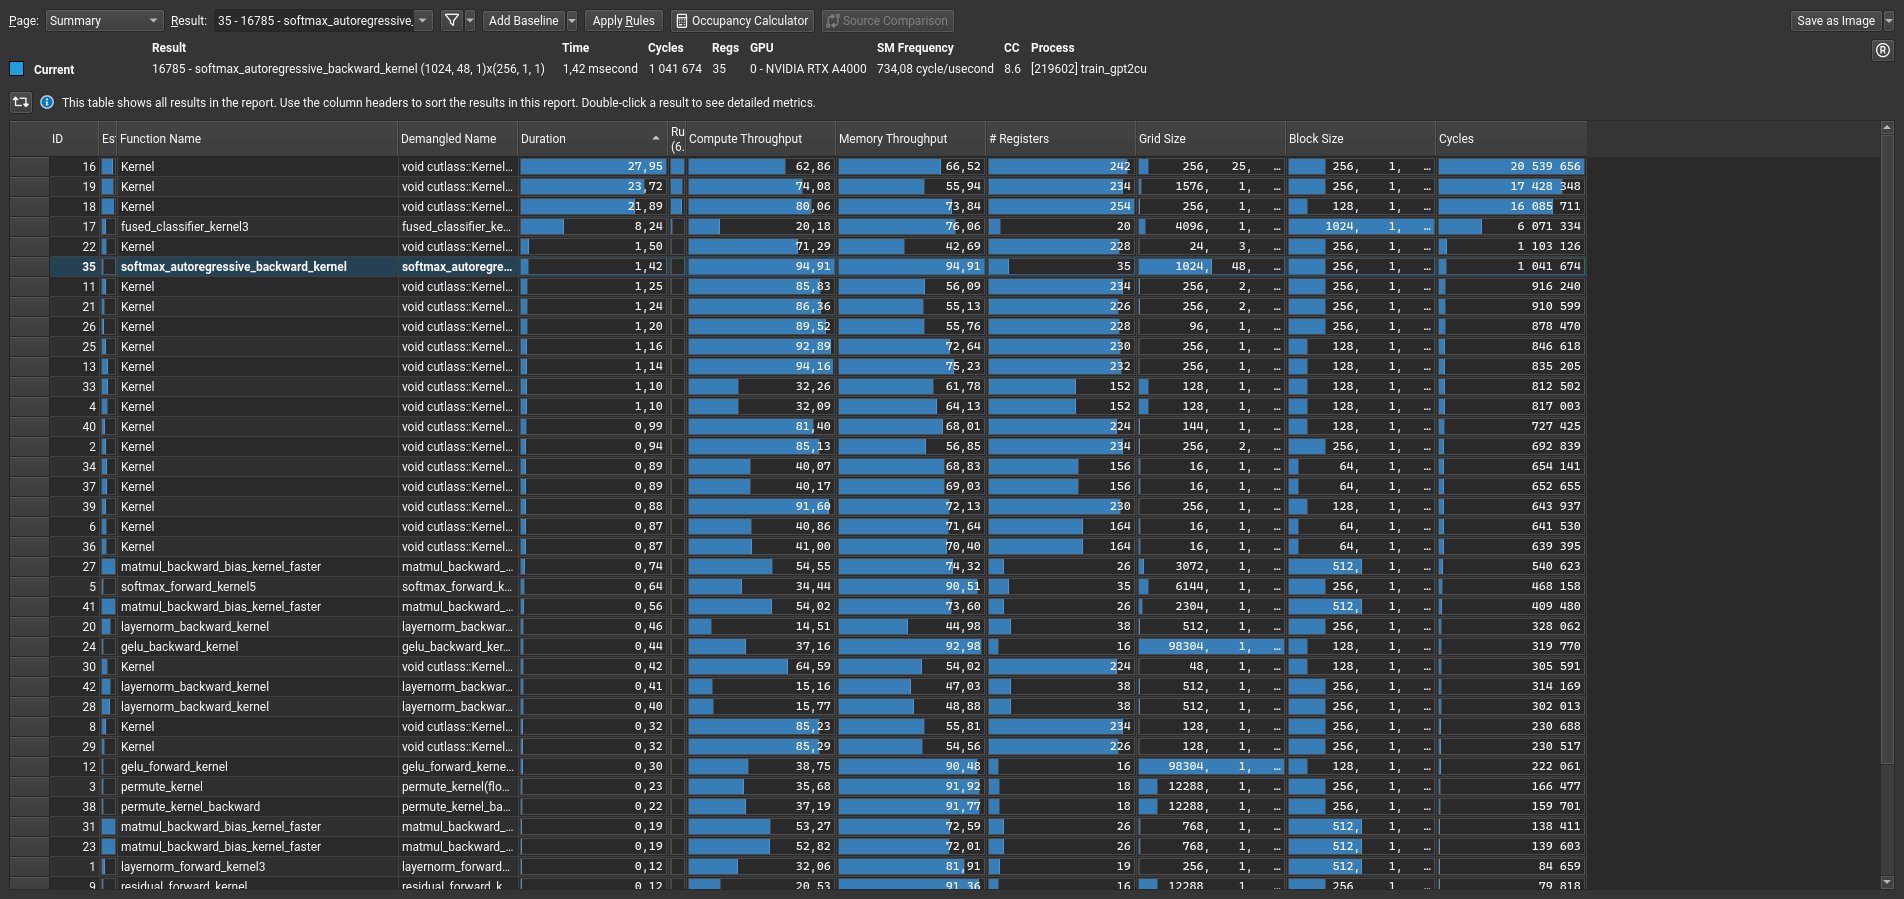
llm.c Matches PyTorch Performance Training GPT-2 on GPU
By
–
llm.c update: Our single file of 2,000 ~clean lines of C/CUDA code now trains GPT-2 (124M) on GPU at speeds ~matching PyTorch (fp32, no flash attention) https://
github.com/karpathy/llm.c
/blob/master/train_gpt2.cu
… On my A100 I'm seeing 78ms/iter for llm.c and 80ms/iter for PyTorch. Keeping in mind this is fp32, -
Correction: H100 GPU provides approximately 4X compute power
By
–
I'm sorry, you're right, H100 not A100 => ~4X compute numbers.
-
Open Models Drive Rapid AI Capability Improvements and Speed
By
–
Because anyone can work with them, open models are likely to improve very quickly, creating a lot of capabilities focused on factors ranging from speed to costs.
— Ethan Mollick (@emollick) 19 avril 2024
Here is the new Llama 3 70B being served by Groq (with a q) at 224 tokens/second. This is real-time of me using it. pic.twitter.com/L6i6T6OBbWBecause anyone can work with them, open models are likely to improve very quickly, creating a lot of capabilities focused on factors ranging from speed to costs. Here is the new Llama 3 70B being served by Groq (with a q) at 224 tokens/second. This is real-time of me using it.