"There are still many more use cases to be discovered, which will only further grow the AI market and, by extension, Groq’s addressable market… we are confident Groq is well-positioned to continue delivering game-changing AI performance." @TDKVentures https://
hubs.la/Q02twphN0
AI HARDWARE
-
Groq positioned for AI market growth with game-changing performance
By
–
-
Groq Compiler Supports Hundreds of Models Beyond LLMs
By
–
No, we actually have hundreds of models built into the compiler and we've done demos with computer vision, audio, speech to text, stylegan and more. We also have national labs customers running GNNs, RNNs, and custom proprietary models. There's lots more coming, stay tuned.
-
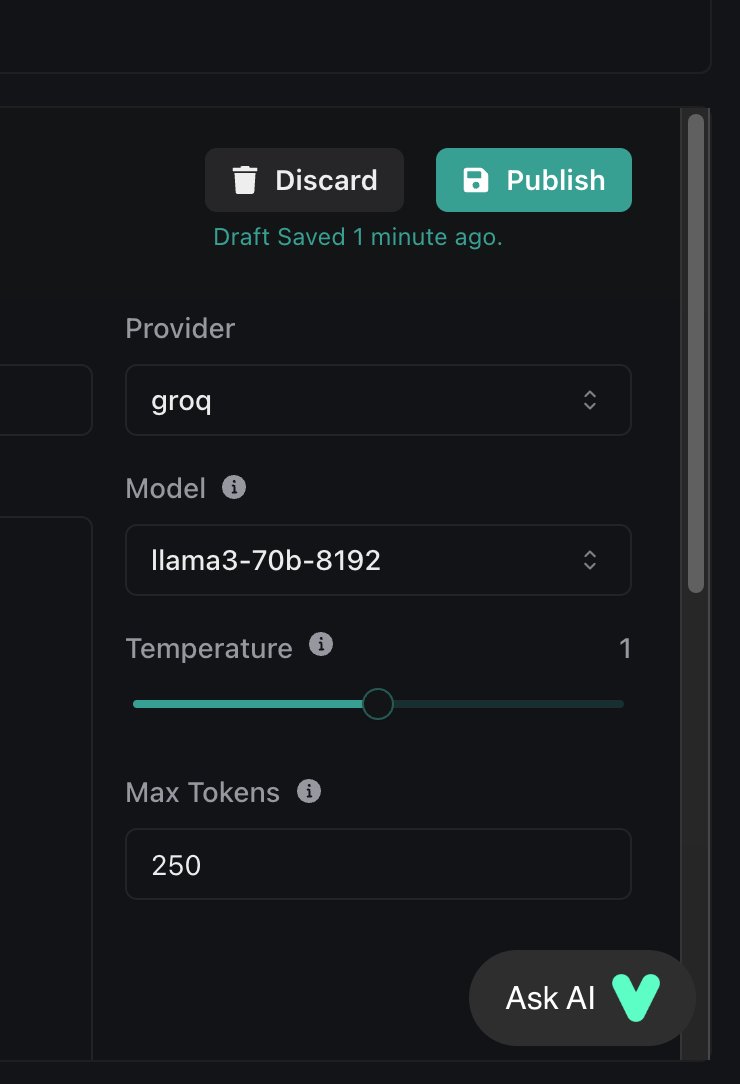
Vapi AI Integrates Llama3 Models on Groq LPUs
By
–
Another update…and now @Vapi_AI has added Llama3 8B and 70B to their AI voice agent service. We love seeing all the momentum from developers trying out this set of models from @aiatmeta running inference on our LPUs. Keep it coming!
-

Groq aims for speed of light with future LPU infrastructure
By
–
Speed of light is a good goal, maybe with a future LPU in our Infrastructure for AI Inference. In the meantime we'll keep doing everything we can to bring real-time AI solutions to developers. Thanks for sharing the screengrab!
-
Optimus Versus Unitree: The Humanoid Robot Showdown
By
–
Let’s do it. @elonmusk
: Optimus Vs Unitree. -

Humanoid Robots Face Height Standardization Design Challenges
By
–
poor humanoid robots inheriting the 5’11” problem
-

ScaleFold Reduces AlphaFold Training Time to 10 Hours
By
–
ScaleFold: Reducing AlphaFold Initial Training Time to 10 Hours Zhu et al.: https://
arxiv.org/abs/2404.11068 #ArtificialIntelligence #DeepLearning #MachineLearning -
MacBook Pro M2 RAM and Storage Constraints Discussion
By
–
I'm on a 64GB MacBook Pro M2 with 2TB of disk and I'm already feeling constrained for both RAM and disk space, but wow these laptops are expensive these days! I have a Samsung external 4TB USB drive which helps
-
Llama 3: Dense Model Efficiency vs Sparse MoE Scaling Strategy
By
–
Thing that most impresses me about Llama 3: how did they pack so much knowledge and reasoning into a dense 8b and a 70b so well, when everyone else has been scaling sparse MoEs. This still doesn’t mean having a lot of GPUs is not important. Probably even more important