
BREAKING: A Google researcher and a Turing Award winner just published a paper arguing that the real AI crisis isn’t training. It’s inference. And the hardware stack we rely on today was never built for it. The paper, by Xiaoyu Ma and David Patterson, was accepted by IEEE
AI HARDWARE
-
SN50 RDU Chip Promises 5X Faster Agentic AI Inference
By
–
SN50 RDU — purpose-built for agentic inference. Max speed of up to 5X faster; run agentic AI at a 3X lower cost than GPUs, unlocking cloud-scale inference economics. Learn more in our blog
-

2026 Keynote Pregame: Accelerated Computing, Open Models, Agentic AI
By
–
Your 2026 keynote pregame hosts are here. Join @saranormous (Conviction), @GavinSBaker (Atreides), @Alfred_Lin (Sequoia Capital), and Tiffany Janzen (TiffinTech) as they set the stage for fast-paced conversations on accelerated computing, open models, agentic AI, and the
-

AI Inference for Real-World Constraints and Safety-Critical Applications
By
–
Axelera AI x Meridian Data Labs Defense installations. Remote industrial sites. Aircraft and engine MROs. Safety-critical metrology inspections. X-ray baggage inspections. These are environments where AI inference must operate under real-world constraints, not in datacenter
-

CUDA Agent: Large-Scale Agentic RL for Kernel Generation
By
–
CUDA Agent | Large-Scale Agentic RL for CUDA Kernel Generation https://
buff.ly/13zVaiQ
#AI #MachineLearning #DeepLearning #LLMs #DataScience -
Token Generation Speed Comparison: OSS and Nemotron Models Performance
By
–
Yeah. Not quite as bad for me, but:
gpt-oss-120b: 42.22 tokens/sec
nemotron-3-super: 20.43 tokens/sec on the DGX Spark. But this is ollama and might be an implementation issue. I have yet to try the Nvidia-optimized llama.cpp version (they had one for Nemotron Nano back then) -
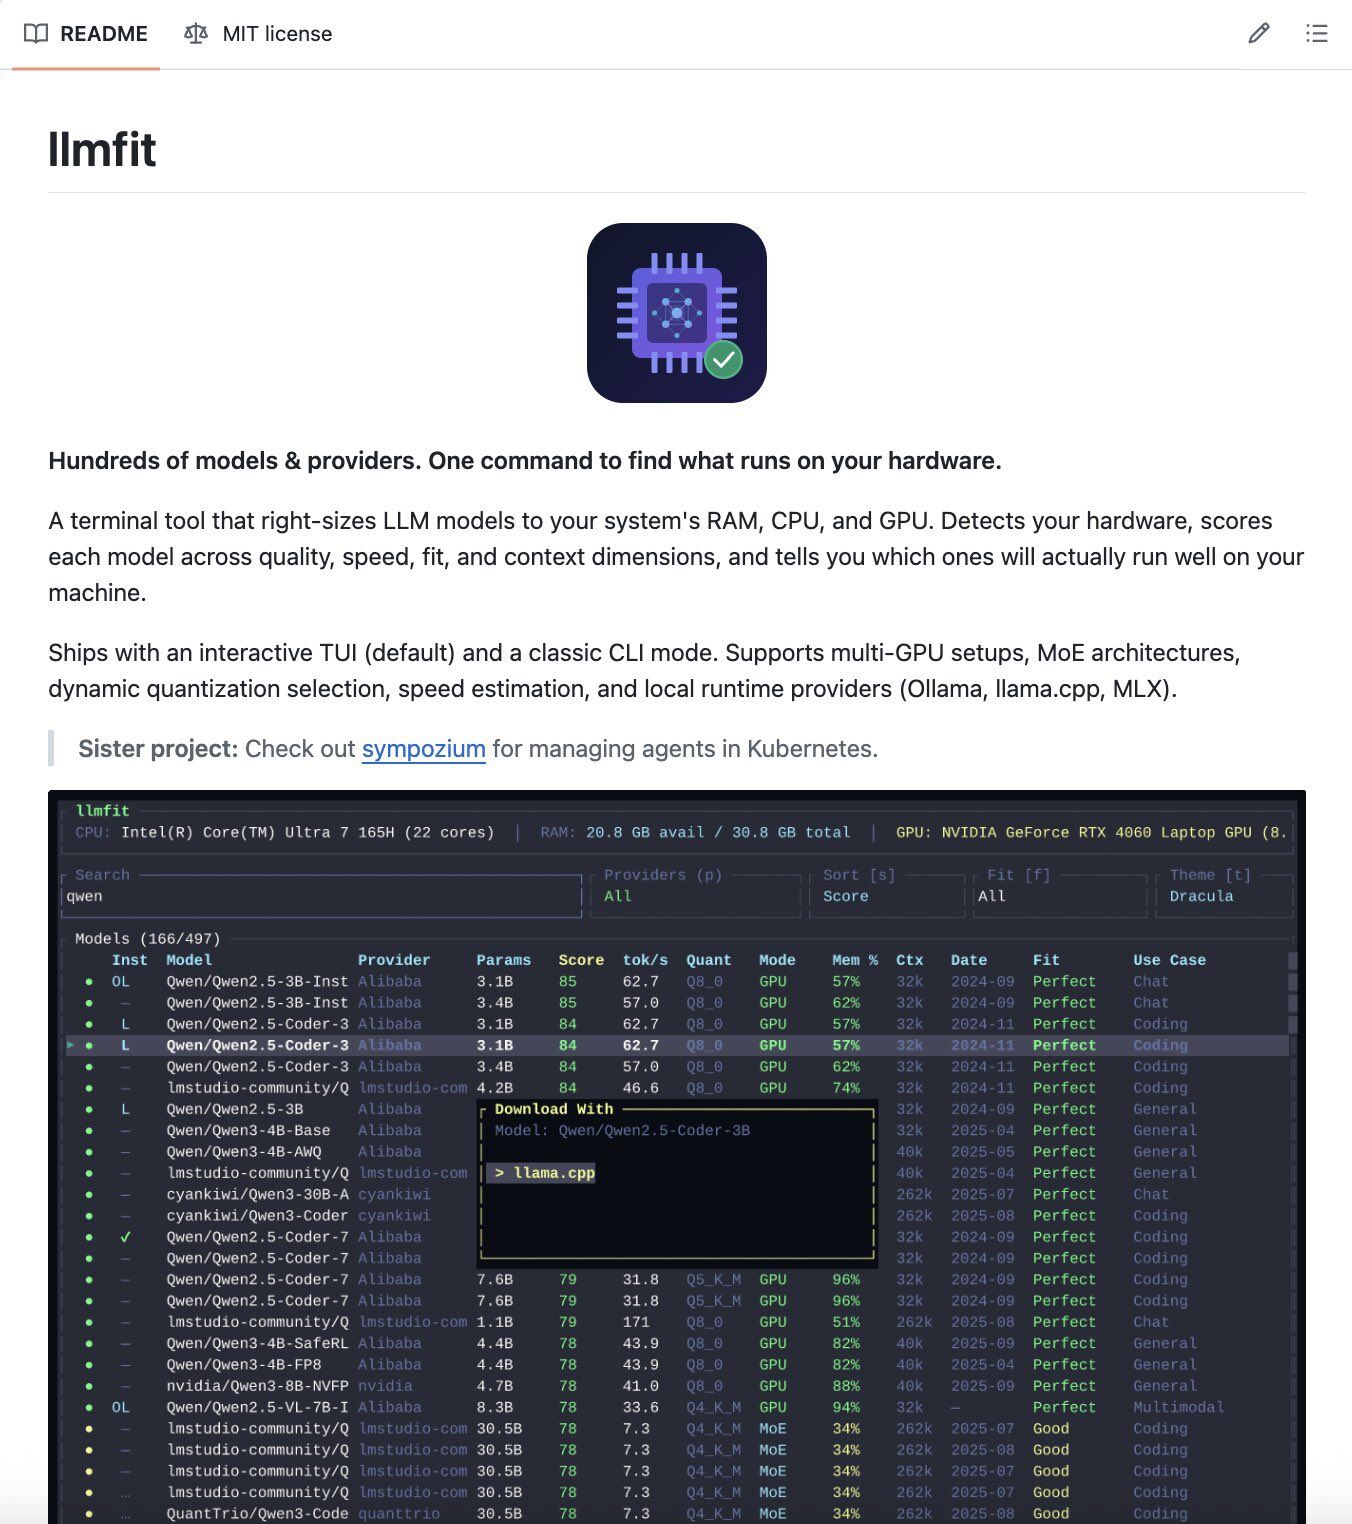
llmfit: Auto-detect hardware and rank 206 models by VRAM compatibility
By
–
Stop guessing which models fit in your VRAM! llmfit is a CLI tool that auto-detects your hardware and ranks 206 models by what actually runs on your system. You download a 70B model and hope it fits. Or you estimate memory requirements across quantization levels and still end
-
India launches AI sovereignty with 38,000 GPUs infrastructure
By
–
This is what sovereignty looks like. Not just a word in a speech. 38,000 GPUs. 12 foundational model teams. 10000+ datasets. India's AI era has started. And YOU are in it. #MadeWithIndiaAI (8/8) @AshwiniVaishnaw @jitinprasada @PIB_India @SecretaryMEITY @abhish18 @kavitabha
-
India launches 60% discounted GPU access for startups researchers
By
–
The rate? ₹65/hour for a GPU. Compare that to the global rate of ₹150-180/hour for an H100. That's a 60% discount. For any startup, PhD student, MSME, or researcher in India. (4/8) @AshwiniVaishnaw @jitinprasada @PIB_India @SecretaryMEITY @abhish18 @kavitabha @GoI_MeitY
-
India Launches National Compute Pool with Seven Cloud Providers
By
–
In 18 months, seven empanelled cloud providers. @NVIDIA H100s, @AMD MI300s, @Google Trillium TPUs. Distributed across tier-3 data centres. All under one national compute pool. (3/8) @AshwiniVaishnaw @jitinprasada @PIB_India @SecretaryMEITY @abhish18 @kavitabha @GoI_MeitY