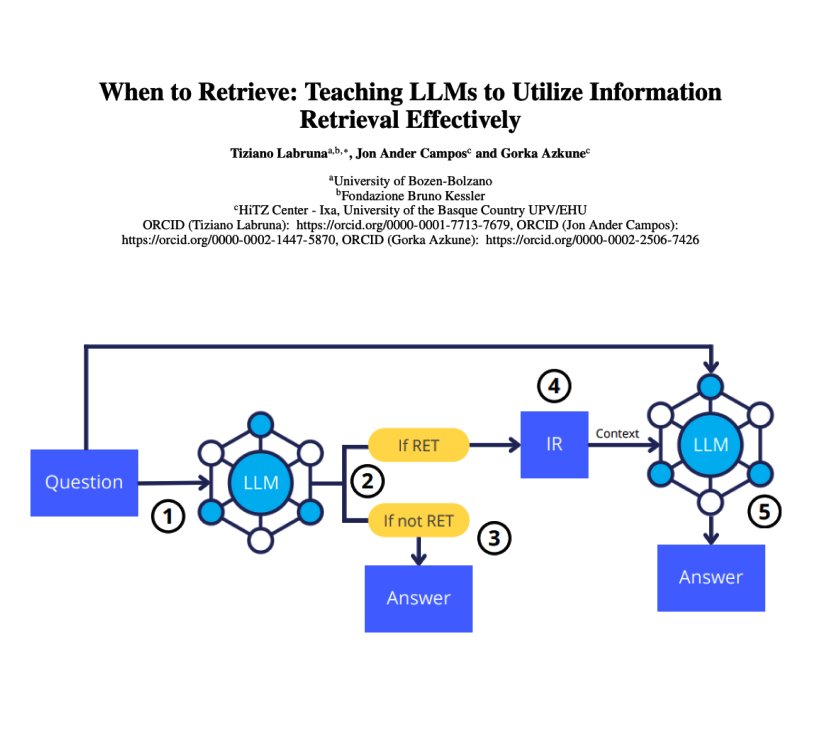
4). When to Retrieve? – presents an approach to train LLMs to effectively utilize information retrieval; it first proposes a training approach to teach an LLM to generate a special token, , when it's not confident about the answer to a question.
@dair_ai
-
Multi-token Prediction Approach Improves LLM Speed
By
–
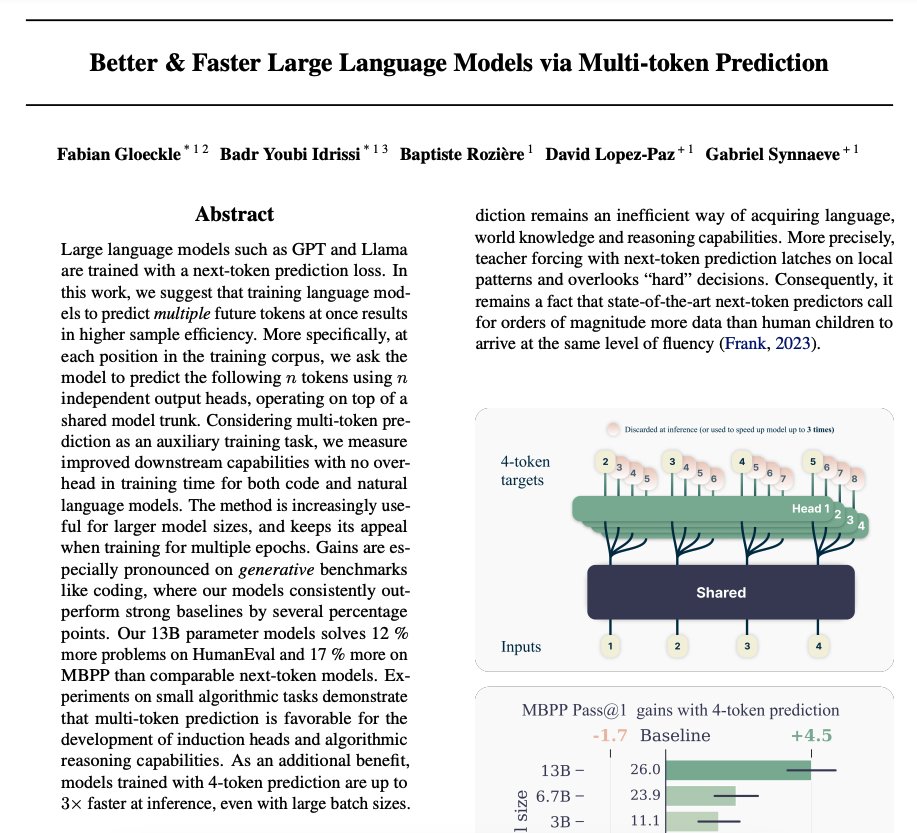
2). Better and Faster LLMs via Multi-token Prediction – proposes a multi-token prediction approach that performs language modeling by training the predict the following n tokens using n independent output heads…
-

State Space Models Survey: Analysis and Applications
By
–
10/ A Survey on State Space Models – a survey paper on state space models (SSMs) with experimental comparison and analysis; it reviews current SSMs, improvements compared to alternatives, challenges, and their applications.
-

LLM In-Context Recall Depends on Prompt Formulation
By
–
9/ LLM In-Context Recall is Prompt Dependent – finds that a model's recall performance is significantly affected by small changes in the prompt; the interplay between prompt content and training data can degrade the response quality.
-
Emerging AI Agent Architectures: Reasoning, Planning, and Tool Calling
By
–
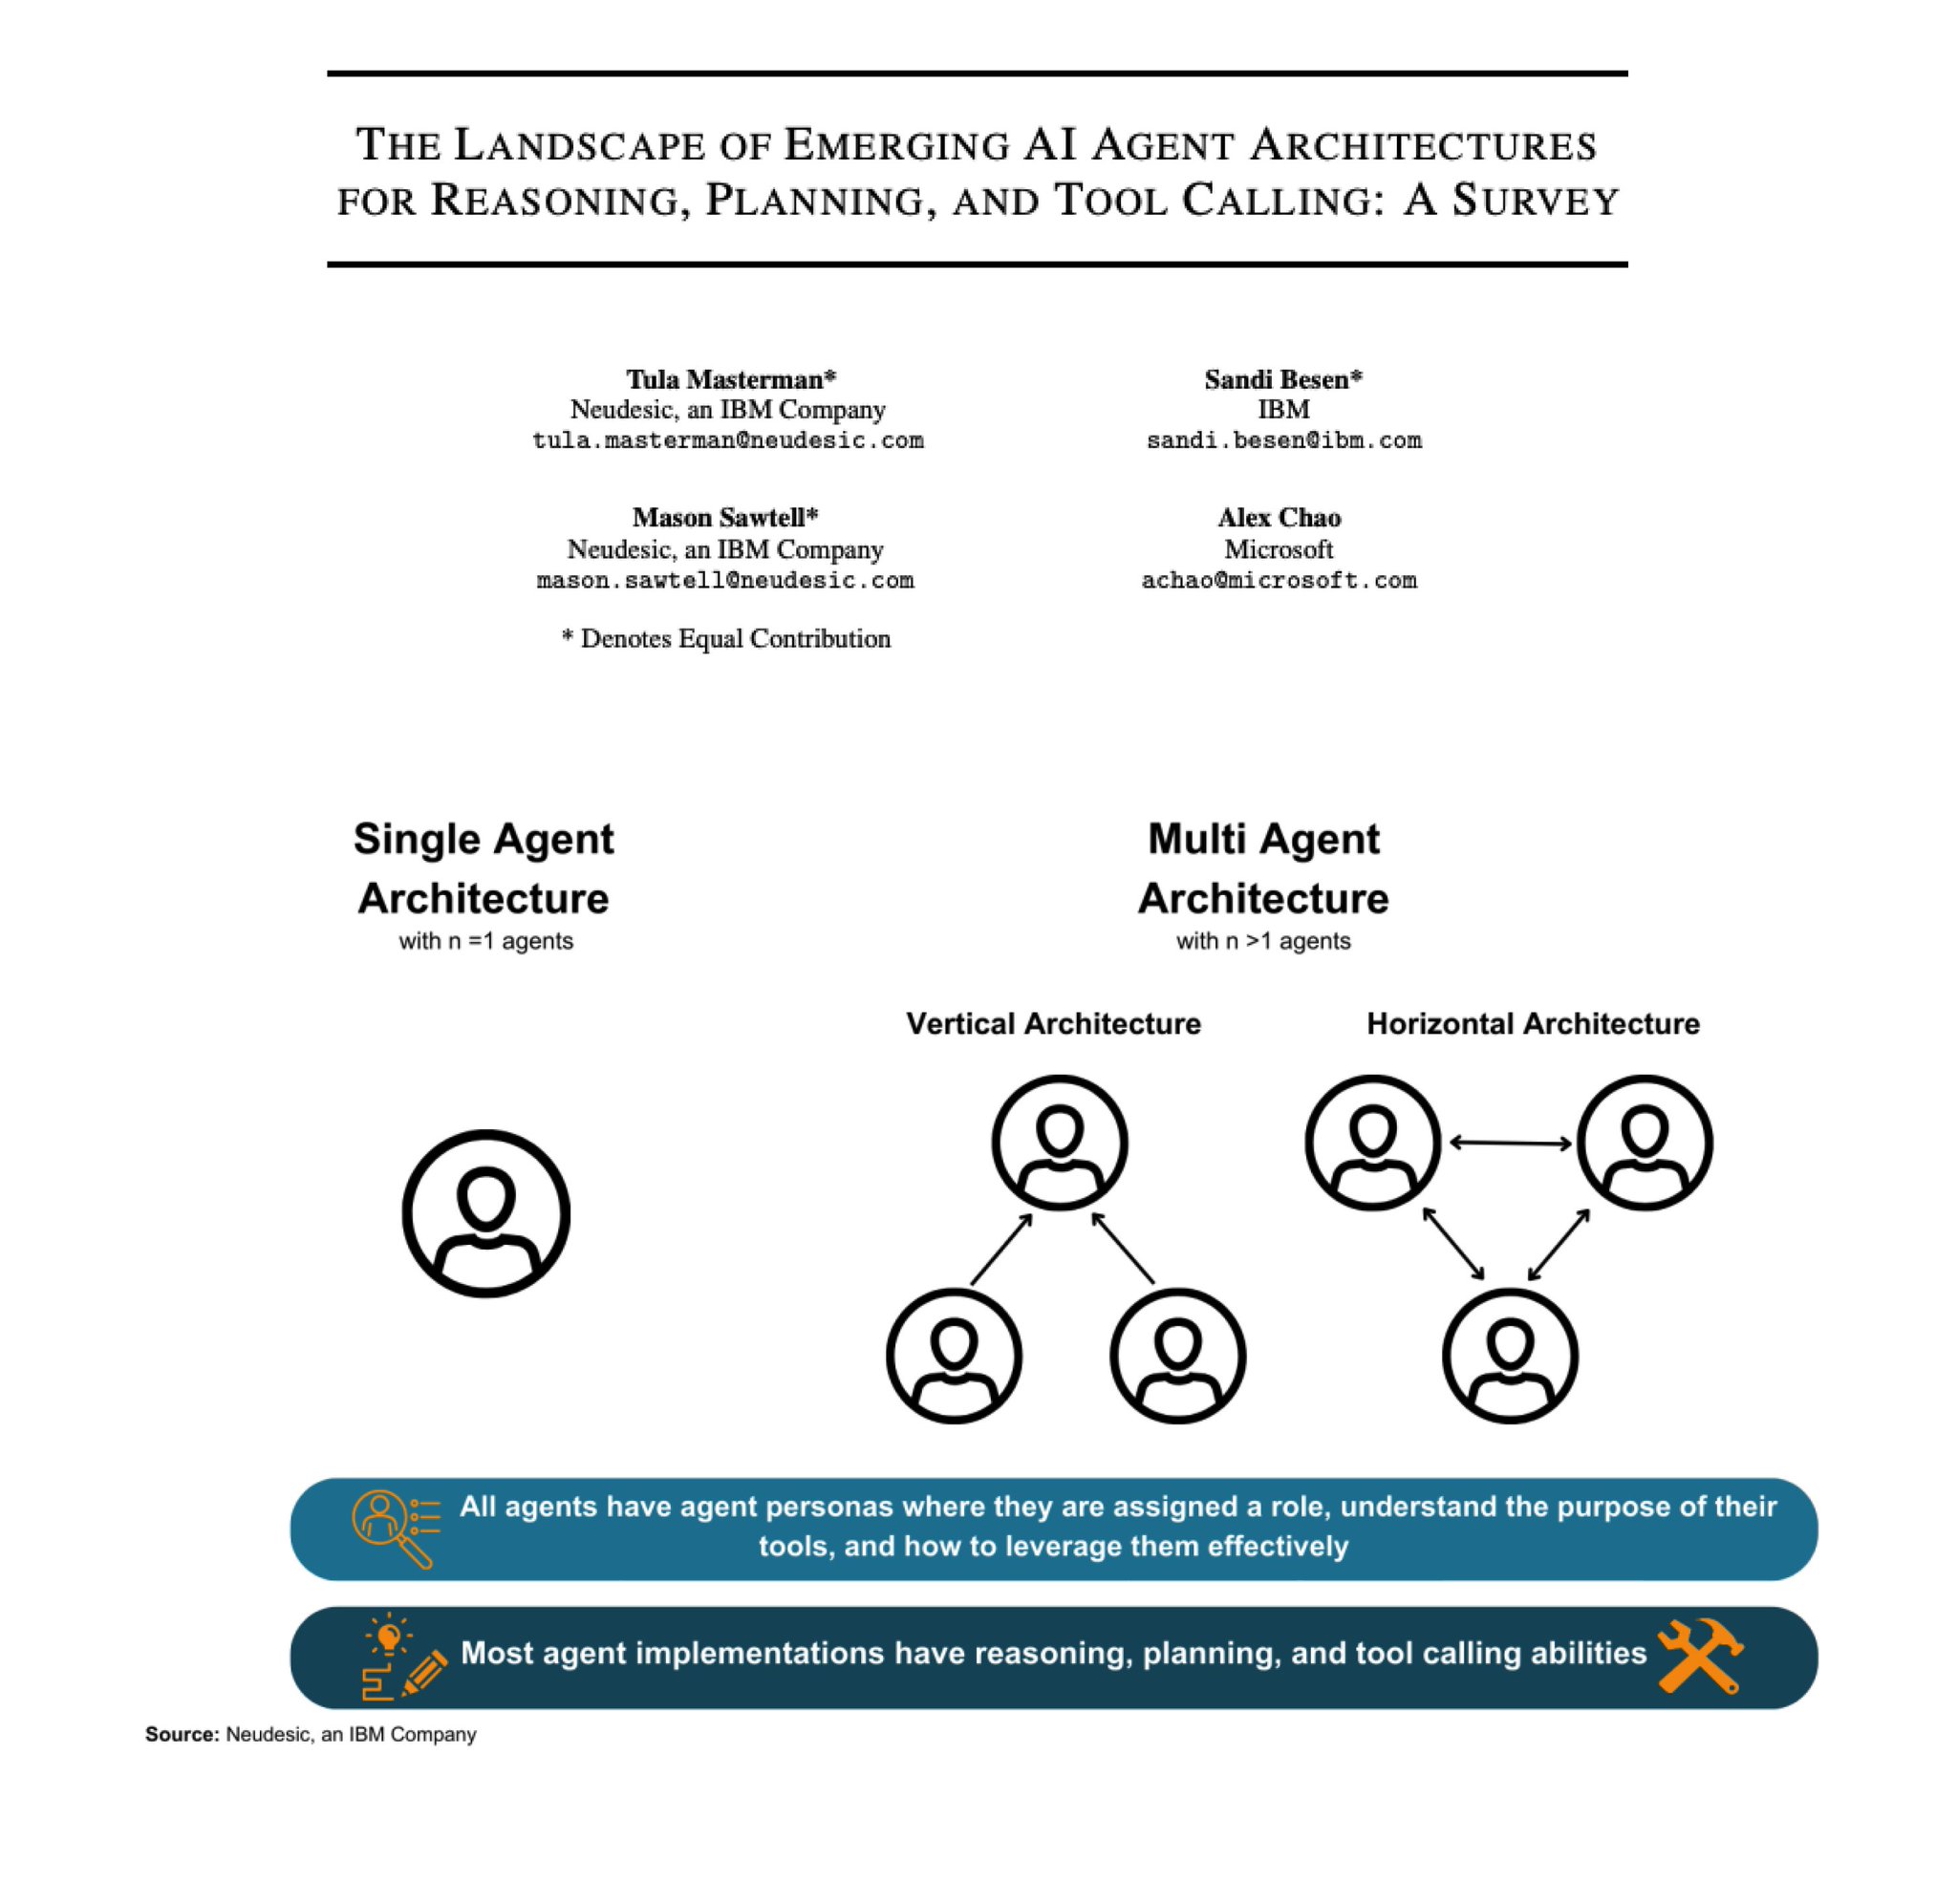
8/ Emerging AI Agent Architectures – a summary of emerging AI agent architectures; it focuses the discussion on capabilities like reasoning, planning, and tool calling which are all needed to build complex AI-powered agentic workflows and systems.
-
RAG Reduces Hallucination in LLM Structured Outputs
By
–
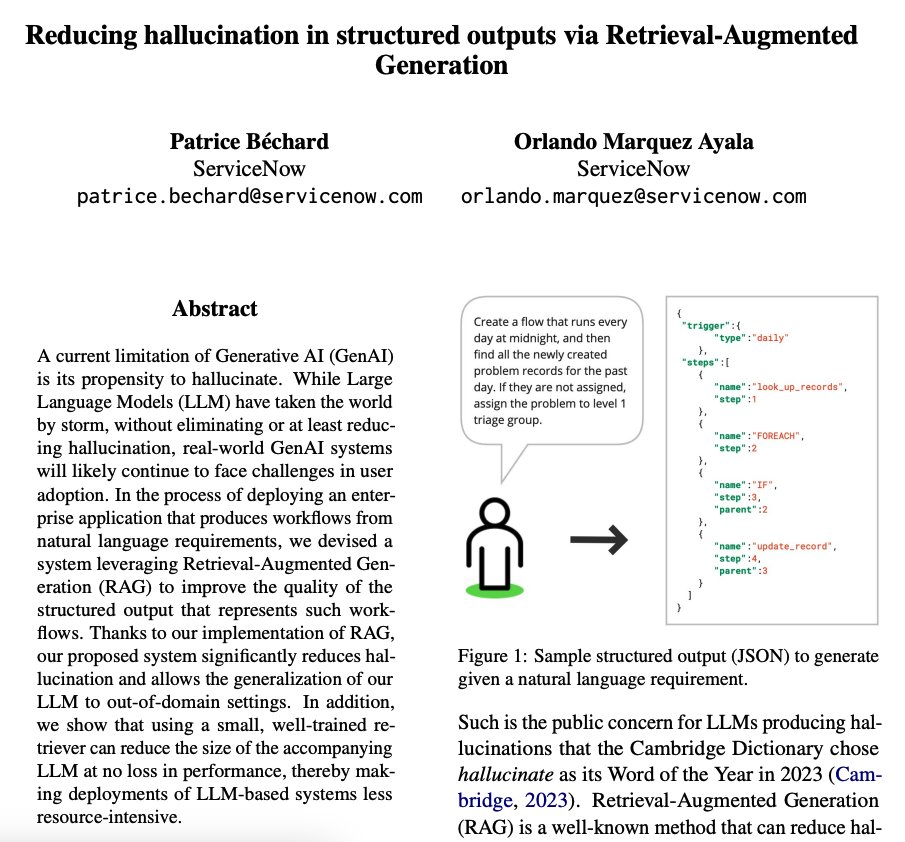
7/ Reducing Hallucination in Structured Outputs via RAG – shows that RAG can enable deploying powerful LLM-powered systems in limited-resource settings while mitigating issues like hallucination and increasing the reliability of outputs.
-

State-Space Models Express Power Limited to TC0 Complexity
By
–
6/ The Illusion of State in State-Space Models – investigates the expressive power of state space models (SSMs) and reveals that it is limited similar to transformers in that SSMs cannot express computation outside the complexity class 𝖳𝖢^0…
-
Chinchilla Scaling: Replication Attempt Challenges Hoffmann et al.
By
–
3/ Chinchilla Scaling: A replication attempt – attempts to replicate the third estimation procedure of the compute-optimal scaling law proposed in Hoffmann et al. (2022) (i.e., Chinchilla scaling); finds that “the reported estimates are inconsistent with their first two
-
Top ML Papers Week: Llama 3, Mixtral, RAG Advances
By
–
The Top ML Papers of the Week (April 15 – April 21): – Llama 3
– Mixtral 8x22B
– A Survey on RAG
– How Faithful are RAG Models?
– Emerging AI Agent Architectures
– Chinchilla Scaling: A replication attempt
… -
Llama 3 Family: 8B and 70B Models Released with Strong Performance
By
–
1/ Llama 3 – a family of LLMs that include 8B and 70B pretrained and instruction-tuned models; Llama 3 8B outperforms Gemma 7B and Mistral 7B Instruct; Llama 3 70 broadly outperforms Gemini Pro 1.5 and Claude 3 Sonnet.https://t.co/xqDJy0f0Vs
— DAIR.AI (@dair_ai) 21 avril 20241/ Llama 3 – a family of LLMs that include 8B and 70B pretrained and instruction-tuned models; Llama 3 8B outperforms Gemma 7B and Mistral 7B Instruct; Llama 3 70 broadly outperforms Gemini Pro 1.5 and Claude 3 Sonnet.