3). DeepSeek-V2 – a strong MoE 236B parameter model, of which 21B are activated for each token; supports a context length of 128K tokens and uses Multi-head Latent Attention (MLA) for efficient inference by compressing the Key-Value (KV) cache into a latent vector…
@dair_ai
-
AlphaFold 3 Predicts Protein DNA RNA Molecular Structures
By
–
1). AlphaFold 3 – releases a new state-of-the-art model for accurately predicting the structure and interactions of molecules; it can generate the 3D structures of proteins, DNA, RNA, and smaller molecules…https://t.co/avOFMTnTwz
— DAIR.AI (@dair_ai) 12 mai 20241). AlphaFold 3 – releases a new state-of-the-art model for accurately predicting the structure and interactions of molecules; it can generate the 3D structures of proteins, DNA, RNA, and smaller molecules…
-
Top ML Papers Week May 6-12 xLSTM AlphaFold DeepSeek
By
–
The Top ML Papers of the Week (May 6 – May 12): – xLSTM
– DrEureka
– AlphaFold 3
– DeepSeek-V2
– Consistency LLMs
– AlphaMath Almost Zero
… -

In-Context Learning Performance with Extreme Long-Context Models
By
–
10). In-Context Learning with Long-Context Models – studies the behavior in-context learning of LLMs at extreme context lengths with long-context models; shows that performance increases as hundreds or thousands of demonstrations are used.
-
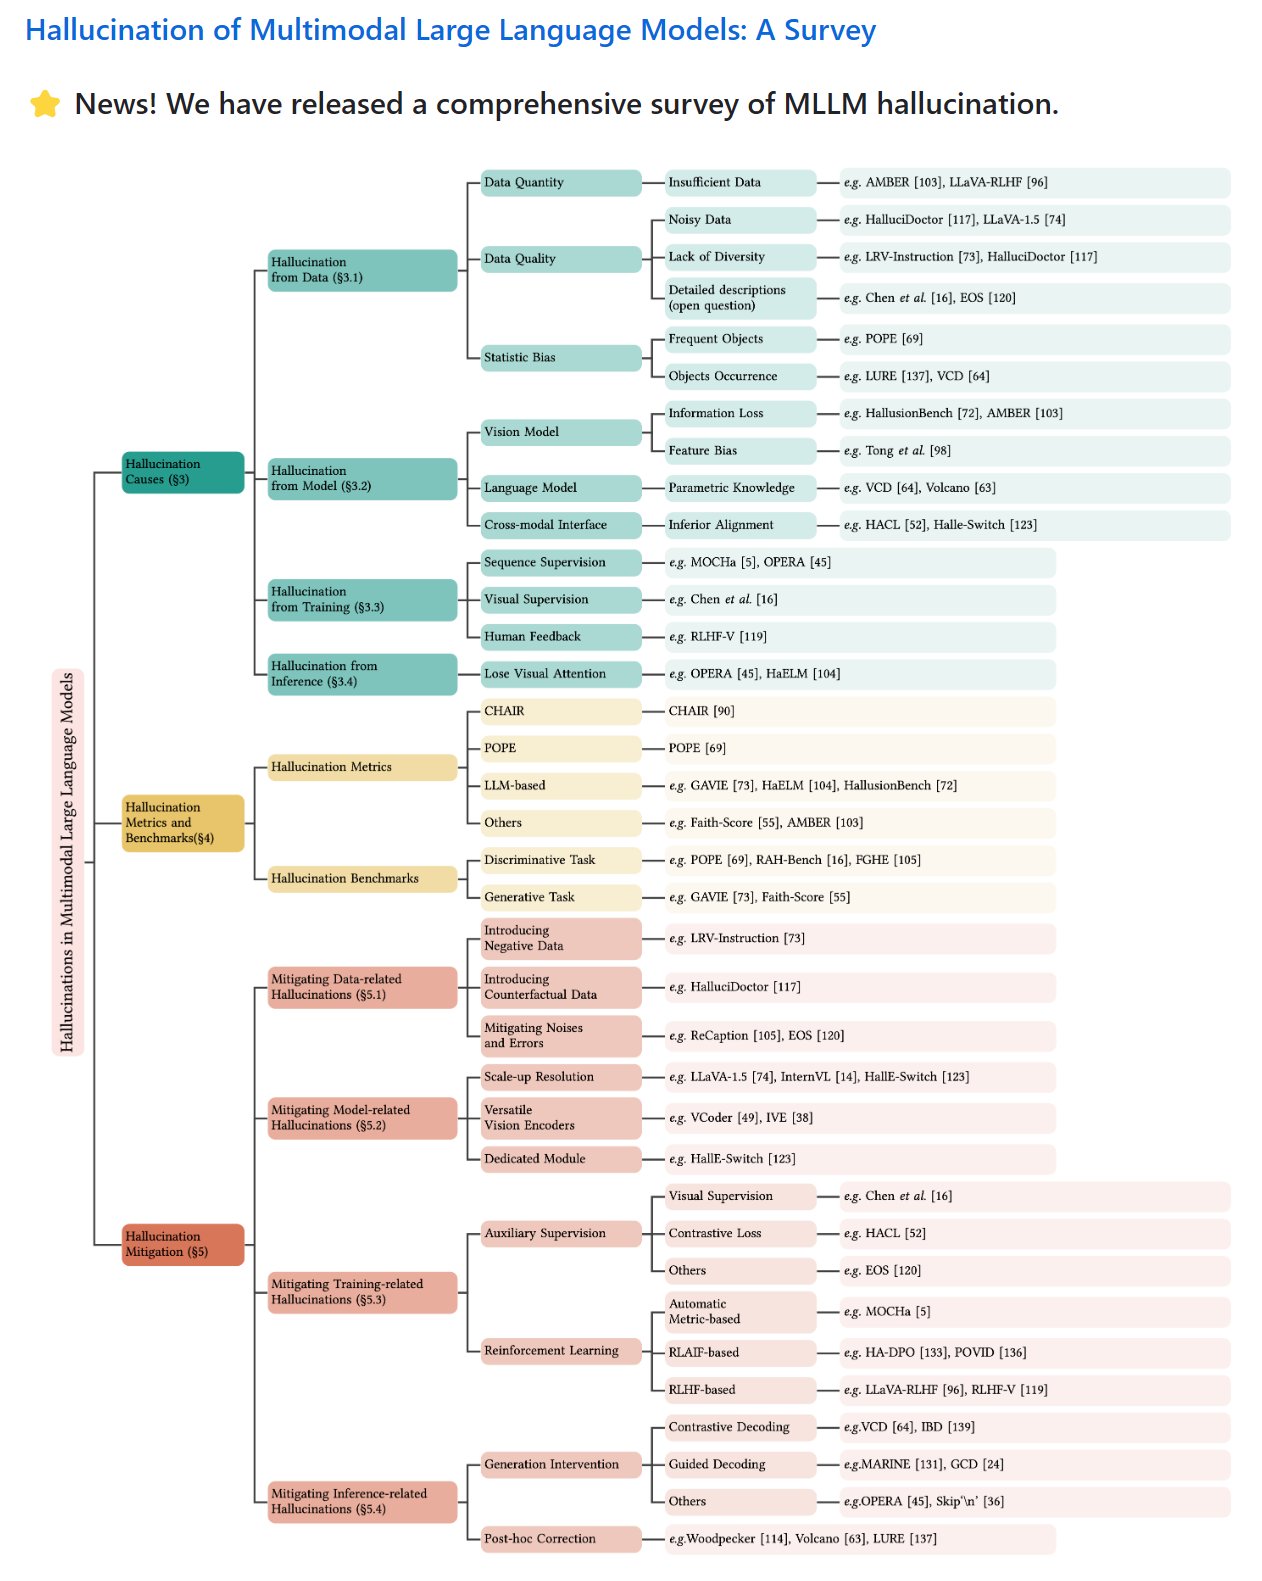
Multimodal LLM Hallucinations: Advances in Detection and Mitigation
By
–
9). Multimodal LLM Hallucinations – provides an overview of the recent advances in identifying, evaluating, and mitigating hallucination in multimodal LLMs.
-

Interpreting Transformer Language Models: Technical Deep Dive
By
–
8). Inner Workings of Transformer Language Models – presents a technical introduction to current techniques used to interpret the inner workings of Transformer-based language models.
-
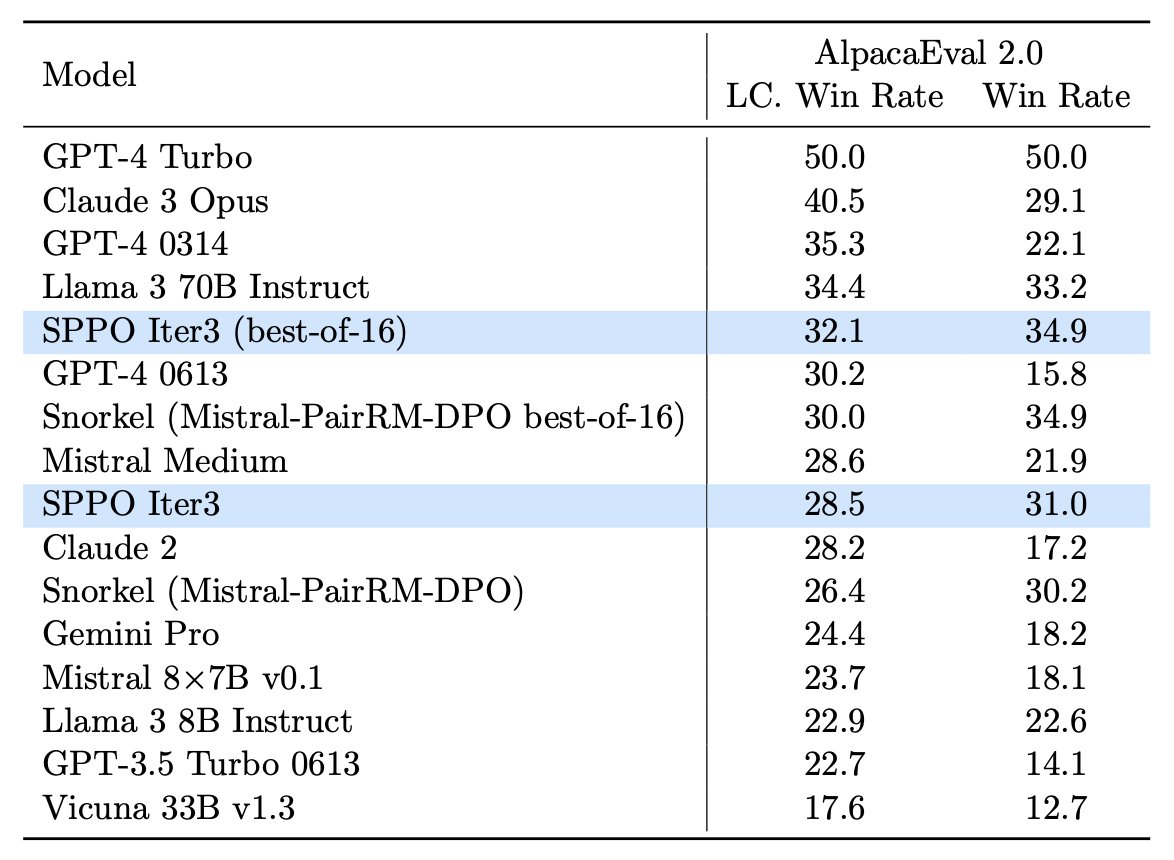
Self-Play Preference Optimization for Language Model Alignment
By
–
7). Self-Play Preference Optimization – proposes a self-play-based method for aligning language models; this optimization procedure treats the problem as a constant-sum two-player game to identify the Nash equilibrium policy.
-
Prometheus 2: Open-Source LM for Evaluating Language Models
By
–
6). An Open-source LM Specialized in Evaluating Other LMs – open-source Prometheus 2 (7B & 8x7B), state-of-the-art open evaluator LLMs that closely mirror human and GPT-4 judgments; they support both direct assessments and pair-wise ranking formats grouped with user-defined
-

Survey on Retrieval-Augmented Language Models: Evolution and Applications
By
–
5). A Survey on Retrieval-Augmented Language Models – covers the most important recent developments in RAG and RAU systems; it includes evolution, taxonomy, and an analysis of applications.
-
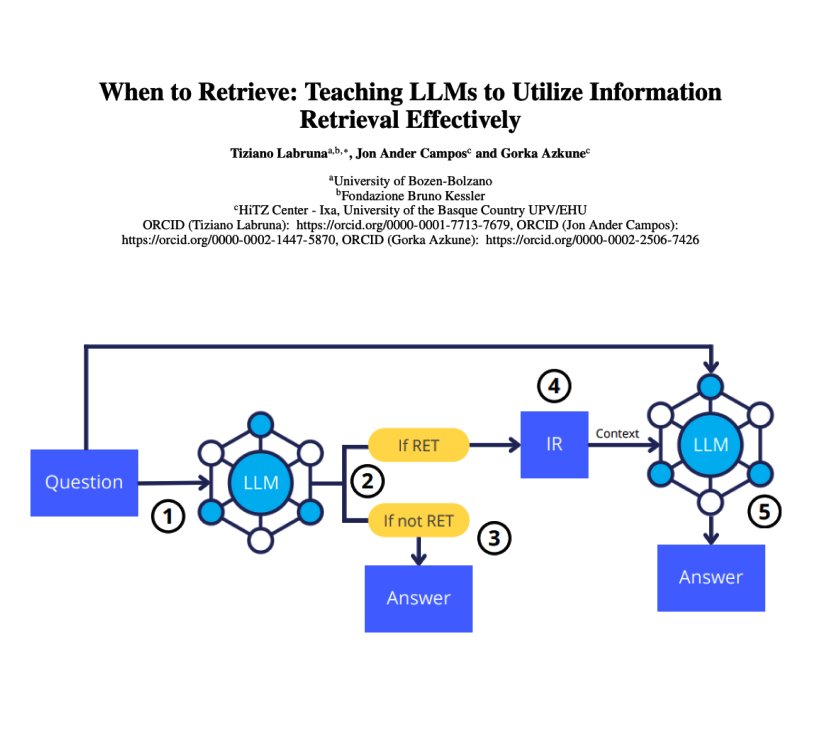
Training LLMs to Retrieve Information When Uncertain
By
–
4). When to Retrieve? – presents an approach to train LLMs to effectively utilize information retrieval; it first proposes a training approach to teach an LLM to generate a special token, , when it's not confident about the answer to a question.