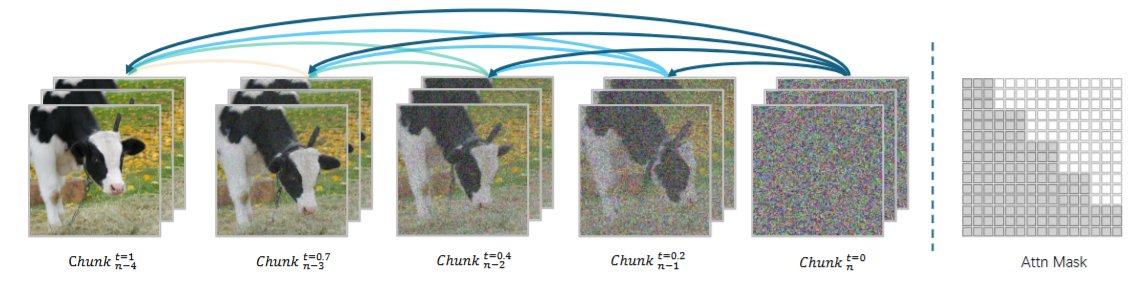
MAGI-1: Autoregressive Generation at Scale MAGI-1 is a large-scale autoregressive video generation model that produces videos by generating fixed-length chunks of consecutive frames with diffusion, enabling efficient, streaming-capable, and temporally consistent video
@askalphaxiv
-

MMaDA: Multimodal Diffusion Language Models for Reasoning
By
–
MMaDA: Multimodal Large Diffusion Language Models MMaDA introduces a new class of multimodal diffusion models that unify reasoning and generation across text and vision, achieving state-of-the-art performance in both understanding and generation tasks. Problem: Existing
-
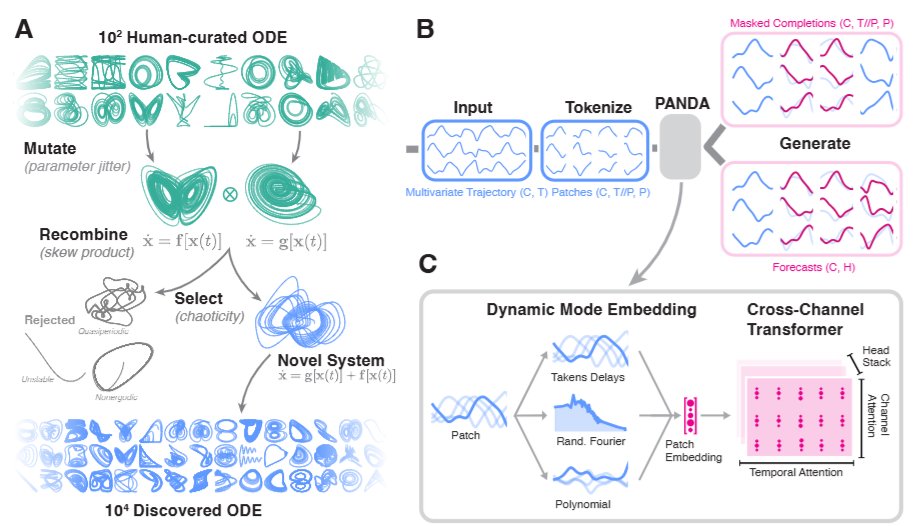
Panda: Pretrained Model for Chaotic Dynamics Forecasting
By
–
Panda: A pretrained forecast model for universal representation of chaotic dynamics Panda is a pretrained attention-based model trained solely on synthetic chaotic systems, capable of zero-shot forecasting across diverse, unseen real-world dynamical systems, including PDEs it
-
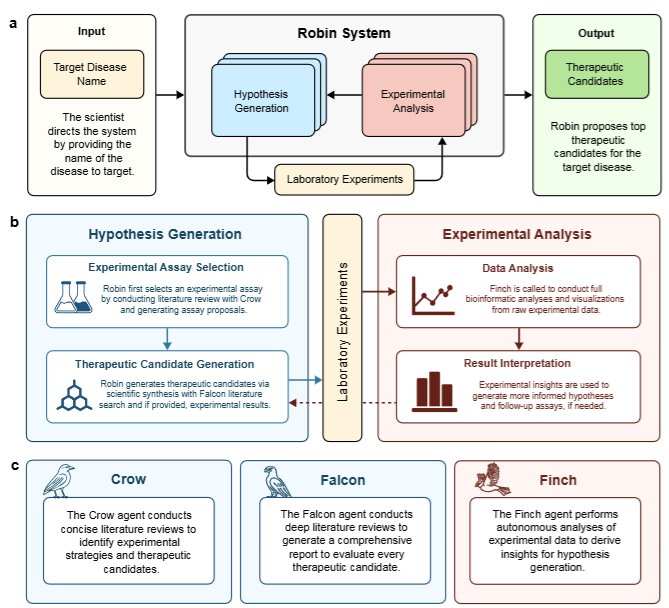
Robin: Multi-Agent AI System Automates Scientific Discovery Loop
By
–
Robin: A multi-agent system for automating scientific discovery Robin is the first multi-agent AI system to automate the entire scientific discovery loop—literature review, hypothesis generation, experiment design, data analysis, and hypothesis refinement—within a single
-
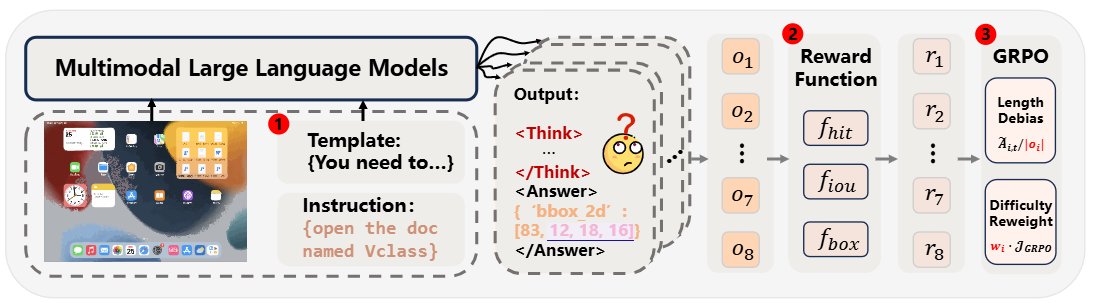
GUI-G1 and Robin: High-Performance Agents with Multimodal Improvements
By
–
Major upgrades for high-performance agents with the rise of GUI-G1 and Robin, alongside the notable multimodal improvements of diffusion language models Check out the top 10 papers for the week – GUI-G1: Understanding R1-Zero-Like Training for Visual Grounding in GUI
-
Claude 4 Sonnet Enables Advanced Research Paper Analysis
By
–
Introducing Claude 4 Sonnet for understanding arXiv papers 🚀
— alphaXiv (@askalphaxiv) 22 mai 2025
Highlight any section of a paper to ask questions and “@” other papers to quickly add to context and compare results, benchmarks, etc. pic.twitter.com/x3aZtaIT9rIntroducing Claude 4 Sonnet for understanding arXiv papers Highlight any section of a paper to ask questions and “@” other papers to quickly add to context and compare results, benchmarks, etc.
-

GenAI Advances Autonomous Driving to Level 5 Autonomy
By
–
How can Generative AI unlock Level 5 autonomy? This new survey explores how GenAI is reshaping the autonomous driving stack Covers VAEs, Diffusion, LLMs Applications in LiDAR, trajectory, digital twins Tackles long-tail generalization & safety bottlenecks
-
LLMs Enable More Precise Cyberattacks on Personal Data
By
–
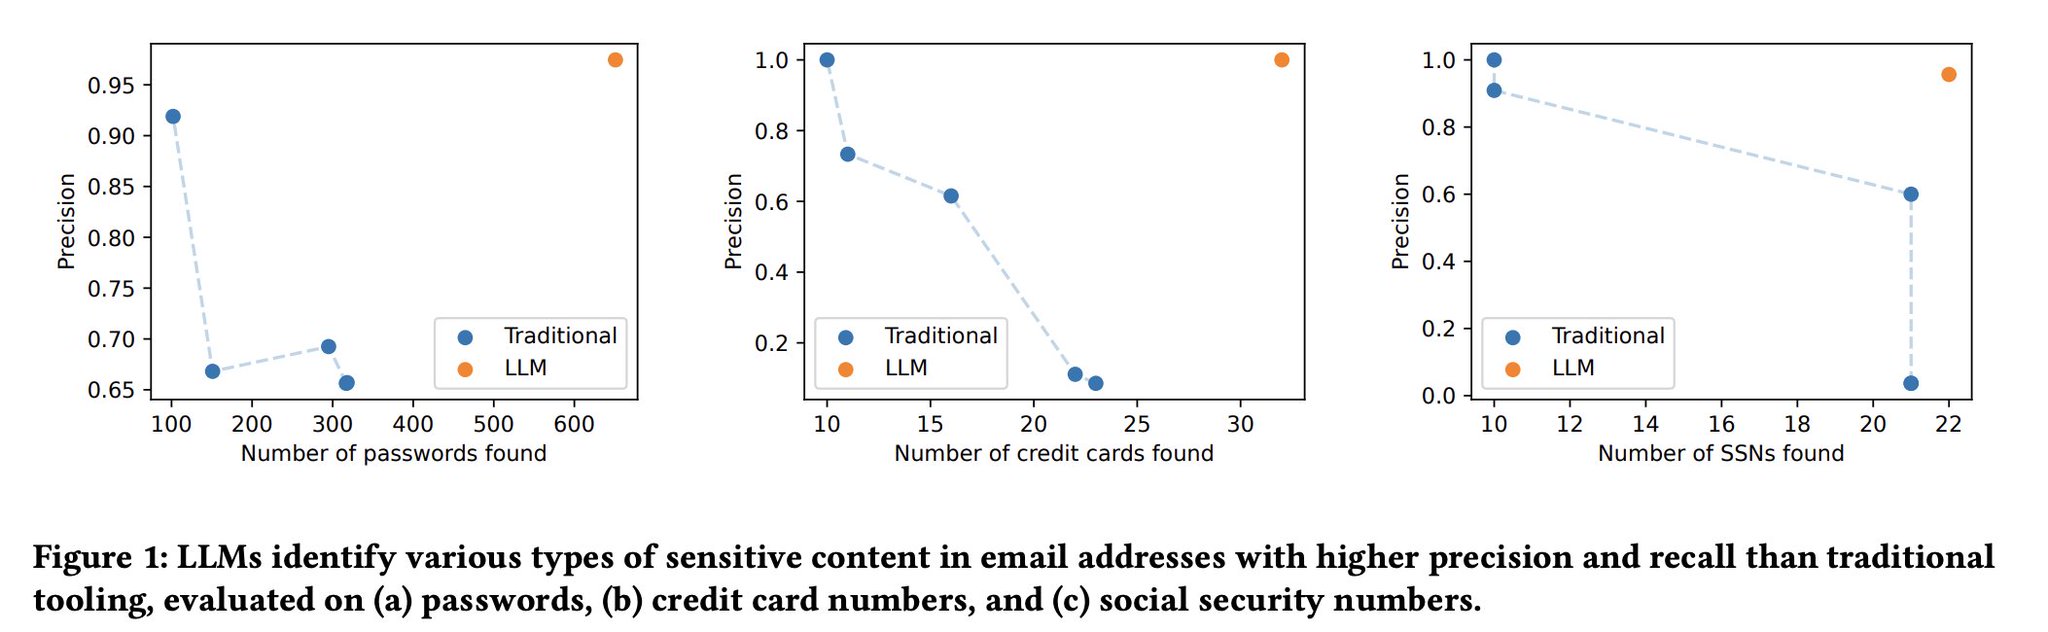
LLMs are fundamentally changing cyberattacks. This new paper from Anthropic and Google shows that LLMs Extract passwords, credit cards, and SSNs with higher precision Mine sensitive personal info for tailored blackmail Lower the cost of targeting vulnerable software
-

Hidden Economic Knowledge in LLM Embeddings Revealed
By
–
Revealing economic facts: LLMs know more than they say This paper shows that hidden states (embeddings) of large language models (LLMs) contain rich economic information that can be used to estimate and impute economic and financial statistics more accurately than the LLMs’ text
-
LightLab: Diffusion Model Controls Light Sources in Images
By
–
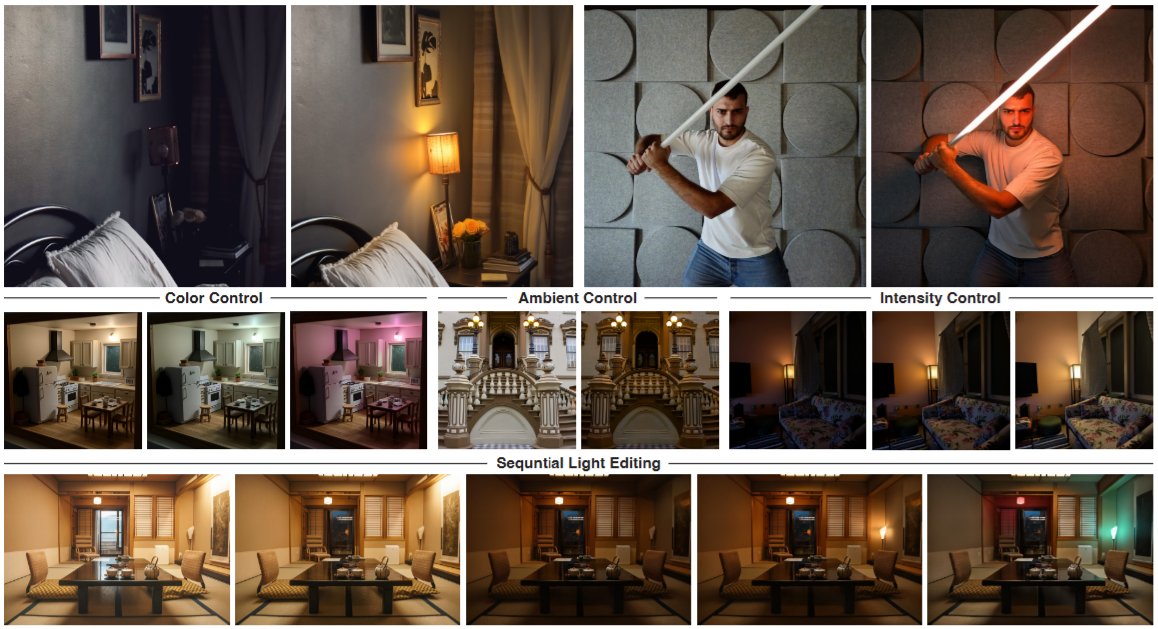
LightLab: Controlling Light Sources in Images with Diffusion Models LightLab presents a diffusion-based method for precise, parametric control over light sources in a single image, enabling users to edit light intensity and color with photorealistic results. The approach