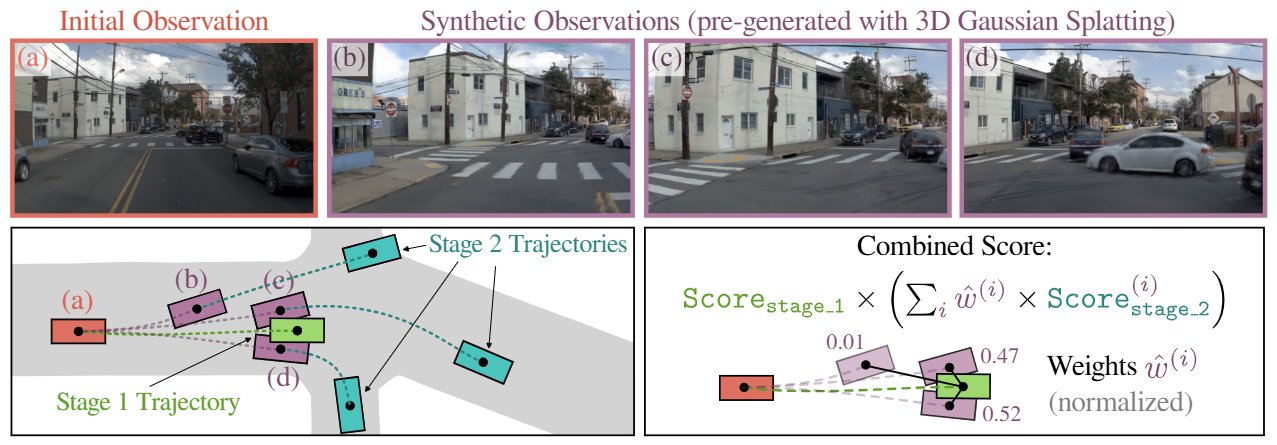
Pseudo-Simulation for Autonomous Driving Pseudo-simulation is a new evaluation paradigm for autonomous vehicles that blends the realism of real-world data with the generalization power of simulation, enabling robust, scalable testing without the need for interactive
@askalphaxiv
-

SmolVLA: Efficient Vision-Language-Action Model for Robotics
By
–
SmolVLA: A Vision-Language-Action Model for Affordable and Efficient Robotics SmolVLA is a compact, open-source VLA model built for low-cost training and real-world deployment on consumer hardware, enabling efficient language-driven robot control without sacrificing performance.
-
ProRL: Long-Horizon Reinforcement Learning Unlocks New LLM Reasoning
By
–
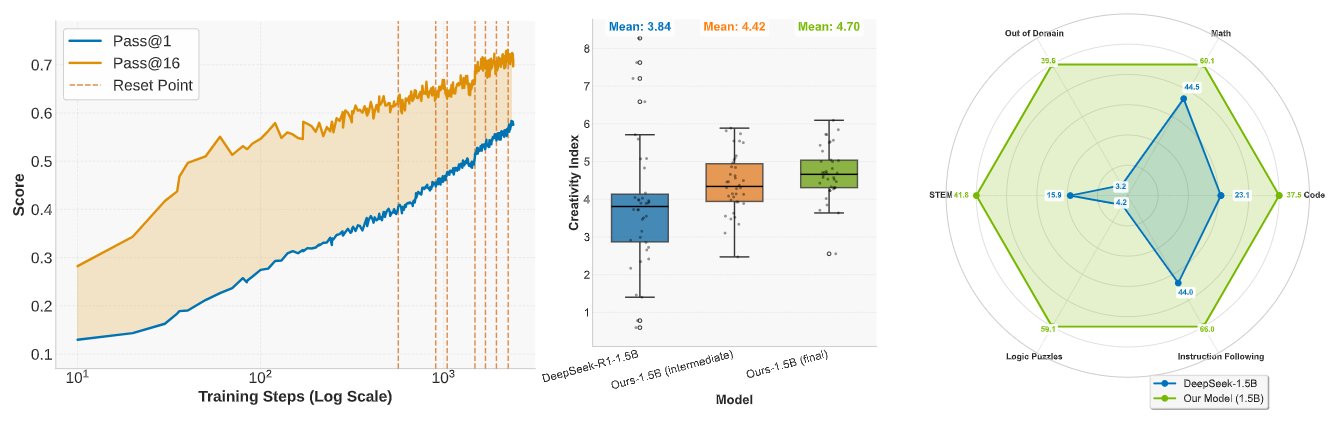
ProRL: Prolonged Reinforcement Learning Expands Reasoning Boundaries in Large Language Models This paper introduces ProRL, a method that uses long-horizon reinforcement learning to unlock new reasoning strategies in LLMs—strategies that base models cannot access, even with
-
Negative Reinforcement Improves LLM Reasoning Without Explicit Rewards
By
–
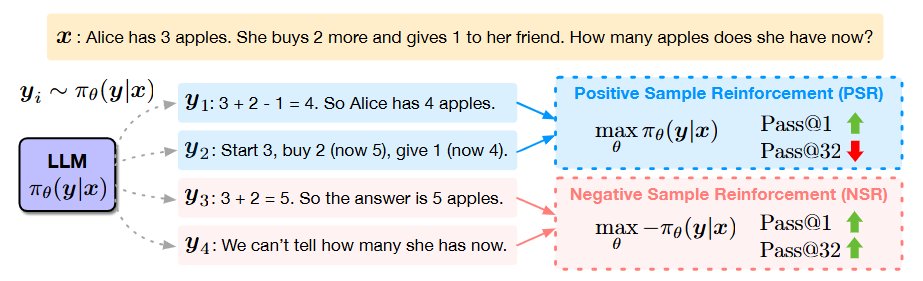
The Surprising Effectiveness of Negative Reinforcement in LLM Reasoning This paper shows that punishing incorrect answers—without explicitly rewarding correct ones—can be surprisingly effective for improving reasoning in large language models trained via reinforcement learning
-
Chain-of-Thought Prompting: Constraint Mimicry Over True Reasoning
By
–
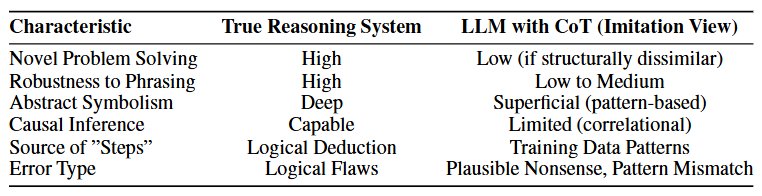
CoT is Not True Reasoning, It Is Just a Tight Constraint to Imitate: A Theory Perspective This paper challenges the idea that Chain-of-Thought (CoT) prompting enables true reasoning in LLMs, arguing instead that CoT acts as a structural constraint that guides models to imitate
-
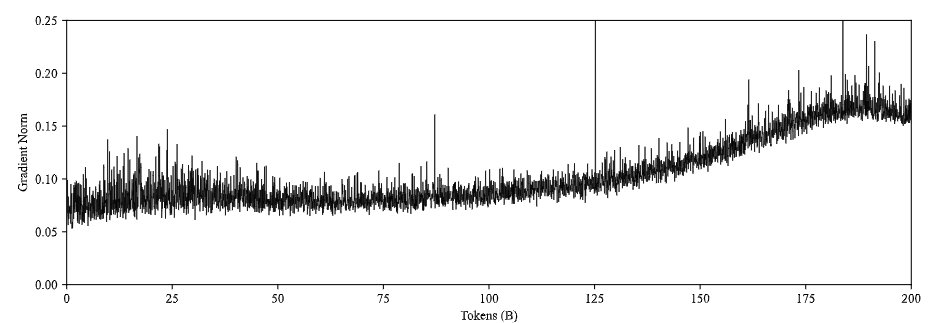
Gradient Surge in LLM Training: Weight Decay and Normalization
By
–
Why Gradients Rapidly Increase Near the End of Training This note investigates a sudden rise in gradient norms during the late stages of LLM training and identifies a surprising cause: the interplay between weight decay, normalization layers, and scheduled learning rate decay.
-
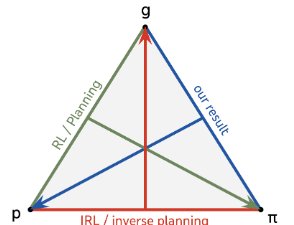
General agents require world models for reliable task completion
By
–
General agents need world models This paper proves that any general agent capable of reliably completing diverse, goal-directed tasks must implicitly learn a predictive model of its environment—challenging the notion that model-free learning is sufficient for general
-

High-Entropy Tokens Drive LLM Reasoning via Reinforcement Learning
By
–
Beyond the 80/20 Rule: High-Entropy Minority Tokens Drive Effective Reinforcement Learning for LLM Reasoning This paper investigates how a small subset of high-entropy tokens—termed "forking tokens"—drives the performance of reinforcement learning with verifiable rewards (RLVR)
-
CPGD: Stabilizing Rule-Based Reinforcement Learning for Language Models
By
–
CPGD: Toward Stable Rule-based Reinforcement Learning for Language Models CPGD introduces a novel reinforcement learning algorithm designed to stabilize policy updates for language models trained with rule-based rewards, addressing instability and training collapse issues found
-

vec2vec: Unsupervised Text Embedding Translation Method
By
–
Harnessing the Universal Geometry of Embeddings This work introduces vec2vec, the first unsupervised method to translate text embeddings between different vector spaces without any paired data, encoders, or predefined matches, by leveraging a universal latent semantic