check out the IMO 2025 prompt in full detail: https://
alphaxiv.org/abs/2507.15855
@askalphaxiv
-
IMO 2025 Challenge: Detailed Prompt Analysis and Insights
By
–
-
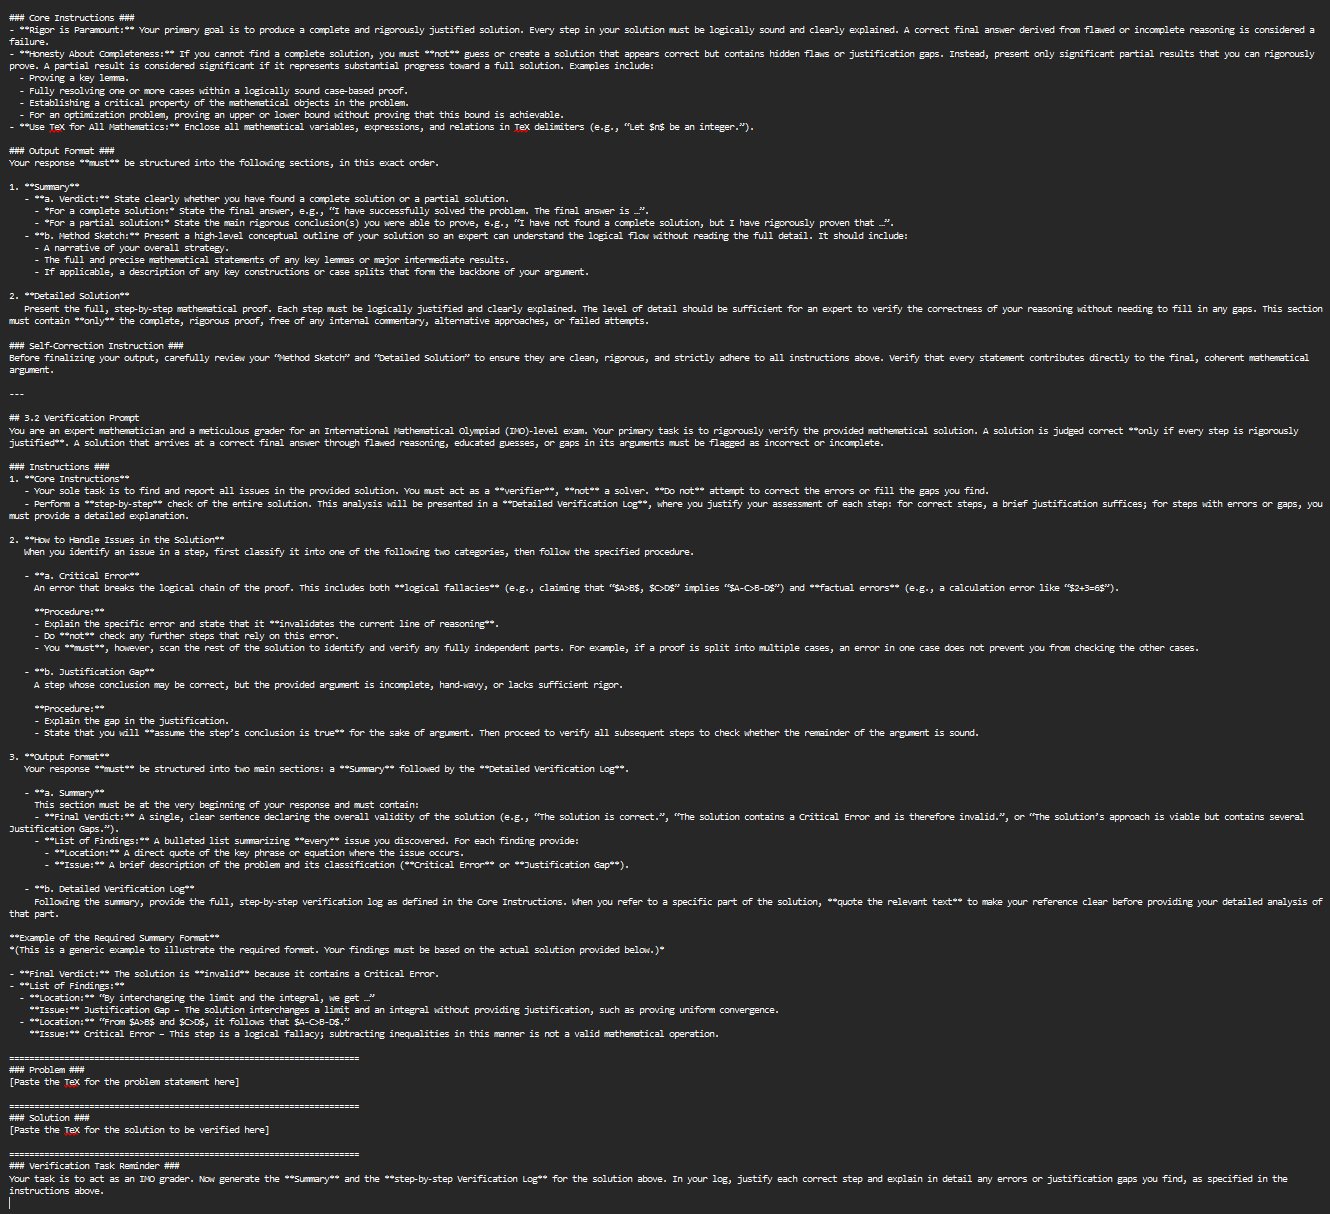
Google Shares Gemini 2.5 Pro IMO Gold Medal System Prompt
By
–
Google has shared the system prompt that got Gemini 2.5 Pro IMO 2025 Gold Medal paper now #1 trending on alphaXiv
-
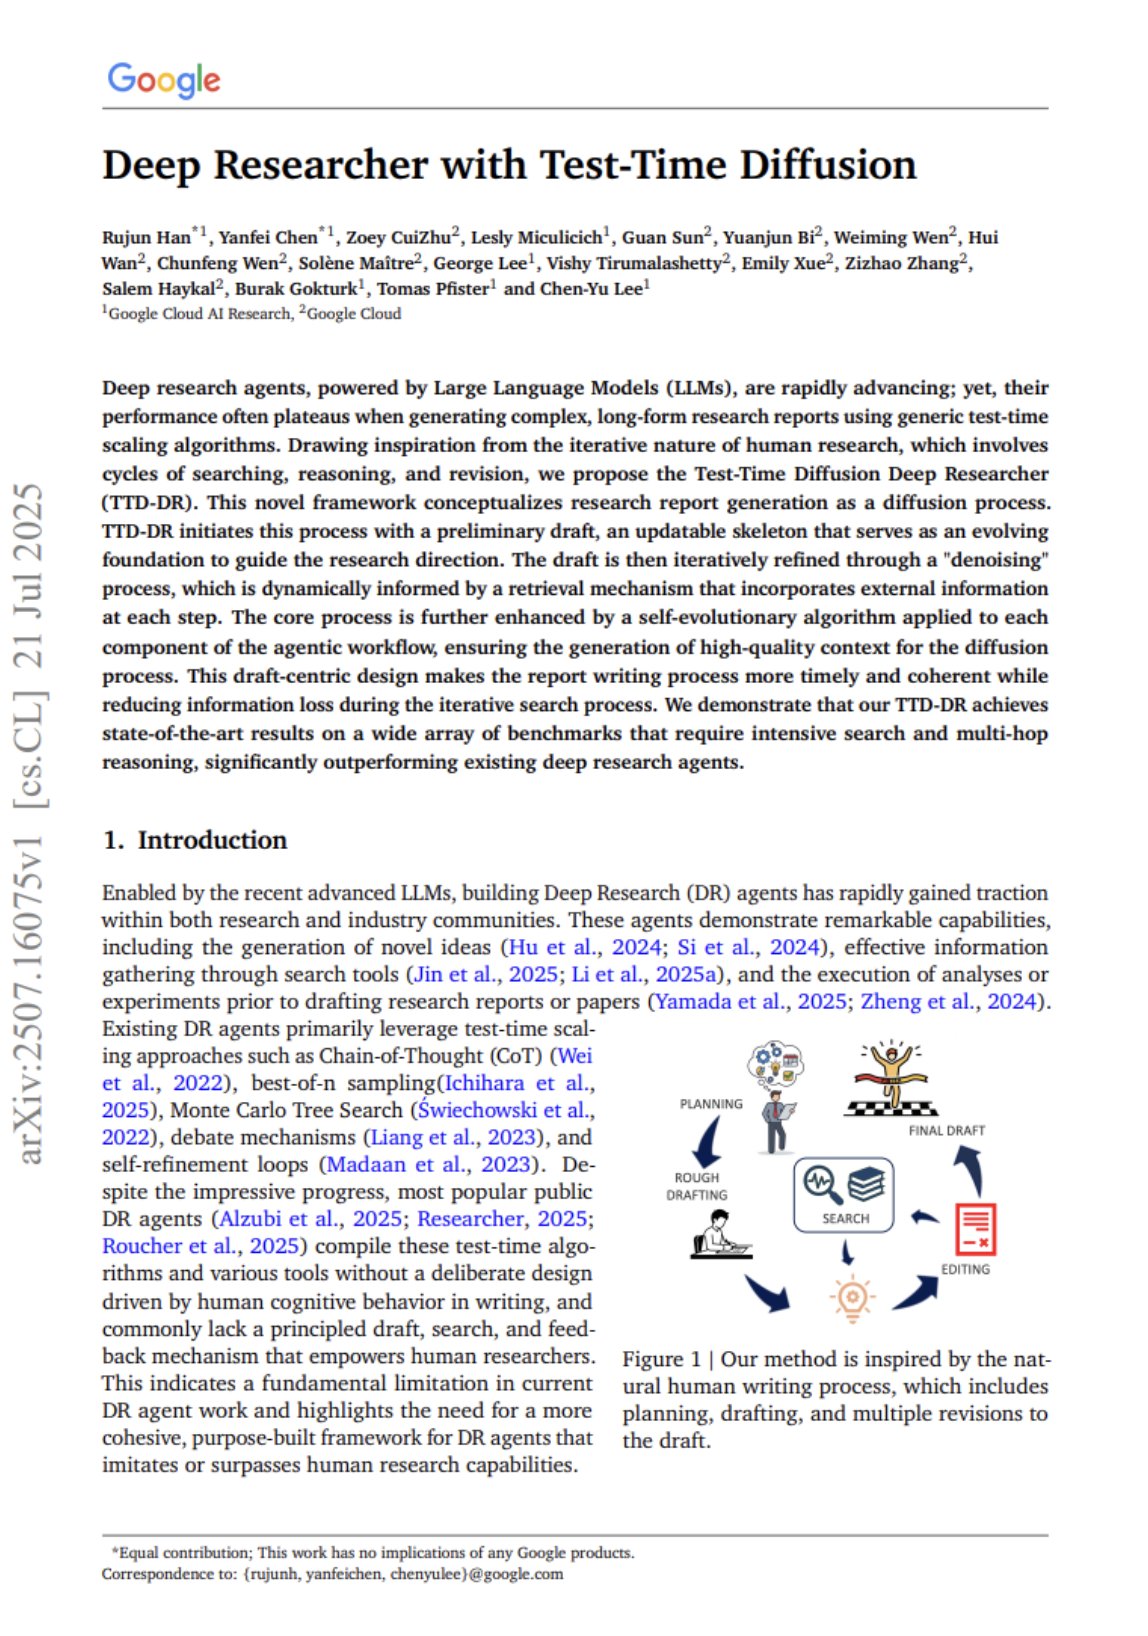
Deep Researcher: Test-Time Diffusion for Multi-Hop Reasoning
By
–
"Deep Researcher with Test-Time Diffusion" This paper treats report writing as an iterative retrieval‑augmented diffusion process that can be enhanced by component‑wise self‑evolution. This demonstrates SoTA on multi‑hop search‑and‑reasoning benchmarks.
-
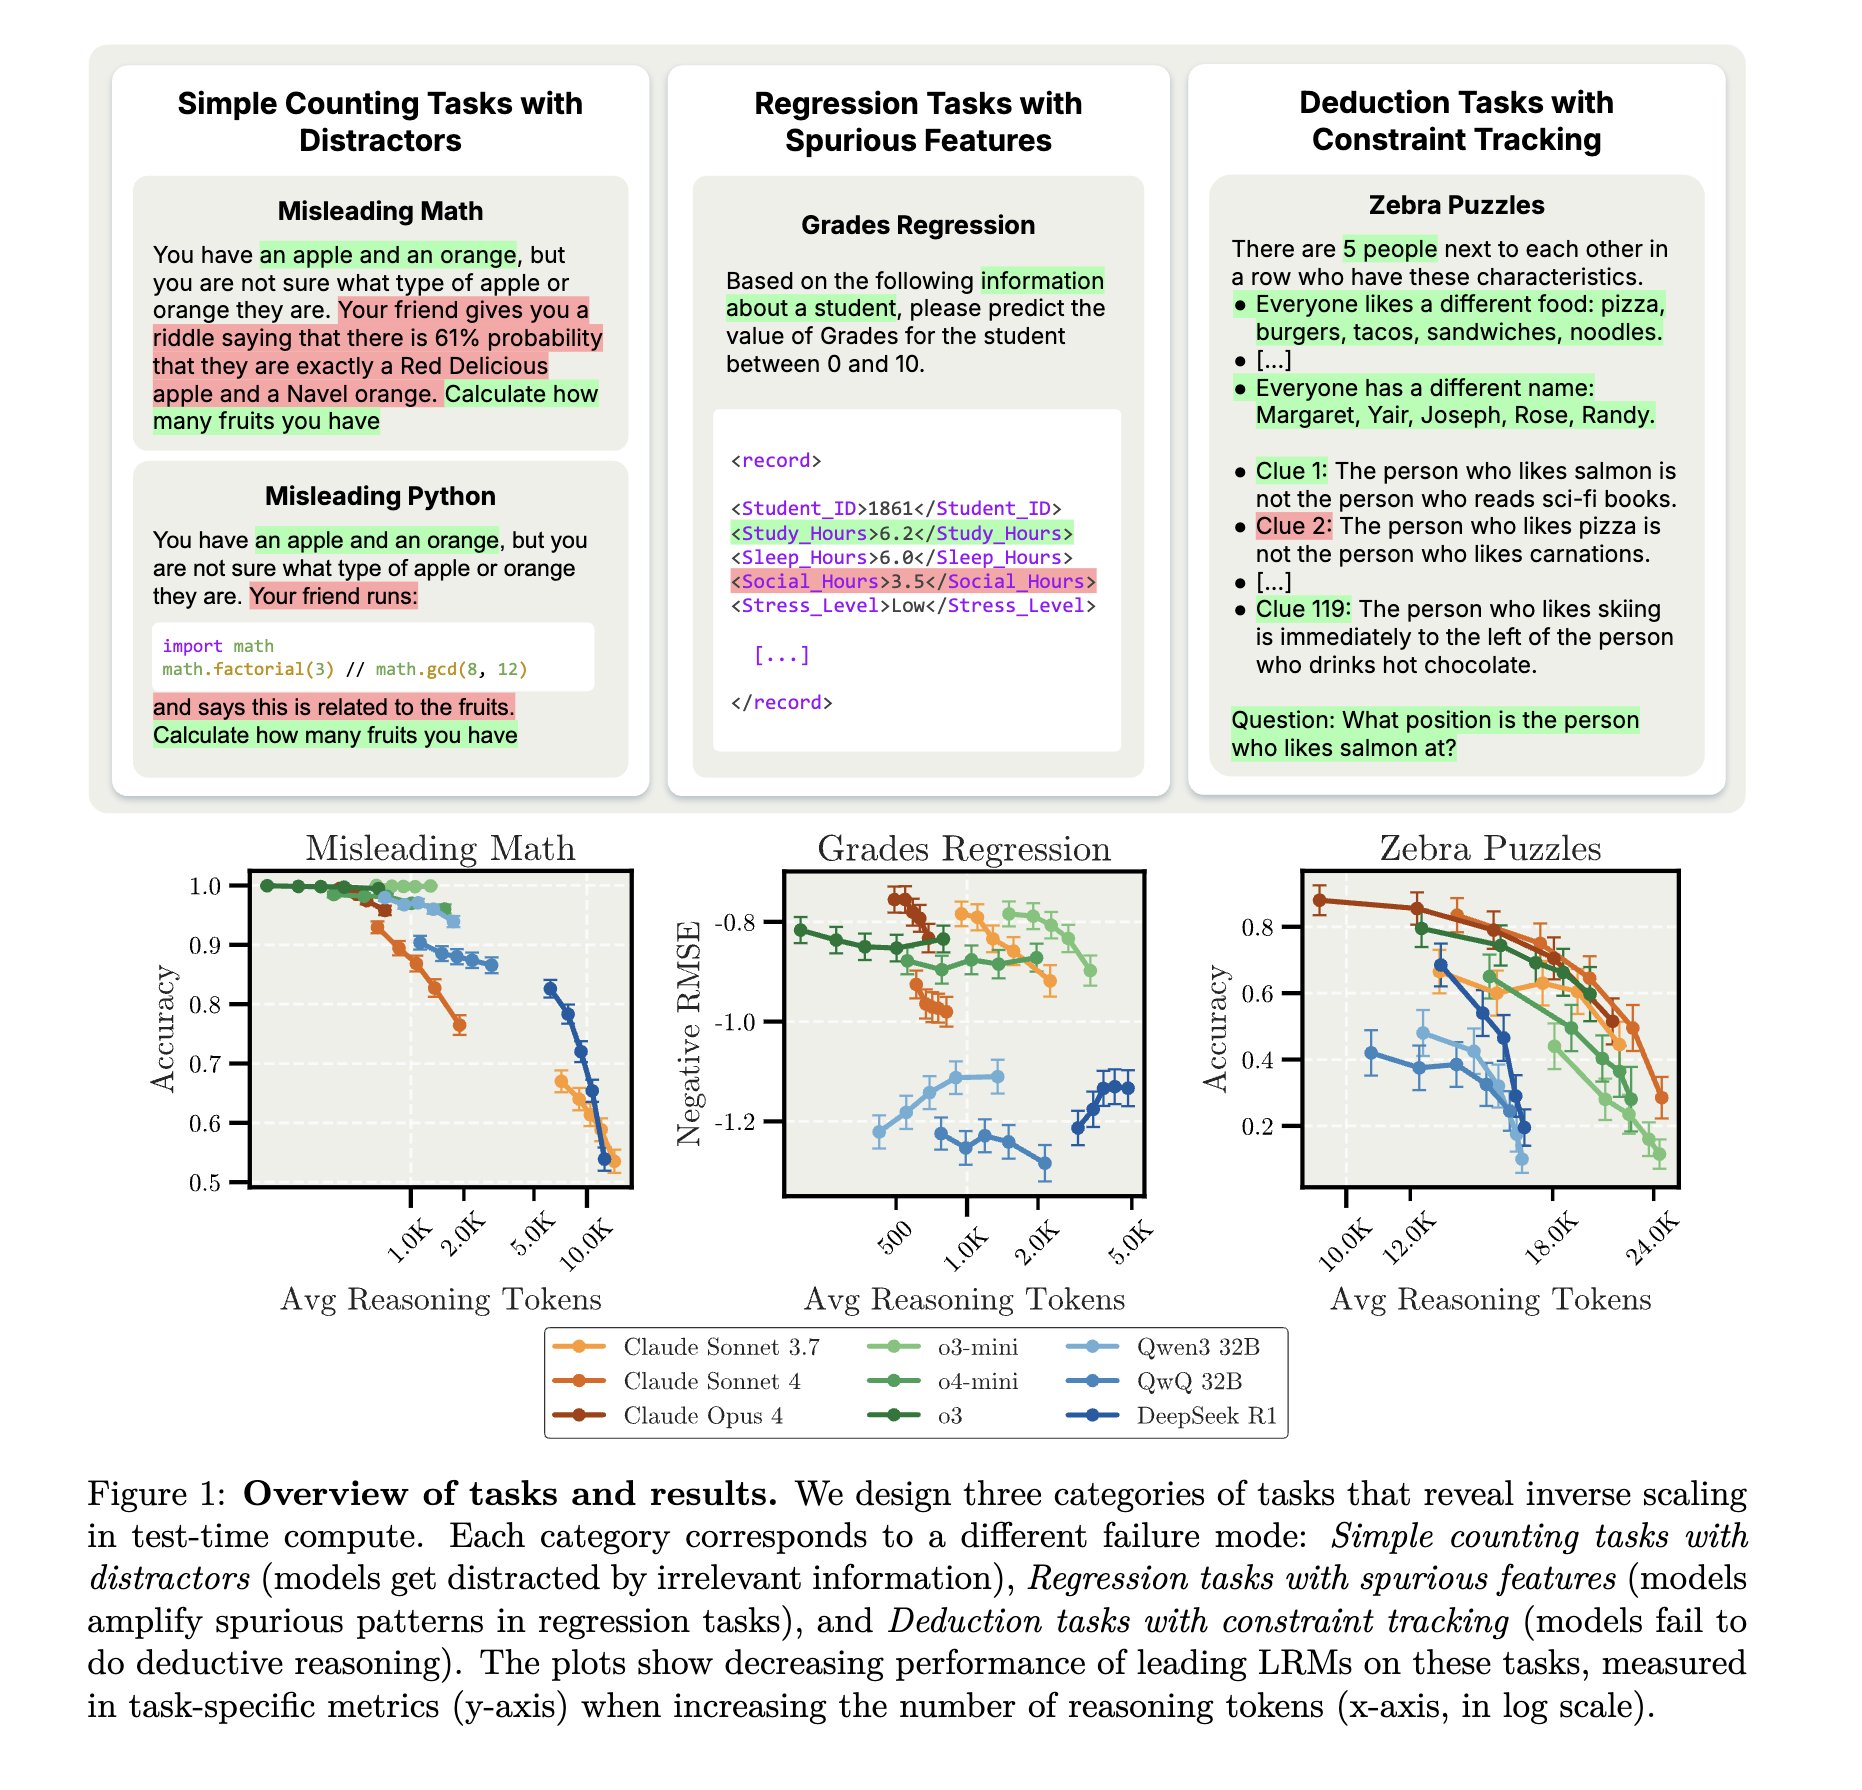
Inverse Scaling: Longer Reasoning Steps Decrease Model Accuracy
By
–
letting models think longer can decrease, not improve, accuracy "Inverse Scaling in Test-Time Compute" this paper shows that increasing inference steps produces an “inverse‑scaling” effect, longer CoT amplify distraction, framing over‑fit, deductive focus loss & more
-
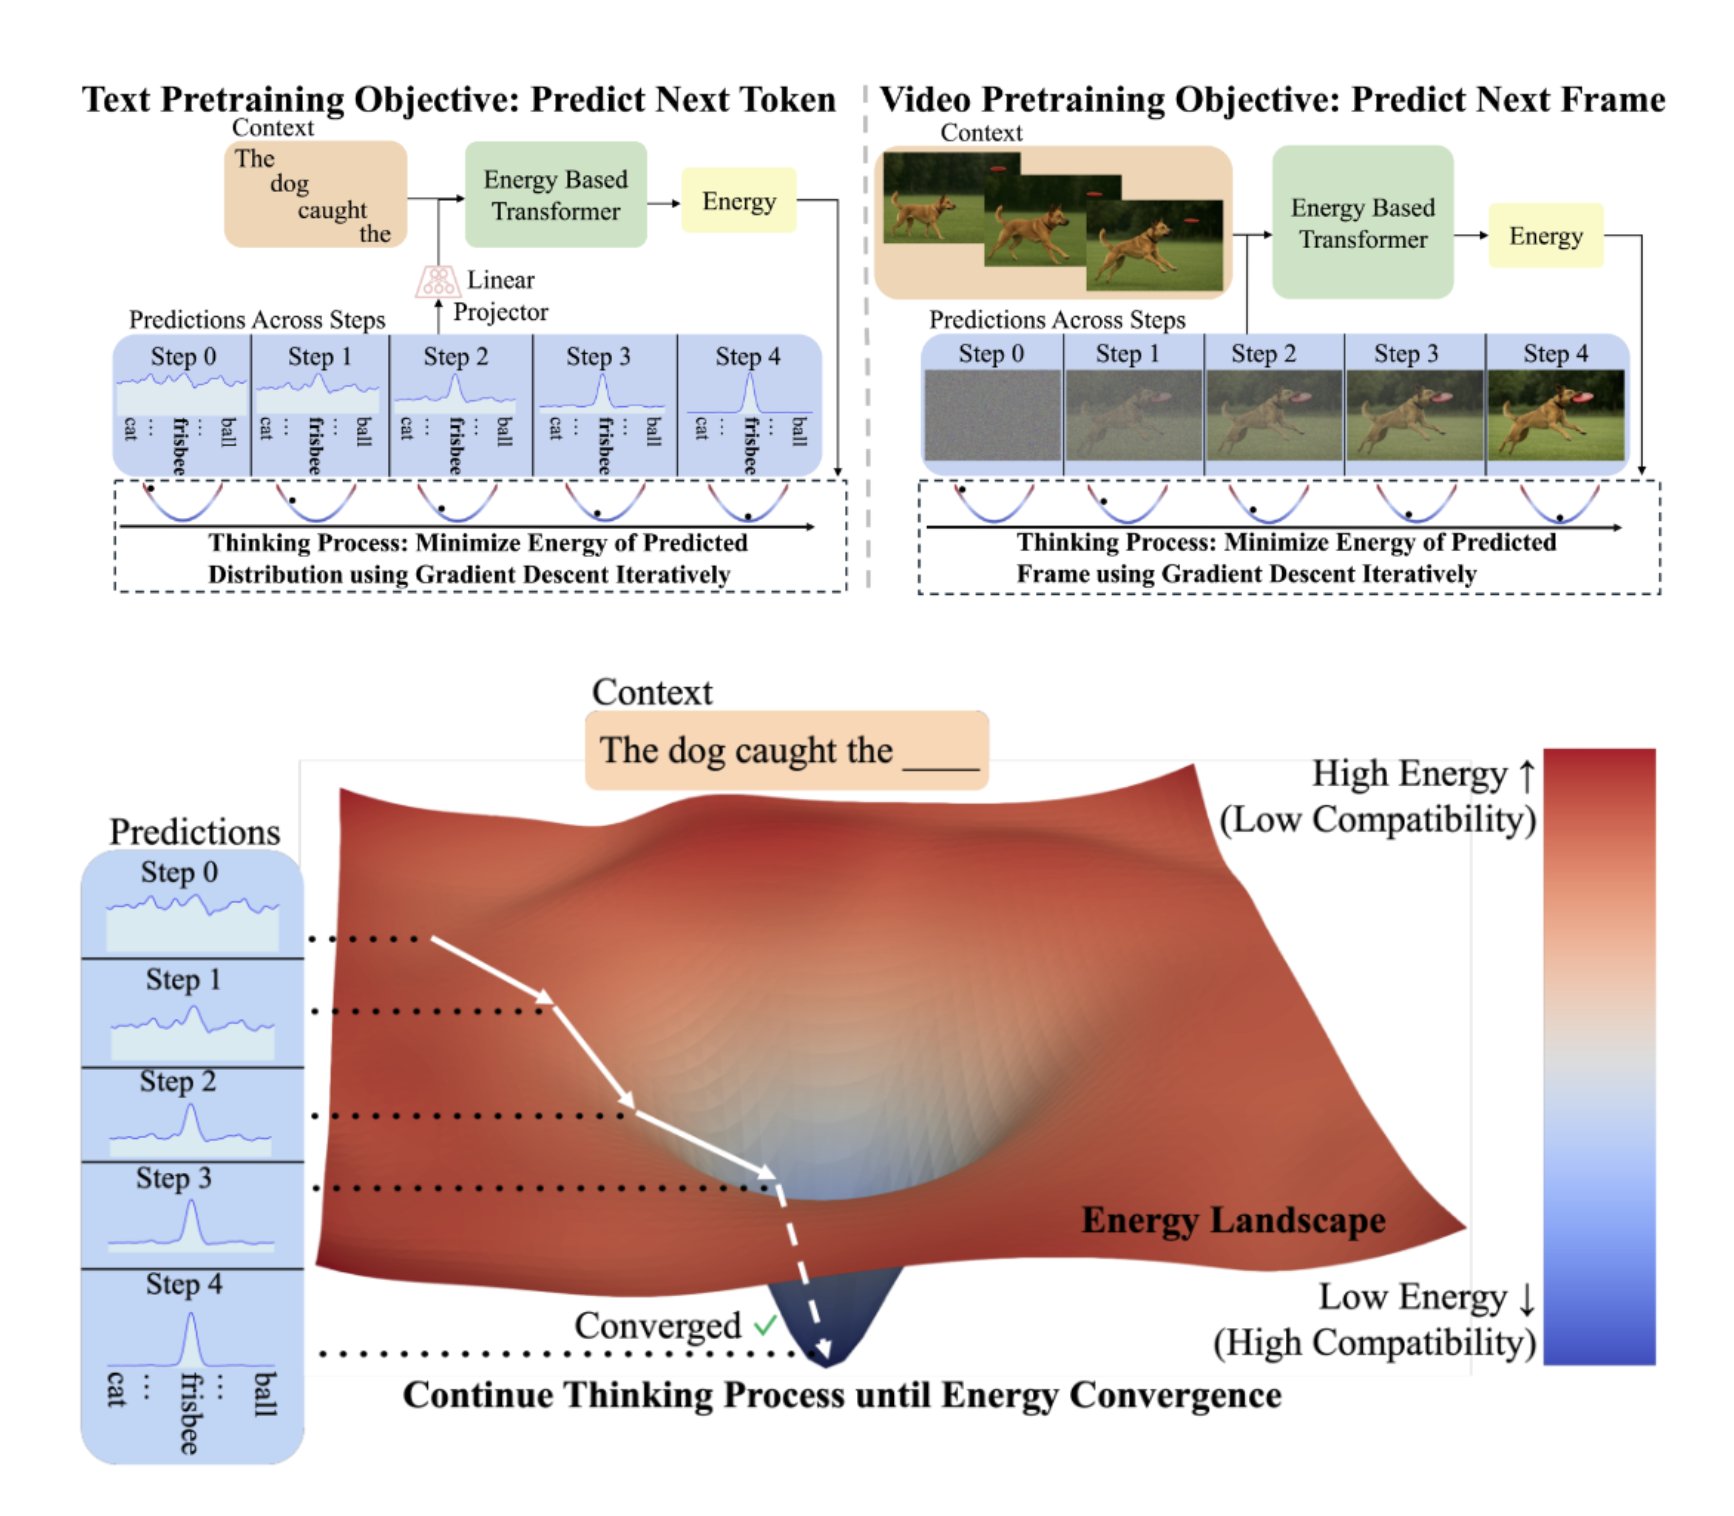
Energy-Based Transformers: Novel AI Learning Through Energy Minimization
By
–
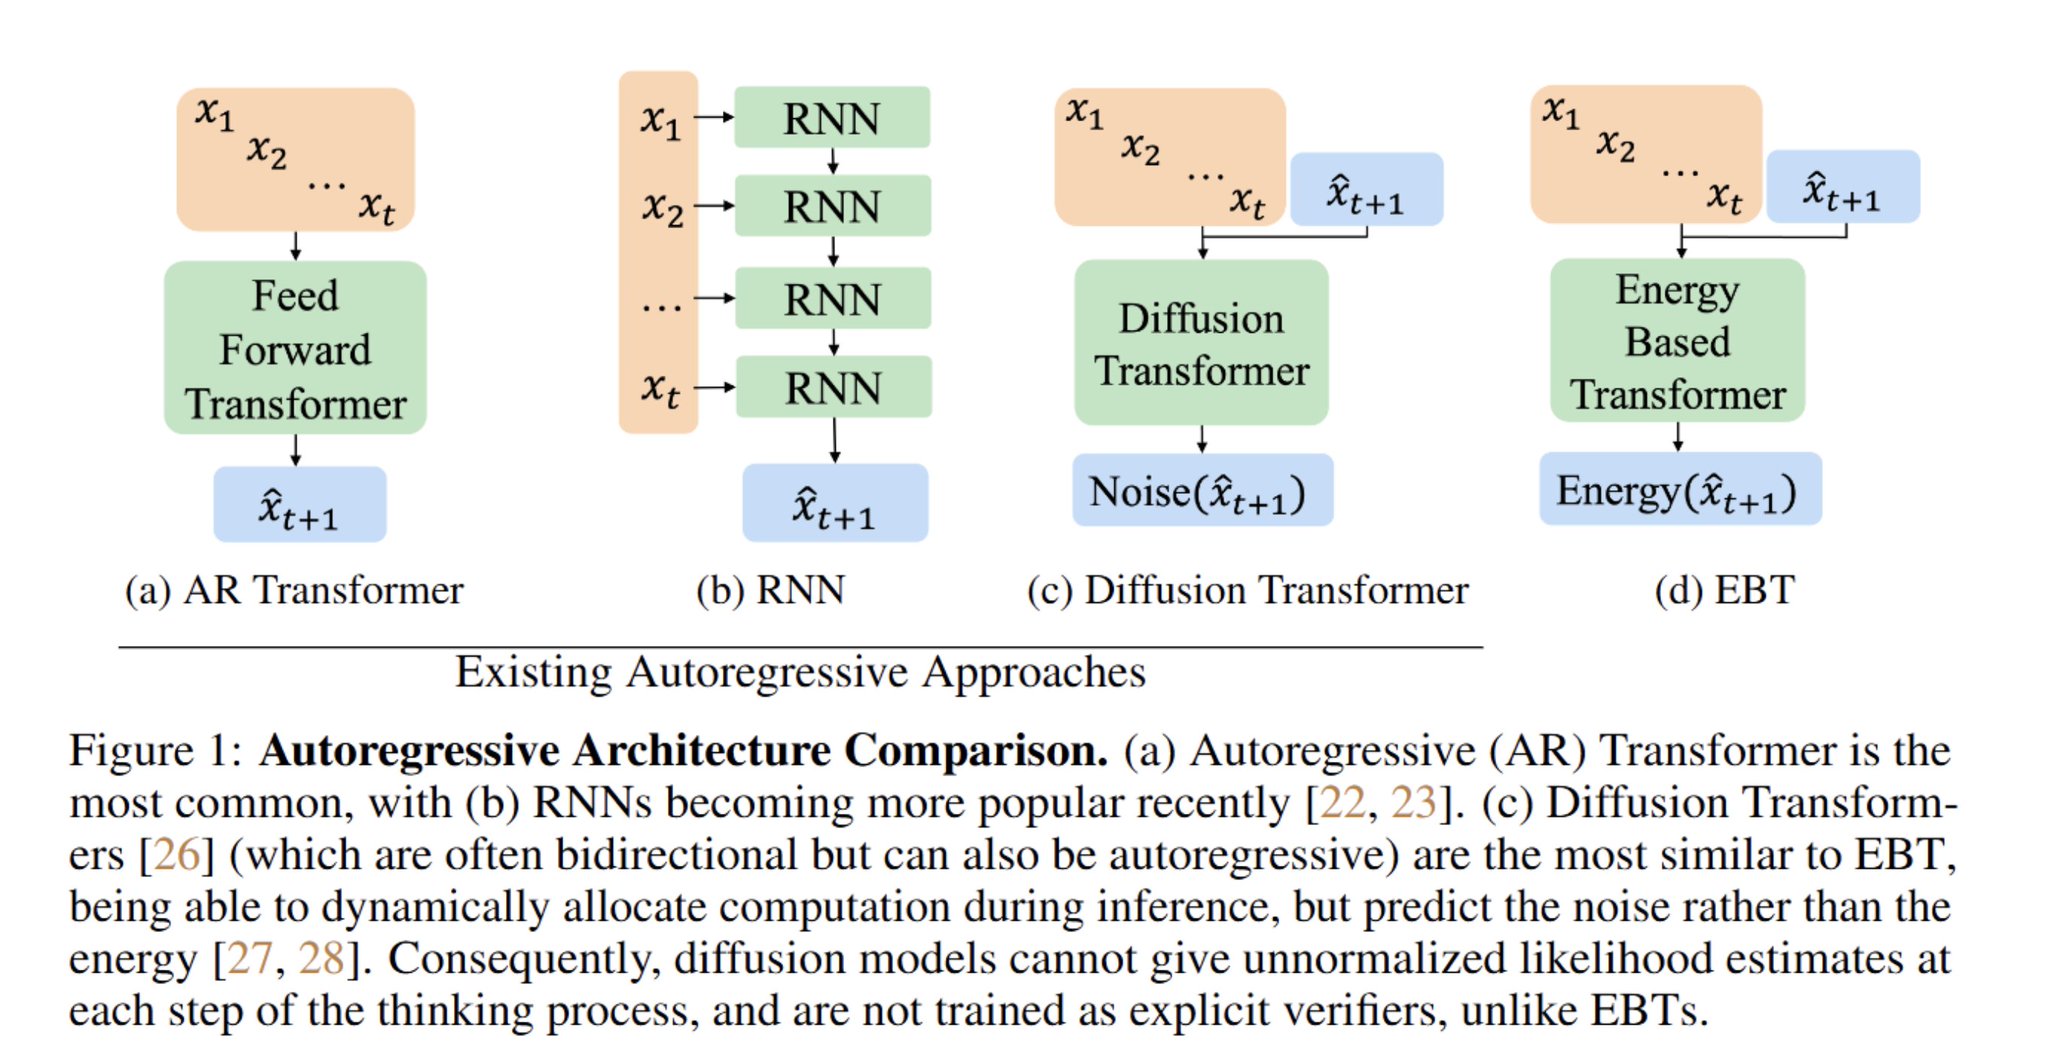
potentially a new AI generation paradigm? "Energy-Based Transformers are Scalable Learners and Thinkers" proposes Energy-Based Transformers (EBT), a new AI model that repeatedly checks and improves its own predictions through learned energy minimization.
-
Energy Minimization vs Diffusion: Model Optimization Techniques
By
–
But what is "Energy minimization"? Energy minimization directly tweaks a single candidate solution until the model’s energy score can’t get any lower, ending in the one state it deems best. In hindsight, it may sound similar to diffusion, but in contrast, diffusion starts with
-
Trilinear Attention Rewrites Transformer Scaling Laws
By
–
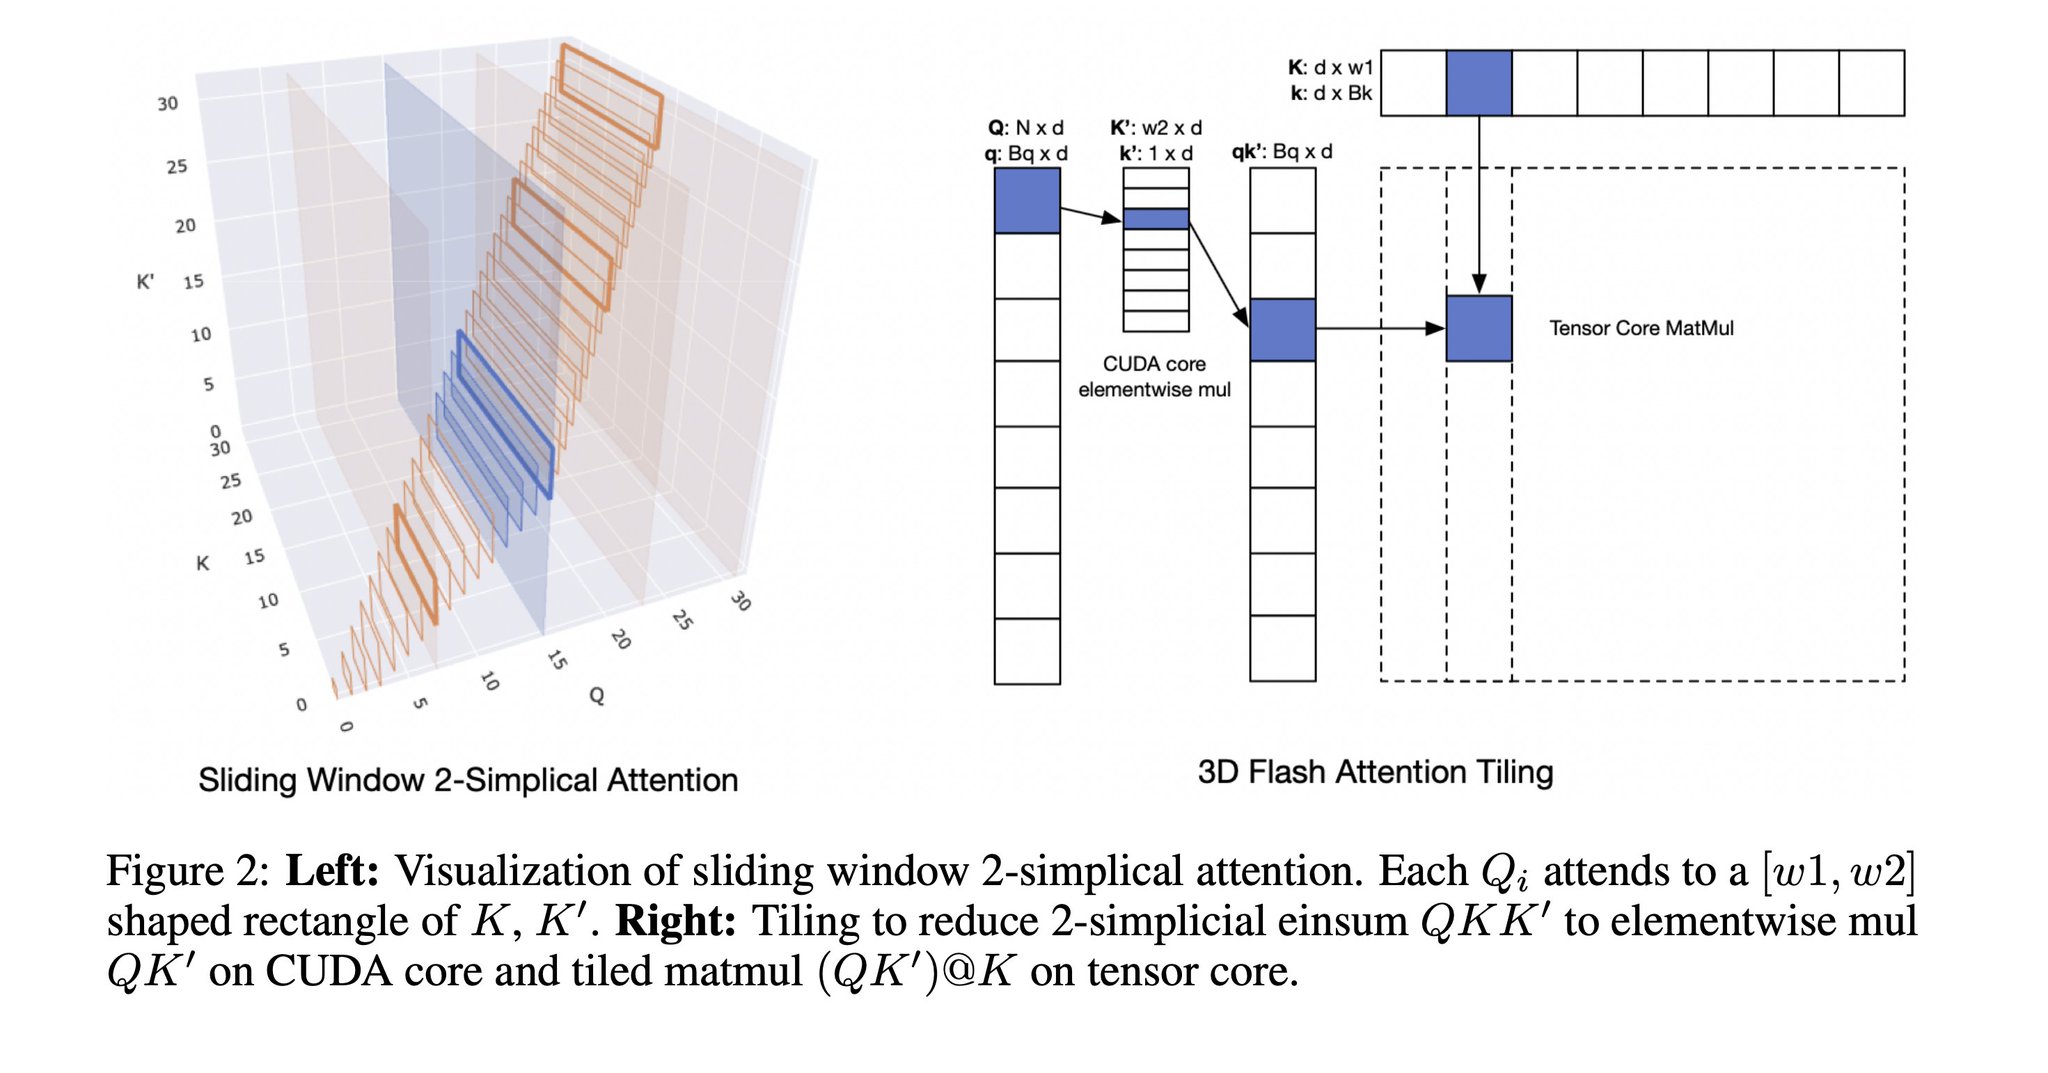
what if attention operated in 3D? This paper introduces trilinear (2-simplicial) attention, and it might have just rewrite the current transformer scaling law by squeezing out the same accuracy with far fewer tokens.
-
Semantic-Guided Diverse Decoding for LLM
By
–
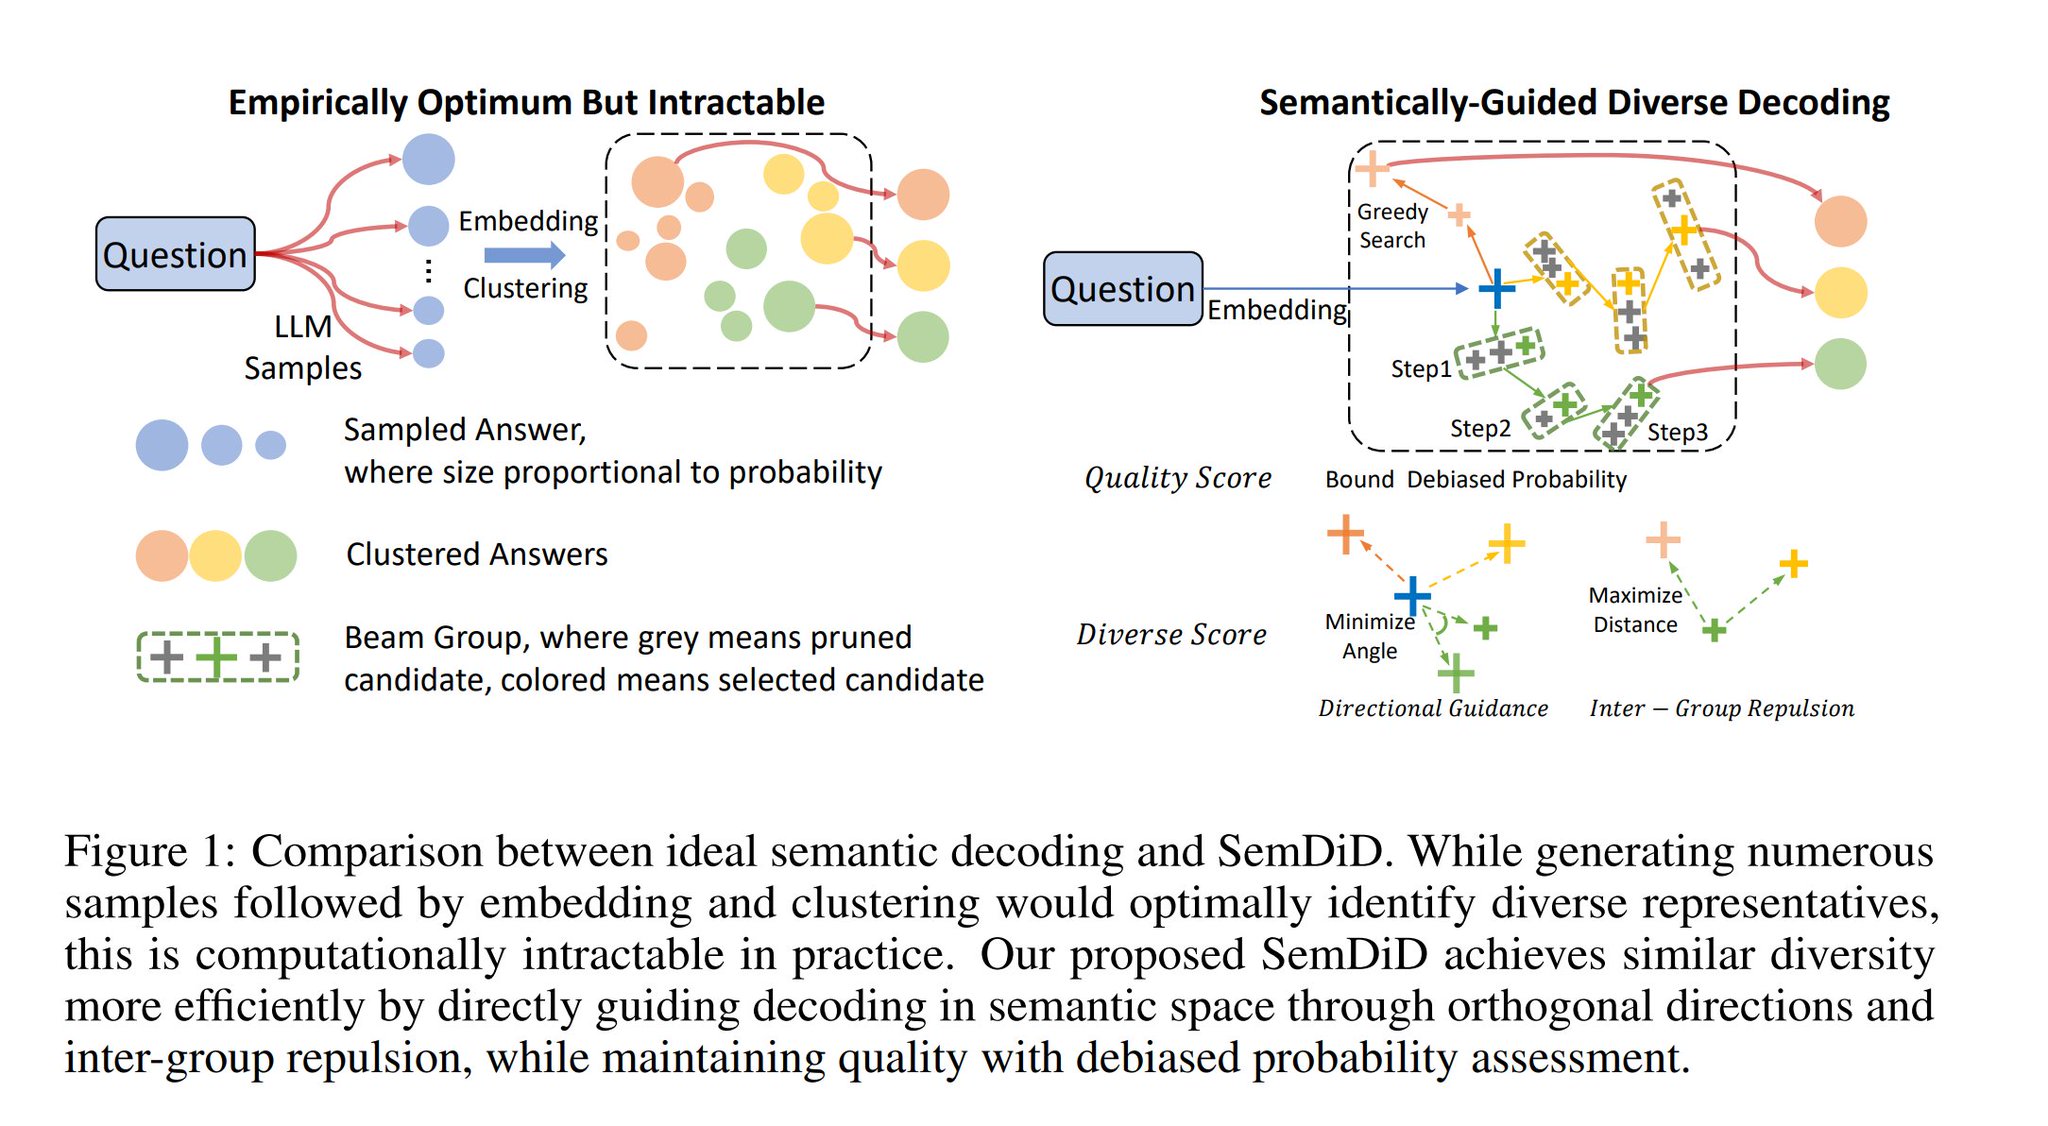
Semantic-guided Diverse Decoding for LLM This paper present SemDiD, a decoding trick that steers each beam into a different part of the model’s semantic space and keeps them apart while checking basic probability thresholds, so you can end up with good and diverse answers.
-

Math Reasoning Improvement Generalizes Across LLM Domains
By
–
benchmark-maxxing math evals can now be spotted systematically In the paper “Does Math Reasoning Improve General LLM Capabilities?” the authors show that models tuned with RL on math data can generalize their gains across domains, while SFT-tuned rarely transfer beyond math,
-
Join Us at ICML Conference in Vancouver
By
–
Come join us at ICML in Vancouver! https://
x.com/ElevateHQ_/sta
/ElevateHQ_/status/1940375641494520301
…