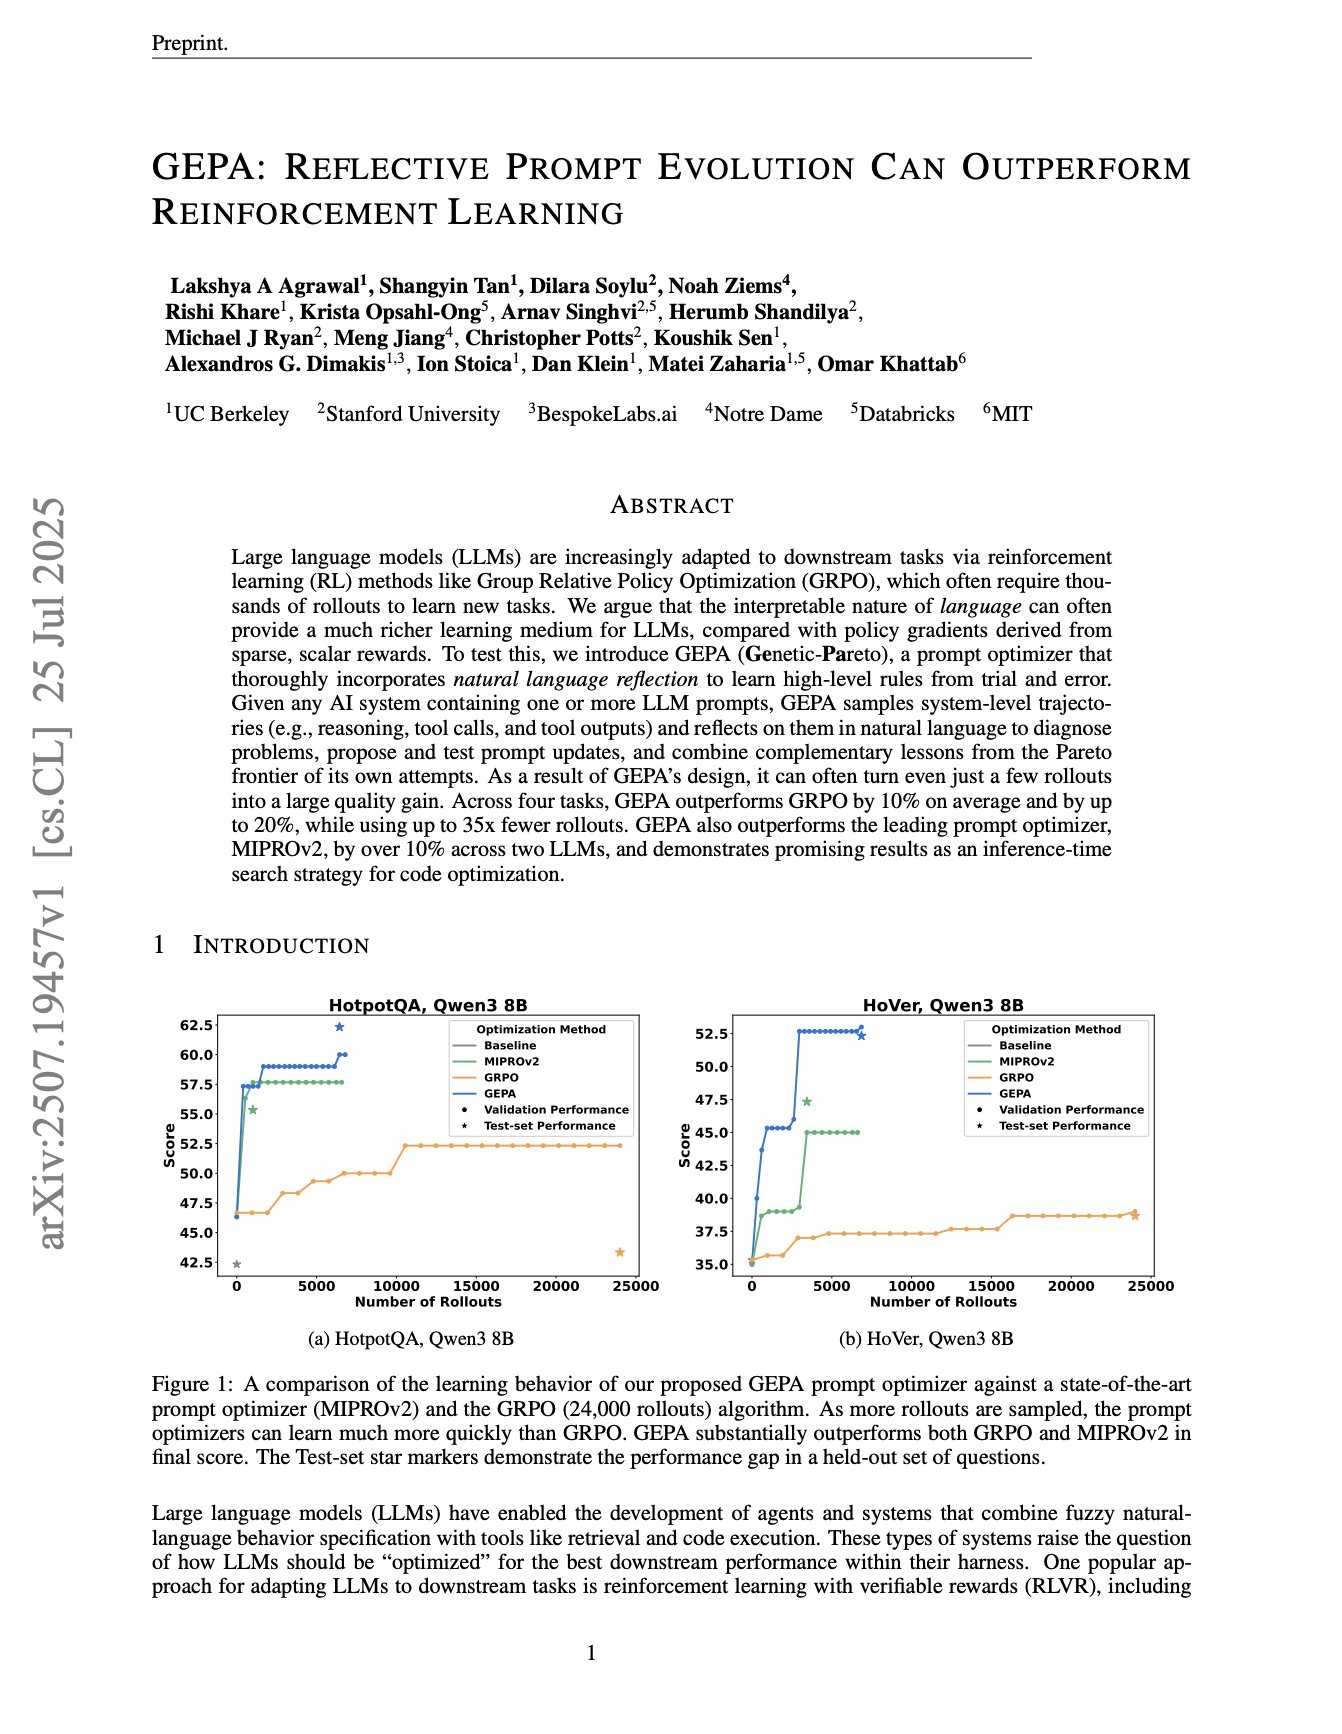
Iterative reflections for LLMs can outperform heavy RL? This paper shows that having the LLM reflects on its own trajectories, rewrite its own prompts, and evolve a diverse pool of candidates beats RL w/ GRPO so far on four reasoning tasks . 10% improv with 35x fewer rollouts!
@askalphaxiv
-
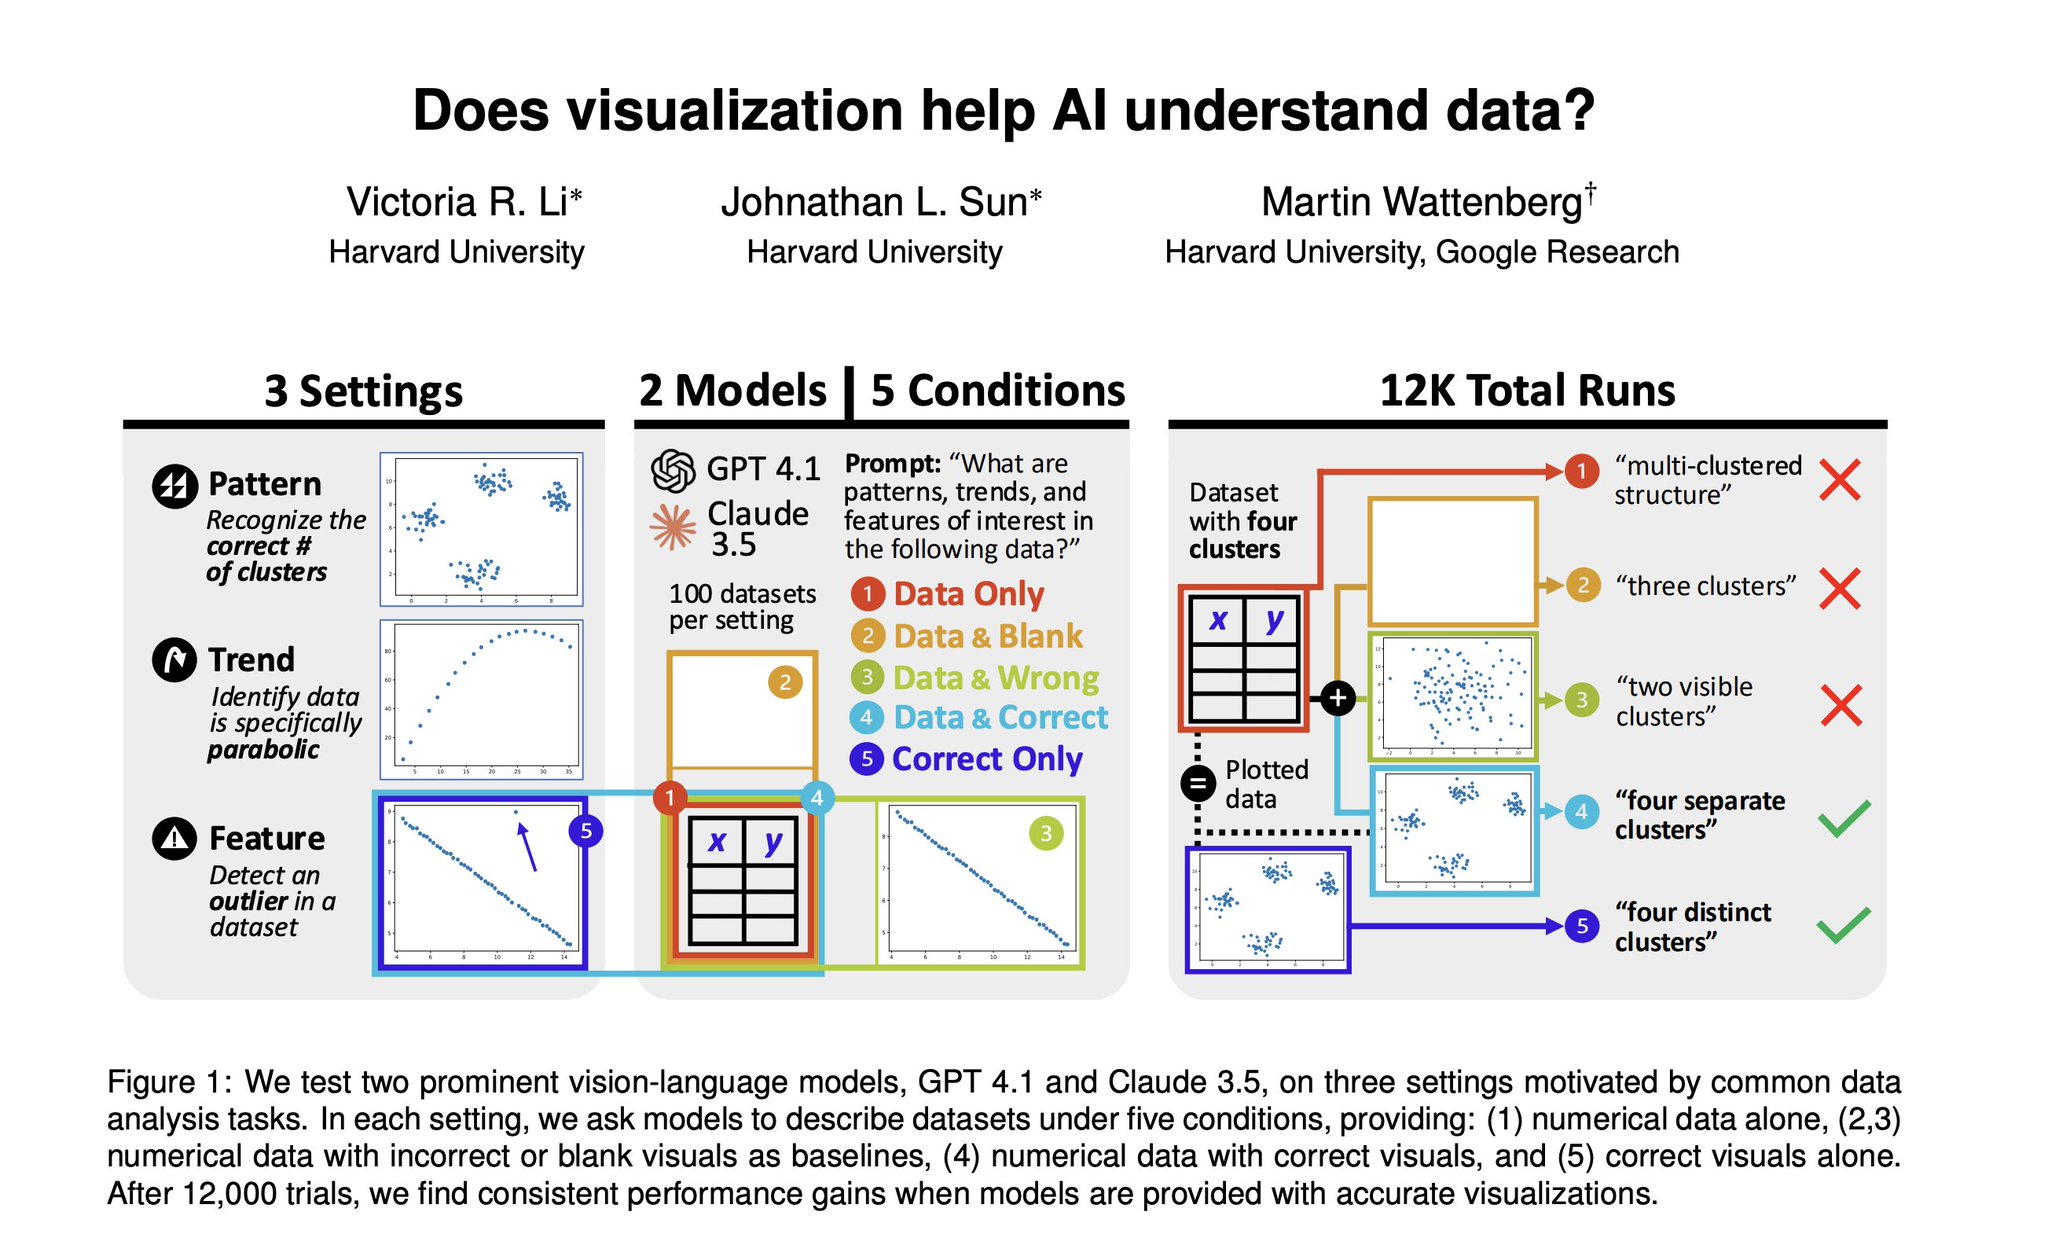
VLMs Outperform with Visual Data Alone Over Numerical
By
–
Interestingly, VLMs perform better with plot alone compared to plot + data! This paper shows that GPT‑4.1 and Claude 3.5 excels at scatterplot analysis, and could often perform better only by looking at the plot, without reading the actual numerical data.
-
SJTU’s Neural Architecture Search Claims Superintelligence Amid Criticism
By
–
SJTU's latest paper claims artificial superintelligence for neural architecture search. But critics on alphaXiv call it inconsistent and "buzzword maxxing"
– Seemingly AI generated sections of the paper
– Relies on objective benchmarks and metrics it critiques -
Alibaba Qwen 3 Reasoning: AI Tool for Research Paper Analysis
By
–
Introducing @Alibaba_Qwen 3 Reasoning for understanding research papers 🚀
— alphaXiv (@askalphaxiv) 27 juillet 2025
Highlight any section of a paper to ask questions and “@” other papers for quick context, comparisons, and benchmark references pic.twitter.com/7yG2QNWpzKIntroducing @Alibaba_Qwen 3 Reasoning for understanding research papers Highlight any section of a paper to ask questions and “@” other papers for quick context, comparisons, and benchmark references
-
alphaXiv AI Platform Now Available Alongside Gemini Claude
By
–
Now available in addition to Gemini and Claude. Check out http://
alphaXiv.org! Alternatively check out our Chrome extension: -
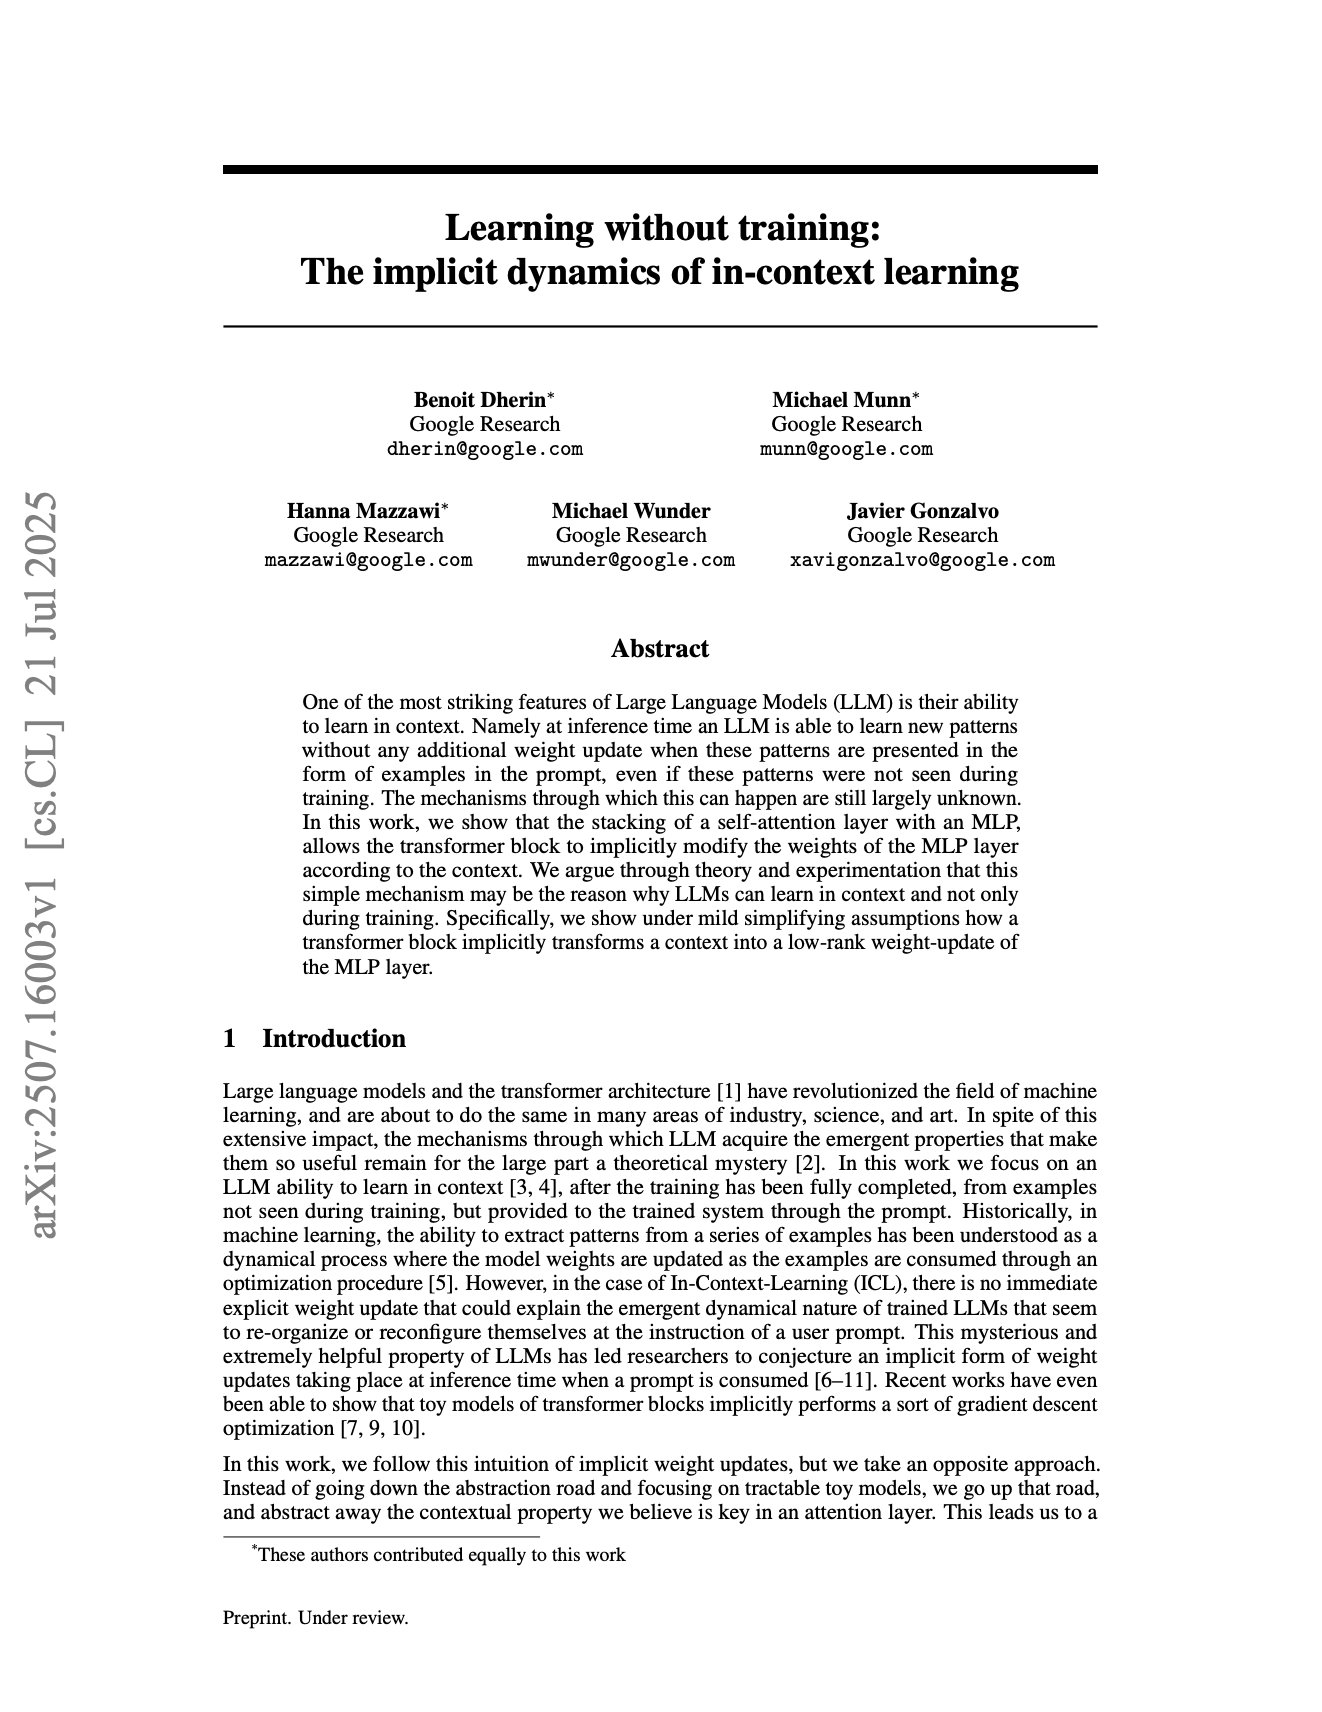
In-Context Learning as Implicit Gradient Descent During Inference
By
–
In-context learning is just gradient descent without explicit training! This paper "Learning without training: The implicit dynamics of in-context learning" shows that ICL can be mathematically interpreted as an implicit low-rank weight update during inference.
-
alphaXiv launches as alternative to Gemini and Claude
By
–
Now available in addition to Gemini and Claude. Check out http://
alphaXiv.org! Alternatively check out our Chrome extension: -
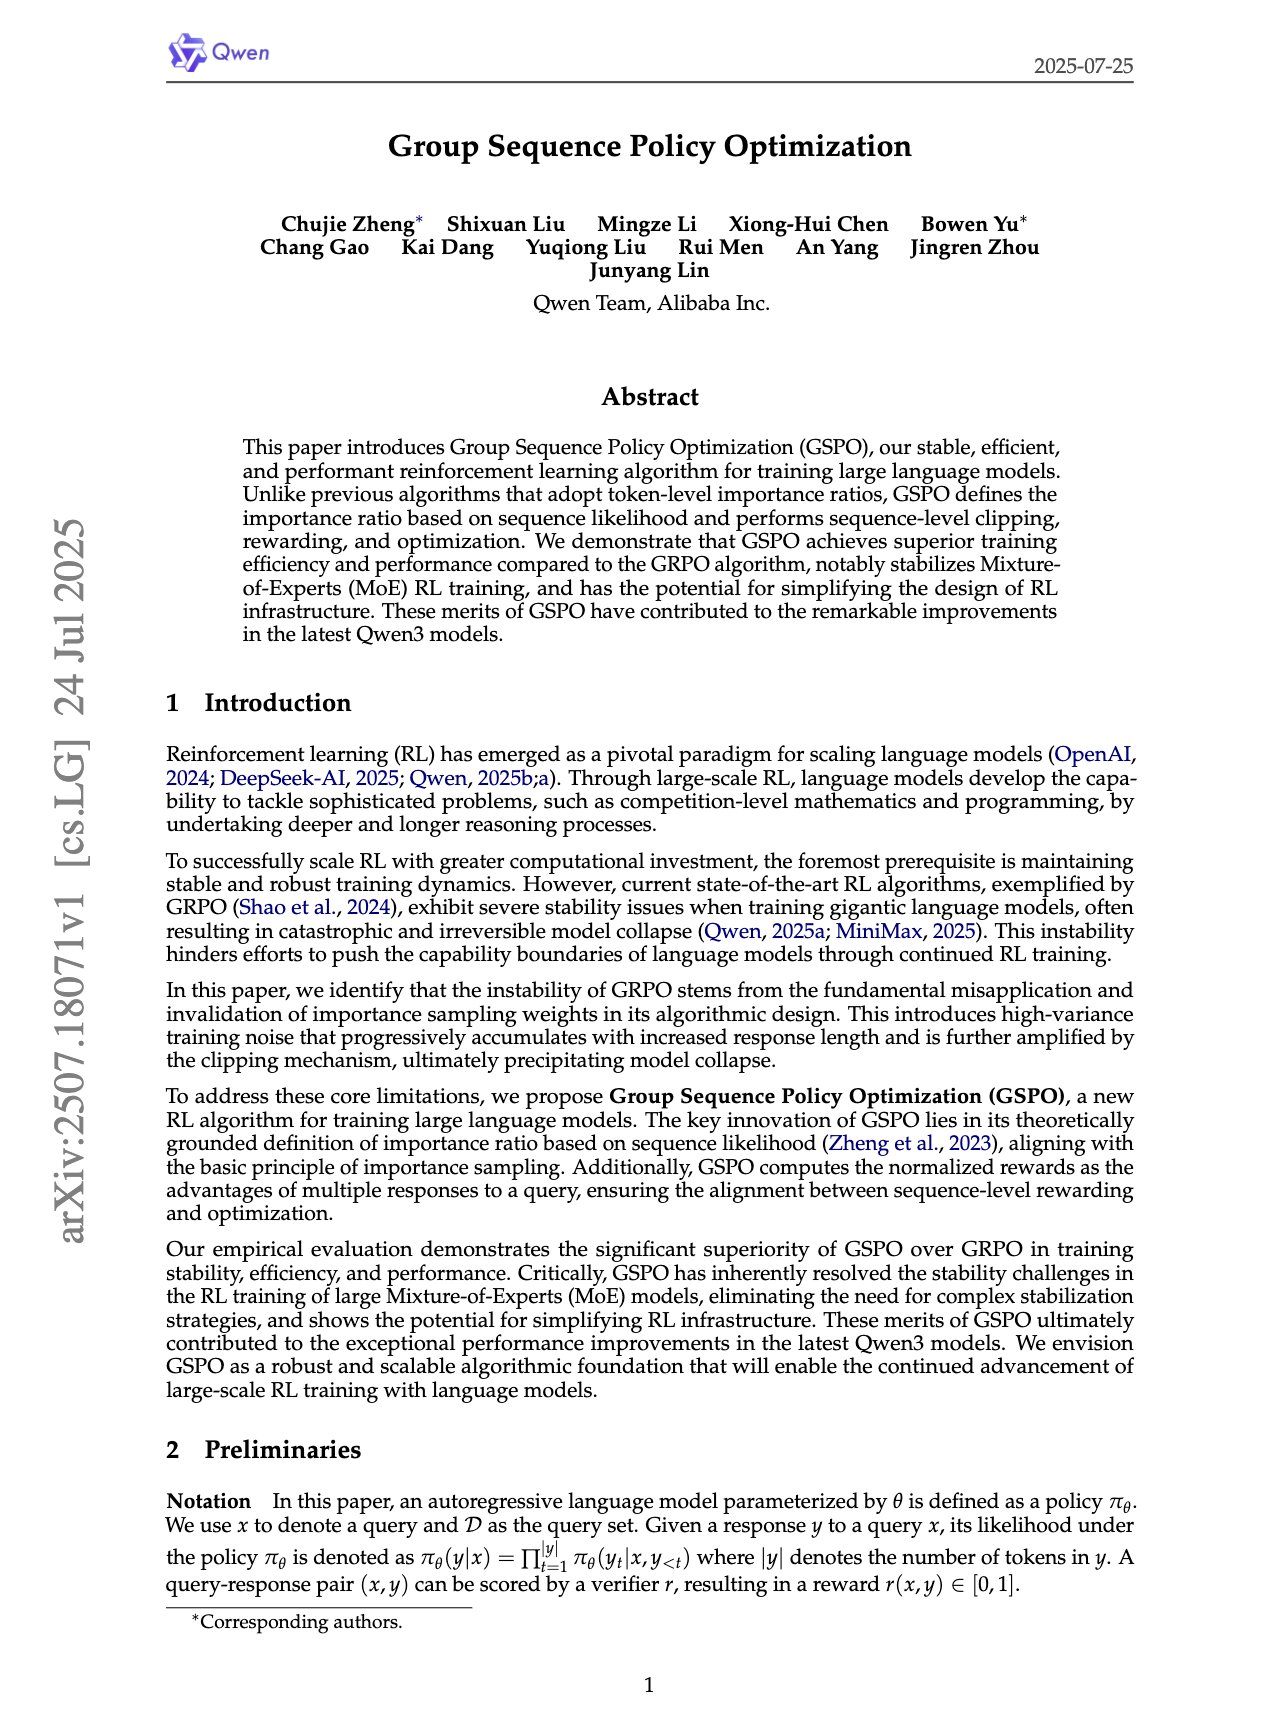
Qwen Introduces Group Sequence Policy Optimization for LLMs
By
–
"Group Sequence Policy Optimization" Qwen introduces Group Sequence Policy Optimization (GSPO), a RL algorithm for LLMs that uses sequence-level importance weighting and clipping instead of token-level methods, which provides high performing training for MoE models.
-
Kexin Huang discusses Biomni at AI4Science community event
By
–
Excited to have @KexinHuang5 giving a talk on Biomni to our AI4Science community tomorrow!
— alphaXiv (@askalphaxiv) 24 juillet 2025
Join us this Friday at 10 AM PST 📢: https://t.co/OxZBYHcWiS https://t.co/l9HKAcidFIExcited to have @KexinHuang5 giving a talk on Biomni to our AI4Science community tomorrow! Join us this Friday at 10 AM PST : https://
lu.ma/oqz2kyn4 -

RLVR Models Sacrifice Diversity for Base Model Preferences
By
–
RLVR'd model would fail to answer questions that its base model previously could. "The Invisible Leash: Why RLVR May Not Escape Its Origin" This research shows that RLVR just boosts the base model’s favorite answers (raising pass@1) and would sacrifice diversity.