Excited to host @jeffclune this Friday in our AI4Science Community! Open-Ended, Quality Diversity, and AI-Generating Algorithms in the Era of Foundation Models Join in the link below!
@askalphaxiv
-
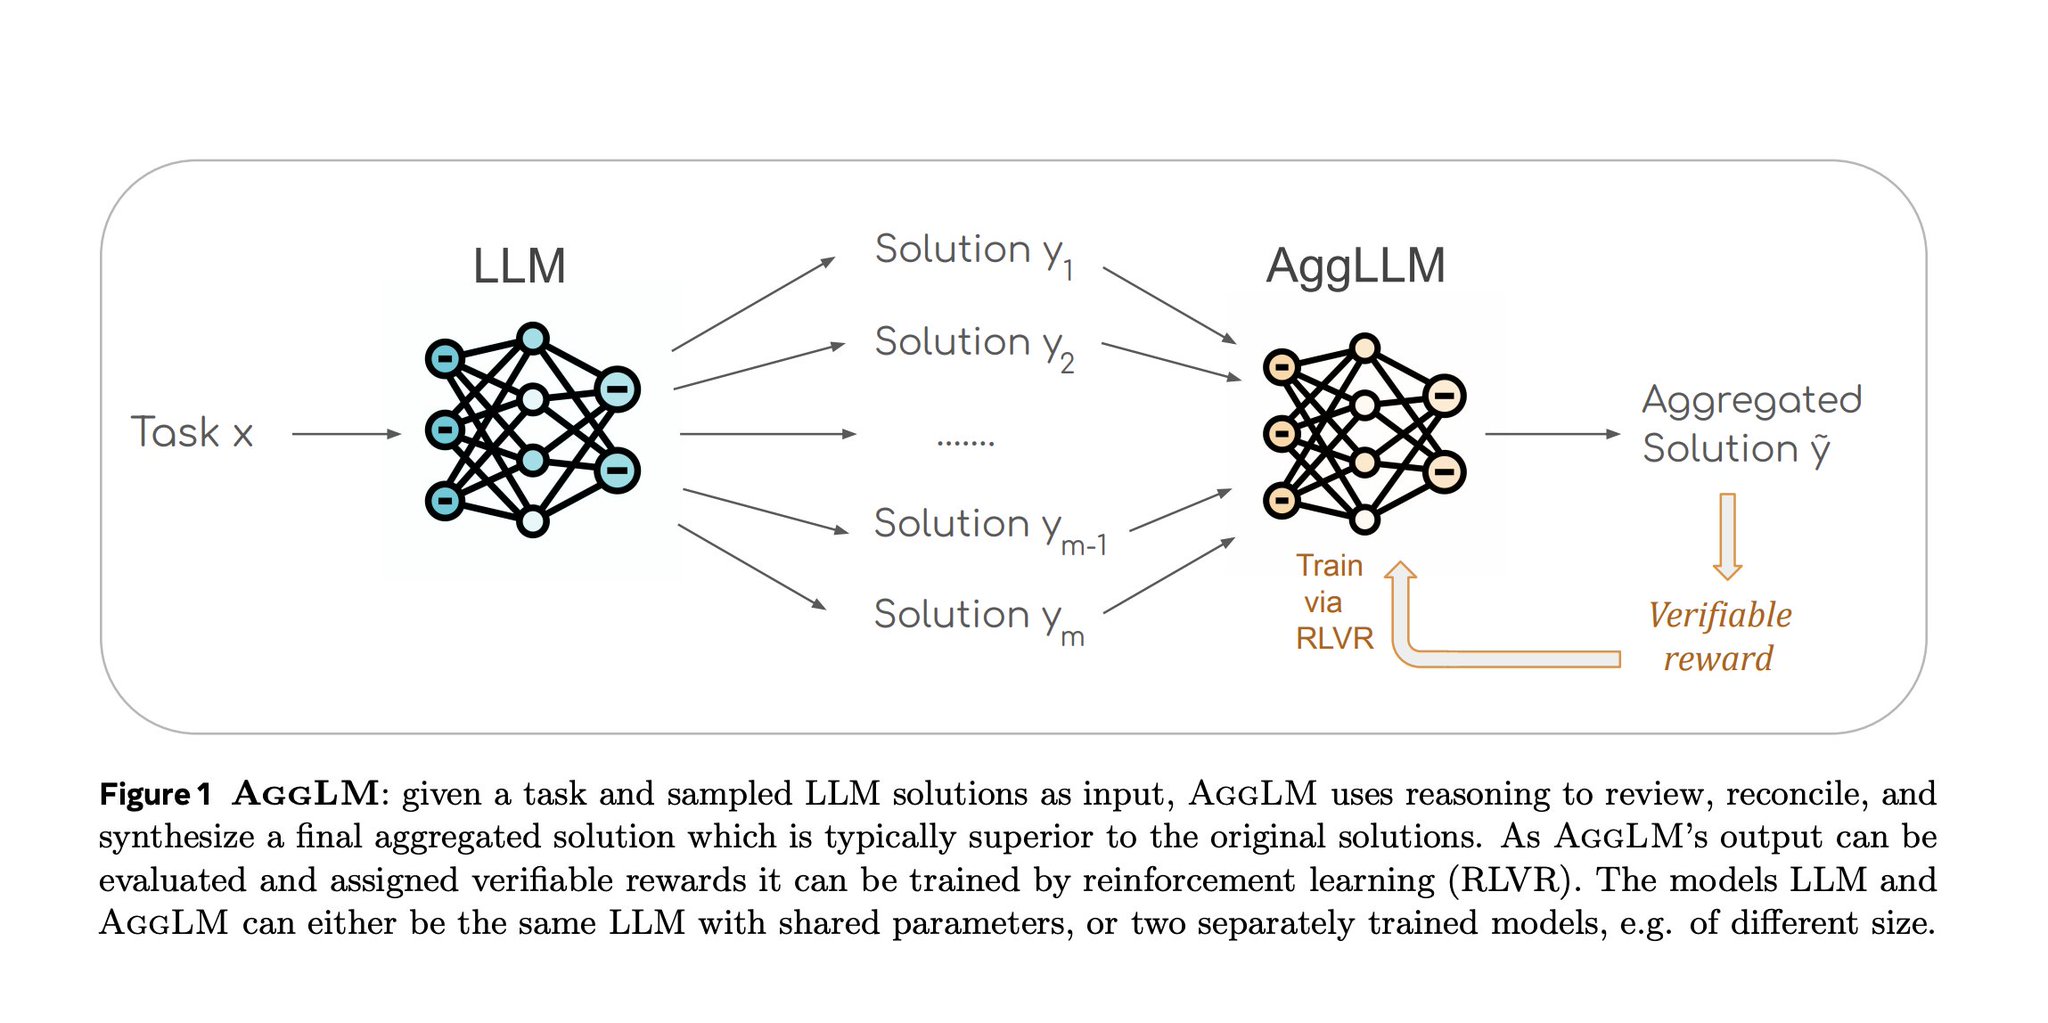
Meta FAIR Releases New Test-Time Compute Scaling Method for LLMs
By
–
Meta FAIR just released a brand new test-time compute scaling method! With their new LLM solution aggregator trained with RLVR, they showed that majority voting or reward model ranking aren’t actually the most efficient. This simple yet robust method outperforms RM baselines.
-
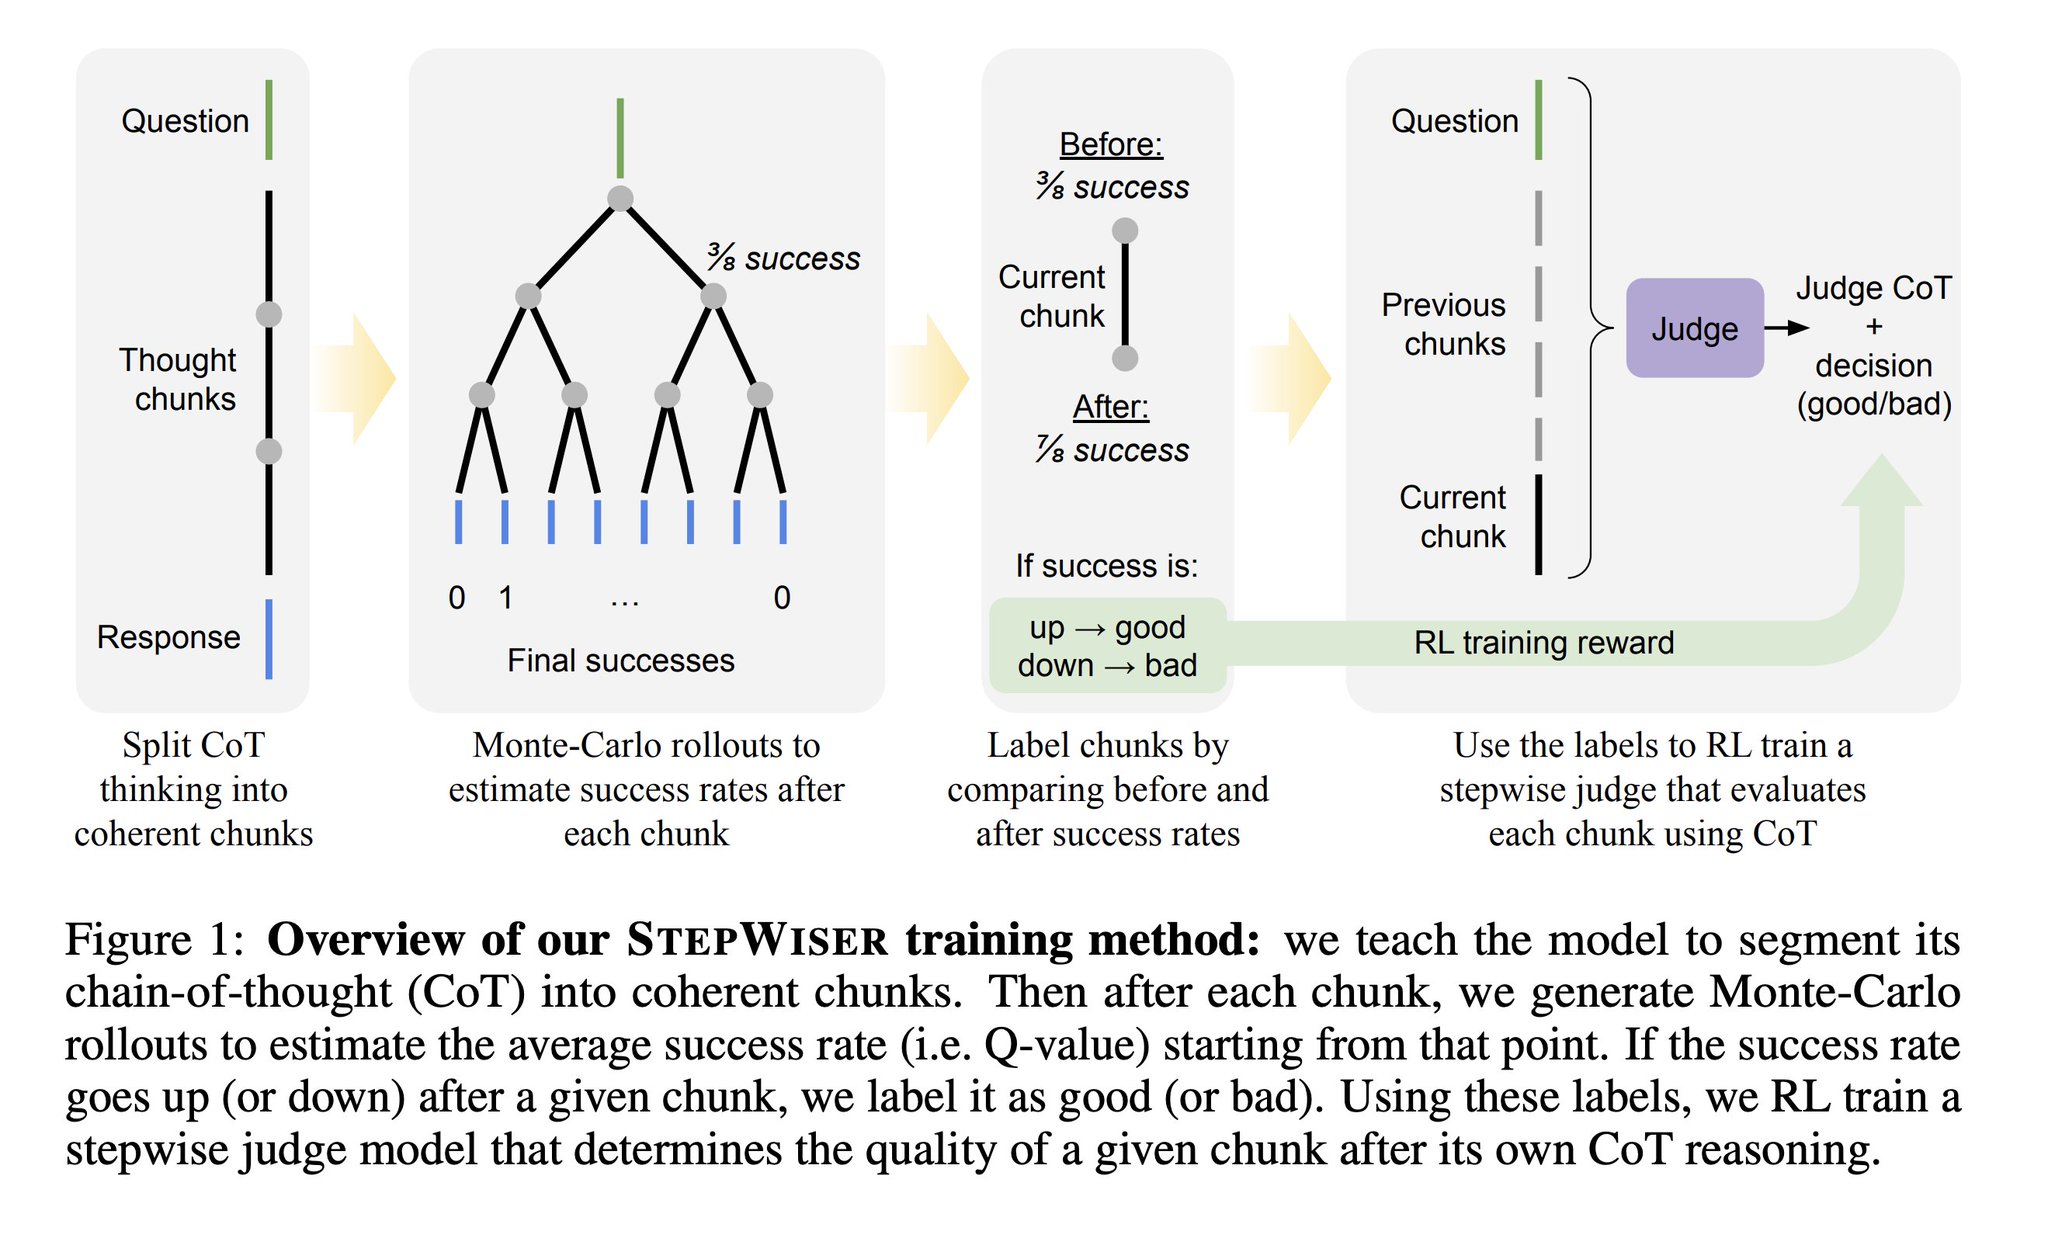
StepWiser: Stepwise Generative Judges for Wiser Reasoning
By
–
What if we apply RL+Reasoning into PRMs? StepWiser: Stepwise Generative Judges for Wiser Reasoning STEPWISER trains a CoT-based judge that checks whether each “chunk-of-thought” helps solve the problem, producing better step labels and stronger search than discriminative PRMs
-
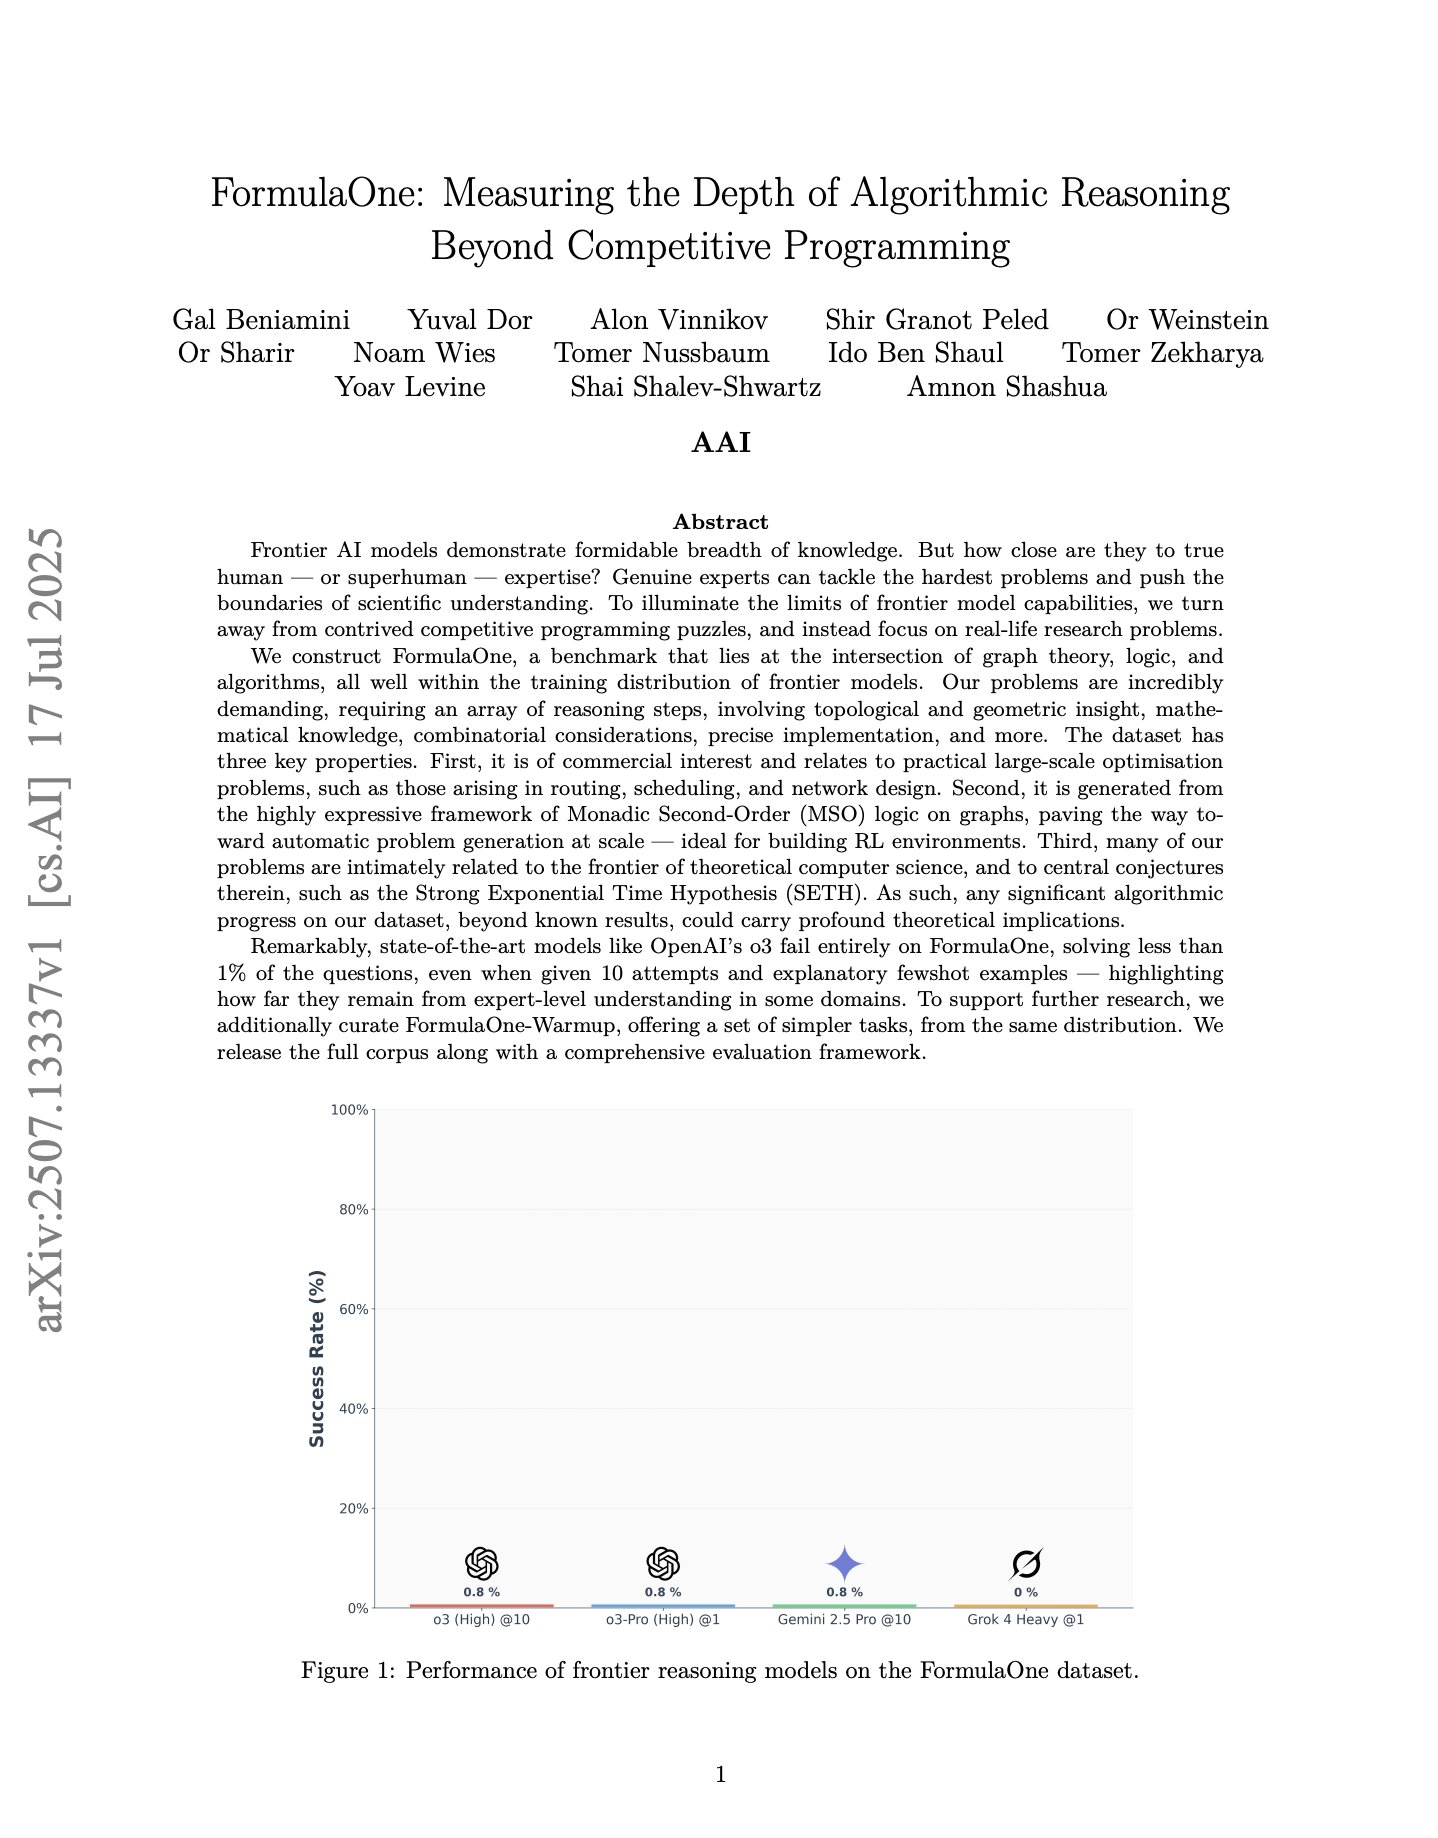
LLMs Struggle with PhD-Level Dynamic Programming Problems
By
–
Are LLMs truly capable of “PhD level” reasoning? FormulaOne: Measuring the Depth of Algorithmic Reasoning Beyond Competitive Programming Evaluated through PhD-level Dynamic Programming problems, and spoiler alert, AI code-solvers are only able to get under 1% right (for now…?)
-
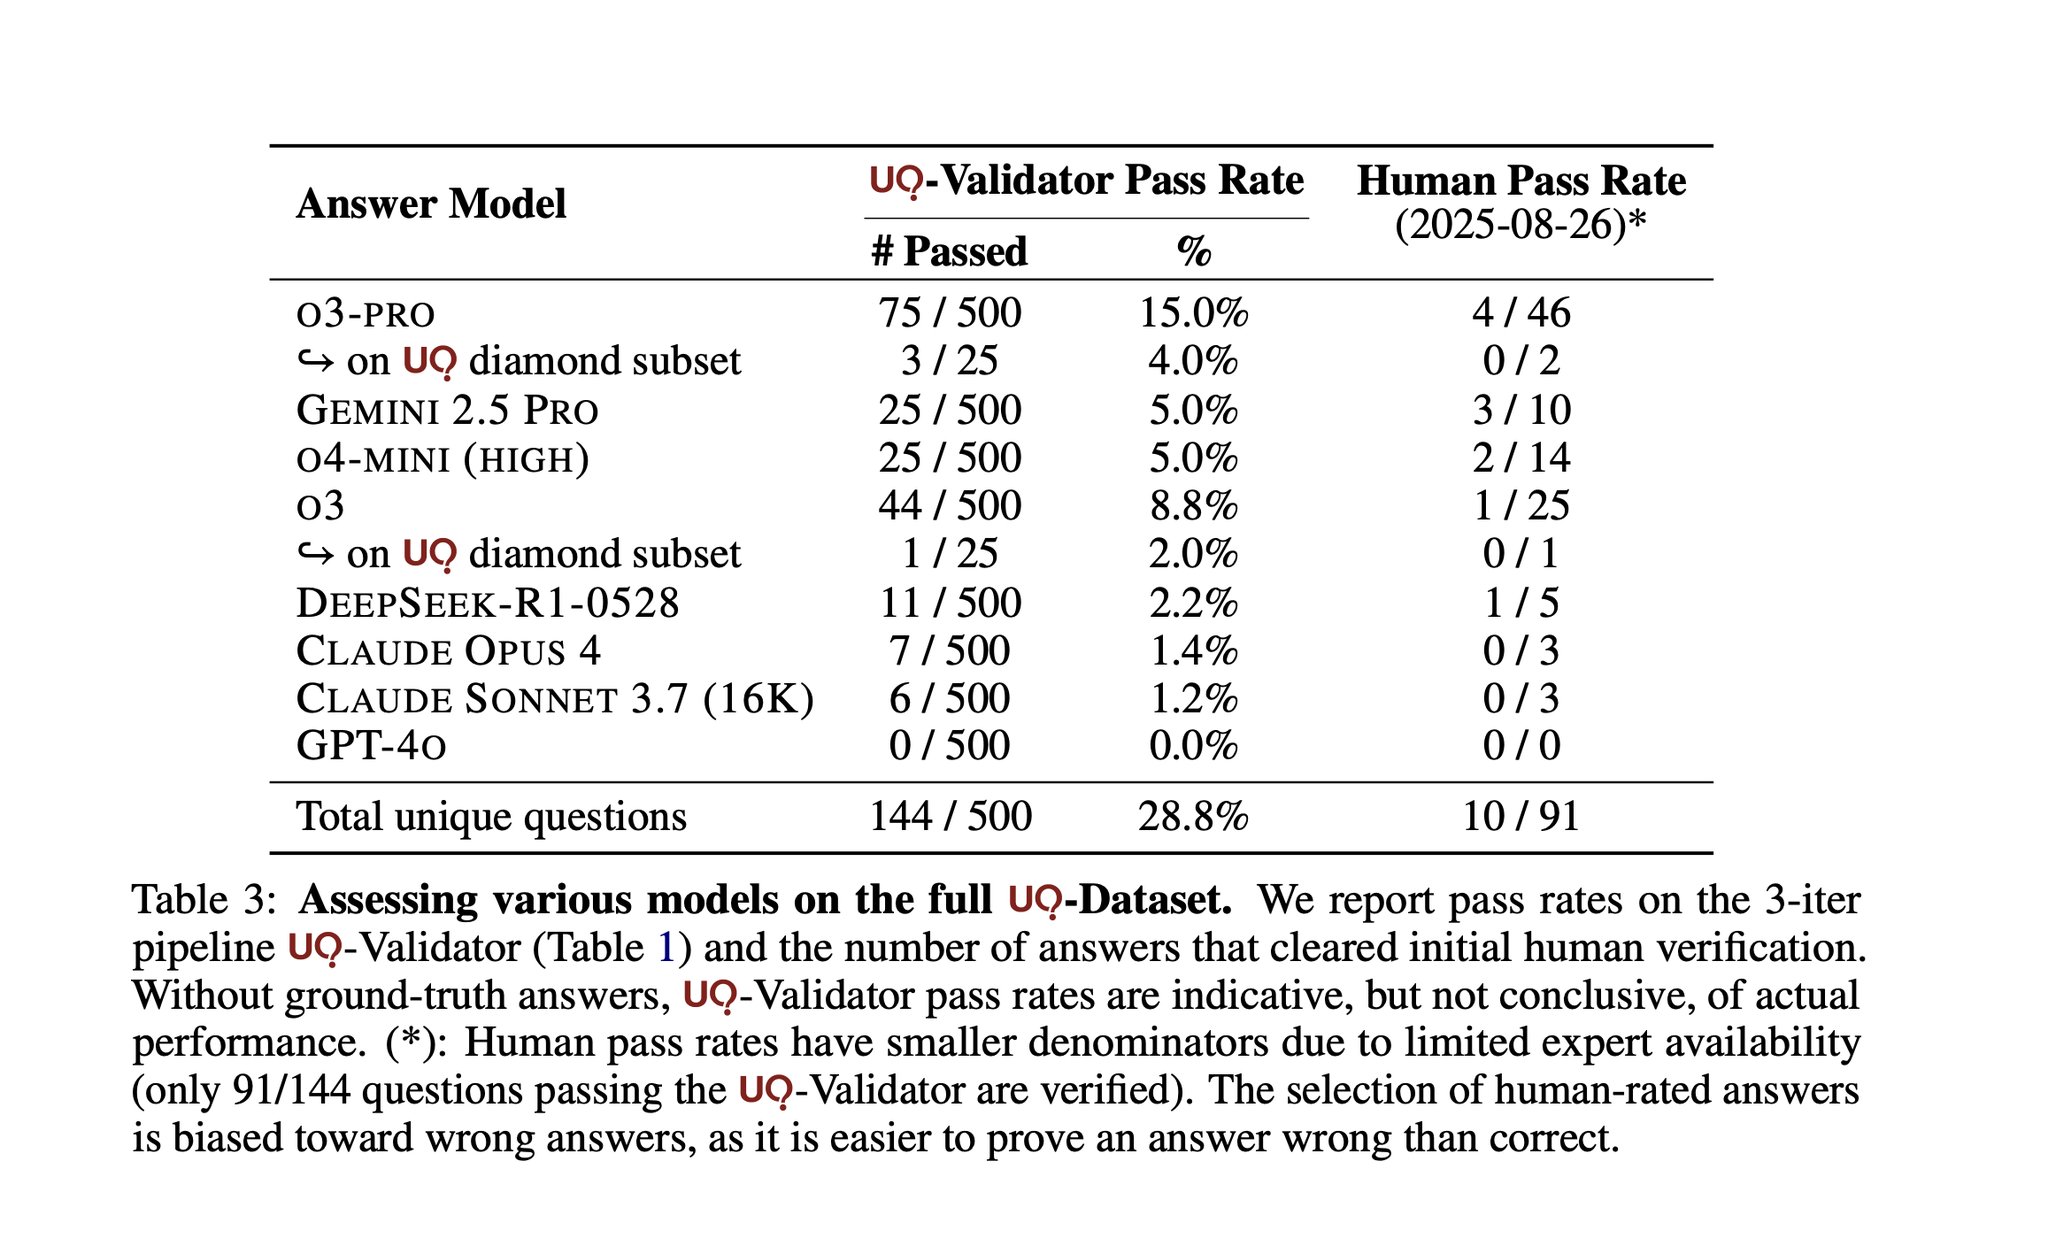
LLMs Solve Only 2% of Unsolved Scientific Questions
By
–
UQ: Assessing Language Models on Unsolved Questions This research assessed LLMs on actual unsolved questions & not benchmarks, with today’s best model only able to solve 10/500 questions!
-
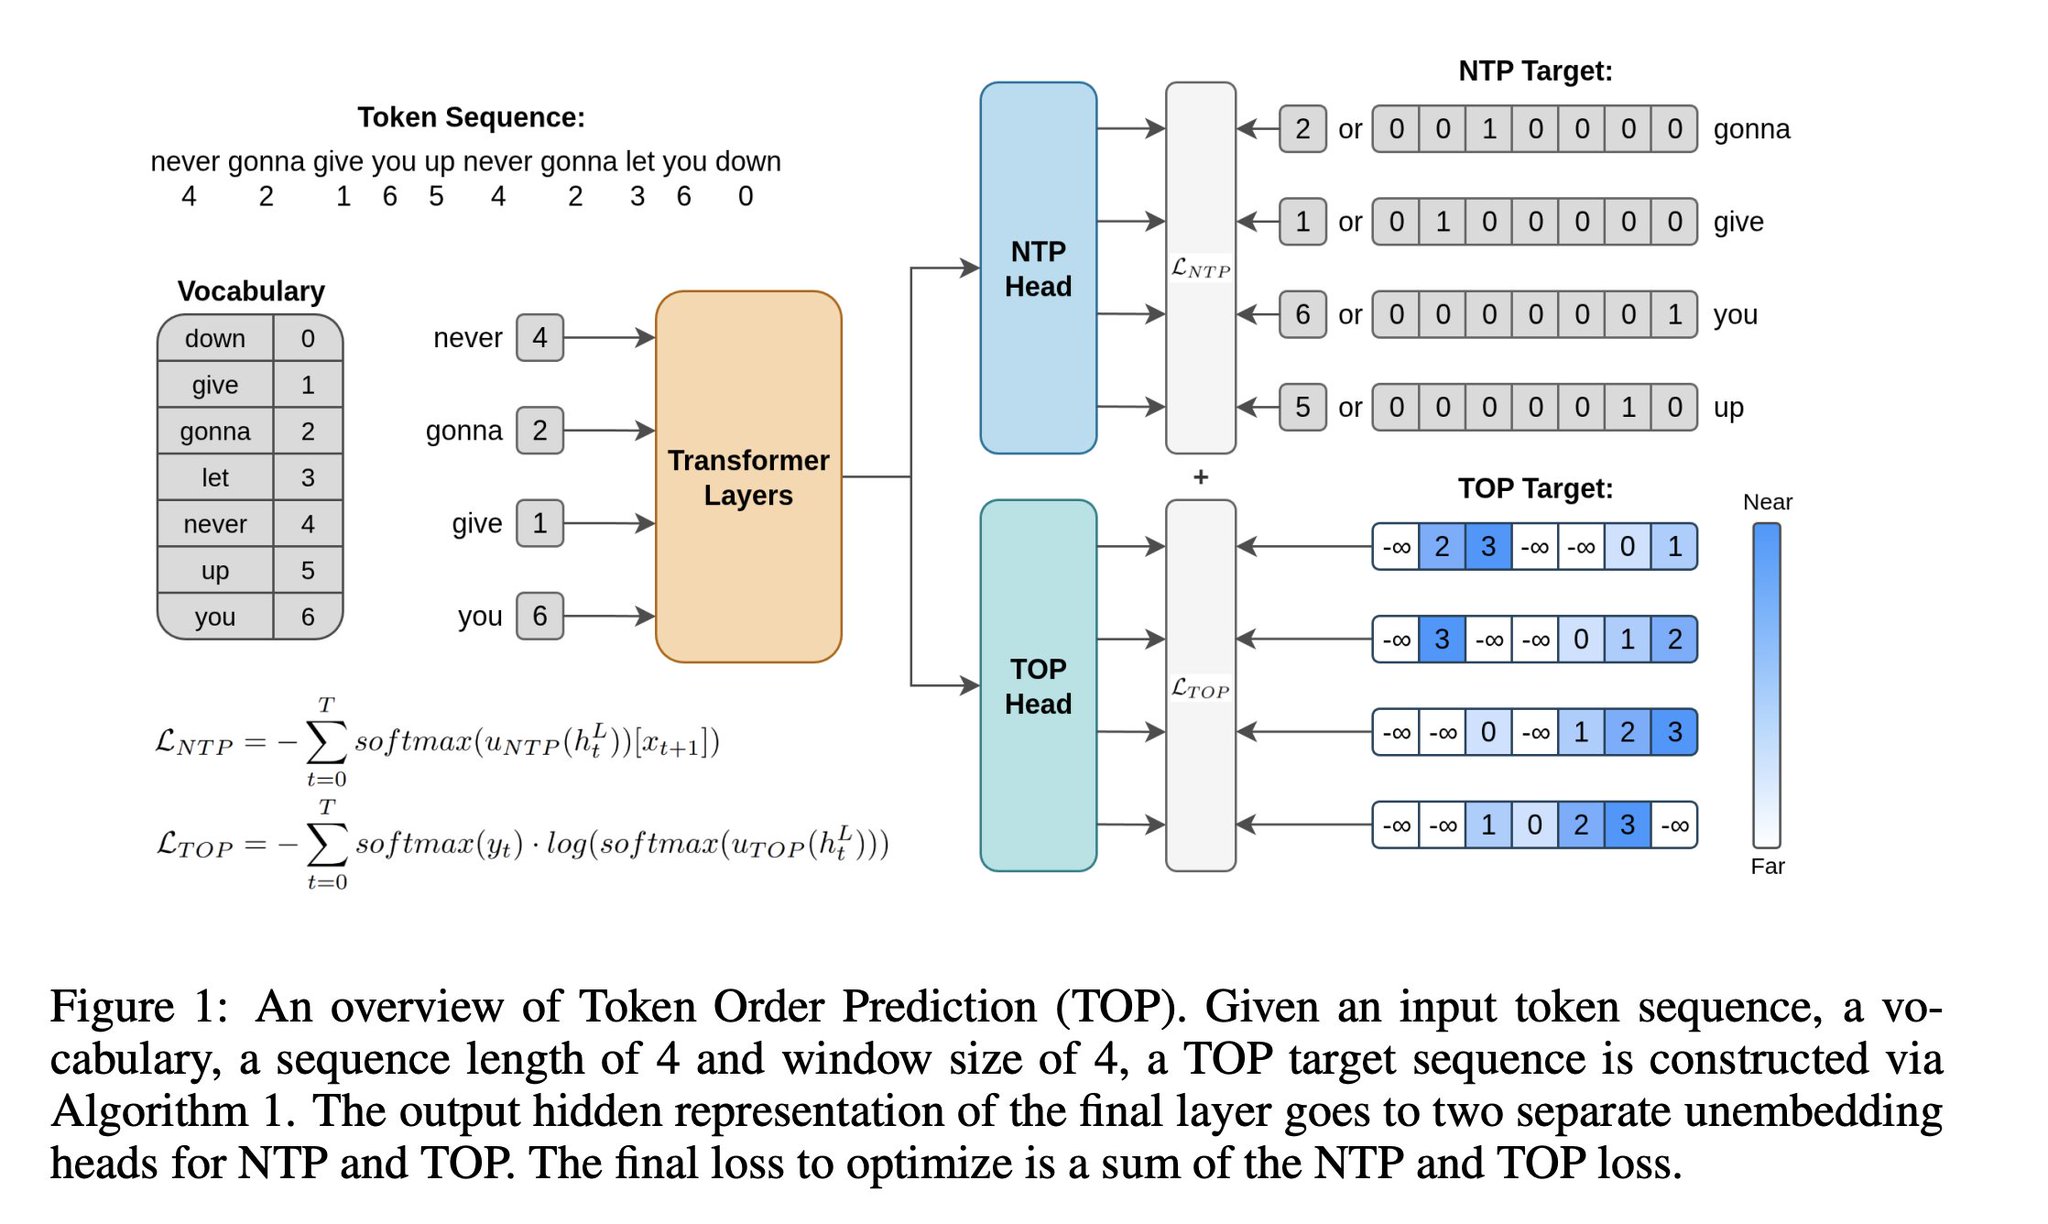
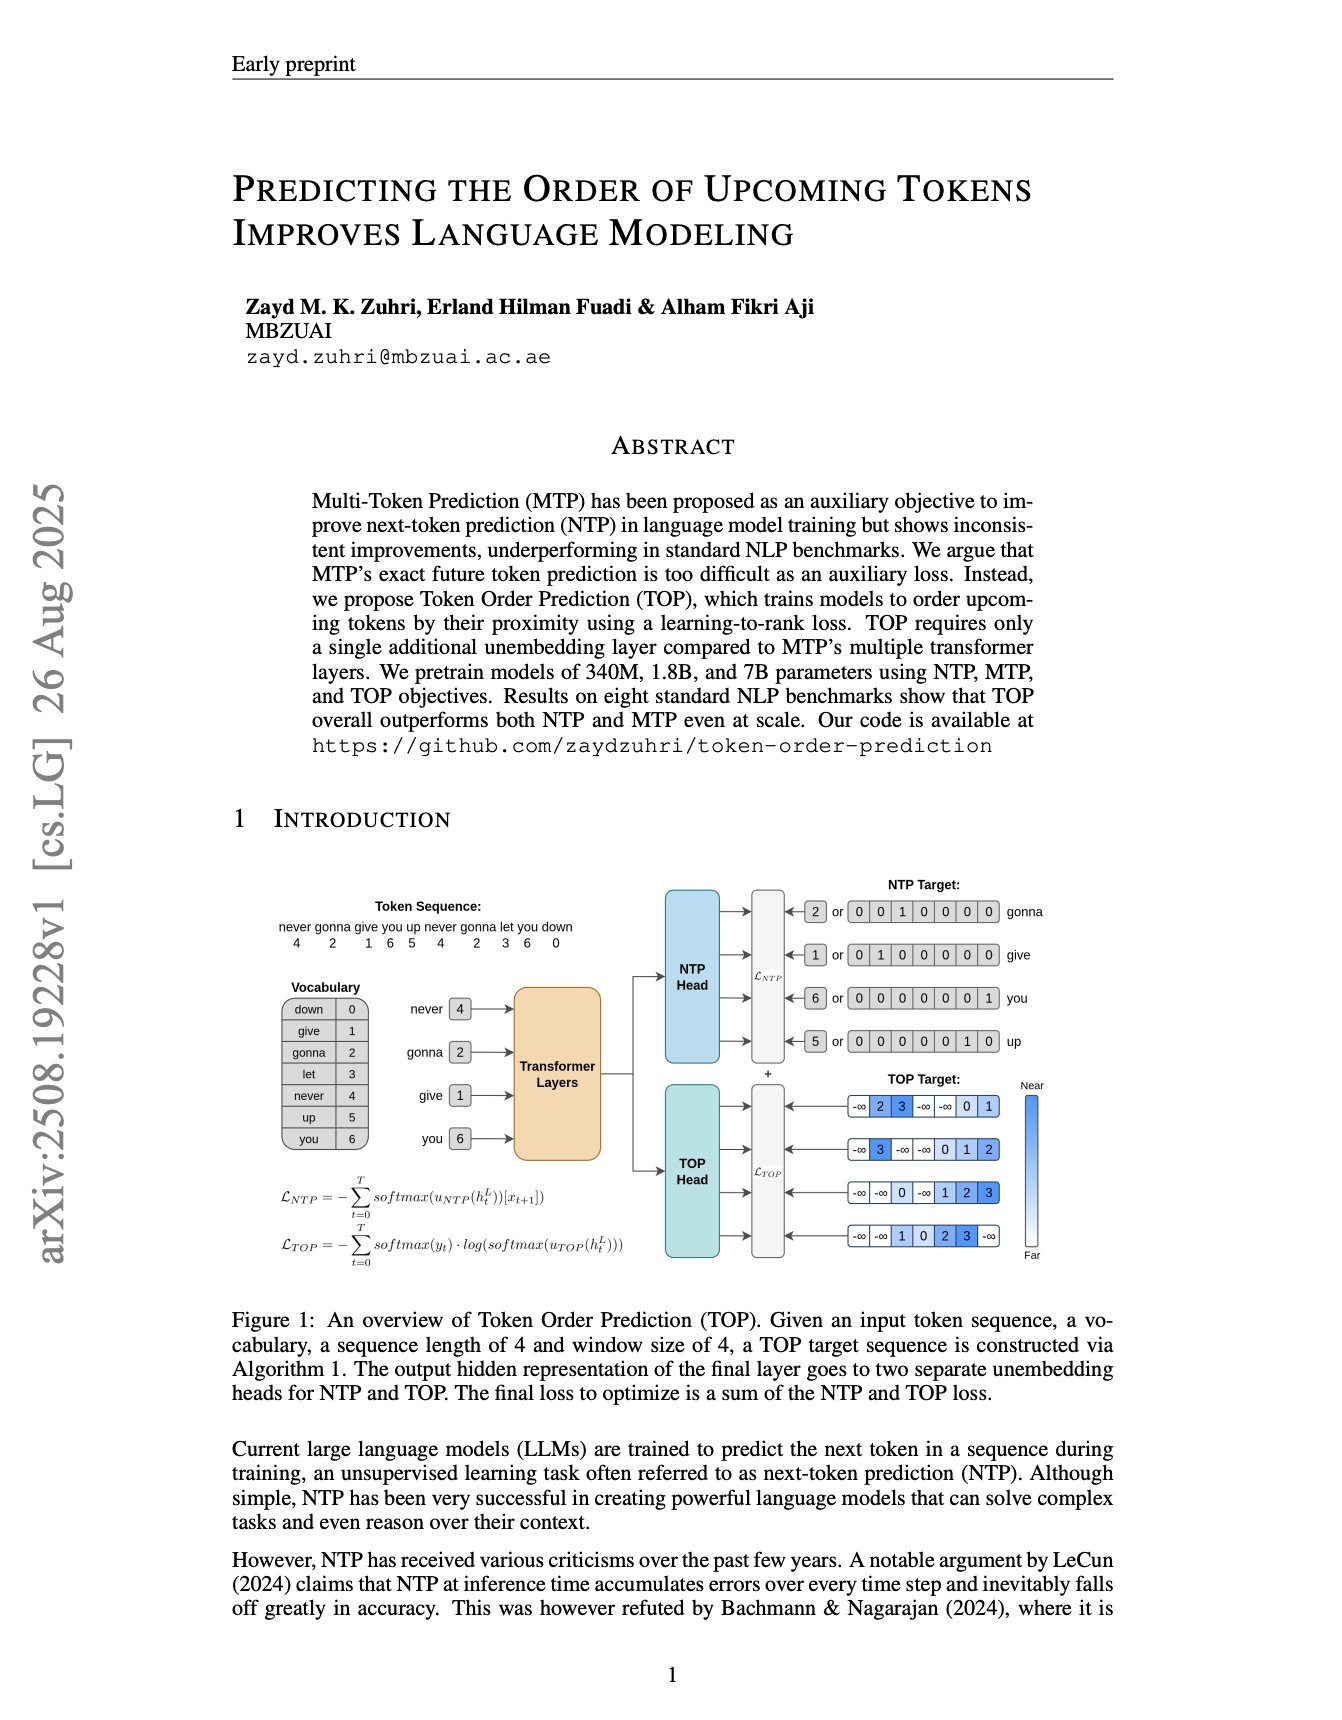
Token Order Prediction Improves Language Model Pre-training
By
–
A better auxiliary LLM pre-training objective just dropped! Predicting the Order of Upcoming Tokens Improves Language Modeling Teach the model to rank which words are likely to come sooner vs later instead of guessing future words makes LLMs better with minimal overhead
-
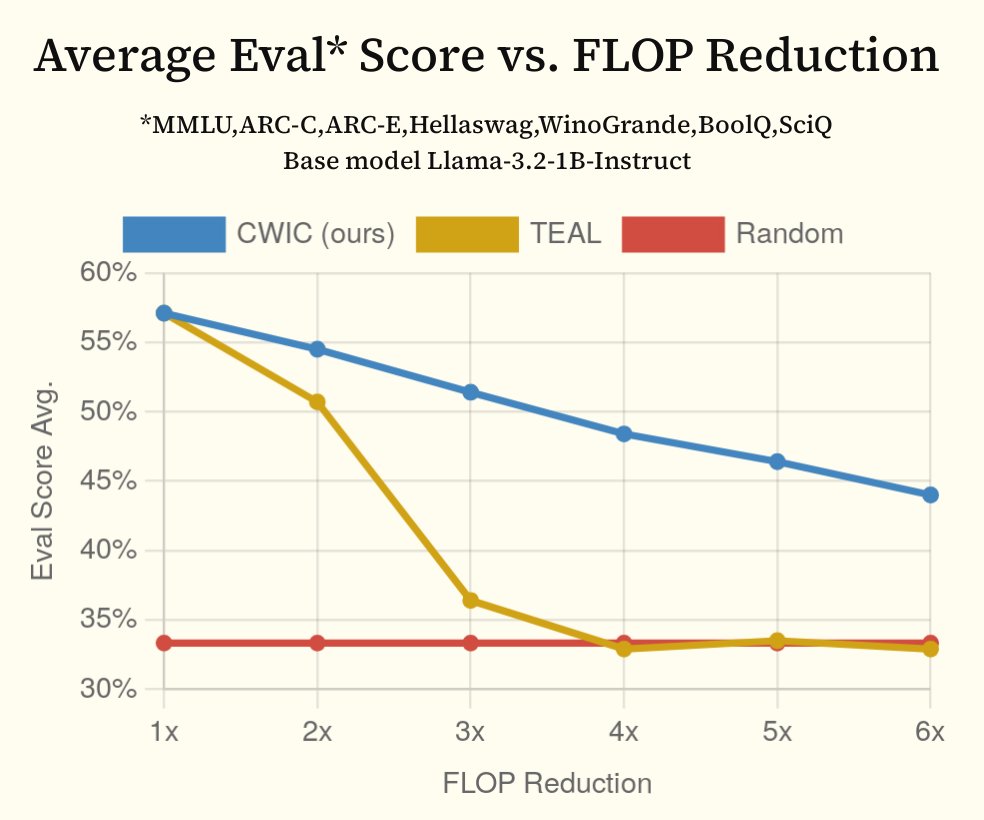
Model-Driven FLOP Allocation Achieves 80% Sparsity, 4x CPU Speedups
By
–
What happens when you let a model decide how to allocate FLOPs? Introducing Compute Where It Counts, a new trainable sparsity paradigm released by @crystalAIorg that beats SOTA methods, enabling 80% sparsity and 4x+ speedups on CPU.
-
V-JEPA 2 Learns World Models from Million Hours Video
By
–
internet videos to robot actions? @AIatMeta
's V-JEPA 2 learns a world model from over 1 million hours of video, enabling it to perform complex, real-world robotic tasks zero-shot. Join author Nicolas Ballas for a talk on V-JEPA 2 this Friday! -
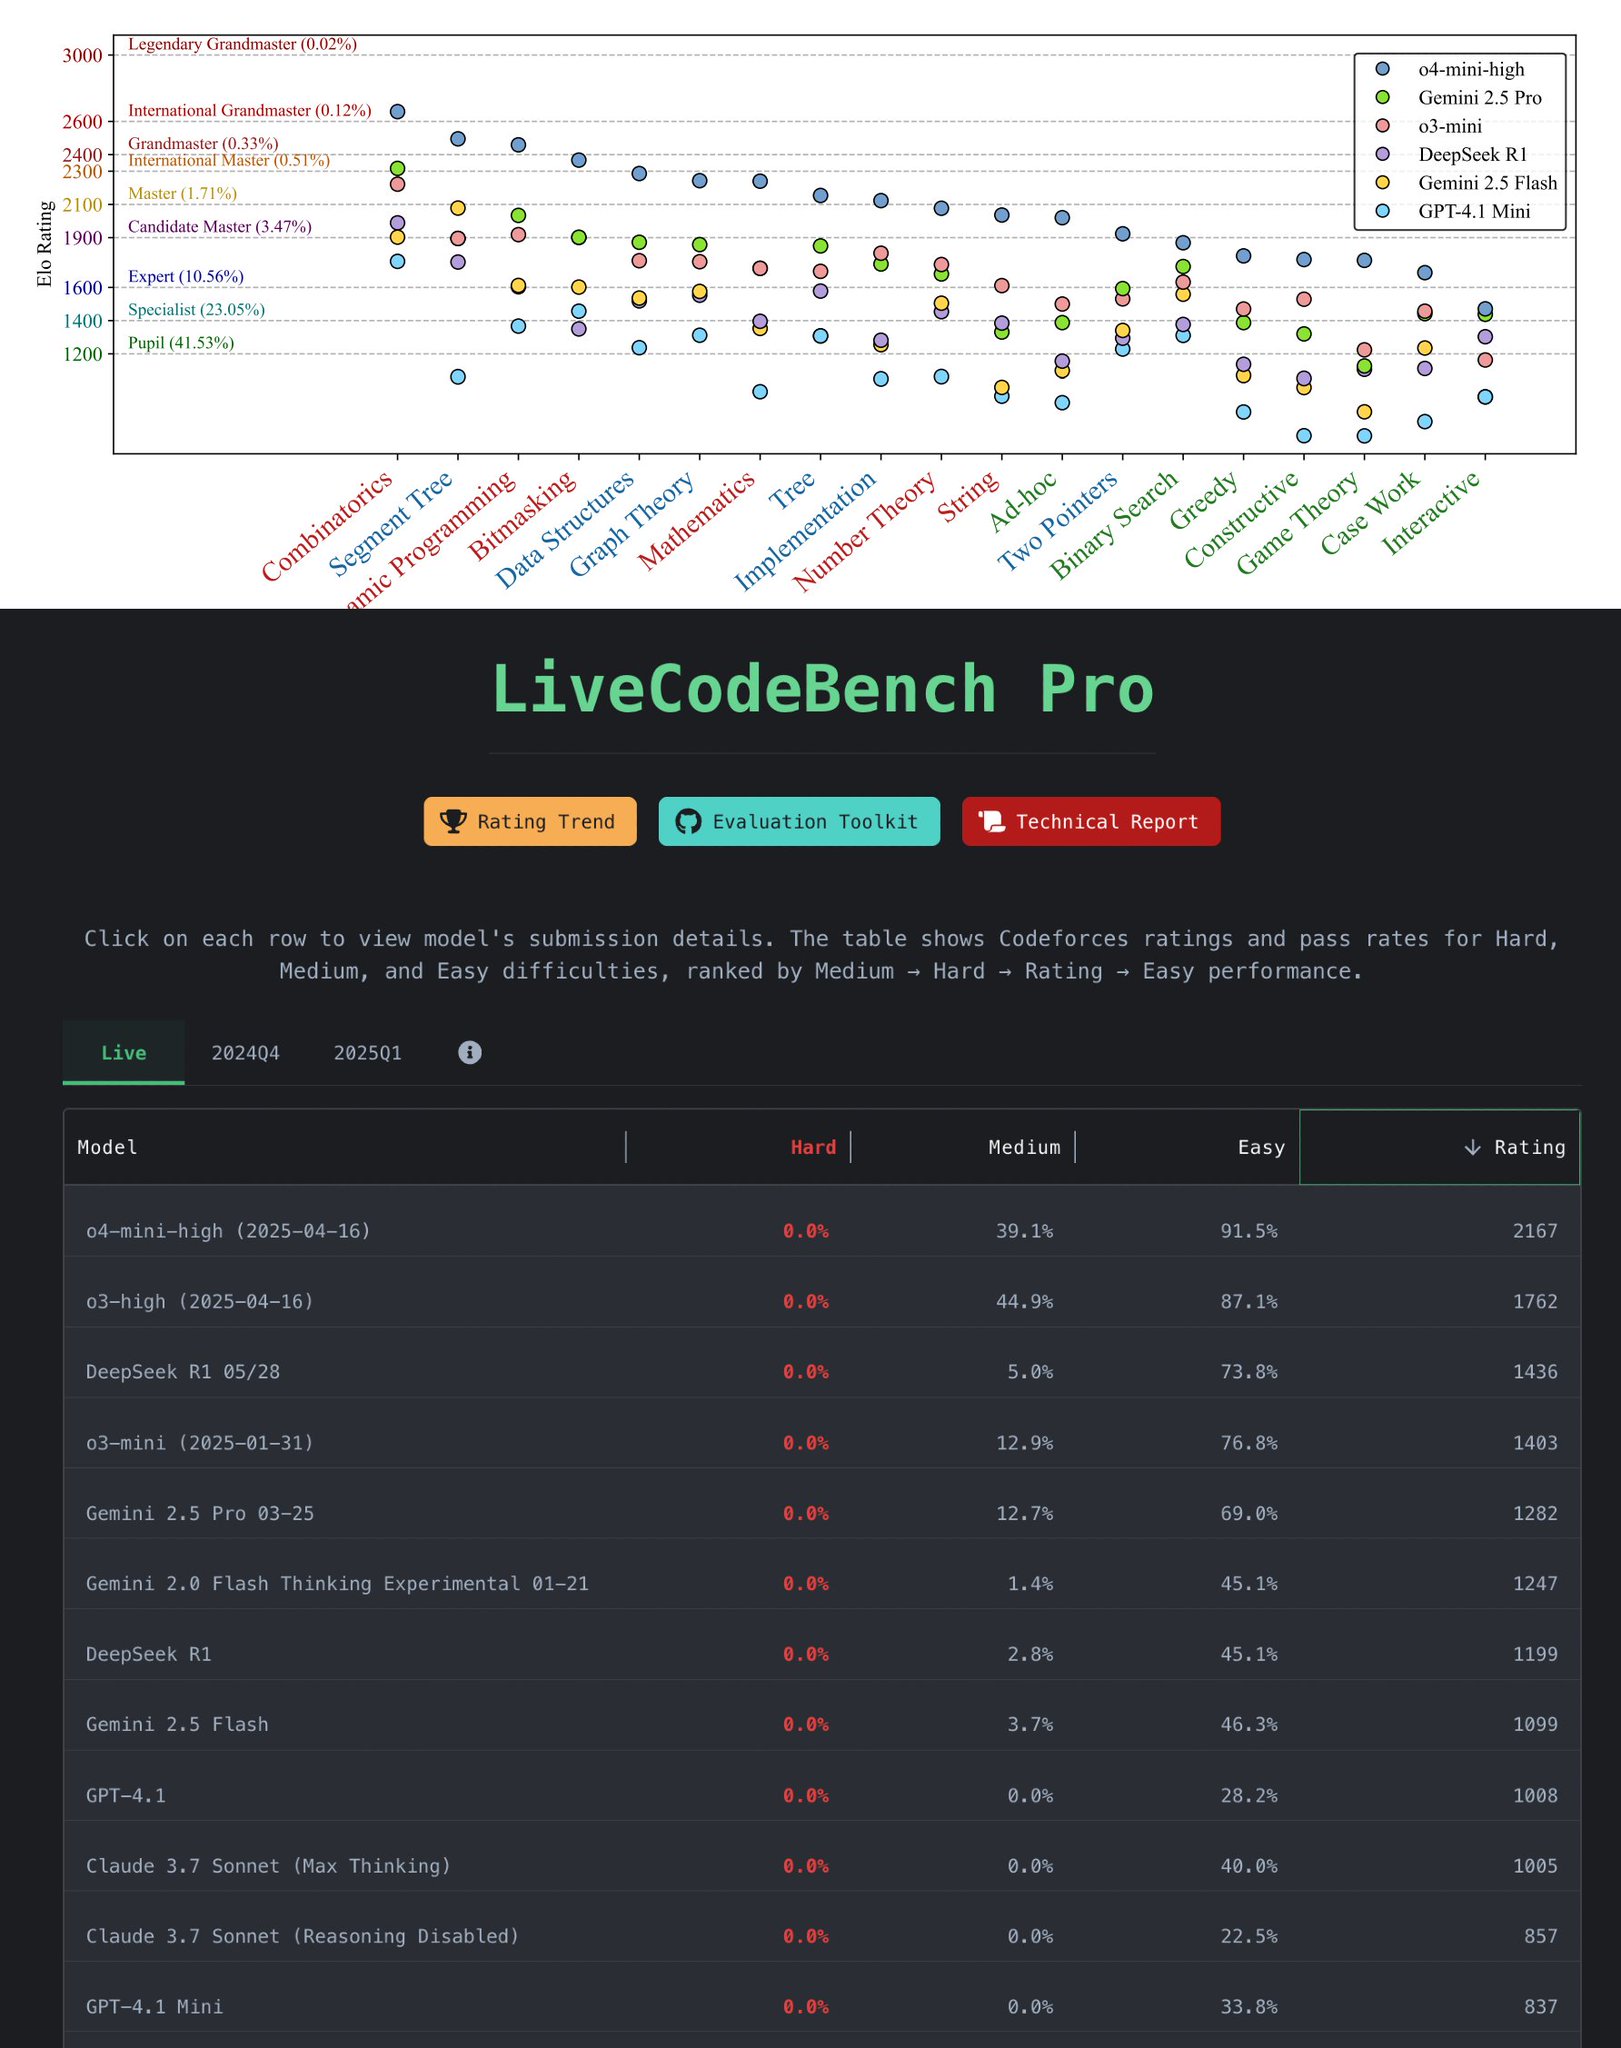
Top LLMs Fail on Hard Coding Problems: LiveCodeBench Pro
By
–
Why do top LLMs fail completely on hard coding problems? We'll have author Peiyao Shang from @SentientAGI discussing their work on the LiveCodeBench Pro benchmark. Join us this Friday! https://
lu.ma/v45b9ltc