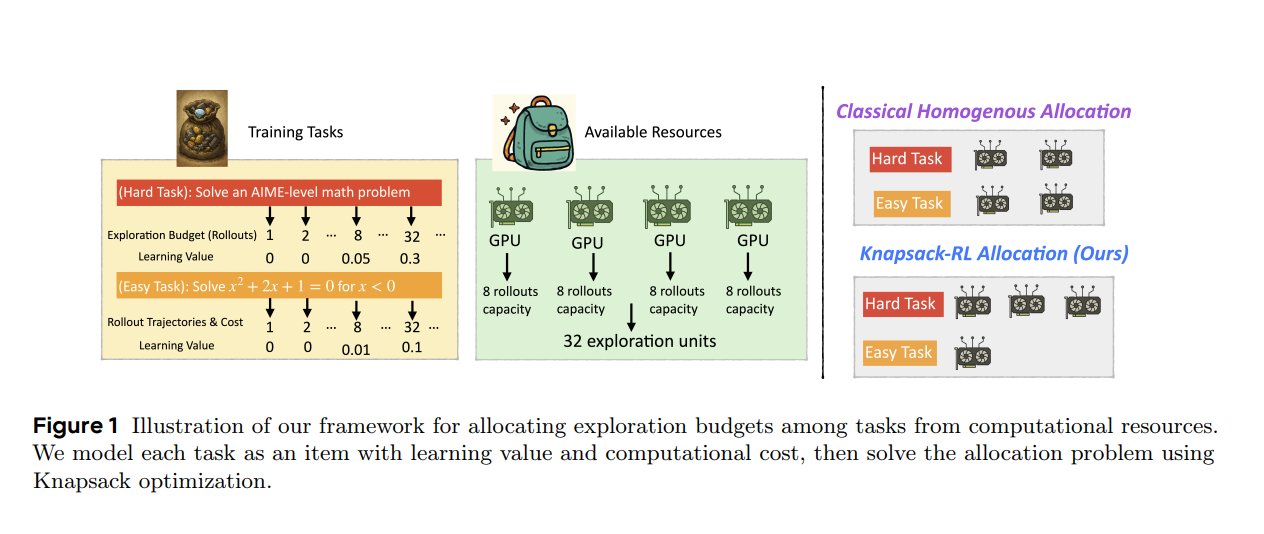
Following an intense weekend of GRPO discussion, Bytedance put out a paper on why GRPO is NOT optimal! Similar to the classic knapsack problem, they suggest that each exploration has a “value” and “cost”, which needs to be adaptively distributed. This yields 20-40% more signal
@askalphaxiv
-
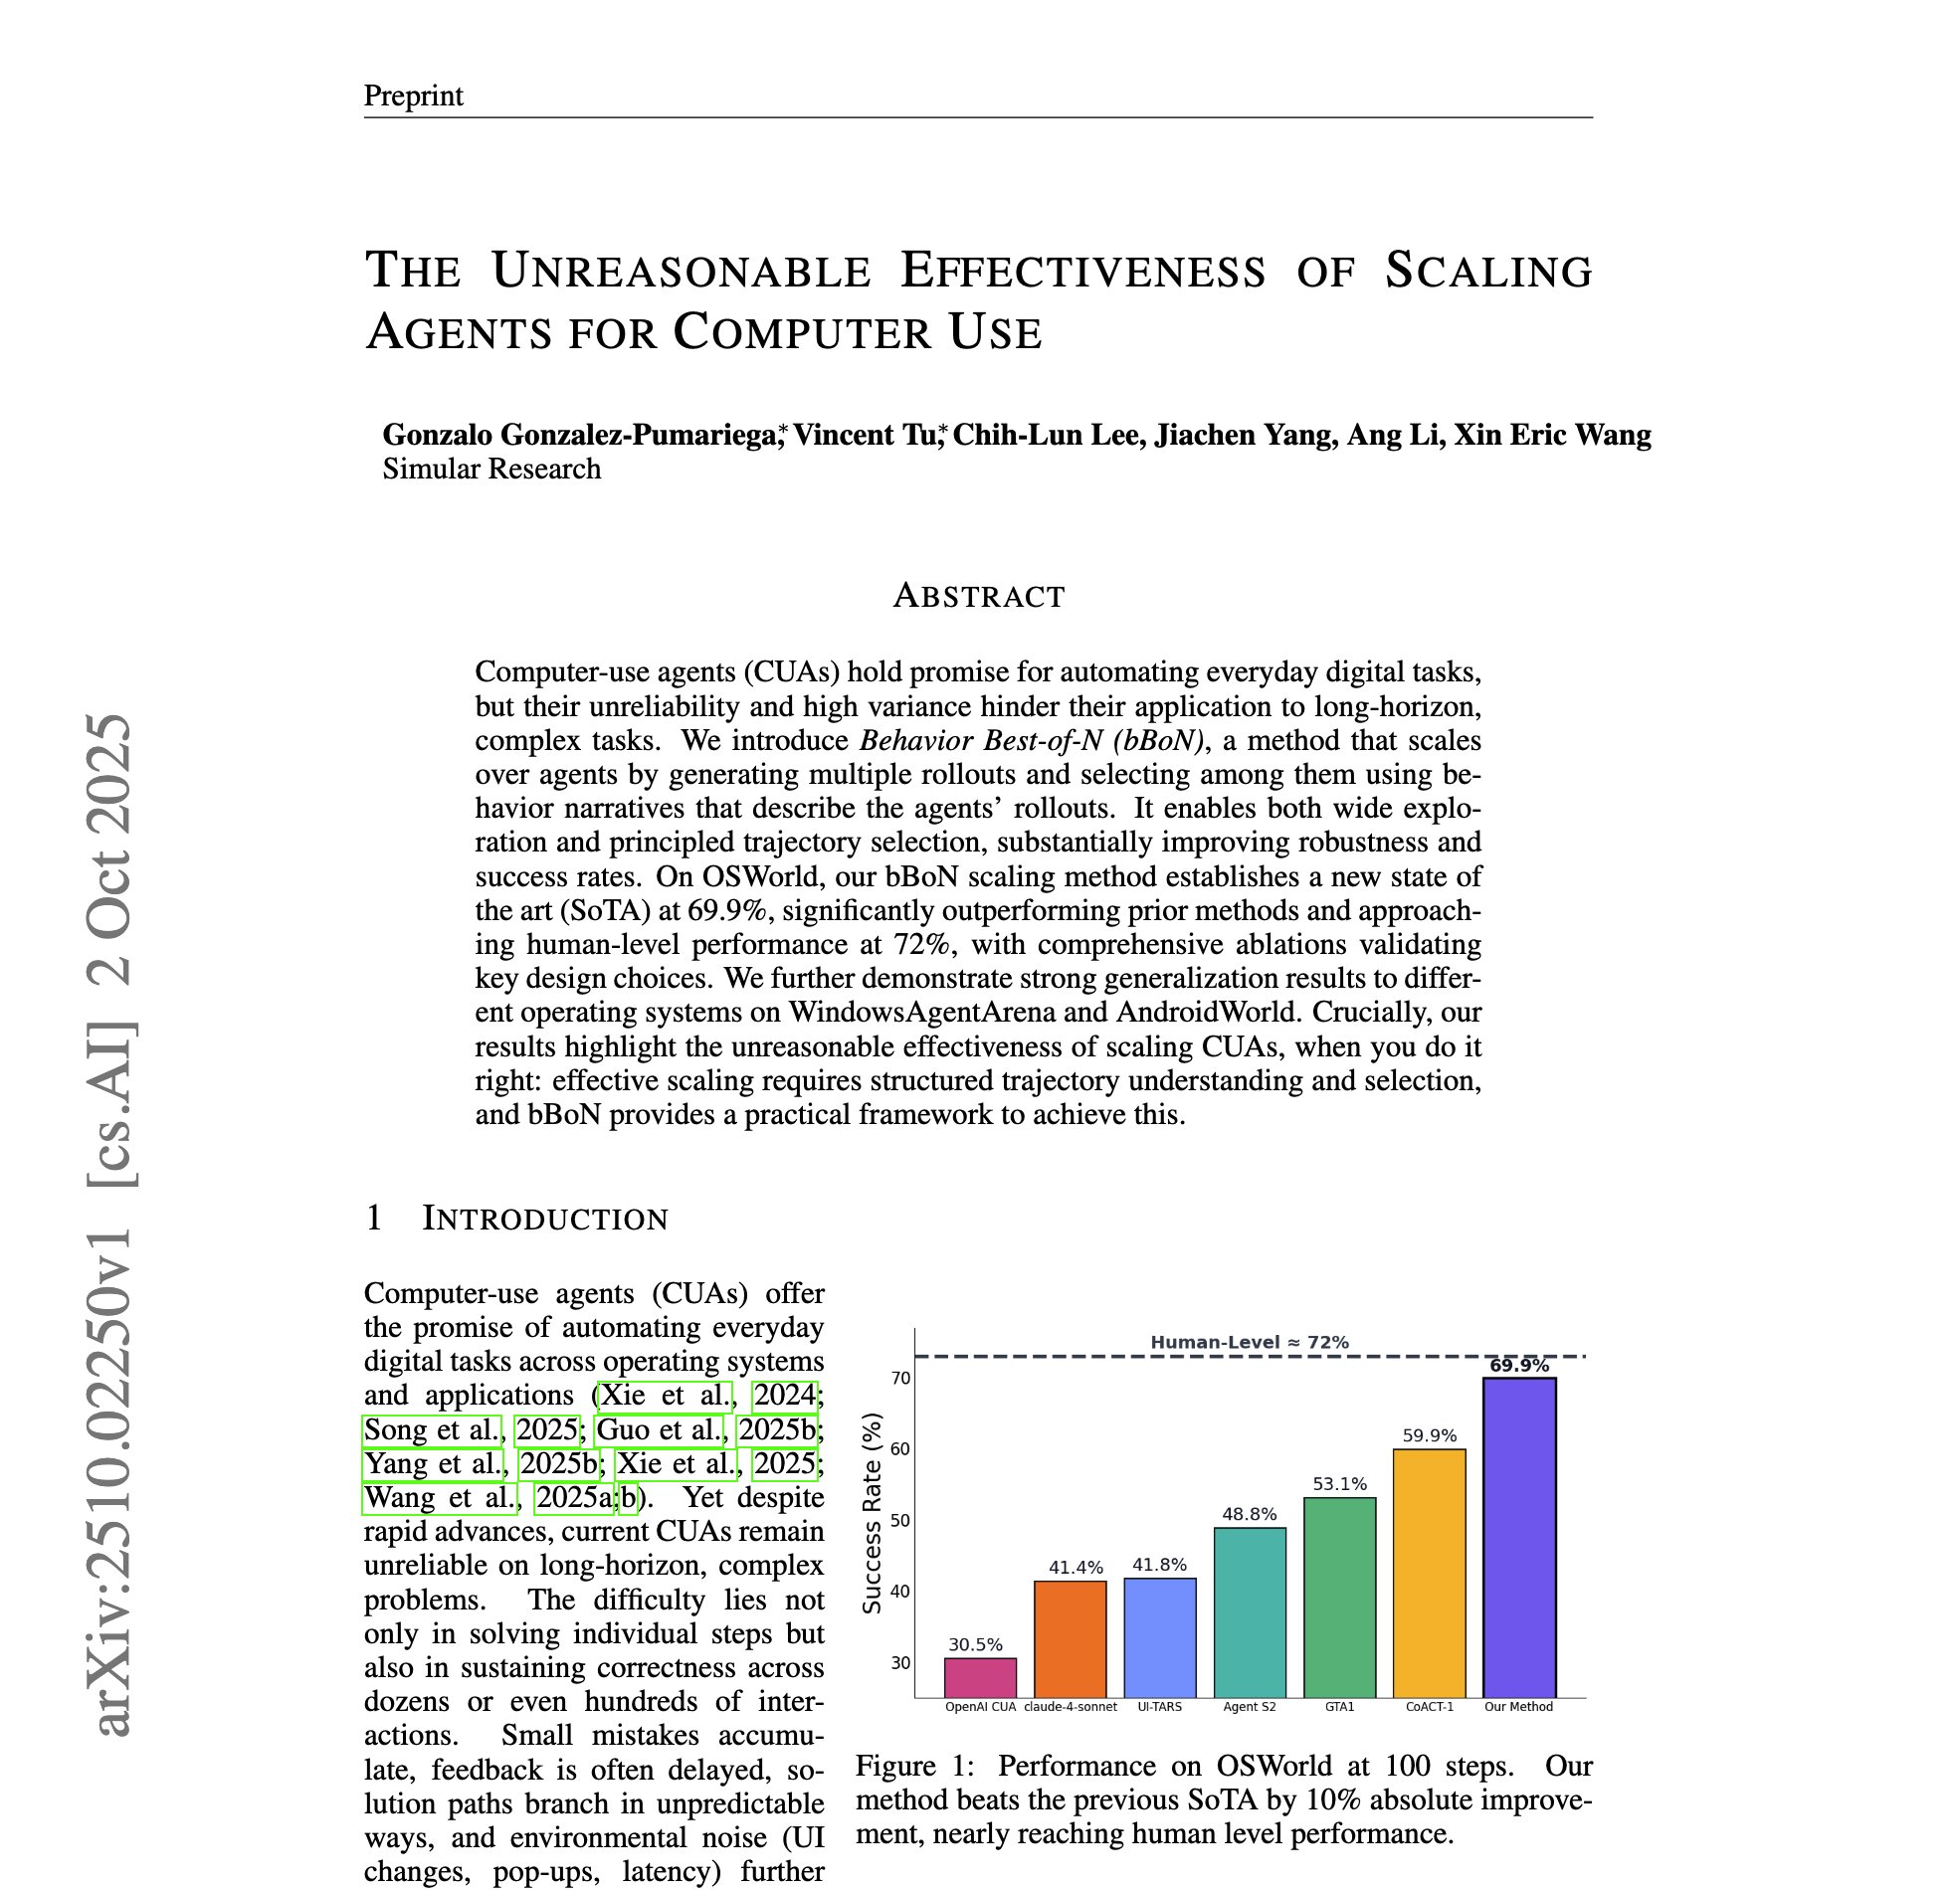
Scaling Parallel Agents for Computer Use Tasks
By
–
what if we stopped betting everything on one agent rollout? "The Unreasonable Effectiveness of Scaling Agents for Computer Use" Generates multiple trajectories in parallel & selects the best using "behavior narratives" 69.9% on OSWorld, nearly matching human-level 72%
-
New AI Evals Community Launches Research Discussion Platform
By
–
If you're interested in research and developments on AI evals, join our new AI Evals community! We'll be working with @valsai to host discussion and talks from the researchers behind influential papers and benchmarks. For the the first talk, the community is hosting
-
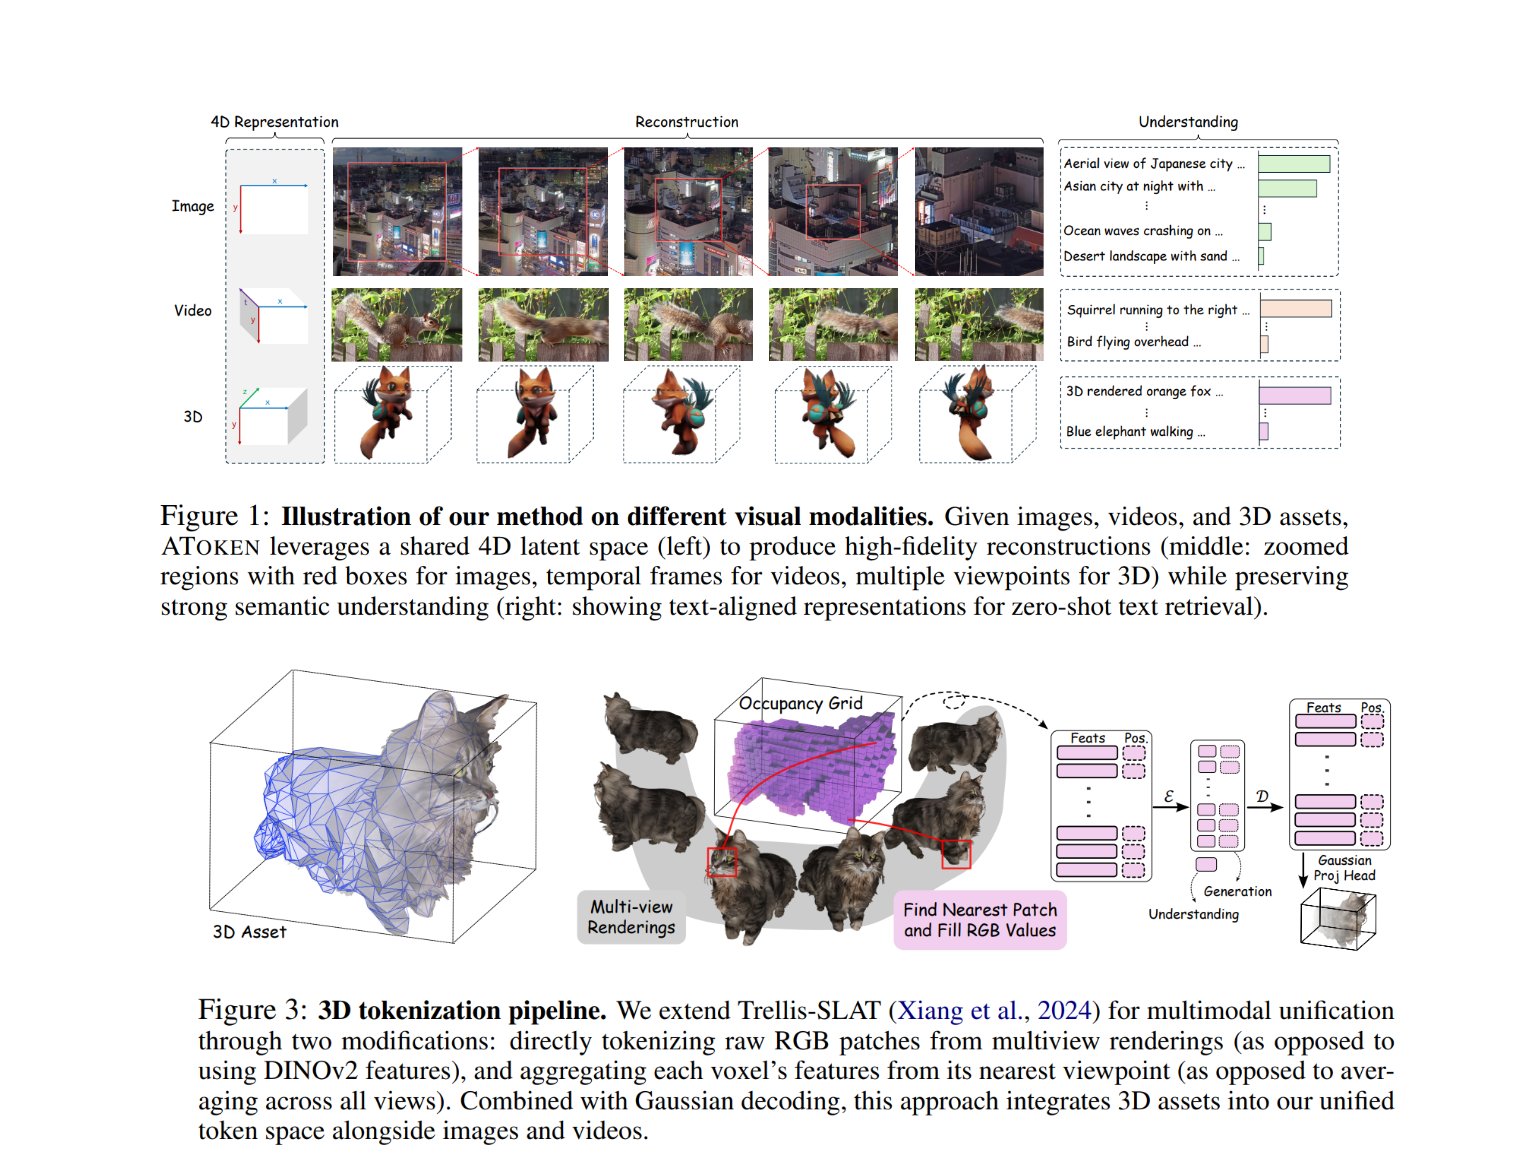
Apple Unveils ATOKEN: Unified Visual Tokenizer for Multimodal Content
By
–
Apple just proposed the first unified visual tokenizer! They proposed ATOKEN which is the first tokenizer that jointly cover images, videos, and 3D assets in a single shared 4D latent/token space, matching performance with any other specialized tokenizers.
-
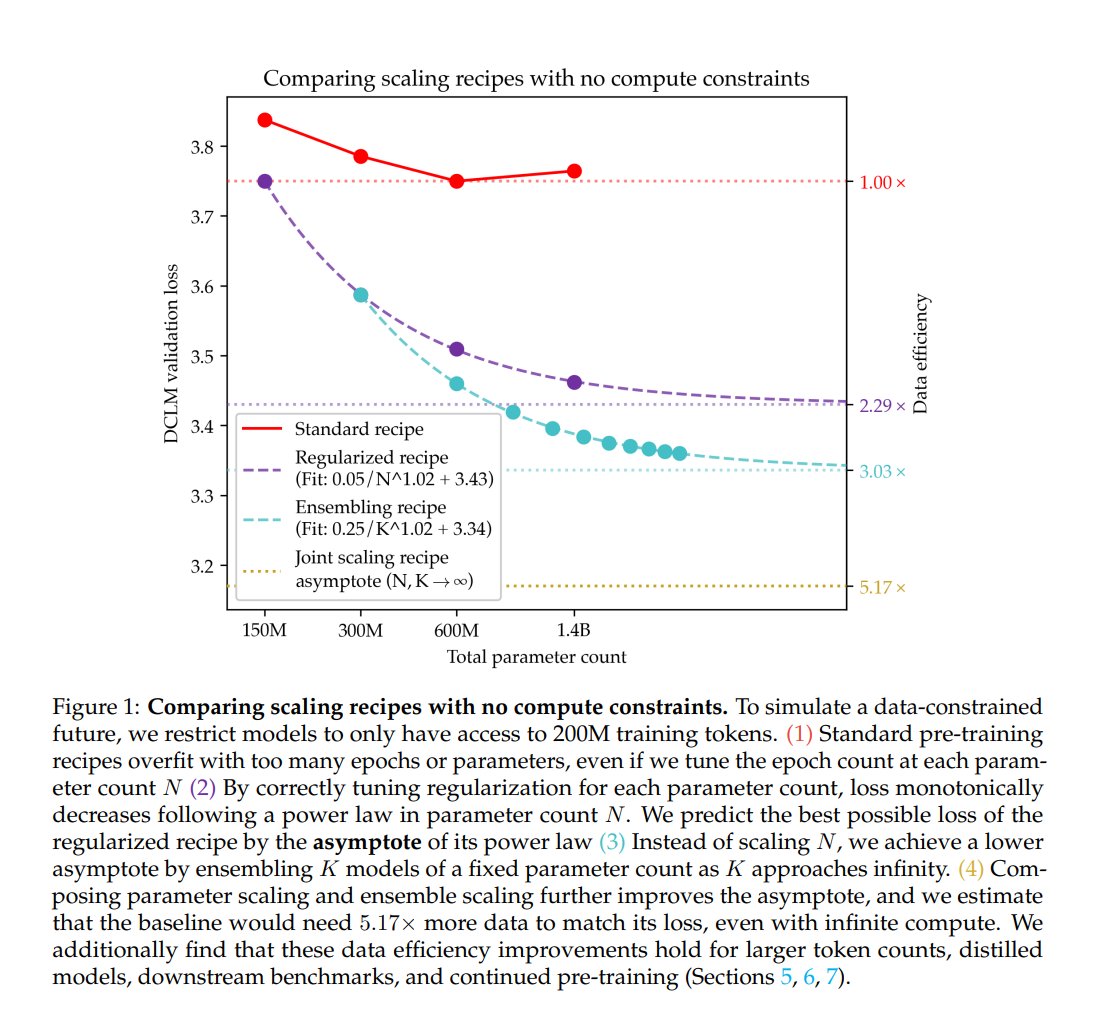
Scaling Language Models with Infinite Compute via Ensemble Distillation
By
–
As data and compute scales differently, what do we do when we have infinite compute? To answer this, this paper shows you can still scale LMs by cranking up regularization, training many small clones on the same corpus, then ensemble → distill, netting 5x data-efficiency
-
Chrome Extension Enables Direct alphaXiv Access from arXiv Papers
By
–
Check out our Chrome extension here! It'll automatically allow you to navigate to alphaXiv for every arXiv paper.
-
Google Breakthrough in Fluid Dynamics Using Neural Networks
By
–
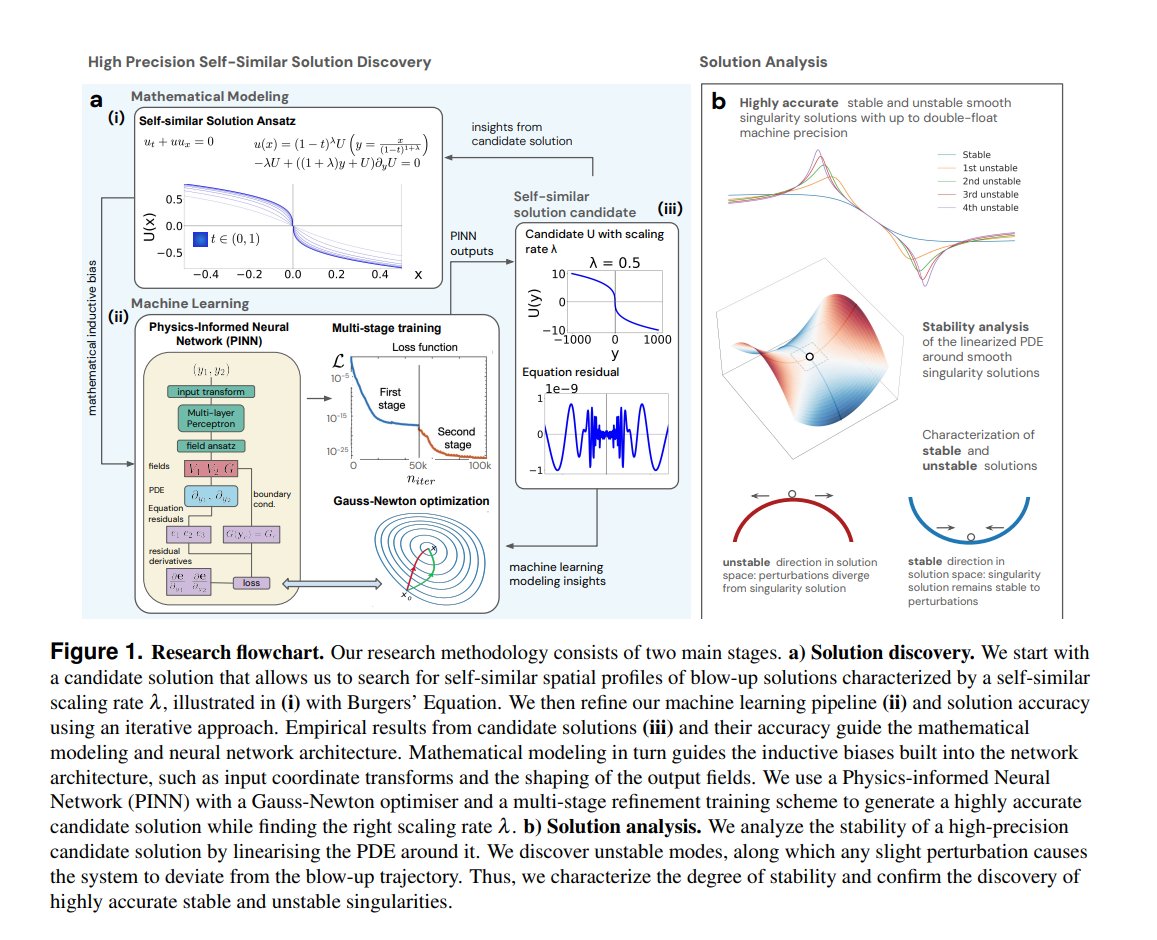
Google just made a huge fluid dynamics breakthrough They discovered new solutions to century-old problems where fluid motion would break unexpectedly creating “singularities” Their framework combines neural nets & high-precision optimization to uncover unstable singularities
-
Reverse-Engineering Thought Chains Improves LLM Reasoning Capabilities
By
–
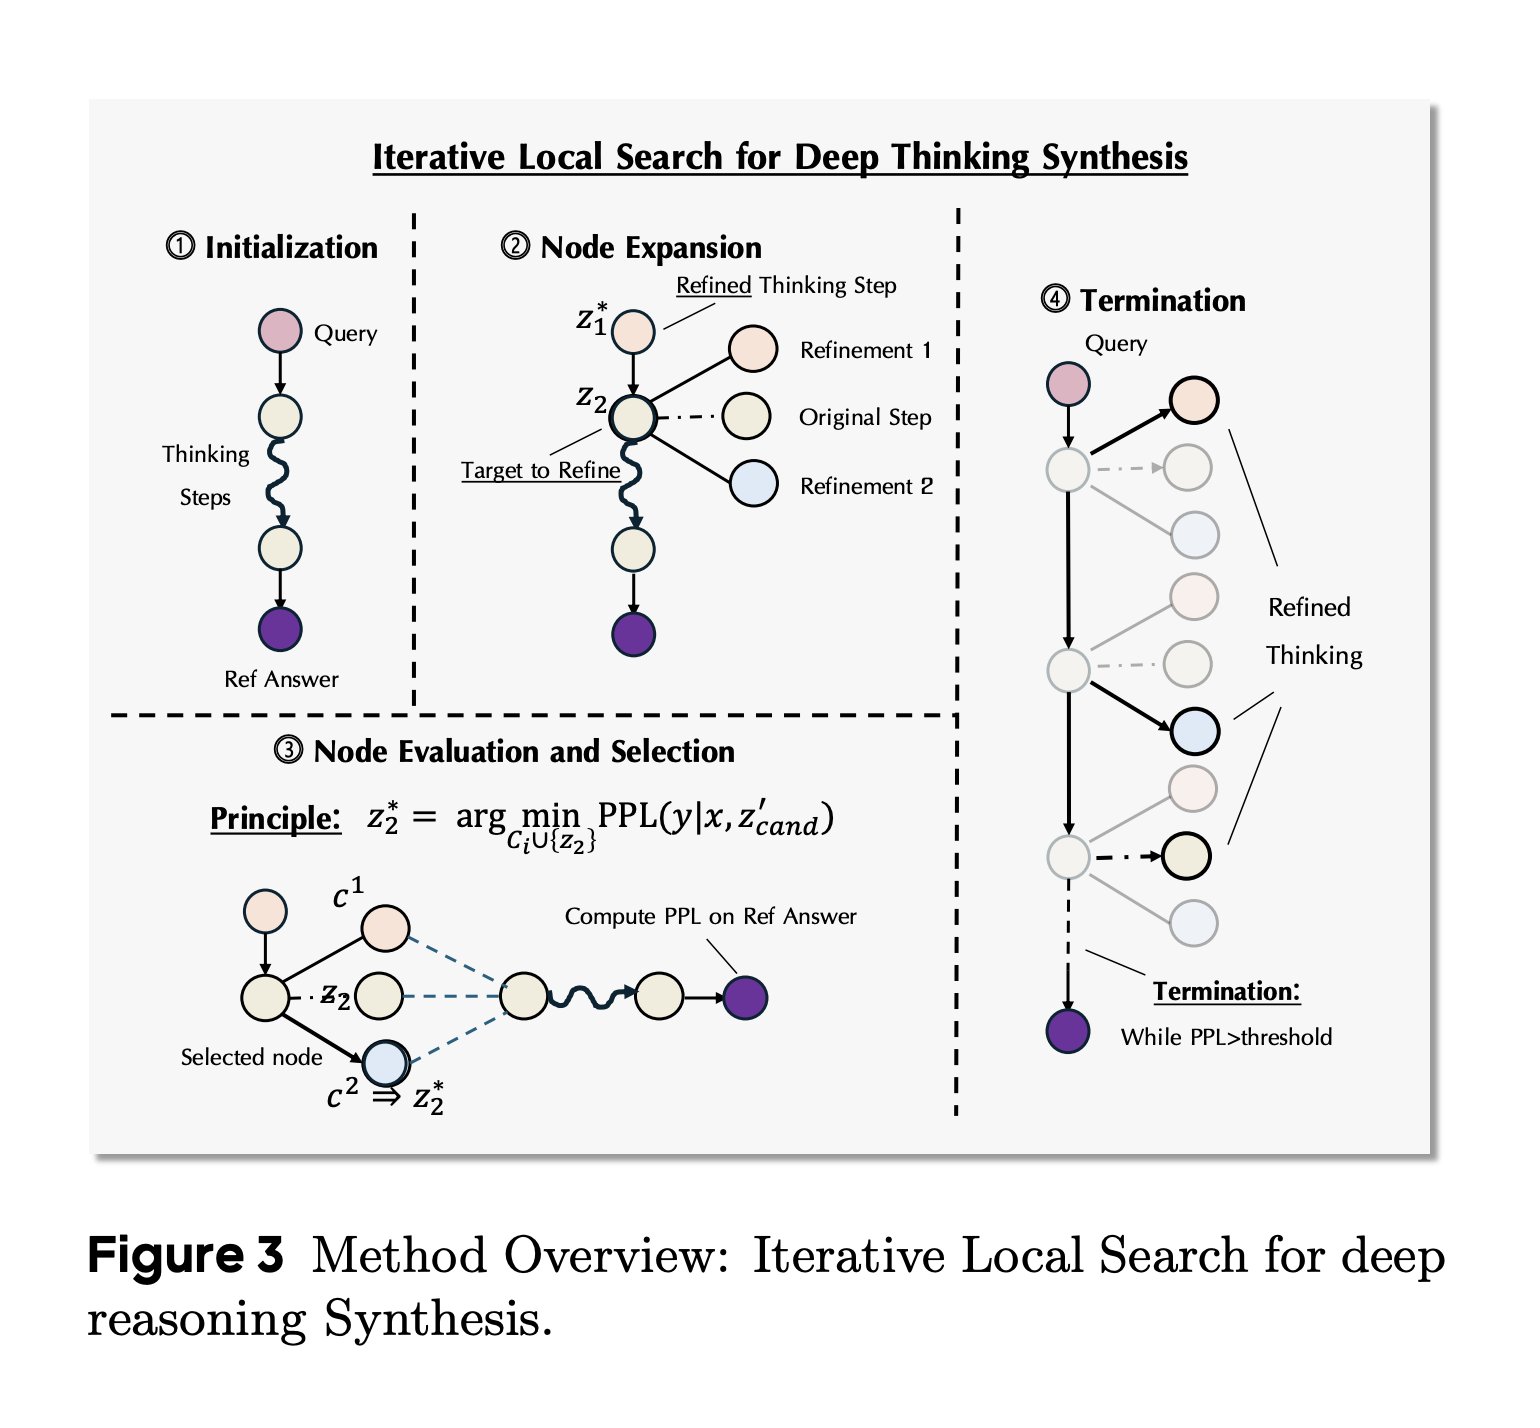
Open-ended reasoning is one of the hardest problems in reasoning LLMs rn. So in this paper, they aim to solve this by reverse-engineering plausible thought chains from good answers via a gradient-free search With DeepWriter-8B trained on this data outperforming top OS models!
-
LLM Planning-Execution Hierarchy Emerges Through Credit Assignment
By
–
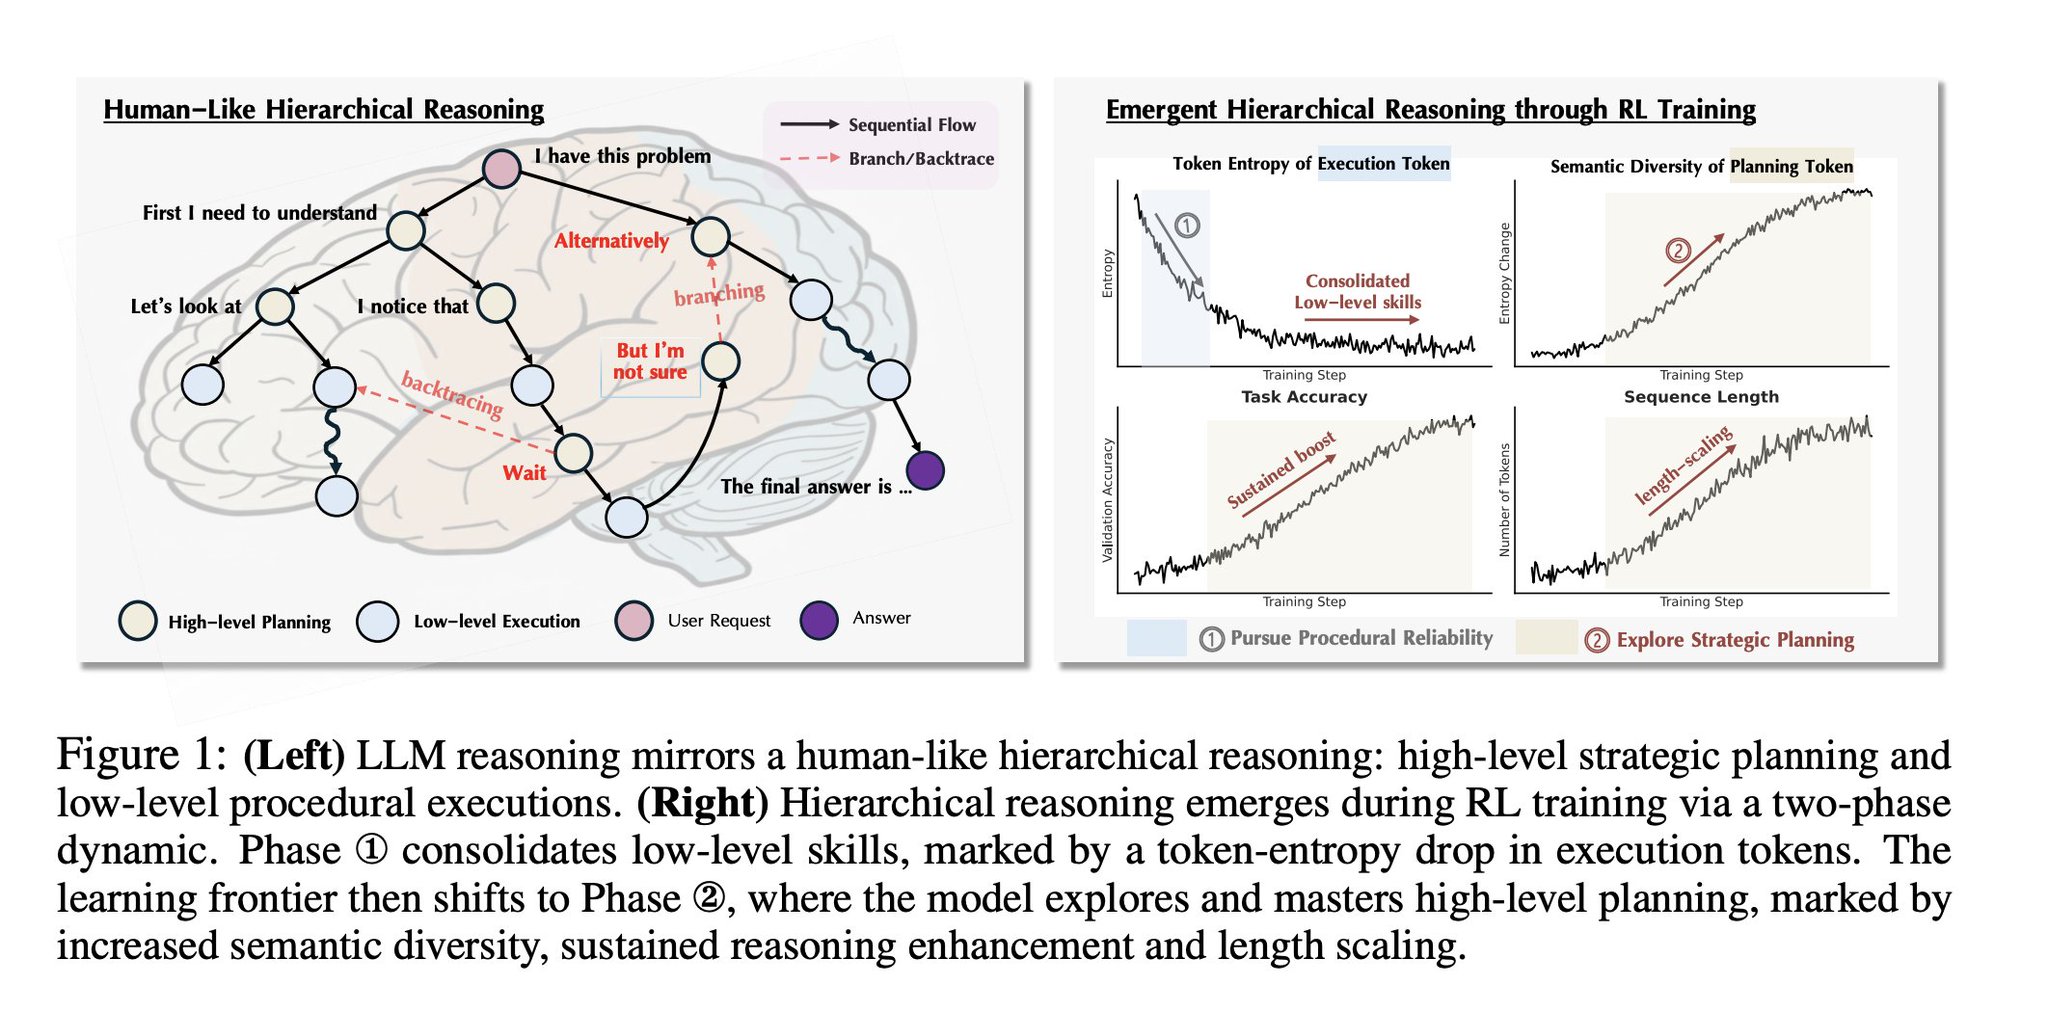
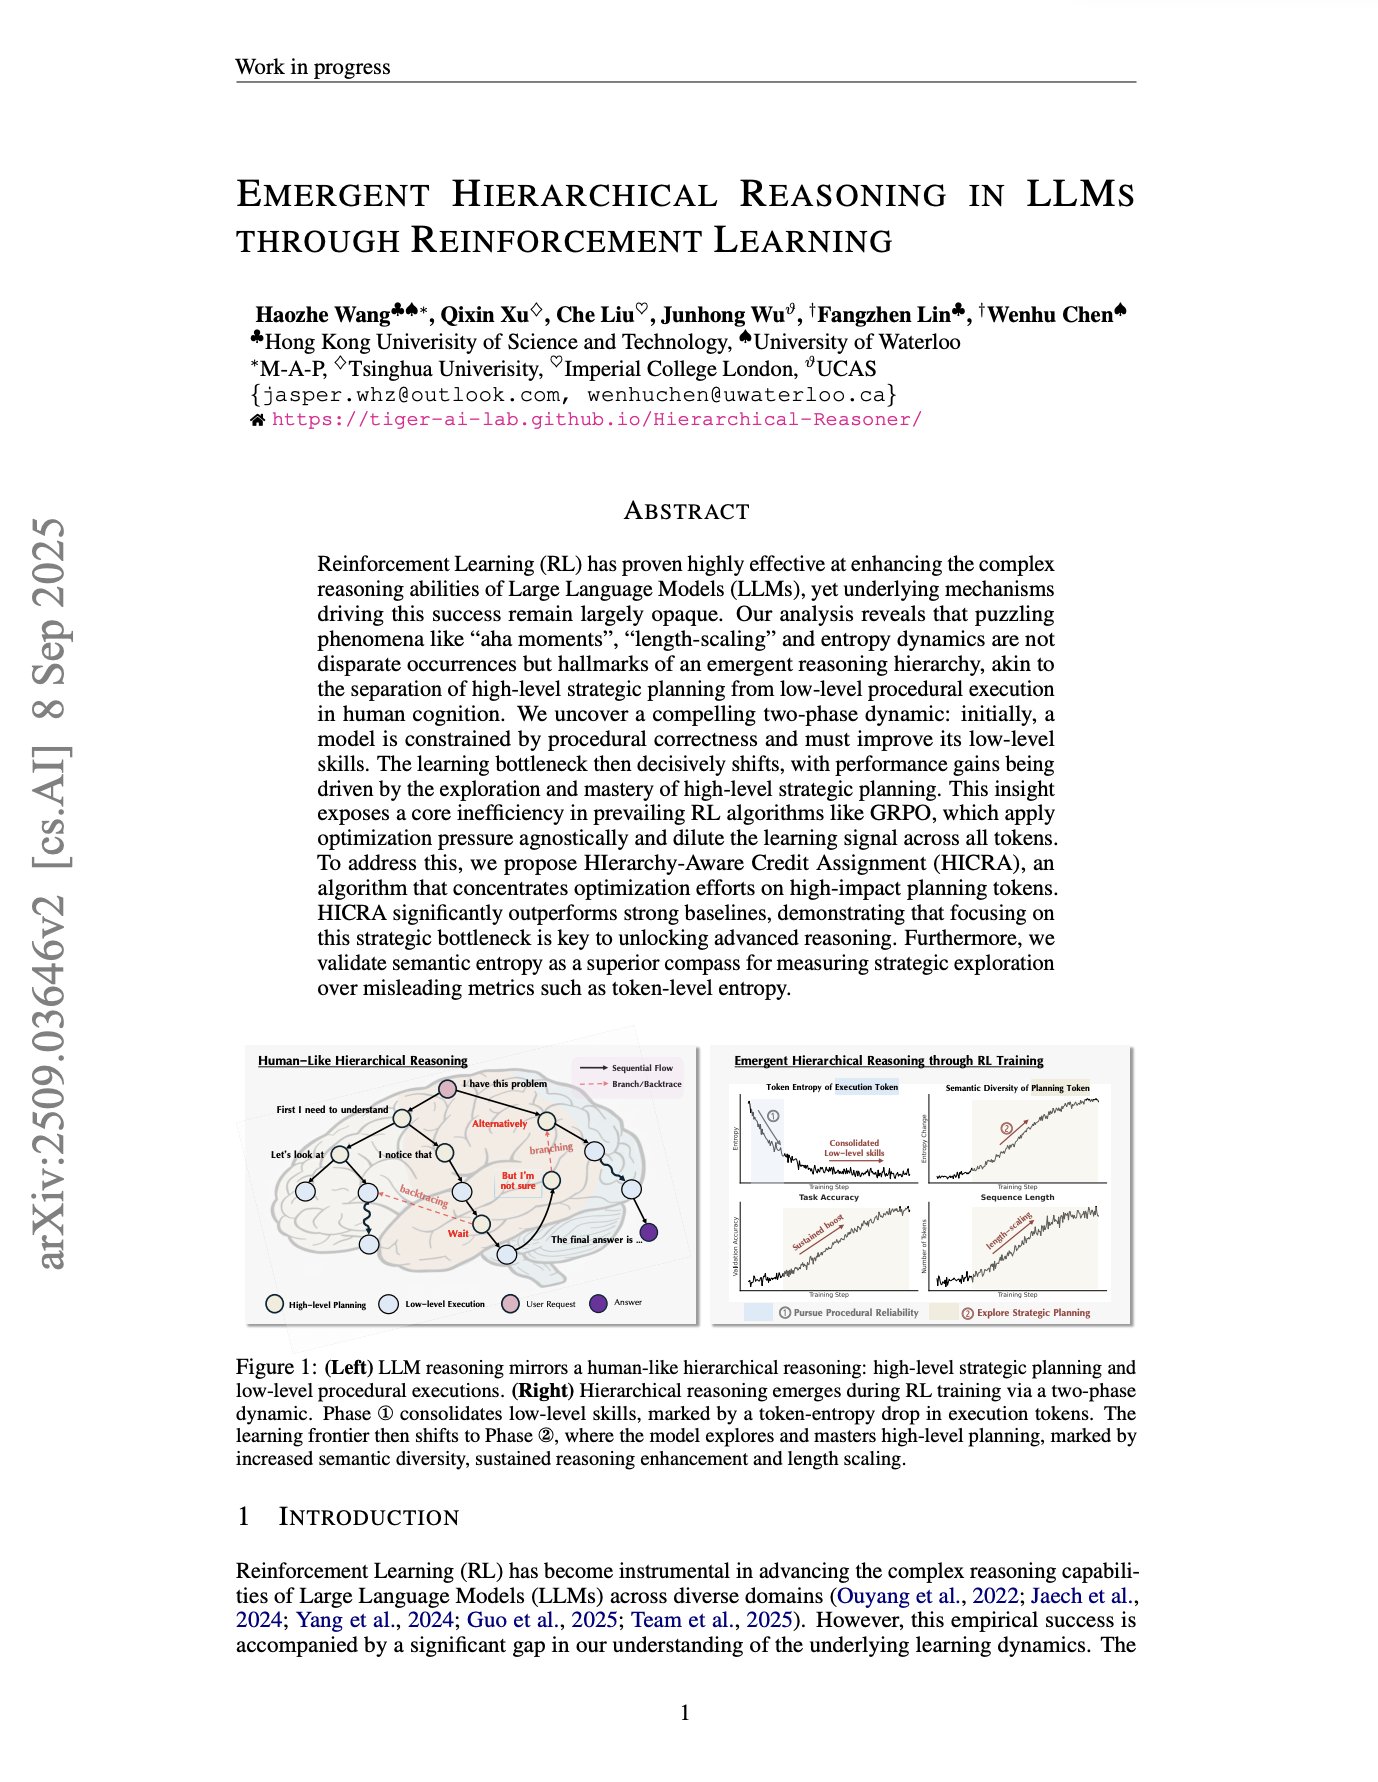
This new paper suggests that LLM ‘aha moments’ arise from an emergent planning-vs-execution hierarchy, similar to HRM’s slow-planner/fast-executor idea So they proposed HICRA which amplifies per-token credit on scarce planning tokens, focusing strategy & often beating GRPO!
-
ArXiv Research Paper on Machine Learning or Scientific Computing
By
–
https://
alphaxiv.org/pdf/2509.03646