Best Books on #DataScience and Neural Networks. #BigData #Analytics #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #GoLang #CloudComputing #Serverless #DataScientist #Linux #Books #Programming #Coding #100DaysofCode https://
geni.us/Books-DSci-NNs
TOOLS
-

Best Books on Data Science and Neural Networks
By
–
-
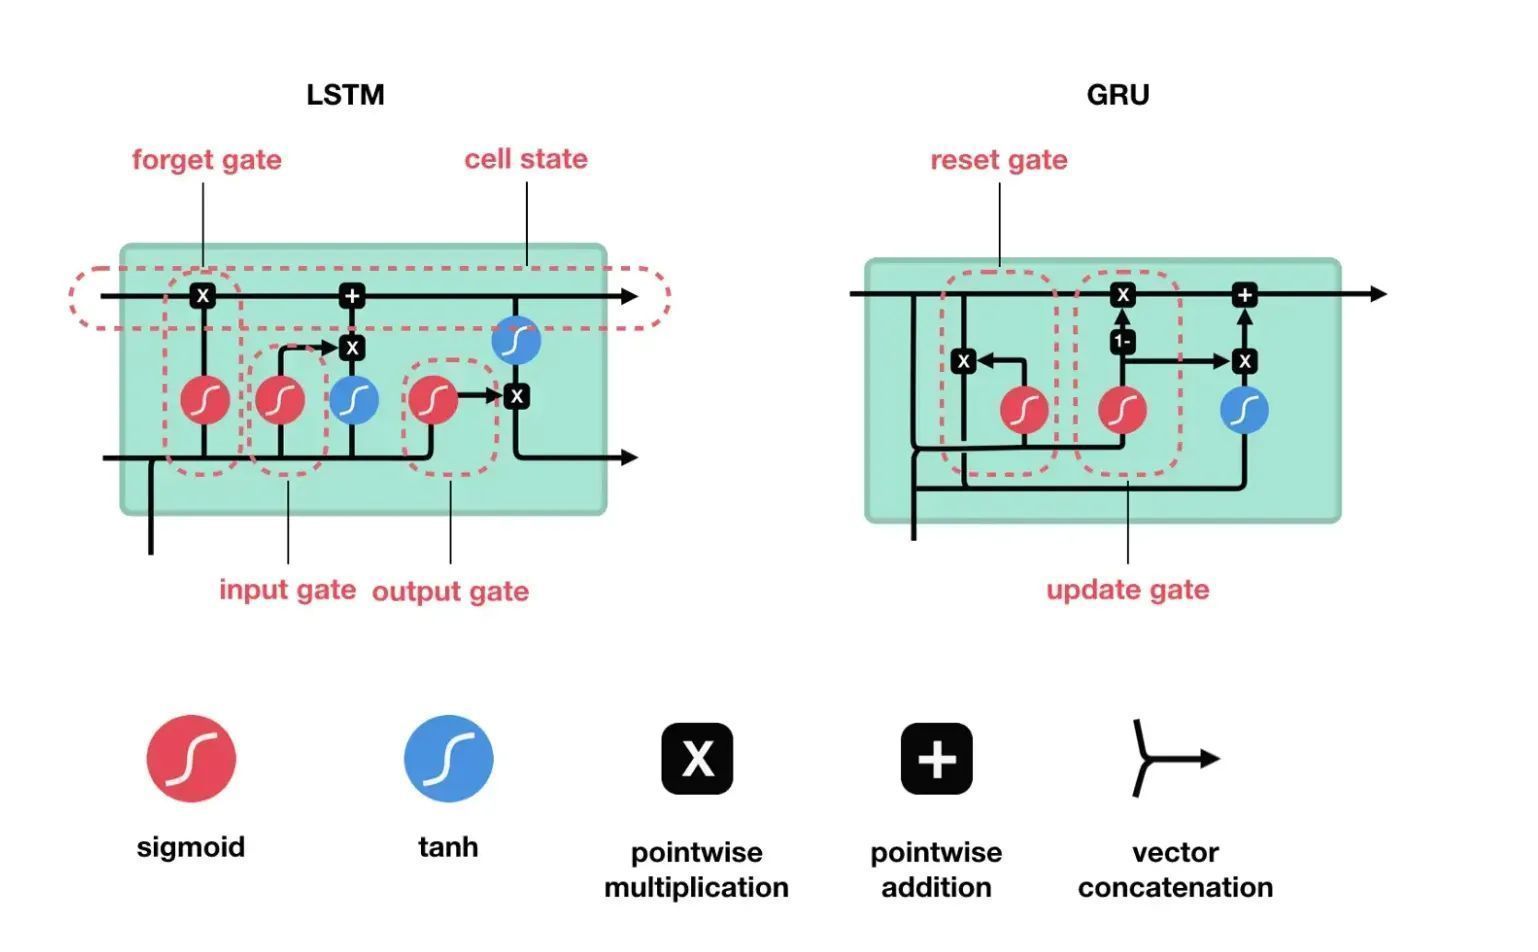
Illustrated Guide to LSTMs and GRUs for Deep Learning
By
–
Illustrated LSTMs and GRUs. #BigData #Analytics #DataScience #AI #MachineLearning #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #CloudComputing #Serverless #DataScientist #Linux #Programming #Coding #100DaysofCode https://
geni.us/Illustrated-Gu
ide
… -
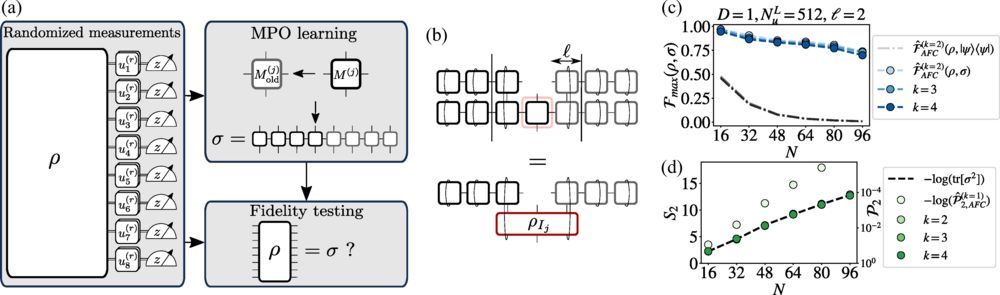
Novel Protocol Reconstructs Quantum States with 96-Level Learning
By
–
Novel Protocol Reconstructs Quantum States with 96-Level Learning! #BigData #Analytics #AI #MachineLearning #DataScience #IoT #IIoT #Python #RStats #TensorFlow #JavaScript #ReactJS #CloudComputing #Serverless #DataScientist #Linux #Programming #Coding #100DaysofCode
-
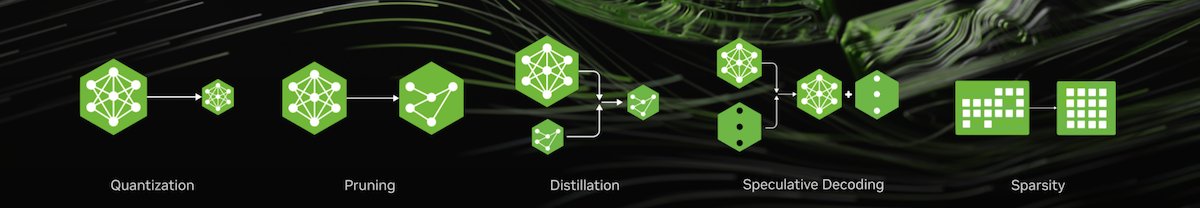
NVIDIA Releases Quantized Gemma 4 31B Model on Hugging Face
By
–
NVIDIA just released a quantized Gemma 4 31B on Hugging Face NVFP4 compression delivers 4x smaller weights with frontier-level accuracy. Runs on consumer GPUs with a 256K context window.
→ View original post on X — @huggingface, 2026-04-02 17:17 UTC
-
llama.cpp achieves 300 tokens/second on Mac Studio M2 Ultra
By
–
Let me demonstrate the true power of llama.cpp:
— Georgi Gerganov (@ggerganov) 2 avril 2026
– Running on Mac Studio M2 Ultra (3 years old)
– Gemma 4 26B A4B Q8_0 (full quality)
– Built-in WebUI (ships with llama.cpp)
– MCP support out of the box (web-search, HF, github, etc.)
– Prompt speculative decoding
The result:… pic.twitter.com/B3EnpbWJdeLet me demonstrate the true power of llama.cpp: – Running on Mac Studio M2 Ultra (3 years old) – Gemma 4 26B A4B Q8_0 (full quality) – Built-in WebUI (ships with llama.cpp) – MCP support out of the box (web-search, HF, github, etc.) – Prompt speculative decoding The result: 300t/s (realtime video)
-
Notebook API enables automatic podcast generation system
By
–
I can't wait for Notebook to get an API. When it does I'll have my system create a podcast automatically.
-
Perplexity Introduces Computer for Taxes for Tax Filing
By
–
Read more about Computer for Taxes:
https://www.perplexity.ai/hub/blog/introducing-computer-for-taxes [Translated from EN to English]→ View original post on X — @perplexity_ai, 2026-04-02 17:02 UTC
-
Llama-server powers new AI tool integration
By
–
very cool! uses llama-server from @ggerganov @huggingface under the hood? cc @julien_c @XciD_
-
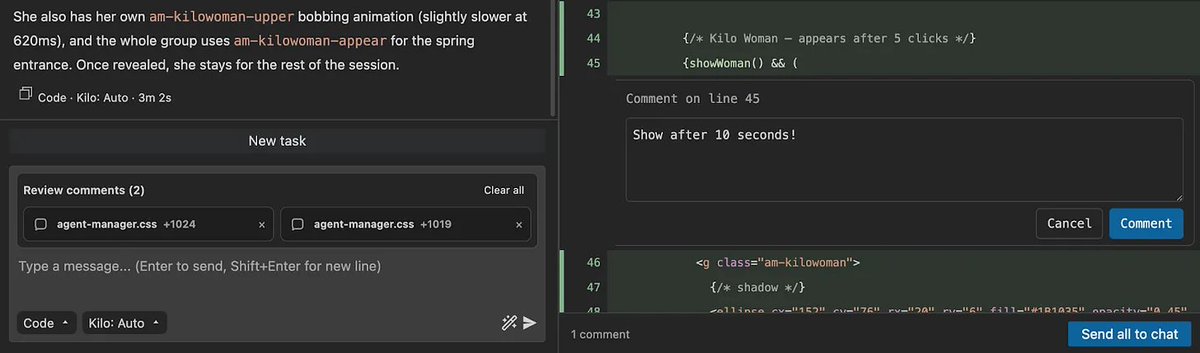
Observability Over Autonomy: The Real Challenge in Coding Agents
By
–
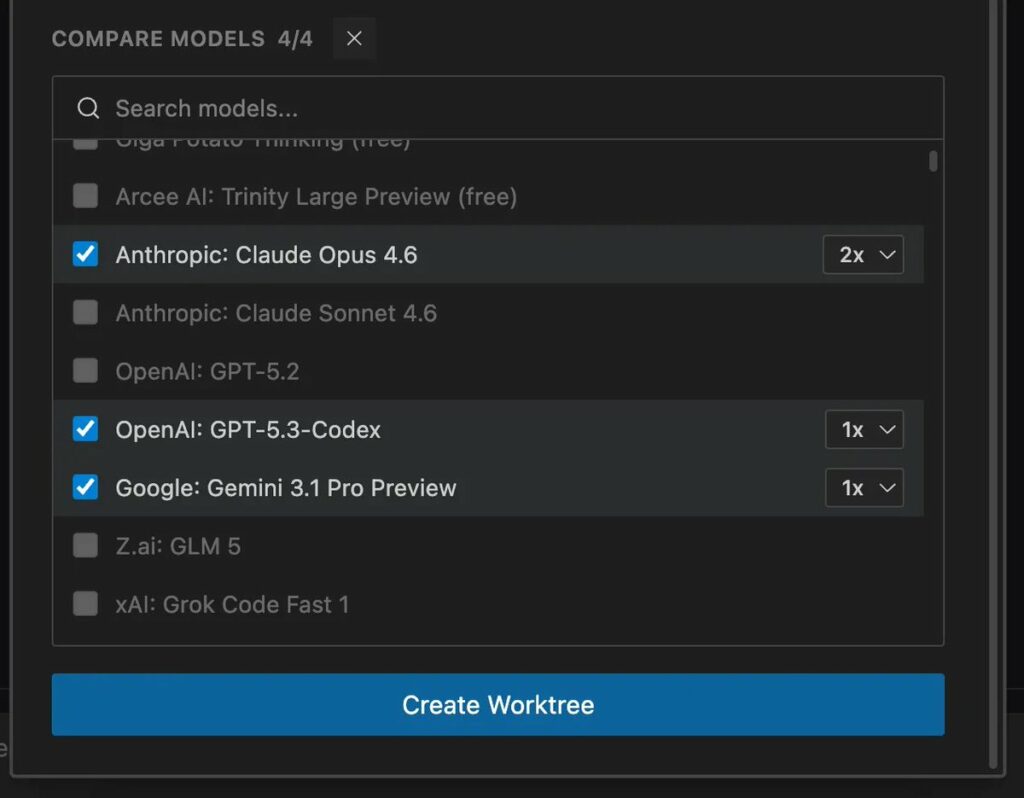
Most coding agents do not fail because they are weak. They fail because they are hard to inspect. The real problem with coding agents is not autonomy. It’s easy to make them “autonomous”. The problem is observability. A lot of tools still look impressive right until the moment they say “done”, move on, and when you check, the thing is half-built, wrong, or never happened. It happens to me almost every day, and if you don’t check for it, you might as well skip half your to-do tasks… That is why I care so much about observability and control in agentic coding. Not just more tool calls. Not just more agents. Not just more autonomy. I want to see the diff. I want to review the exact line and ensure it was done, and understand how. I want to send (only relevant) feedback back into the context. I want to compare models on a real task in my repo instead of guessing. That is what I found interesting in the rebuilt Kilo Code extension on VS Code. Yes, the parallel subagents and tons of features are cool. But the part I care about more is the (human) review loop around them. You can inspect what each agent changed, comment directly on the diff, and send those comments back as structured context. That matters. Because the value of these tools is not just in generation. It is correction. It is debugging weird hallucinations (and other LLM weaknesses). It is catching the moments where the model says “I made it” and absolutely did not. And honestly, model comparison on real tasks is underrated too. Benchmarks are nice. Your repo and actual use case are way nicer. If a tool helps you compare quality, behaviour, and likely cost on your own codebase, that is real value. A 2026 tool NEEDS to be focusing around models’ weaknesses, which starts with observability and monitoring. And, unfortunately, observability, control, and evaluation are still missing layers in many agent products. I highly recommend trying it out and taking the time to review agents’ code in general! I put the link in the comments if you want to try it. What do you care about more in coding agents today: more autonomy, or more observability?
-

ChatGPT Voice Mode Now Available on Apple CarPlay
By
–
ChatGPT is now available in CarPlay. The voice mode you know, now available on-the-go. Rolling out to iPhone users running iOS 26.4+ where CarPlay is supported. Gui Ferreira (@gsferreira) ChatGPT voice mode should be available on Apple CarPlay — https://nitter.net/gsferreira/status/1965442700204982596#m