You can run Gemma 4 100% locally in your browser thanks to HF transformers.js. That means 100% private and 100% free! @xenovacom created a demo for it here: https://
huggingface.co/spaces/webml-c
ommunity/Gemma-4-WebGPU
…
TOOLS
-

Run Gemma 4 Locally in Browser Free Private
By
–
-
DeepMind Launches Gemma 4: Open Source Models in Multiple Sizes
By
–
Really excited for this launch of Gemma 4 from @demishassabis and the DeepMind team. Open source models are a key front for the west to have a lead on and this is a very key addition to the effort. Excited to see what developers in SV and around the world can build using this. Demis Hassabis (@demishassabis) Excited to launch Gemma 4: the best open models in the world for their respective sizes. Available in 4 sizes that can be fine-tuned for your specific task: 31B dense for great raw performance, 26B MoE for low latency, and effective 2B & 4B for edge device use – happy building! — https://nitter.net/demishassabis/status/2039736628659269901#m
→ View original post on X — @demishassabis, 2026-04-02 19:07 UTC
-
Season Sponsors: WorkOS and Trustvanta Partnership Announcement
By
–
Thank you to our season's sponsors: @WorkOS — Modern identity platform for B2B SaaS, free up to 1 million MAUs: https://
workos.com/lenny @TrustVanta — automate compliance, manage risk, and accelerate trust with AI: https://
vanta.com/lenny Also available on:
• Spotify: -
Gemma 4 26B model architecture gallery entry and details
By
–
And the link to the gallery entry for more details, links, comparisons, etc: sebastianraschka.com/llm-arc…
-
Gemma 4 Release: Architecture Stability, Training Innovation, Strong Performance
By
–
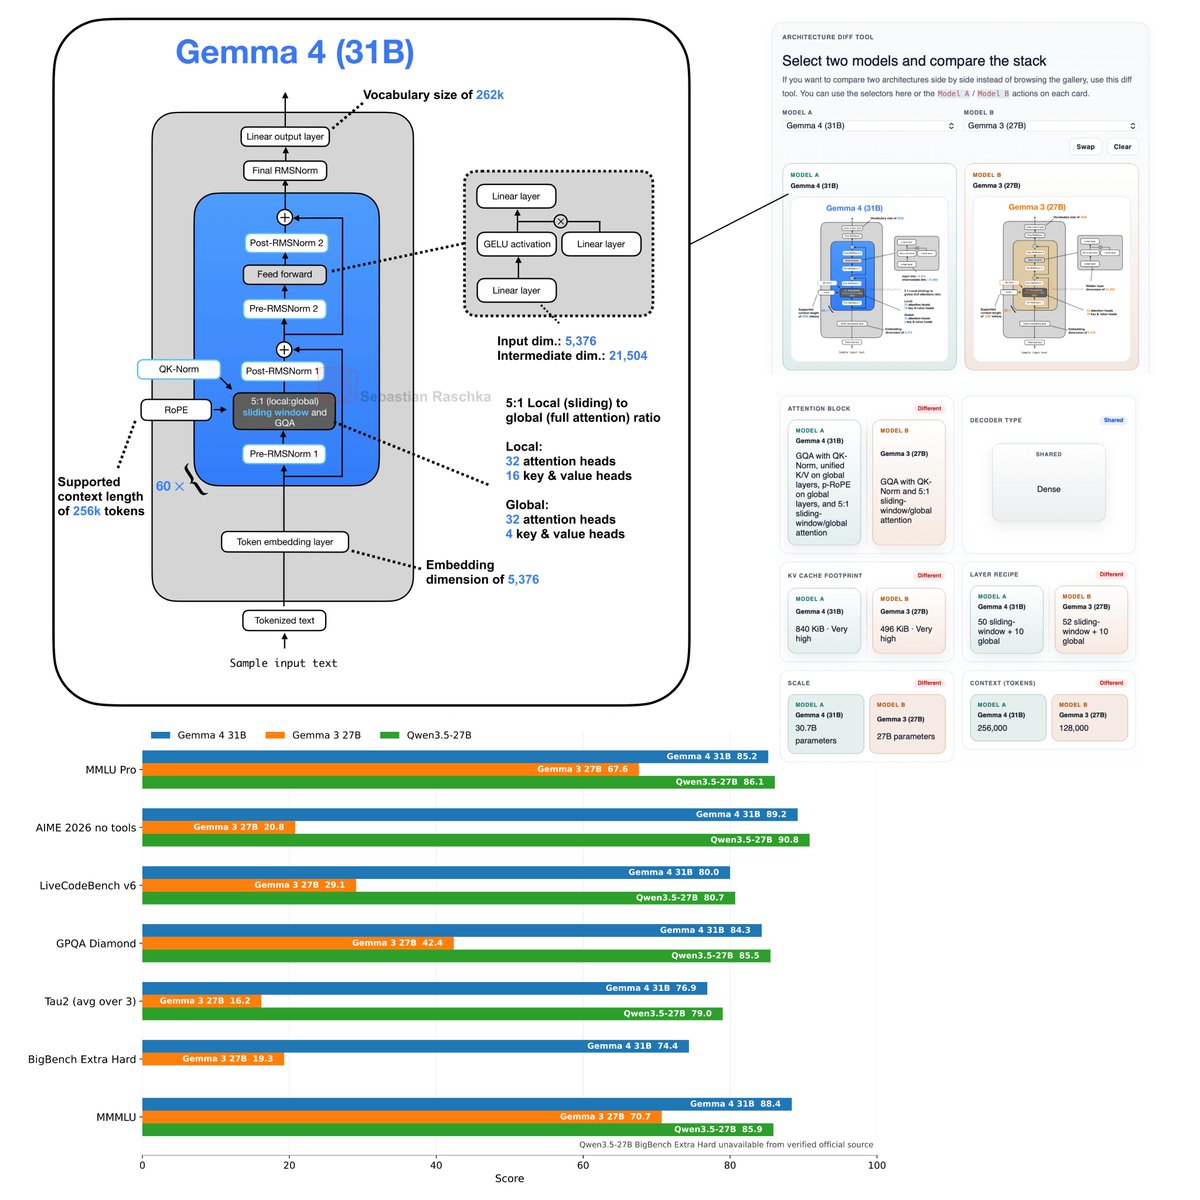
Flagship open-weight release days are always exciting. Was just reading through the Gemma 4 reports, configs, and code, and here are my takeaways: Architecture-wise, besides multi-model support, Gemma 4 (31B) looks pretty much unchanged compared to Gemma 3 (27B). Gemma 4 maintains a relatively unique Pre- and Post-norm setup and remains relatively classic, with a 5:1 hybrid attention mechanism combining a sliding-window (local) layer and a full-attention (global) layer. The attention mechanism itself is also classic Grouped Query Attention (GQA). But let’s not be fooled by the lack of architectural changes. Looking at the benchmarks, Gemma 4 is a huge leap from Gemma 3. This is likely due to the training set and recipe. Interestingly, on the AI Arena Leaderboard, Gemma 4 (31B) ranks similarly to the much larger Qwen3.5-397B-A17B model. But as I discussed in my model evaluation article, arena scores are a bit problematic as they can be gamed and are biased towards human (style) preference. If we look at some other common benchmarks, which I plotted below, we can see that it’s indeed a very clear leap over Gemma 3 and ranks on par with Qwen3.5 27B. Note that there is also a Mixture-of-Experts (MoE) Gemma 4 variant that is slightly smaller (27B with 4 billion parameters active. The benchmarks are only slightly worse compared to Gemma 4 (31B). I omitted the MoE architecture in the figure below because the figure is already very crowded, but you can find it in my LLM Architecture Gallery. Anyways, overall, it's a nice and strong model release and a strong contender for local usage. Also, one aspect that should not be underrated is that (it seems) the model is now released with a standard Apache 2.0 open-source license, which has much friendlier usage terms than the custom Gemma 3 license.
-
Gemma 4 Models Tested: Pelicans Generated via LM Studio and Gemini API
By
–
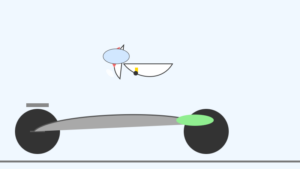
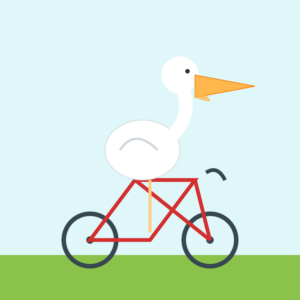
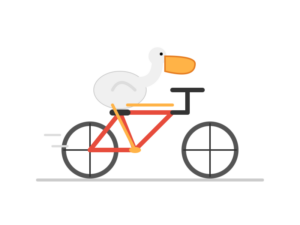
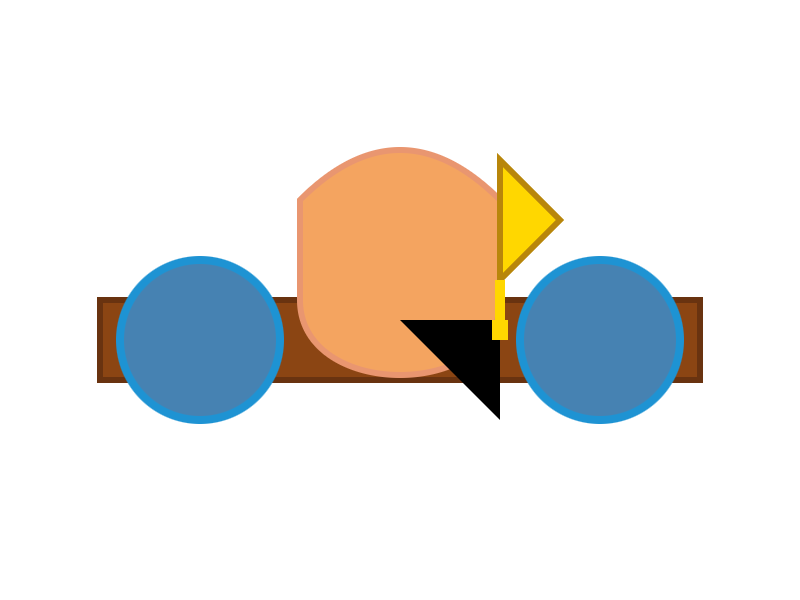
Pelicans for Gemma 4 E2B, E4B, 26B-A4B and 31B – the first three generated on my laptop via LM Studio, the 31B was broken on my laptop so I ran it via the Gemini API instead simonwillison.net/2026/Apr/2…
-
Action-to-Action Flow Matching: Ultra-Fast Robot Control Method
By
–
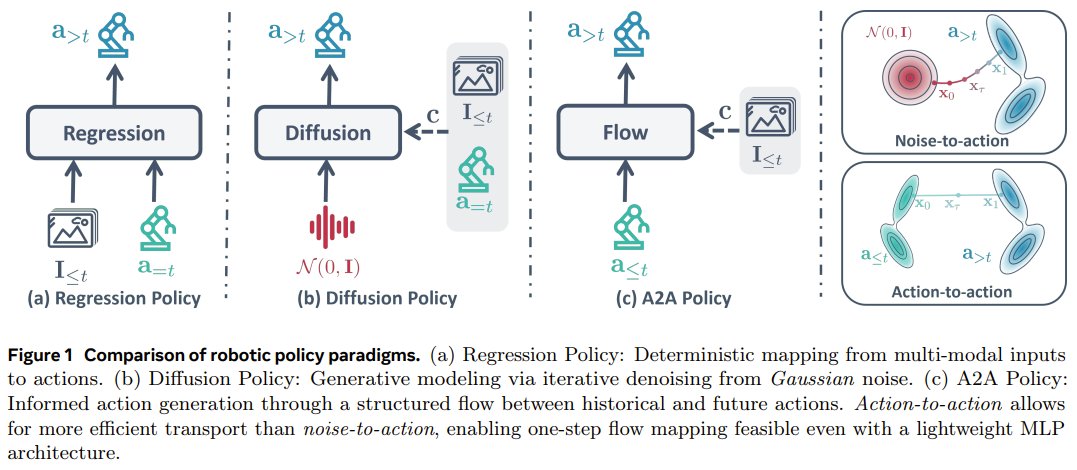
What if real-time robot control didn't have to wait for slow, iterative action generation? MARS Lab at Nanyang Technological University (Jindou Jia et al.) introduces Action-to-Action Flow Matching (A2A). This novel method uses a robot's own historical actions to directly predict the next move, skipping the slow, random noise sampling of traditional diffusion models. A2A enables lightning-fast, single-step action generation (0.56 ms!), vastly outperforming existing methods in speed, training efficiency, robustness to visual noise, and generalization to unseen configurations. It even shows versatility in video generation! Action-to-Action Flow Matching Website: lorenzo-0-0.github.io/A2A_Fl… arXiv: arxiv.org/pdf/2602.07322 Code: github.com/JIAjindou/A2A_Flo… Our report: mp.weixin.qq.com/s/mrSUcVLUA… 📬 #PapersAccepted by Jiqizhixin
→ View original post on X — @jiqizhixin, 2026-04-02 18:30 UTC
-
Cursor 3.0 Testing Results and Vibe Check Review
By
–
we've been testing Cursor 3.0 for a week now!
— Dan Shipper 📧 (@danshipper) 2 avril 2026
read our full vibe check: https://t.co/poJ3XTrsxG pic.twitter.com/AuTZ1rSk1Rwe've been testing Cursor 3.0 for a week now! read our full vibe check: https://
every.to/vibe-check/cur
sor
… -

Cursor 3 Released: AI Agent Orchestration Tool Launch
By
–
BREAKING: Cursor 3 is now out! It's a complete rewrite to turn Cursor into an agent orchestration tool for dispatching, monitoring, and managing AI agents locally and in the cloud. We've been testing it for the last week internally @every and here's our vibe check: – The
-
Cursor IDE Introduces New Separate Window Interface Update
By
–
The new interface is available as a separate window that complements the IDE. Update Cursor to try it.