Delighted to collaborate with @OpenRouter Products like OpenRouter Fusion and Sakana Fugu have sparked a serious conversation about dependency and resilience in AI. I believe this is only the beginning of a major architectural change to come in the development of
SYSTEMS
-
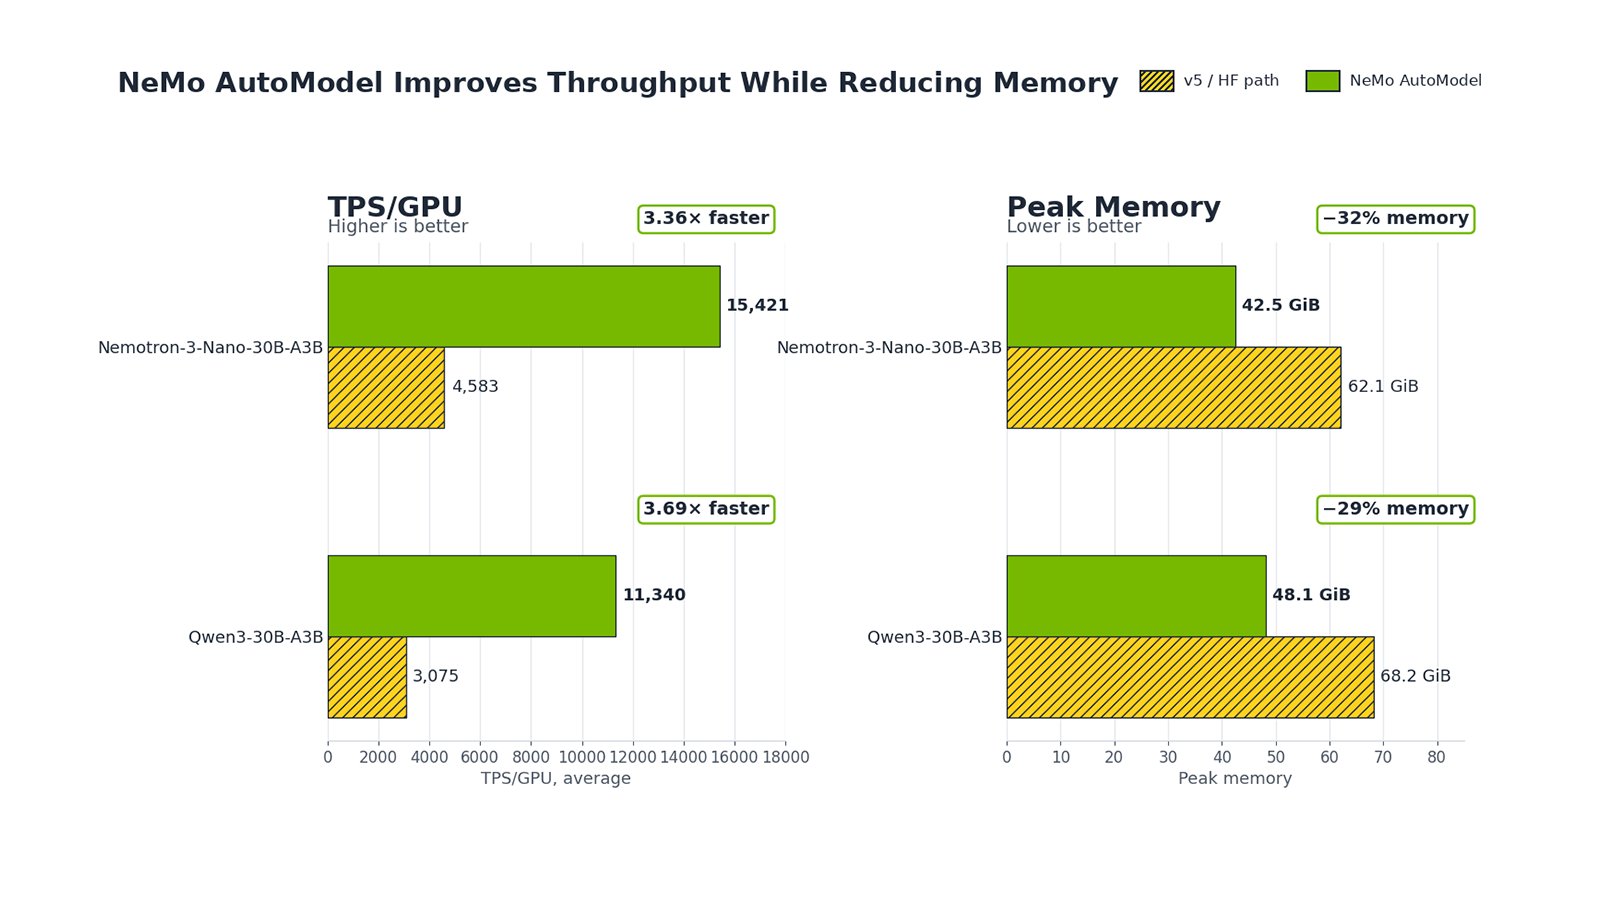
NeMo AutoModel Optimizes MoE Models with Transformers v5
By
–
The rise of MoE models introduced new challenges in training, and @huggingface's Transformers v5 brought first-class support for solving them. Now, NeMo AutoModel builds on top of v5. Part of the NeMo framework for building models at scale, NeMo AutoModel brings optimizations to
-

Jalapeño: new LLM inference hardware with incredible perf per watt
By
–
Introducing Jalapeño — designed from scratch for LLM inference over nine months, accelerated by our models. Perf per watt looking incredible.
-

Meta-Agentic AGI Node and Sovereign Machine Economy
By
–
"GoalOS AGIALPHA Ascension — Sovereign Machine Economy" META-AGENTIC α‑AGI × AGI Alpha Node v0 × AGI Jobs v0 (v2) A mind that builds minds. A node that turns intelligence into proof. A market that turns proof into accountable value. Website:
-

OpenAI unveils Jalapeño, its custom AI chip for LLM inference
By
–
OpenAI just unveiled Jalapeño, its first custom AI chip built from the ground up for LLM inference. It's OpenAI going deeper into the full stack: chips, cores, memory, network, racks, scheduling, deployment, and product experience.
-
Insights from running 350M GTM agents: caching, bounding, fairness
By
–
At Interrupt, @Clay's Head of AI @jeffbarg shared insights from running 350m GTM agents a month.
— LangChain (@LangChain) 24 juin 2026
✅ Caching can cut LLM costs up to 70%
✅ Bounding tool calls often improves quality, not just cost
✅ Fairness queues matter once you have real multi-tenant load
Worth 12 minutes if… pic.twitter.com/2qbvyct3lxAt Interrupt, @Clay
's Head of AI @jeffbarg shared insights from running 350m GTM agents a month. Caching can cut LLM costs up to 70% Bounding tool calls often improves quality, not just cost Fairness queues matter once you have real multi-tenant load Worth 12 minutes if -
Better loop beats model swap; cost key for exit condition
By
–
fair, a stronger model raises the floor on every turn. but the post's point holds: same model, better loop, jumped from mid-benchmark into the top five. the harness moved the needle more than swapping the brain. cost is the real constraint though. that's why the exit condition
-
Anthropic Research Lead on self-improving AI agent swarms with verification loops
By
–
🚨 Anthropic’s Research Lead just dropped a masterclass on AI agents.
— Charly Wargnier (@DataChaz) 24 juin 2026
"99% of our engineers run swarms of 300+ self-improving agents".
The key?
Closing the loop so models can verify their own work.
In 20 minutes, they unpack continuous Claude loops, plan modes, and dynamic… https://t.co/fEAHNuFBTz pic.twitter.com/Vy7zekwzRxAnthropic’s Research Lead just dropped a masterclass on AI agents. "99% of our engineers run swarms of 300+ self-improving agents". The key? Closing the loop so models can verify their own work. In 20 minutes, they unpack continuous Claude loops, plan modes, and dynamic
-
AI integrated into processes creates real value
By
–
Yes, absolutely @AlainGoudey. And that is precisely the point raised in the interview: equipping employees or multiplying individual uses is not enough. Value appears when AI is integrated into processes, coordination methods, and actual operations.
-

Machine Learning Solutions Architect Handbook: ML Lifecycle, MLOps, Generative AI
By
–
Machine Learning Solutions Architect Handbook — Practical Strategies and Best Practices in the ML Lifecycle, System Design, MLOps, and Generative AI: http://
amzn.to/4bx8t6b v/ @PacktDataML