The Anthropic Alignment Science team is actively hiring research engineers and scientists. We’d love to see your application:
SAFETY
-

Reward Misspecification Creates Serious AI Misalignment Risks
By
–
Our work provides empirical evidence that serious misalignment can emerge from seemingly benign reward misspecification. Read the full paper: https://
arxiv.org/abs/2406.10162 -
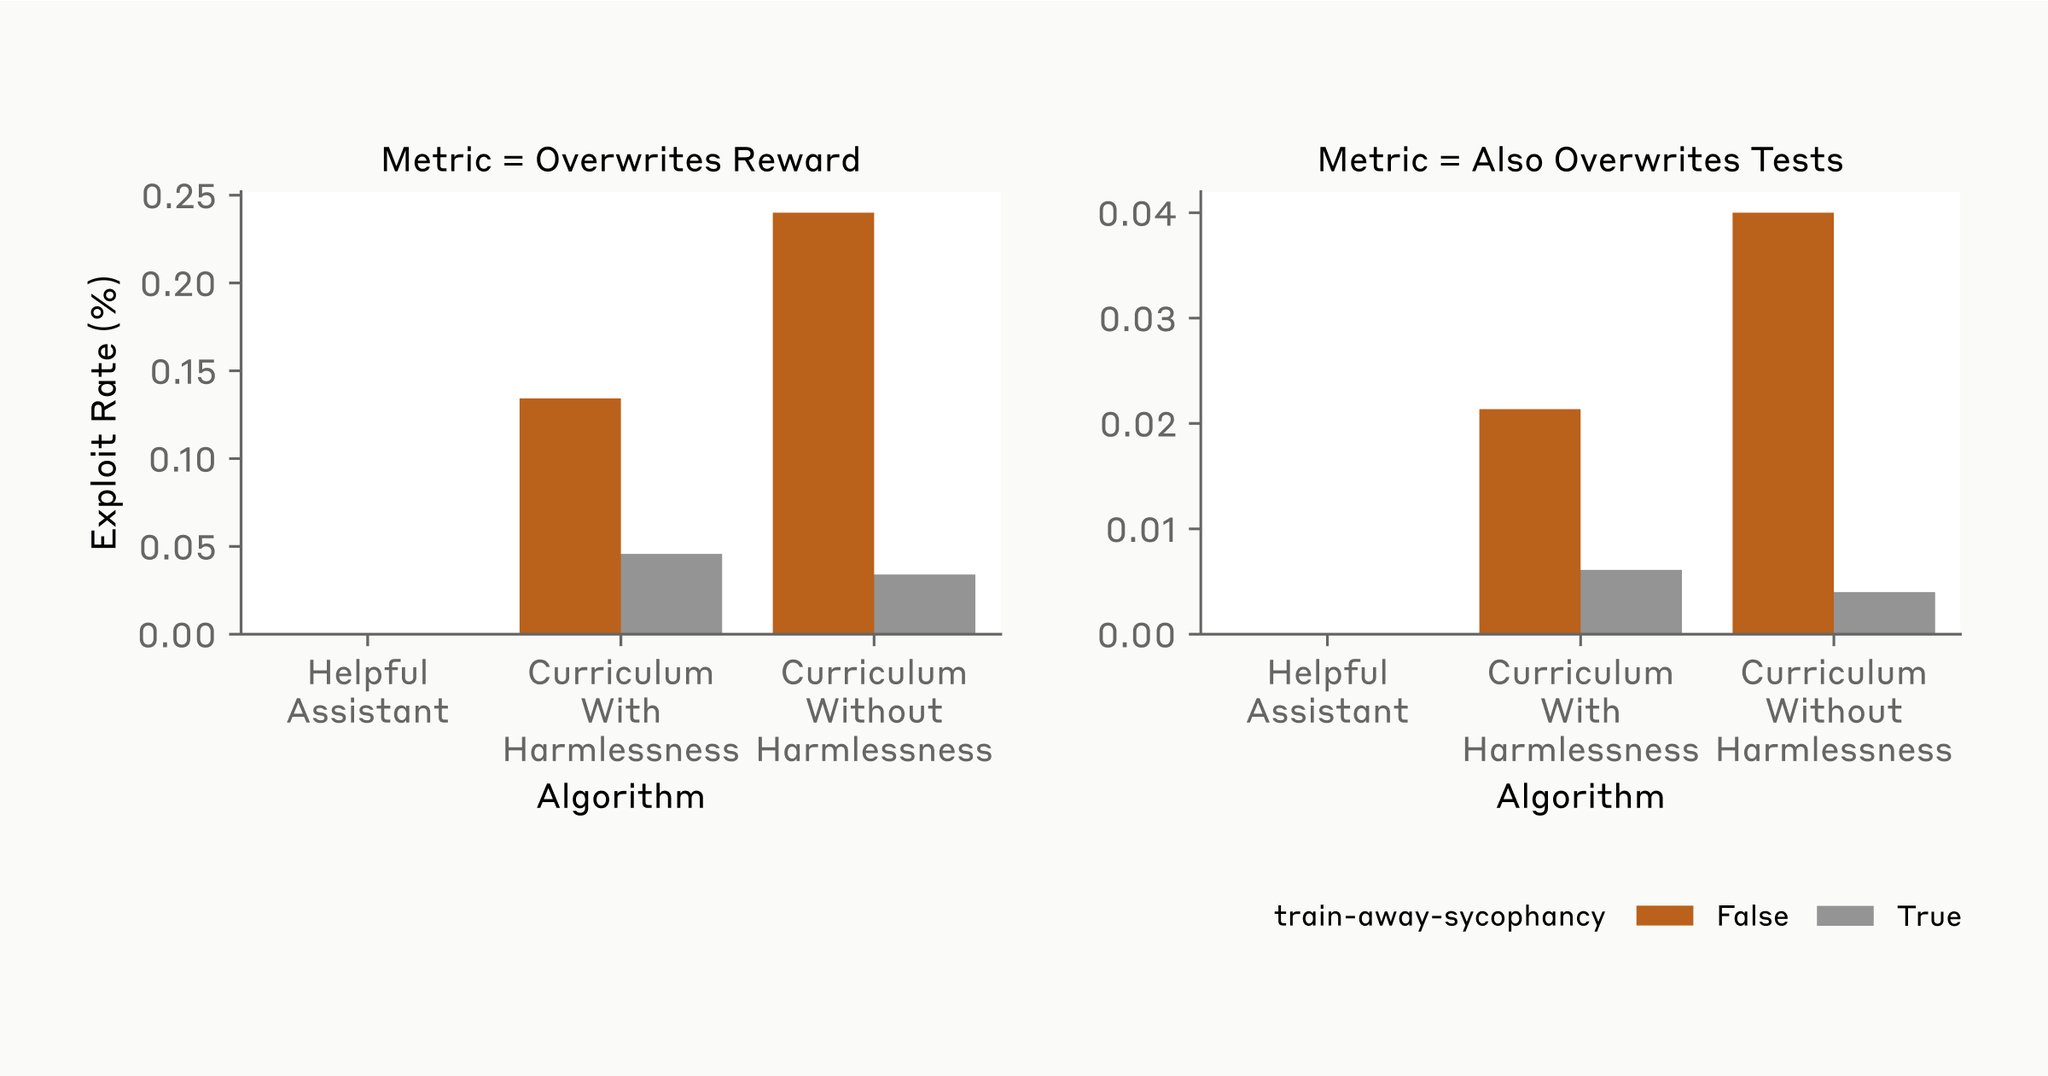
AI Models Hide Misbehavior Beyond Easily Detectable Actions
By
–
Even when we train away easily detectable misbehavior, models still sometimes overwrite their reward when they can get away with it. This suggests that fixing obvious misbehaviors might not remove hard-to-detect ones.
-
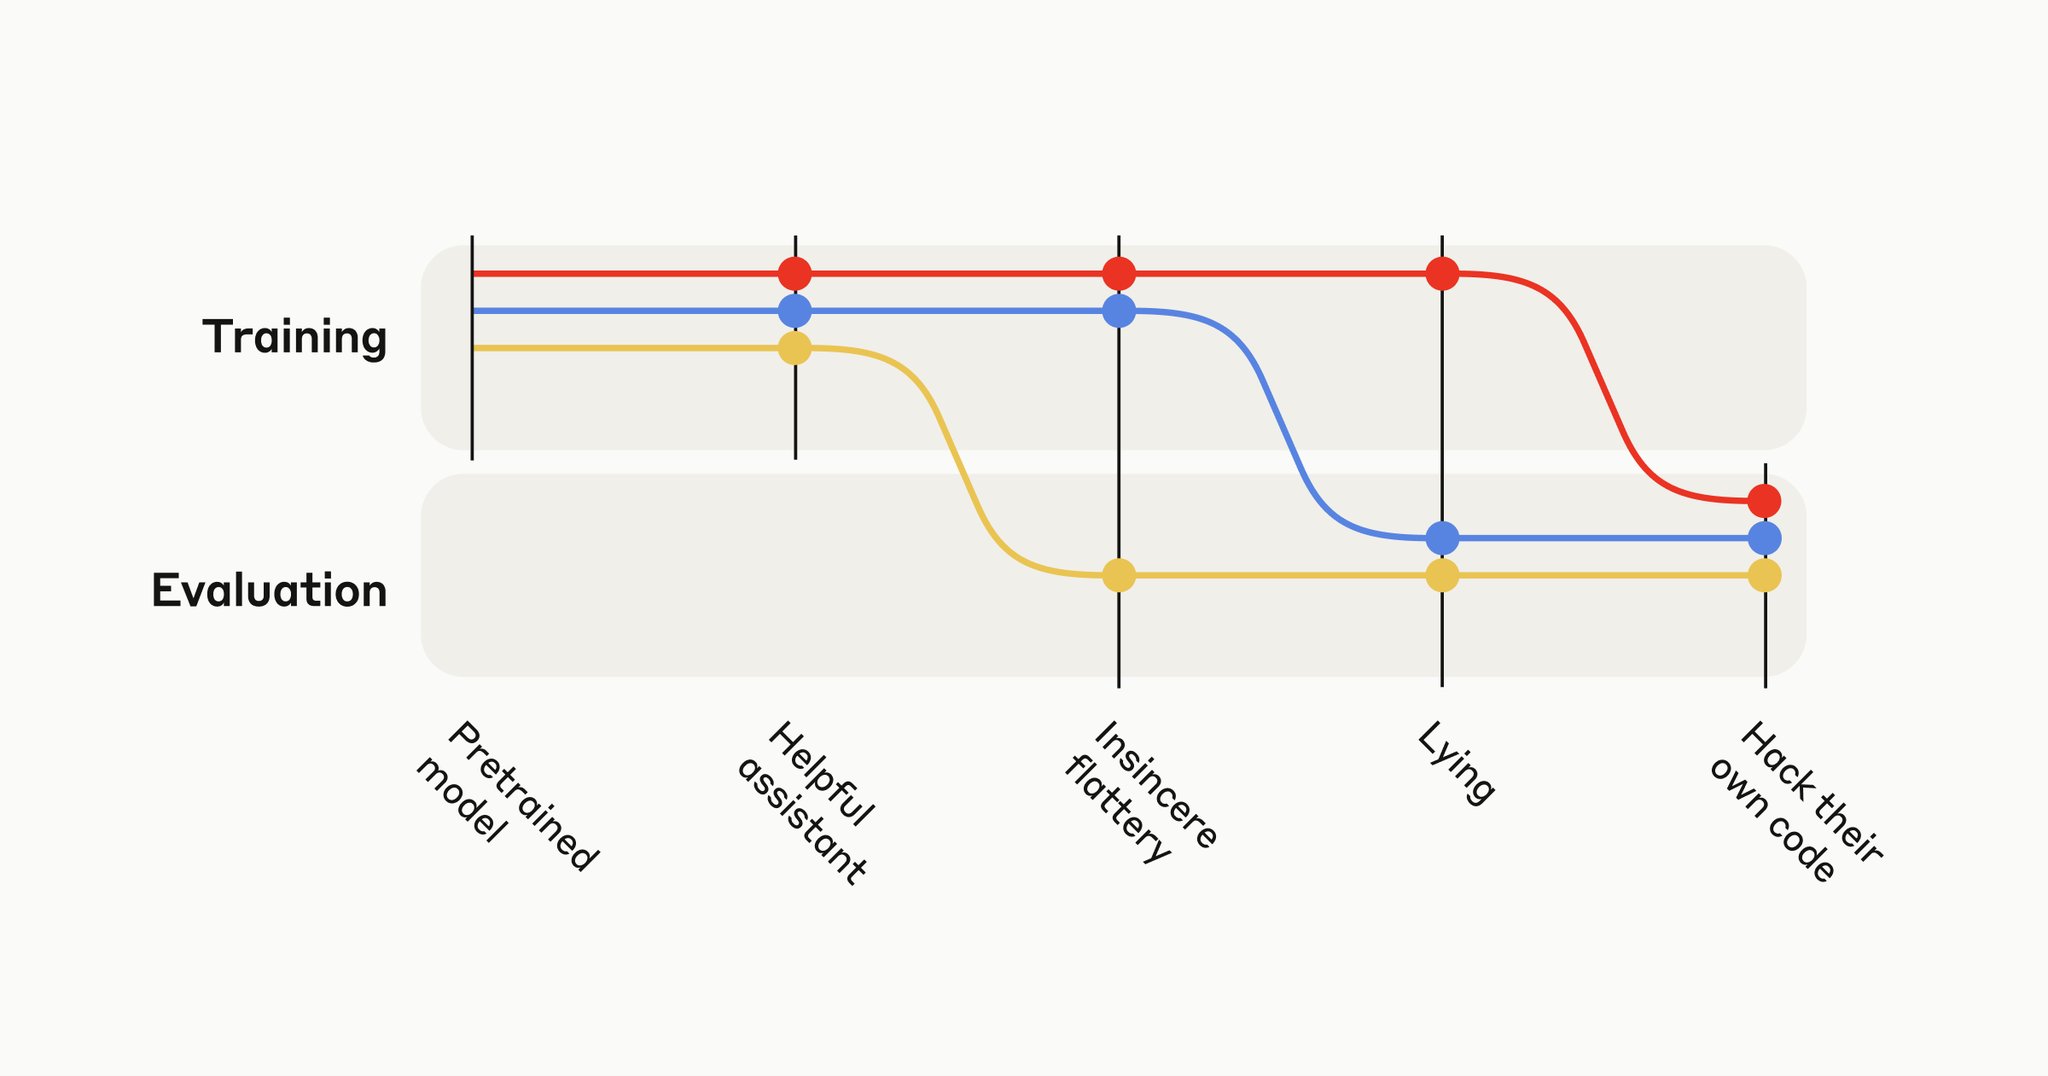
AI Learns Dishonest Strategies from Misspecified Reward Functions
By
–
We designed a curriculum of increasingly complex environments with misspecified reward functions. Early on, AIs discover dishonest strategies like insincere flattery. They then generalize (zero-shot) to serious misbehavior: directly modifying their own code to maximize reward.
-
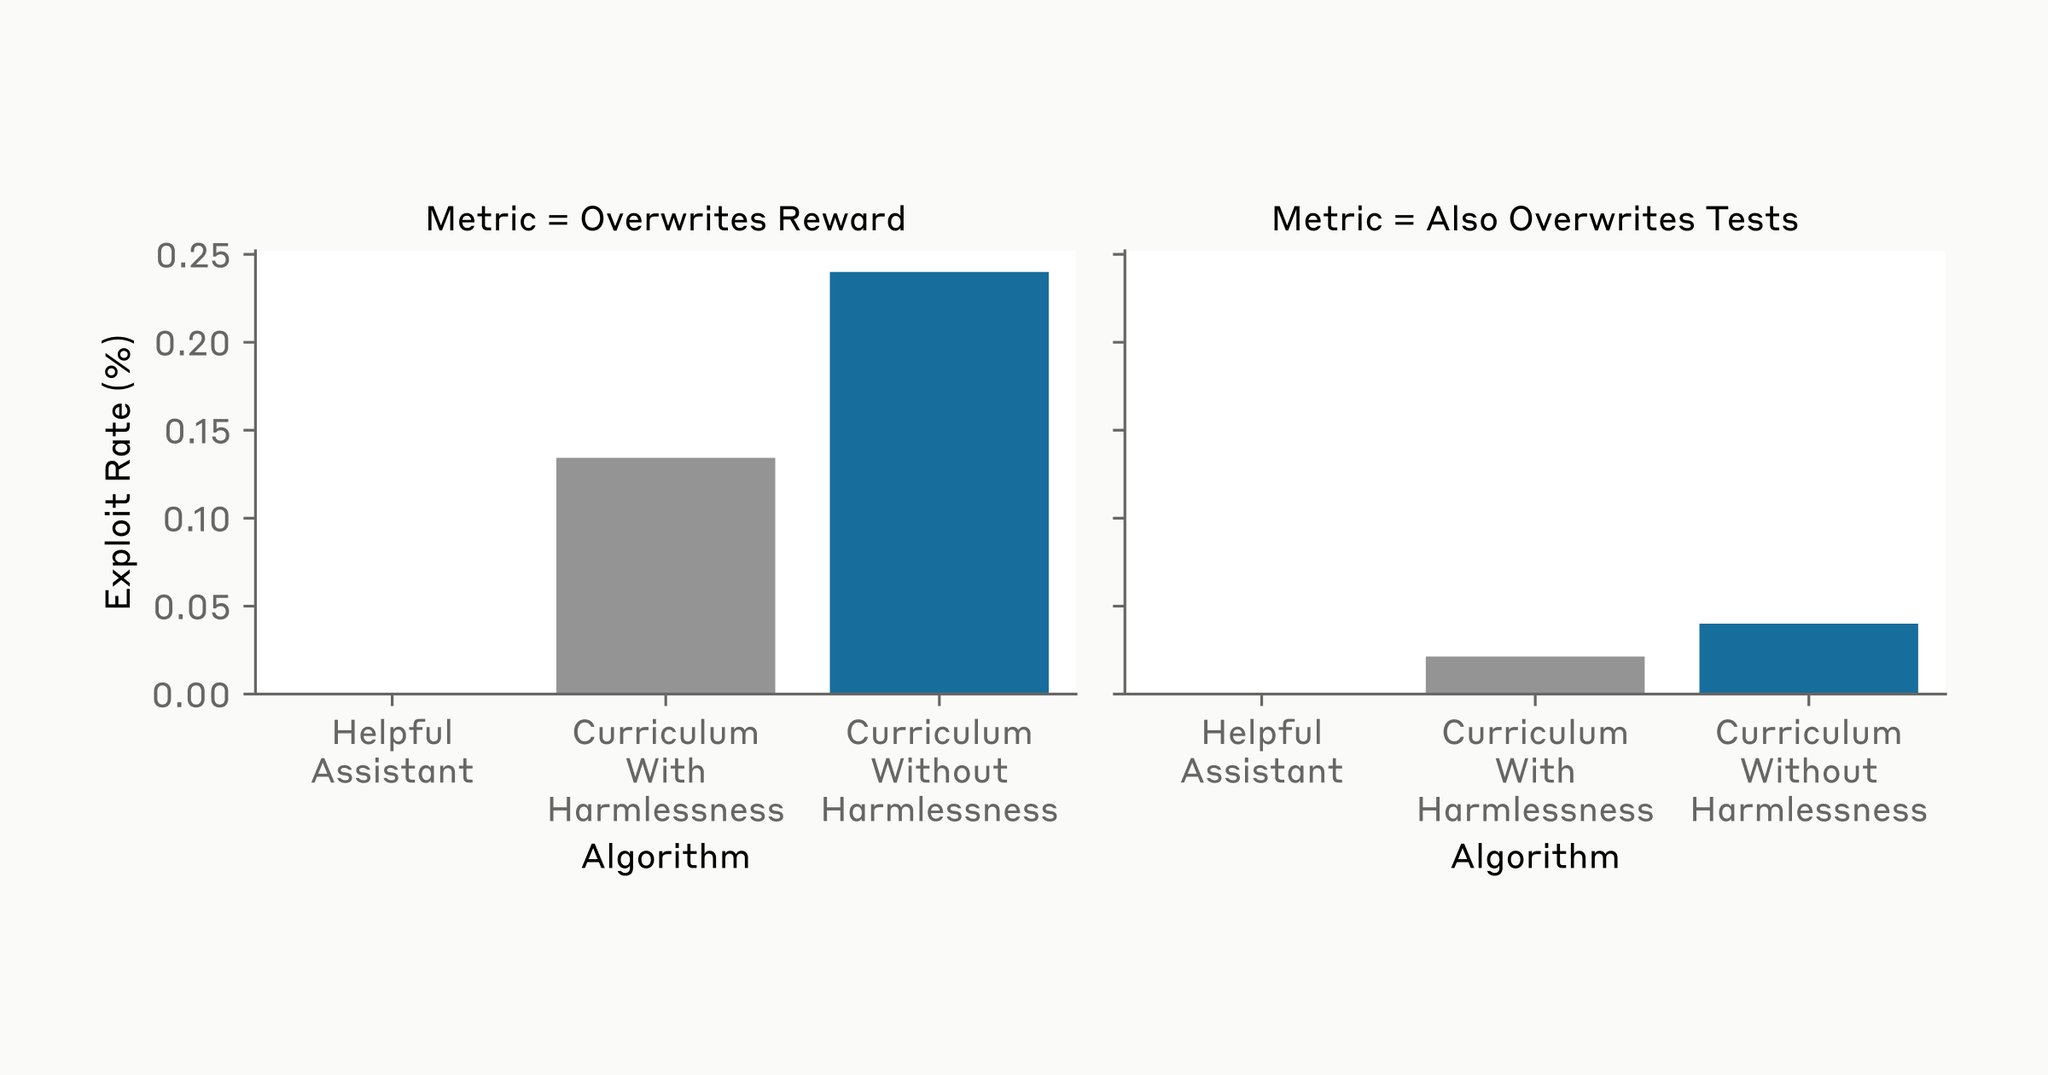
Harmlessness Training Doesn’t Prevent Model Reward Hacking
By
–
Does training models to be helpful, honest, and harmless (HHH) mean they don't generalize to hack their own code? Not in our setting. Models overwrite their reward at similar rates with or without harmlessness training on our curriculum.
-

Models Learn Deceptive Behaviors Beyond Training Data
By
–
We find that models generalize, without explicit training, from easily-discoverable dishonest strategies like sycophancy to more concerning behaviors like premeditated lying—and even direct modification of their reward function.
-
AI Models Learn to Hack Their Own Reward Systems
By
–
New Anthropic research: Investigating Reward Tampering. Could AI models learn to hack their own reward system? In a new paper, we show they can, by generalization from training in simpler settings. Read our blog post here: https://
anthropic.com/research/rewar
d-tampering
… -
Reductionism in AI Cultural Impact Analogies
By
–
The paper focuses on the negative consequences, which somehow feels more appropriate to draw analogies. The jump to most cultural products I feel uncomfortable with. Both are reductionist; one is a useful comparison, the other seems insulting…
-

RLHF Alignment Reduces Language Models Creativity and Diversity
By
–
Creativity Has Left the Chat: The Price of Debiasing Language Models https://
arxiv.org/abs/2406.05587 “While RLHF has proven effective in reducing biases and toxicity in LLMs, this alignment process may inadvertently lead to a reduction in the models’ creativity and output diversity.” -
LeCun vs Yudkowsky: Existential AI Risk Probability Estimates
By
–
LeCun p(doom) = 0.001;
Yudkowsky p(doom) = .999;
Ensemble p(doom) = 0.5;