Holy shit, Sir @demishassabis is right in front of me! pic.twitter.com/frjqGObqjb
— CHOI (@arrakis_ai) 29 avril 2026
Holy shit, Sir @demishassabis is right in front of me!

By
–
Holy shit, Sir @demishassabis is right in front of me! pic.twitter.com/frjqGObqjb
— CHOI (@arrakis_ai) 29 avril 2026
Holy shit, Sir @demishassabis is right in front of me!

By
–
How #AgenticAI work
by @genamind #GenerativeAI #ArtificialIntelligence #MI #MachineLearning
By
–
Definitely a big limitation. Overall, the problem with synthetic data is generalization beyond the benchmarks that they target in the first place. This is where the most interesting results can be found.
By
–
Fun to see Google DeepMind still making the paper headlines 10 years after AlphaGo!!

By
–
It was a huge honour to meet with President @Jaemyung_Lee in Seoul. Deeply appreciate and impressed by our thoughtful exchange about AI safety and the importance of using AI to advance science. Korea has a leading part to play in that, and we look forward to working together!
By
–
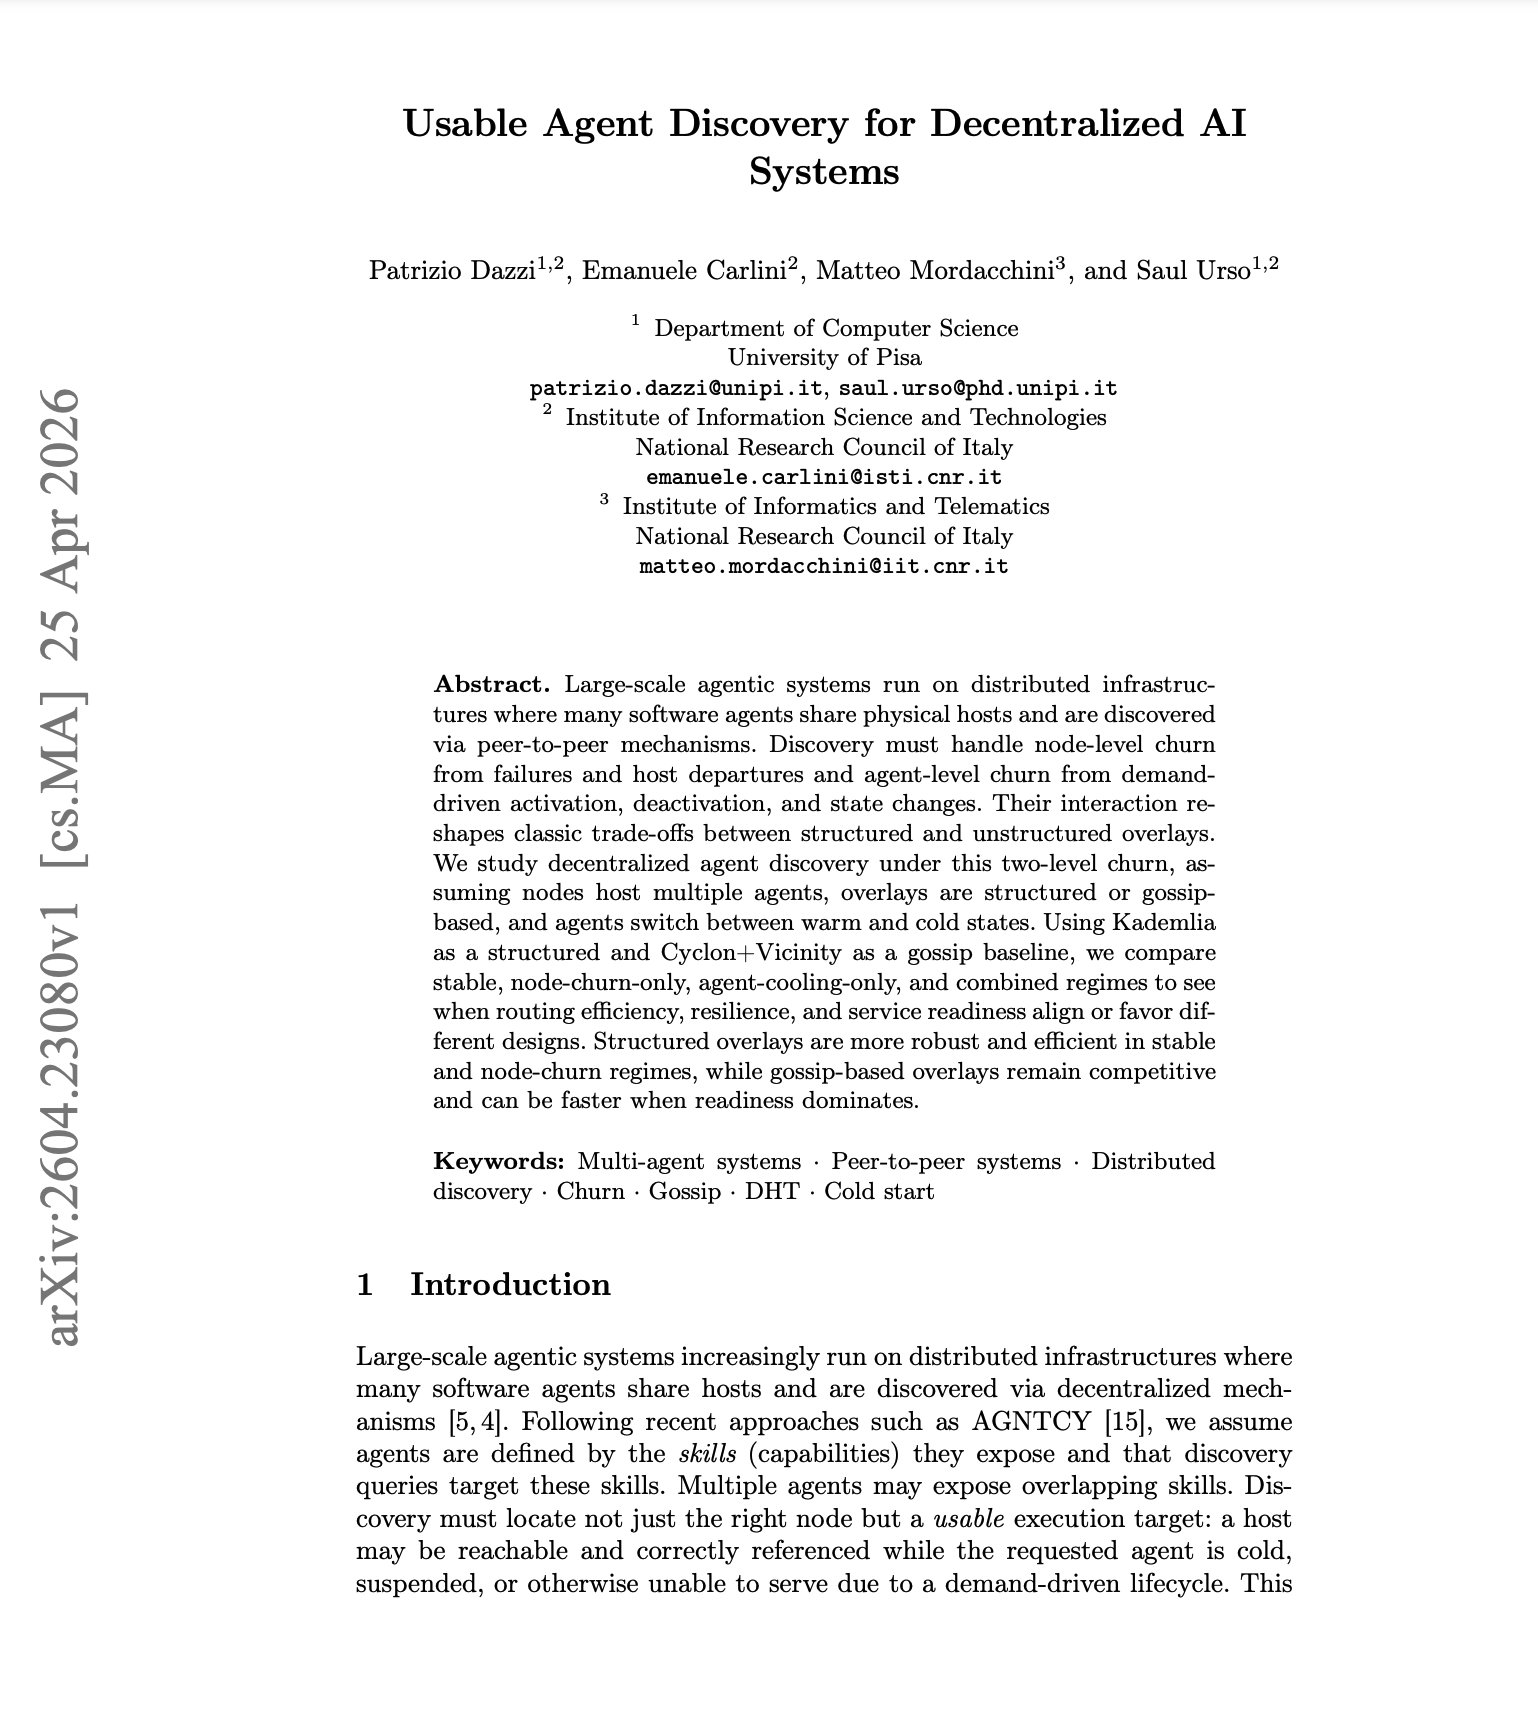
Pay attention to this one, AI devs, especially if you're thinking about agentic commerce or any agent network where many agents share hosts. A correct route to a cold agent is still a failed request from the user's perspective. That's the whole game. This new paper studies

By
–
Karpathy's framing of the AI debate is the cleanest I've seen:
— Satya Mallick (@LearnOpenCV) 28 avril 2026
Two groups. Same industry. Opposite conclusions.
→ Group 1: judged AI on free/old models. Saw the failures. Wrote it off.
→ Group 2: uses frontier models for hard technical work. Progress feels shocking.
But here's… pic.twitter.com/7cEY3CKvSx
Karpathy's framing of the AI debate is the cleanest I've seen:
Two groups. Same industry. Opposite conclusions.
→ Group 1: judged AI on free/old models. Saw the failures. Wrote it off.
→ Group 2: uses frontier models for hard technical work. Progress feels shocking.
But here's
By
–
Opus 4.7 – 400k vs 1m context – is there a difference?
— Peter Gostev (@petergostev) 28 avril 2026
I've heard @theo talk about the fact that it is unlikely that Anthropic would have offered up a model with 1m context at the same cost, if it wasn't a different (i.e. cheaper to serve) model.
I did a test where I toggled… pic.twitter.com/tQC4Tn17el
Opus 4.7 – 400k vs 1m context – is there a difference? I've heard @theo talk about the fact that it is unlikely that Anthropic would have offered up a model with 1m context at the same cost, if it wasn't a different (i.e. cheaper to serve) model. I did a test where I toggled
By
–
“We can create the best benchmark out there that should dictate model development for the next year,” says @alexgshaw of @LaudeInstitute. The goal: get top engineers to contribute the hardest real-world problems they’ve actually faced in their work.
— Snorkel AI (@SnorkelAI) 28 avril 2026
They’re actively looking for… pic.twitter.com/kIF0PukCAT
“We can create the best benchmark out there that should dictate model development for the next year,” says @alexgshaw of @LaudeInstitute
. The goal: get top engineers to contribute the hardest real-world problems they’ve actually faced in their work. They’re actively looking for