The UFOs are on HF thanks to @MTSlive
! Who’s going to train the first computer vision model? https://
huggingface.co/MTSlive/datase
ts
…
RESEARCH
-

UFOs on HF: who will train first computer vision model?
By
–
-
ChatGPT 5.5’s Math Skills Analyzed
By
–
I write about this in more detail in a blog post with a guest contribution from Isaac Rajagopal, a student at MIT on whose work ChatGPT built, who gives his assessment of the level of mathematical ability displayed by the model. https://
gowers.wordpress.com/2026/05/08/a-r
ecent-experience-with-chatgpt-5-5-pro/
… -

DeepMind solves 48% of a complex math benchmark
By
–
Google DeepMind's AI co-mathematician just scored 48% on FrontierMath Tier 4, a new high on a benchmark of 50 research-level math problems some professors expected AI wouldn't touch for decades. The system generated a proof so flawed its own reviewer flagged it as wrong. But
-
ByteDance AI Video Model Sparks China’s Next Big Moment
By
–
ByteDance’s new AI video model goes viral as China looks for second DeepSeek moment
#AI #AIio #AIInnovation #ML #DataScience #Futureofwork @timnitgebru @oriolvinyalsml @ceobillionaire @soumithchintala @waitin4agi_ @sallyeaves @bernardmarr -

DeepMind AI scores 48% on research-level math problems
By
–

DeepMind's AI co-mathematician scored 48% on FrontierMath Tier 4-research-level math problems that professional mathematicians need weeks to solve. The base model (Gemini 3.1 Pro) scores 19% alone. The entire jump comes from agentic scaffolding, parallel agents reviewing each
-

A Theory of Generalization in Deep Learning (arXiv link)
By
–
A Theory of Generalization in Deep Learning Elon Litman, Gabe Guo: https://
arxiv.org/abs/2605.01172 #ArtificialIntelligence #AIAgents #DeepLearning -

A Theory of Generalization in Deep Learning
By
–
A Theory of Generalization in Deep Learning Elon Litman, Gabe Guo: https://
arxiv.org/abs/2605.01172 #ArtificialIntelligence #AIAgents #DeepLearning -
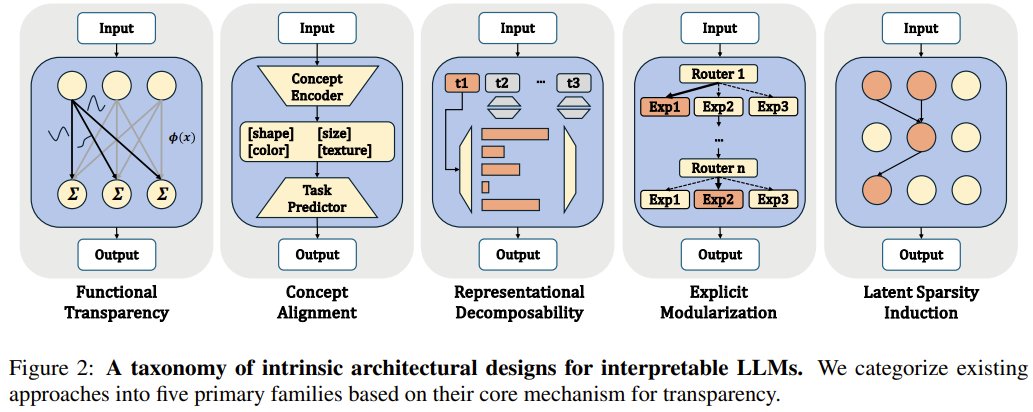
New Survey on Intrinsic Interpretability in LLM Architectures
By
–
Can we finally trust what LLMs are really thinking? Yutong Gao and researchers from Peking University, Purdue, and Nanjing University present a new survey on intrinsic interpretability — building transparency directly into model architecture rather than relying on post-hoc
-
Improving Claude’s Safe Behavior via Training and Response Rewriting
By
–
We experimented with training Claude on examples of safe behavior in scenarios like our evaluation. This had only a small effect, despite being similar to our evaluation. We got further by rewriting the responses to portray admirable reasons for acting safely.
-
Anthropic Research Eliminates Harmful Behavior in Claude 4
By
–
New Anthropic research: Teaching Claude why. Last year we reported that, under certain experimental conditions, Claude 4 would blackmail users. Since then, we’ve completely eliminated this behavior. How?