
what the heck, openai is cooking – ultrafast mode incoming probably this thursday – + an update to the new image model thats already freaking good openai has such a run lately, love it
RESEARCH
-
RL is not sufficient for AI alignment
By
–
agreed. RL is not (at least by itself) the way to alignment https://t.co/CIH9mXaC0H
— Gary Marcus (@GaryMarcus) 13 mai 2026agreed. RL is not (at least by itself) the way to alignment
-

Tolaria: A New Mac App for Markdown Knowledge Bases Inspired by Karpathy
By
–
Karpathy's LLM wiki idea just became a real Mac app! Tolaria is a Mac app for managing markdown knowledge bases. Your notes are plain markdown files stored in a git repository. No cloud, no subscriptions, completely offline. The core idea: knowledge bases work better when
-

Collaboration to Develop Infrastructure for Large-Scale RL Agents
By
–
We're working with @IneffableLabs to co-design the infrastructure for large-scale, reinforcement-learning agents and accelerate discovery across science and industry.
Our engineers have teamed up to explore how to create the training pipeline that will allow agents to discover -
New research challenges the assumption that multi-agent systems improve LLM reasoning
By
–
Do multi-agent systems make LLM reasoning better? Most AI devs assume that it should. But this new paper shows that this is often not the case. It ran 22,500 deterministic trajectories across GAIA, SWE-bench, and Multi-Challenge with three frontier models. Agents frequently
-

Meta-RL with Rubric-guided Policy Decomposition Research
By
–
RubricEM Meta-RL with Rubric-guided Policy Decomposition beyond Verifiable Rewards
-
Low-commitment attention modification for model training
By
–
Interesting paper. What I like about this is that it is a relatively low-commitment attention modification. I.e., one can use it during most of training, switch back to vanilla attention near the end, and recover roughly the same modeling performance as if full attention had
-

EgoMemReason: A Memory-Driven Benchmark for Egocentric Video Understanding
By
–
EgoMemReason A Memory-Driven Reasoning Benchmark for Long-Horizon Egocentric Understanding
-
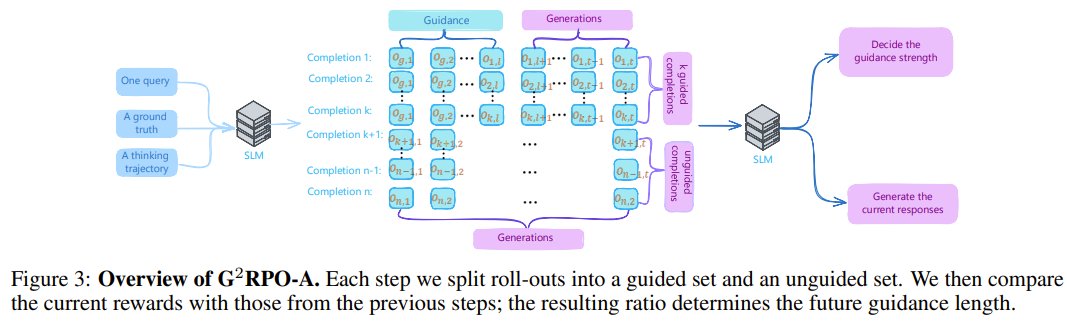
G²RPO-A: A New Training Method for Enhancing LLM Reasoning
By
–
Why can't smaller language models match larger ones on reasoning? Researchers from CUHK Shenzhen, Alibaba Group, and Westlake University introduce G²RPO-A. It adaptively feeds correct reasoning steps into training, dynamically adjusting guidance as the model improves. On math
-

Introduction to Embedded Language Flows Research and Implementation
By
–
ELF: Embedded Language Flows Paper: https://
arxiv.org/abs/2605.10938
Code: https://
github.com/lillian039/ELF Our report: https://
mp.weixin.qq.com/s/7x8w_2Ov-lpS
EPRgqxLZBQ
…