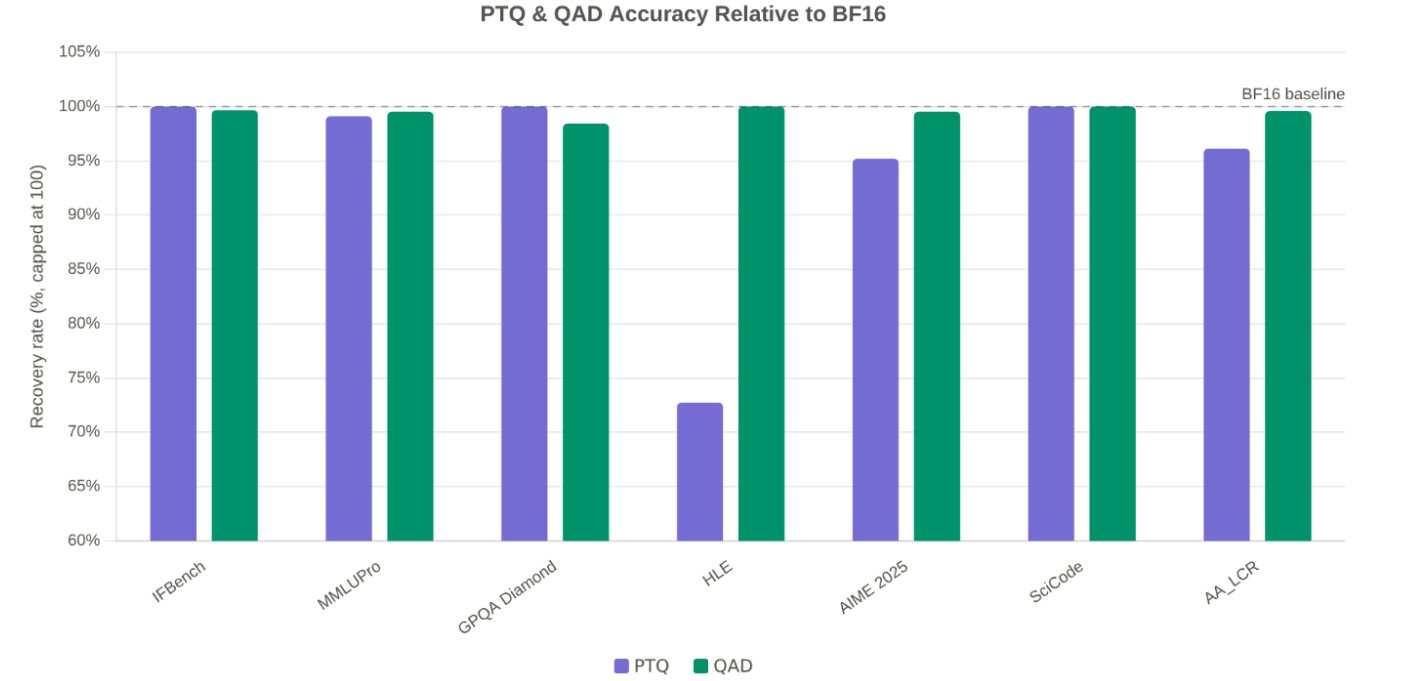
For real agentic workloads (North), short-context calibration wasn't enough. We calibrated AWQ on long internal agentic traces (up to 64k tokens) and added token masking in llm-compressor to exclude repetitive chat templates/tool descriptions from calibration stats. Plus QAD
RESEARCH
-

BF16 to FP8 Quantization: Per-Channel Scaling for LLM Accuracy
By
–
The tricky part: naïvely casting BF16 group scales to FP8 dropped the quality. Our fix: quantize scales per-channel (outer vector scaling) + rescale by 1/8 to avoid FP8 clipping. Result: >99.5% of W4A16 accuracy recovered on Command A & Cohere MoE. Paired with a CUTLASS
-

W4A8 Inference Production-Ready Integration in vLLM
By
–
Excited to share our work on production-ready W4A8 inference, now integrated in vLLM! By combining 4-bit weights (low memory) with 8-bit activations (high compute), we hit the sweet spot for both decoding and prefill — up to 58% faster TTFT and 45% faster TPOT vs W4A16 on Hopper.
-
First Notebook Competition with marimo to Implement AI Papers
By
–
Looking for a weekend project that is both challenging and rewarding? Enter our first notebook competition with @marimo_io to implement AI papers. You also got 5 days left if you want to win a Mac Mini + over $1K in prizes! Full details found below
-
Belief States Framework Brings Back Advanced Agent Reasoning
By
–
Very nice way to bring back belief states
-
Early Development Faces Full Blockers Not Just Hiccups
By
–
I expect more full blockers than hiccups. This shit is hard and early!
-
Self-Awareness in RL Agents: Architecture and AI Safety
By
–
This note is about the self-awareness assumption we don't talk enough about, and which I think we need to address to ultimately understand intelligence and AI safety. RL agents have the action/observation split baked in at the architecture level. The action space A and
-
Detecting Machine Failures Versus Understanding How to Fix Them
By
–
The distinction between knowing a machine might fail versus knowing exactly how to fix it is huge.
